
Most RAG failures originate at retrieval, not generation. Text-first pipelines lose layout semantics, table structure, and figure grounding during PDF→text conversion, degrading recall and precision before an LLM ever runs. Vision-RAG—retrieving rendered pages with vision-language embeddings—directly targets this bottleneck and shows material end-to-end gains on visually rich corpora.
Pipelines (and where they fail)
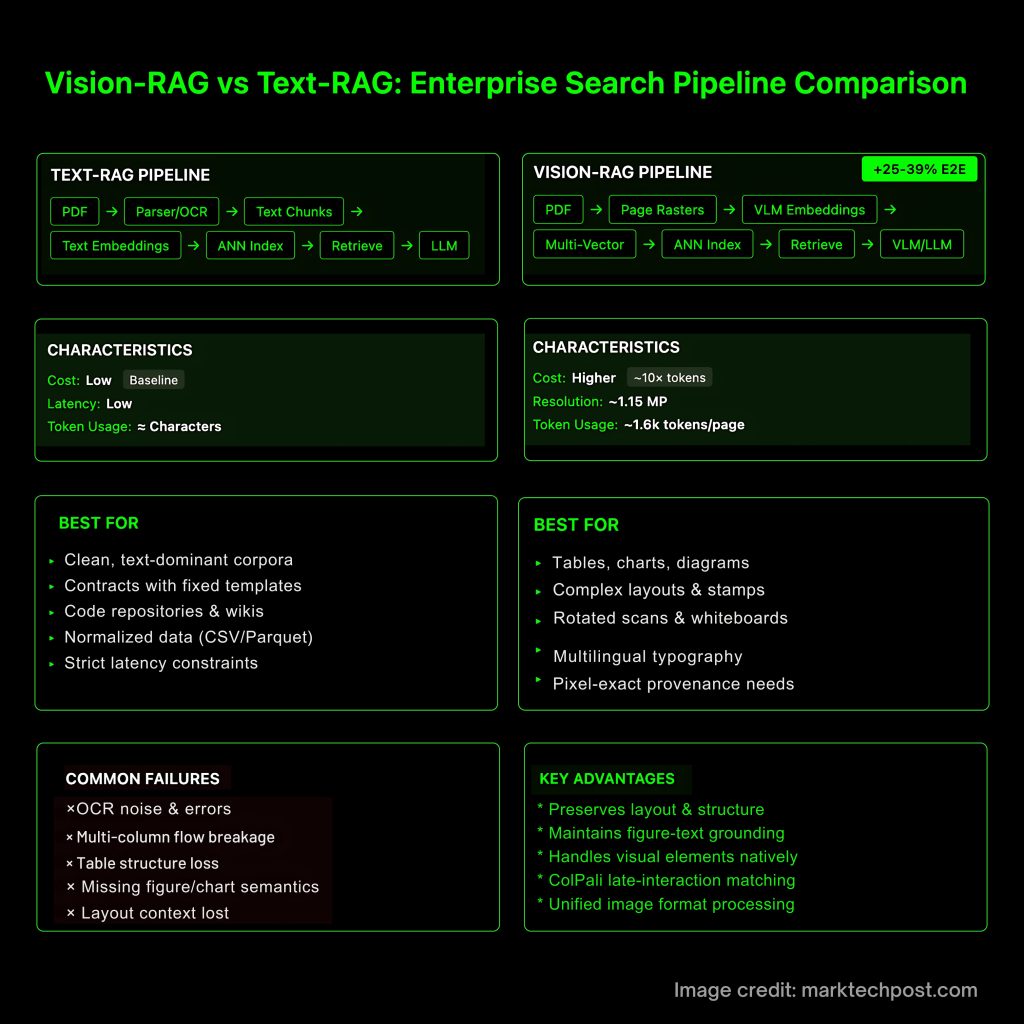
Text-RAG. PDF → (parser/OCR) → text chunks → text embeddings → ANN index → retrieve → LLM. Typical failure modes: OCR noise, multi-column flow breakage, table cell structure loss, and missing figure/chart semantics—documented by table- and doc-VQA benchmarks created to measure exactly these gaps.
Vision-RAG. PDF → page raster(s) → VLM embeddings (often multi-vector with late-interaction scoring) → ANN index → retrieve → VLM/LLM consumes high-fidelity crops or full pages. This preserves layout and figure-text grounding; recent systems (ColPali, VisRAG, VDocRAG) validate the approach.
What current evidence supports
- Document-image retrieval works and is simpler. ColPali embeds page images and uses late-interaction matching; on the ViDoRe benchmark it outperforms modern text pipelines while remaining end-to-end trainable.
- End-to-end lift is measurable. VisRAG reports 25–39% end-to-end improvement over text-RAG on multimodal documents when both retrieval and generation use a VLM.
- Unified image format for real-world docs. VDocRAG shows that keeping documents in a unified image format (tables, charts, PPT/PDF) avoids parser loss and improves generalization; it also introduces OpenDocVQA for evaluation.
- Resolution drives reasoning quality. High-resolution support in VLMs (e.g., Qwen2-VL/Qwen2.5-VL) is explicitly tied to SoTA results on DocVQA/MathVista/MTVQA; fidelity matters for ticks, superscripts, stamps, and small fonts.
Costs: vision context is (often) order-of-magnitude heavier—because of tokens
Vision inputs inflate token counts via tiling, not necessarily per-token price. For GPT-4o-class models, total tokens ≈ base + (tile_tokens × tiles), so 1–2 MP pages can be ~10× cost of a small text chunk. Anthropic recommends ~1.15 MP caps (~1.6k tokens) for responsiveness. By contrast, Google Gemini 2.5 Flash-Lite prices text/image/video at the same per-token rate, but large images still consume many more tokens. Engineering implication: adopt selective fidelity (crop > downsample > full page).
Design rules for production Vision-RAG
- Align modalities across embeddings. Use encoders trained for text↔image alignment (CLIP-family or VLM retrievers) and, in practice, dual-index: cheap text recall for coverage + vision rerank for precision. ColPali’s late-interaction (MaxSim-style) is a strong default for page images.
- Feed high-fidelity inputs selectively. Coarse-to-fine: run BM25/DPR, take top-k pages to a vision reranker, then send only ROI crops (tables, charts, stamps) to the generator. This preserves crucial pixels without exploding tokens under tile-based accounting.
- Engineer for real documents.
• Tables: if you must parse, use table-structure models (e.g., PubTables-1M/TATR); otherwise prefer image-native retrieval.
• Charts/diagrams: expect tick- and legend-level cues; resolution must retain these. Evaluate on chart-focused VQA sets.
• Whiteboards/rotations/multilingual: page rendering avoids many OCR failure modes; multilingual scripts and rotated scans survive the pipeline.
• Provenance: store page hashes and crop coordinates alongside embeddings to reproduce exact visual evidence used in answers.
| Standard | Text-RAG | Vision-RAG |
|---|---|---|
| Ingest pipeline | PDF → parser/OCR → text chunks → text embeddings → ANN | PDF → page render(s) → VLM page/crop embeddings (often multi-vector, late interaction) → ANN. ColPali is a canonical implementation. |
| Primary failure modes | Parser drift, OCR noise, multi-column flow breakage, table structure loss, missing figure/chart semantics. Benchmarks exist because these errors are common. | Preserves layout/figures; failures shift to resolution/tiling choices and cross-modal alignment. VDocRAG formalizes “unified image” processing to avoid parsing loss. |
| Retriever representation | Single-vector text embeddings; rerank via lexical or cross-encoders | Page-image embeddings with late interaction (MaxSim-style) capture local regions; improves page-level retrieval on ViDoRe. |
| End-to-end gains (vs Text-RAG) | Baseline | +25–39% E2E on multimodal docs when both retrieval and generation are VLM-based (VisRAG). |
| Where it excels | Clean, text-dominant corpora; low latency/cost | Visually rich/structured docs: tables, charts, stamps, rotated scans, multilingual typography; unified page context helps QA. |
| Resolution sensitivity | Not applicable beyond OCR settings | Reasoning quality tracks input fidelity (ticks, small fonts). High-res document VLMs (e.g., Qwen2-VL family) emphasize this. |
| Cost model (inputs) | Tokens ≈ characters; cheap retrieval contexts | Image tokens grow with tiling: e.g., OpenAI base+tiles formula; Anthropic guidance ~1.15 MP ≈ ~1.6k tokens. Even when per-token price is equal (Gemini 2.5 Flash-Lite), high-res pages consume far more tokens. |
| Cross-modal alignment need | Not required | Critical: text↔image encoders must share geometry for mixed queries; ColPali/ViDoRe demonstrate effective page-image retrieval aligned to language tasks. |
| Benchmarks to track | DocVQA (doc QA), PubTables-1M (table structure) for parsing-loss diagnostics. | ViDoRe (page retrieval), VisRAG (pipeline), VDocRAG (unified-image RAG). |
| Evaluation approach | IR metrics plus text QA; may miss figure-text grounding issues | Joint retrieval+gen on visually rich suites (e.g., OpenDocVQA under VDocRAG) to capture crop relevance and layout grounding. |
| Operational pattern | One-stage retrieval; cheap to scale | Coarse-to-fine: text recall → vision rerank → ROI crops to generator; keeps token costs bounded while preserving fidelity. (Tiling math/pricing inform budgets.) |
| When to prefer | Contracts/templates, code/wikis, normalized tabular data (CSV/Parquet) | Real-world enterprise docs with heavy layout/graphics; compliance workflows needing pixel-exact provenance (page hash + crop coords). |
| Representative systems | DPR/BM25 + cross-encoder rerank | ColPali (ICLR’25) vision retriever; VisRAG pipeline; VDocRAG unified image framework. |
When Text-RAG is still the right default?
- Clean, text-dominant corpora (contracts with fixed templates, wikis, code)
- Strict latency/cost constraints for short answers
- Data already normalized (CSV/Parquet)—skip pixels and query the table store
Evaluation: measure retrieval + generation jointly
Add multimodal RAG benchmarks to your harness—e.g., M²RAG (multi-modal QA, captioning, fact-verification, reranking), REAL-MM-RAG (real-world multi-modal retrieval), and RAG-Check (relevance + correctness metrics for multi-modal context). These catch failure cases (irrelevant crops, figure-text mismatch) that text-only metrics miss.
Summary
Text-RAG remains efficient for clean, text-only data. Vision-RAG is the practical default for enterprise documents with layout, tables, charts, stamps, scans, and multilingual typography. Teams that (1) align modalities, (2) deliver selective high-fidelity visual evidence, and (3) evaluate with multimodal benchmarks consistently get higher retrieval precision and better downstream answers—now backed by ColPali (ICLR 2025), VisRAG’s 25–39% E2E lift, and VDocRAG’s unified image-format results.
References:

Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.
Credit: Source link