
• bitcoinBitcoin(BTC)$84,154.00-1.01%
  • ethereumEthereum(ETH)$2,686.37-1.70%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$774.15-0.85%
  • rippleXRP(XRP)$1.55-1.29%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$120.47-1.14%
  • tronTRON(TRX)$0.336762-0.08%
  • zcashZcash(ZEC)$1,534.97-4.87%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.020.00%
  • HyperliquidHyperliquid(HYPE)$92.08-2.33%
  • dogecoinDogecoin(DOGE)$0.0978950.06%
  • chainlinkChainlink(LINK)$14.181.07%
  • moneroMonero(XMR)$553.65-2.92%
  • whitebitWhiteBIT Coin(WBT)$83.97-1.17%
  • USDSUSDS(USDS)$1.000.00%
  • cardanoCardano(ADA)$0.2569930.57%
  • RainRain(RAIN)$0.0120571.28%
  • leo-tokenLEO Token(LEO)$8.961.52%
  • stellarStellar(XLM)$0.219418-1.00%
  • bitcoin-cashBitcoin Cash(BCH)$339.24-0.18%
  • nearNEAR Protocol(NEAR)$4.92-2.21%
  • uniswapUniswap(UNI)$9.652.27%
  • litecoinLitecoin(LTC)$73.763.80%
  • CantonCanton(CC)$0.13455310.31%
  • Ethena USDeEthena USDe(USDE)$1.00-0.03%
  • suiSui(SUI)$1.199.72%
  • avalanche-2Avalanche(AVAX)$10.802.71%
  • daiDai(DAI)$1.000.00%
  • USD1USD1(USD1)$1.000.00%
  • hedera-hashgraphHedera(HBAR)$0.094470-0.05%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.462.23%
  • BittensorBittensor(TAO)$320.653.86%
  • shiba-inuShiba Inu(SHIB)$0.0000060.55%
  • crypto-com-chainCronos(CRO)$0.065759-0.15%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • EthenaEthena(ENA)$0.28454818.80%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • MemeCoreMemeCore(M)$1.232.49%
  • OndoOndo(ONDO)$0.560.51%
  • tether-goldTether Gold(XAUT)$4,280.19-0.66%
  • okbOKB(OKB)$121.570.79%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BitwayBitway(BTW)$0.90-16.94%
  • Circle USYCCircle USYC(USYC)$1.140.03%
  • aaveAave(AAVE)$154.504.86%
  • mantleMantle(MNT)$0.703.08%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.00%
  • polkadotPolkadot(DOT)$1.234.74%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Top 10 Local LLMs (2025): Context Windows, VRAM Targets, and Licenses Compared

September 28, 2025
in AI & Technology
Reading Time: 5 mins read
A A
Top 10 Local LLMs (2025): Context Windows, VRAM Targets, and Licenses Compared
ShareShareShareShareShare

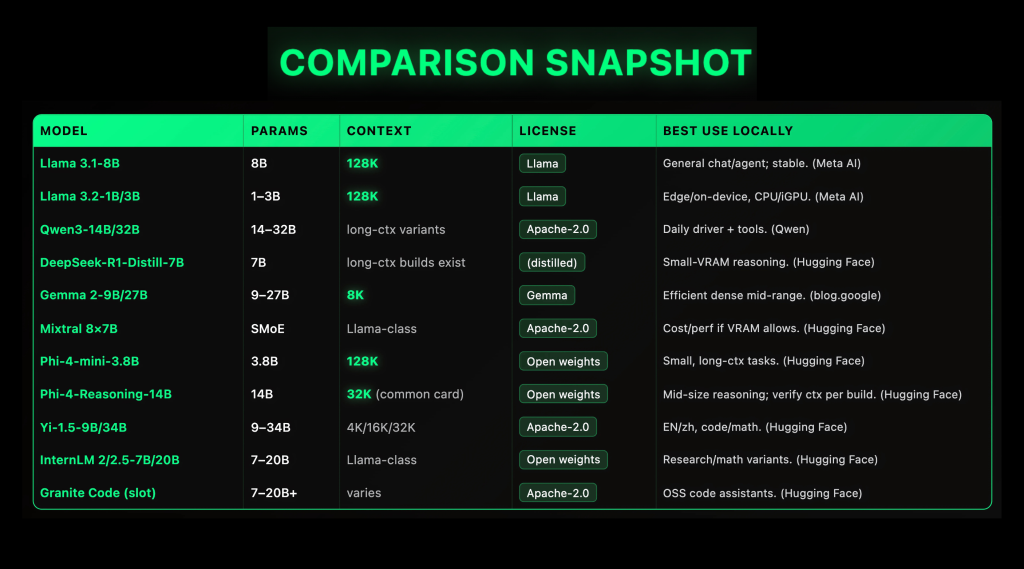
Local LLMs matured fast in 2025: open-weight families like Llama 3.1 (128K context length (ctx)), Qwen3 (Apache-2.0, dense + MoE), Gemma 2 (9B/27B, 8K ctx), Mixtral 8×7B (Apache-2.0 SMoE), and Phi-4-mini (3.8B, 128K ctx) now ship reliable specs and first-class local runners (GGUF/llama.cpp, LM Studio, Ollama), making on-prem and even laptop inference practical if you match context length and quantization to VRAM. This guide lists the ten most deployable options by license clarity, stable GGUF availability, and reproducible performance characteristics (params, context length (ctx), quant presets).

Top 10 Local LLMs (2025)

1) Meta Llama 3.1-8B — robust “daily driver,” 128K context

Why it matters. A stable, multilingual baseline with long context and first-class support across local toolchains.
Specs. Dense 8B decoder-only; official 128K context; instruction-tuned and base variants. Llama license (open weights). Common GGUF builds and Ollama recipes exist. Typical setup: Q4_K_M/Q5_K_M for ≤12-16 GB VRAM, Q6_K for ≥24 GB.

YOU MAY ALSO LIKE

Exa Launches Agent Ultra: A Subagent Swarm Deep Research API Built for Exhaustive List Building

End-to-End Multimodal Data Augmentation and Adversarial Robustness Benchmark with AugLy for Images, Text, Audio, and PyTorch

2) Meta Llama 3.2-1B/3B — edge-class, 128K context, on-device friendly

Why it matters. Small models that still take 128K tokens and run acceptably on CPUs/iGPUs when quantized; good for laptops and mini-PCs.
Specs. 1B/3B instruction-tuned models; 128K context confirmed by Meta. Works well via llama.cpp GGUF and LM Studio’s multi-runtime stack (CPU/CUDA/Vulkan/Metal/ROCm).

3) Qwen3-14B / 32B — open Apache-2.0, strong tool-use & multilingual

Why it matters. Broad family (dense+MoE) under Apache-2.0 with active community ports to GGUF; widely reported as a capable general/agentic “daily driver” locally.
Specs. 14B/32B dense checkpoints with long-context variants; modern tokenizer; rapid ecosystem updates. Start at Q4_K_M for 14B on 12 GB; move to Q5/Q6 when you have 24 GB+. (Qwen)

4) DeepSeek-R1-Distill-Qwen-7B — compact reasoning that fits

Why it matters. Distilled from R1-style reasoning traces; delivers step-by-step quality at 7B with widely available GGUFs. Excellent for math/coding on modest VRAM.
Specs. 7B dense; long-context variants exist per conversion; curated GGUFs cover F32→Q4_K_M. For 8–12 GB VRAM try Q4_K_M; for 16–24 GB use Q5/Q6.

5) Google Gemma 2-9B / 27B — efficient dense; 8K context (explicit)

Why it matters. Strong quality-for-size and quantization behavior; 9B is a great mid-range local model.
Specs. Dense 9B/27B; 8K context (don’t overstate); open weights under Gemma terms; widely packaged for llama.cpp/Ollama. 9B@Q4_K_M runs on many 12 GB cards.

6) Mixtral 8×7B (SMoE) — Apache-2.0 sparse MoE; cost/perf workhorse

Why it matters. Mixture-of-Experts throughput benefits at inference: ~2 experts/token selected at runtime; great compromise when you have ≥24–48 GB VRAM (or multi-GPU) and want stronger general performance.
Specs. 8 experts of 7B each (sparse activation); Apache-2.0; instruct/base variants; mature GGUF conversions and Ollama recipes.

7) Microsoft Phi-4-mini-3.8B — small model, 128K context

Why it matters. Realistic “small-footprint reasoning” with 128K context and grouped-query attention; solid for CPU/iGPU boxes and latency-sensitive tools.
Specs. 3.8B dense; 200k vocab; SFT/DPO alignment; model card documents 128K context and training profile. Use Q4_K_M on ≤8–12 GB VRAM.

8) Microsoft Phi-4-Reasoning-14B — mid-size reasoning (check ctx per build)

Why it matters. A 14B reasoning-tuned variant that is materially better for chain-of-thought-style tasks than generic 13–15B baselines.
Specs. Dense 14B; context varies by distribution (model card for a common release lists 32K). For 24 GB VRAM, Q5_K_M/Q6_K is comfortable; mixed-precision runners (non-GGUF) need more.

9) Yi-1.5-9B / 34B — Apache-2.0 bilingual; 4K/16K/32K variants

Why it matters. Competitive EN/zh performance and permissive license; 9B is a strong alternative to Gemma-2-9B; 34B steps toward higher reasoning under Apache-2.0.
Specs. Dense; context variants 4K/16K/32K; open weights under Apache-2.0 with active HF cards/repos. For 9B use Q4/Q5 on 12–16 GB.

10) InternLM 2 / 2.5-7B / 20B — research-friendly; math-tuned branches

Why it matters. An open series with lively research cadence; 7B is a practical local target; 20B moves you toward Gemma-2-27B-class capability (at higher VRAM).
Specs. Dense 7B/20B; multiple chat/base/math variants; active HF presence. GGUF conversions and Ollama packs are common.

source: marktechpost.com

Summary

In local LLMs, the trade-offs are clear: pick dense models for predictable latency and simpler quantization (e.g., Llama 3.1-8B with a documented 128K context; Gemma 2-9B/27B with an explicit 8K window), move to sparse MoE like Mixtral 8×7B when your VRAM and parallelism justify higher throughput per cost, and treat small reasoning models (Phi-4-mini-3.8B, 128K) as the sweet spot for CPU/iGPU boxes. Licenses and ecosystems matter as much as raw scores: Qwen3’s Apache-2.0 releases (dense + MoE) and Meta/Google/Microsoft model cards give the operational guardrails (context, tokenizer, usage terms) you’ll actually live with. On the runtime side, standardize on GGUF/llama.cpp for portability, layer Ollama/LM Studio for convenience and hardware offload, and size quantization (Q4→Q6) to your memory budget. In short: choose by context + license + hardware path, not just leaderboard vibes.

The post Top 10 Local LLMs (2025): Context Windows, VRAM Targets, and Licenses Compared appeared first on MarkTechPost.

Credit: Source link

ShareTweetSendSharePin

Related Posts

Exa Launches Agent Ultra: A Subagent Swarm Deep Research API Built for Exhaustive List Building
AI & Technology

Exa Launches Agent Ultra: A Subagent Swarm Deep Research API Built for Exhaustive List Building

September 26, 2026
End-to-End Multimodal Data Augmentation and Adversarial Robustness Benchmark with AugLy for Images, Text, Audio, and PyTorch
AI & Technology

End-to-End Multimodal Data Augmentation and Adversarial Robustness Benchmark with AugLy for Images, Text, Audio, and PyTorch

September 26, 2026
Liquid AI Releases LFM2.5-VL-3B-DSpark: Speculative Decoding for Vision-Language Models With Up to 3.13x Faster Decoding
AI & Technology

Liquid AI Releases LFM2.5-VL-3B-DSpark: Speculative Decoding for Vision-Language Models With Up to 3.13x Faster Decoding

September 25, 2026
How To Stop Meta Training Its AI Models On Your Smart Glasses’ Visual Data
AI & Technology

How To Stop Meta Training Its AI Models On Your Smart Glasses’ Visual Data

September 25, 2026
Next Post
Ives, Lee Tap Social Media Megaphone for New ETFs

Ives, Lee Tap Social Media Megaphone for New ETFs

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Moulton says he shares same progressive values as Markey but isn’t afraid to challenge establishment

Moulton says he shares same progressive values as Markey but isn’t afraid to challenge establishment

September 19, 2026
At least 7 dead after ferry carrying nearly 270 capsizes off northern Cyprus

At least 7 dead after ferry carrying nearly 270 capsizes off northern Cyprus

September 21, 2026
Iconic Los Angeles Starbucks closing after 30 years

Iconic Los Angeles Starbucks closing after 30 years

September 26, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!