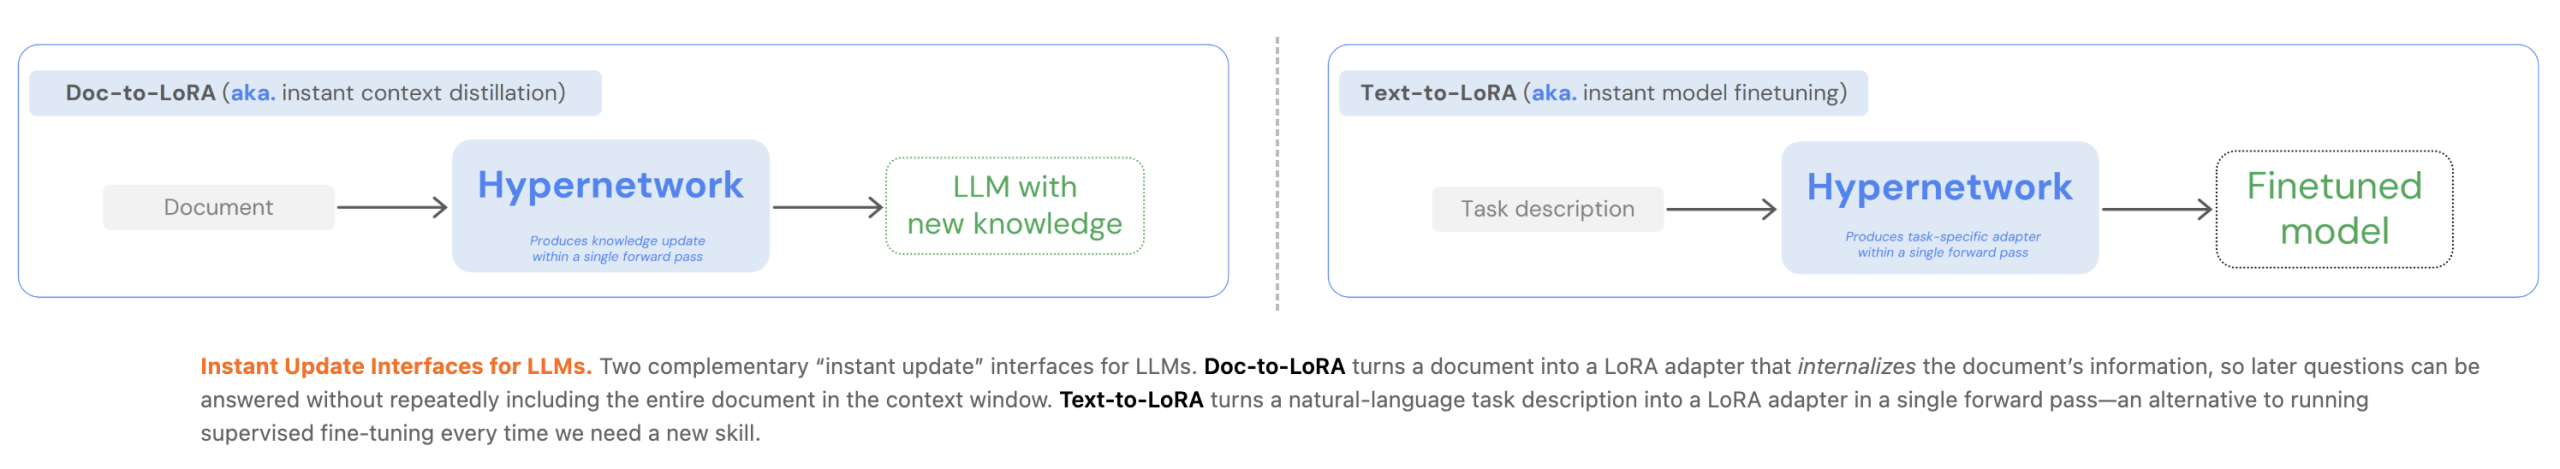

Customizing Large Language Models (LLMs) currently presents a significant engineering trade-off between the flexibility of In-Context Learning (ICL) and the efficiency of Context Distillation (CD) or Supervised Fine-Tuning (SFT). Tokyo-based Sakana AI has proposed a new approach to bypass these constraints through cost amortization. In two of their recent papers, they introduced Text-to-LoRA (T2L) and Doc-to-LoRA (D2L), lightweight hypernetworks that meta-learn to generate Low-Rank Adaptation (LoRA) matrices in a single forward pass.
The Engineering Bottleneck: Latency vs. Memory
For AI Devs, the primary limitation of standard LLM adaptation is computational overhead:
- In-Context Learning (ICL): While convenient, ICL suffers from quadratic attention costs and linear KV-cache growth, which increases latency and memory consumption as prompts lengthen.
- Context Distillation (CD): CD transfers information into model parameters, but per-prompt distillation is often impractical due to high training costs and update latency.
- SFT: Requires task-specific datasets and expensive re-training if information changes.
Sakana AI’s methods amortize these costs by paying a one-time meta-training fee. Once trained, the hypernetwork can instantly adapt the base LLM to new tasks or documents without additional backpropagation.
Text-to-LoRA (T2L): Adaptation via Natural Language
Text-to-LoRA (T2L) is a hypernetwork designed to adapt LLMs on the fly using only a natural language description of a task.
Architecture and Training
T2L uses a task encoder to extract vector representations from text descriptions. This representation, combined with learnable module and layer embeddings, is processed through a series of MLP blocks to generate the A and B low-rank matrices for the target LLM.
The system can be trained via two primary schemes:
- LoRA Reconstruction: Distilling existing, pre-trained LoRA adapters into the hypernetwork.
- Supervised Fine-Tuning (SFT): Optimizing the hypernetwork end-to-end on multi-task datasets.
The research indicates that SFT-trained T2L generalizes better to unseen tasks because it implicitly learns to cluster related functionalities in weight space. In benchmarks, T2L matched or outperformed task-specific adapters on tasks like GSM8K and Arc-Challenge, while reducing adaptation costs by over 4x compared to 3-shot ICL.
Doc-to-LoRA (D2L): Internalizing Context
Doc-to-LoRA (D2L) extends this concept to document internalization. It enables an LLM to answer subsequent queries about a document without re-consuming the original context, effectively removing the document from the active context window.
Perceiver-Based Design
D2L utilizes a Perceiver-style cross-attention architecture. It maps variable-length token activations (Z) from the base LLM into a fixed-shape LoRA adapter.
To handle documents exceeding the training length, D2L employs a chunking mechanism. Long contexts are partitioned into K contiguous chunks, each processed independently to produce per-chunk adapters. These are then concatenated along the rank dimension, allowing D2L to generate higher-rank LoRAs for longer inputs without changing the hypernetwork’s output shape.
Performance and Memory Efficiency
On a Needle-in-a-Haystack (NIAH) retrieval task, D2L maintained near-perfect zero-shot accuracy on context lengths exceeding the base model’s native window by more than 4x.
- Memory Impact: For a 128K-token document, a base model requires over 12 GB of VRAM for the KV cache. Internalized D2L models handled the same document using less than 50 MB.
- Update Latency: D2L internalizes information in sub-second regimes (<1s), whereas traditional CD can take between 40 to 100 seconds.
Cross-Modal Transfer
A significant finding in the D2L research is the ability to perform zero-shot internalization of visual information. By using a Vision-Language Model (VLM) as the context encoder, D2L mapped visual activations into a text-only LLM’s parameters. This allowed the text model to classify images from the Imagenette dataset with 75.03% accuracy, despite never seeing image data during its primary training.
Key Takeaways
- Amortized Customization via Hypernetworks: Both methods use lightweight hypernetworks to meta-learn the adaptation process, paying a one-time meta-training cost to enable instant, sub-second generation of LoRA adapters for new tasks or documents.
- Significant Memory and Latency Reduction: Doc-to-LoRA internalizes context into parameters, reducing KV-cache memory consumption from over 12 GB to less than 50 MB for long documents and lowering update latency from minutes to less than a second.
- Effective Long-Context Generalization: Using a Perceiver-based architecture and a chunking mechanism, Doc-to-LoRA can internalize information at sequence lengths more than 4x the native context window of the base LLM with near-perfect accuracy.
- Zero-Shot Task Adaptation: Text-to-LoRA can generate specialized LoRA adapters for entirely unseen tasks based solely on a natural language description, matching or exceeding the performance of task-specific ‘oracle’ adapters.
- Cross-Modal Knowledge Transfer: The Doc-to-LoRA architecture enables zero-shot internalization of visual information from a Vision-Language Model (VLM) into a text-only LLM, allowing the latter to classify images with high accuracy without having seen pixel data during its primary training.
Check out the Doc-to-Lora Paper, Code, Text-to-LoRA Paper, Code . Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
The post Sakana AI Introduces Doc-to-LoRA and Text-to-LoRA: Hypernetworks that Instantly Internalize Long Contexts and Adapt LLMs via Zero-Shot Natural Language appeared first on MarkTechPost.
Credit: Source link