
• bitcoinBitcoin(BTC)$86,635.006.73%
  • ethereumEthereum(ETH)$2,761.524.86%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$799.943.95%
  • rippleXRP(XRP)$1.506.63%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$118.046.86%
  • tronTRON(TRX)$0.3442940.36%
  • zcashZcash(ZEC)$1,472.78-3.03%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.010.00%
  • HyperliquidHyperliquid(HYPE)$93.25-0.04%
  • dogecoinDogecoin(DOGE)$0.09835612.57%
  • moneroMonero(XMR)$584.493.39%
  • whitebitWhiteBIT Coin(WBT)$87.125.20%
  • RainRain(RAIN)$0.0141500.36%
  • chainlinkChainlink(LINK)$13.023.83%
  • USDSUSDS(USDS)$1.000.00%
  • cardanoCardano(ADA)$0.2441667.13%
  • leo-tokenLEO Token(LEO)$8.89-0.53%
  • stellarStellar(XLM)$0.2112337.67%
  • uniswapUniswap(UNI)$8.820.82%
  • nearNEAR Protocol(NEAR)$4.16-0.18%
  • bitcoin-cashBitcoin Cash(BCH)$266.826.11%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • avalanche-2Avalanche(AVAX)$11.05-0.93%
  • litecoinLitecoin(LTC)$62.265.54%
  • CantonCanton(CC)$0.1162337.49%
  • daiDai(DAI)$1.000.01%
  • USD1USD1(USD1)$1.000.01%
  • suiSui(SUI)$1.0216.28%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.454.32%
  • hedera-hashgraphHedera(HBAR)$0.0911067.12%
  • shiba-inuShiba Inu(SHIB)$0.0000068.10%
  • BittensorBittensor(TAO)$303.0714.41%
  • MemeCoreMemeCore(M)$1.501.86%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • crypto-com-chainCronos(CRO)$0.0637938.08%
  • paypal-usdPayPal USD(PYUSD)$1.000.01%
  • tether-goldTether Gold(XAUT)$4,347.78-0.54%
  • BitwayBitway(BTW)$0.9629.94%
  • okbOKB(OKB)$122.954.12%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.45%
  • aaveAave(AAVE)$145.195.83%
  • EthenaEthena(ENA)$0.213522-3.62%
  • OndoOndo(ONDO)$0.4424933.33%
  • mantleMantle(MNT)$0.657.10%
  • pepePepe(PEPE)$0.00000523.96%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Rubrics as Rewards (RaR): A Reinforcement Learning Framework for Training Language Models with Structured, Multi-Criteria Evaluation Signals

July 30, 2025
in AI & Technology
Reading Time: 5 mins read
A A
Rubrics as Rewards (RaR): A Reinforcement Learning Framework for Training Language Models with Structured, Multi-Criteria Evaluation Signals
ShareShareShareShareShare

Reinforcement Learning with Verifiable Rewards (RLVR) allows LLMs to perform complex reasoning on tasks with clear, verifiable outcomes, with strong performance in mathematics and coding. However, many real-world scenarios lack such explicit verifiable answers, posing a challenge for training models without direct reward signals. Current methods address this gap through RLHF via preference ranking, where human judgments are collected over pairs or lists of model outputs. Moreover, preference-based reward models can boost performance in the early stages, but they tend to overfit to superficial artifacts such as response length, formatting quirks, and annotator biases. These models require large volumes of pairwise comparisons, making them brittle and costly.

RLVR methods now extend beyond mathematics and coding, with GENERAL-REASONER demonstrating strong performance in physics, finance, and policy, achieving a ten-point gain on MMLU-Pro through GRPO fine-tuning. Rubric-based evaluation has become a standard for advanced LLMs, with frameworks like HEALTHBENCH pairing clinician-written criteria with automated judges to evaluate factuality, safety, and empathy. However, these rubrics appear only during evaluation phases rather than training. Moreover, process supervision methods try to provide more granular feedback by rewarding intermediate reasoning steps through MCTS-generated labels and generative reward models such as THINKPRM.

YOU MAY ALSO LIKE

Here’s Why Apple’s Mac Studio Has Become So Expensive

Tesla Will Soon Roll Out FSD Supervised In The Czech Republic

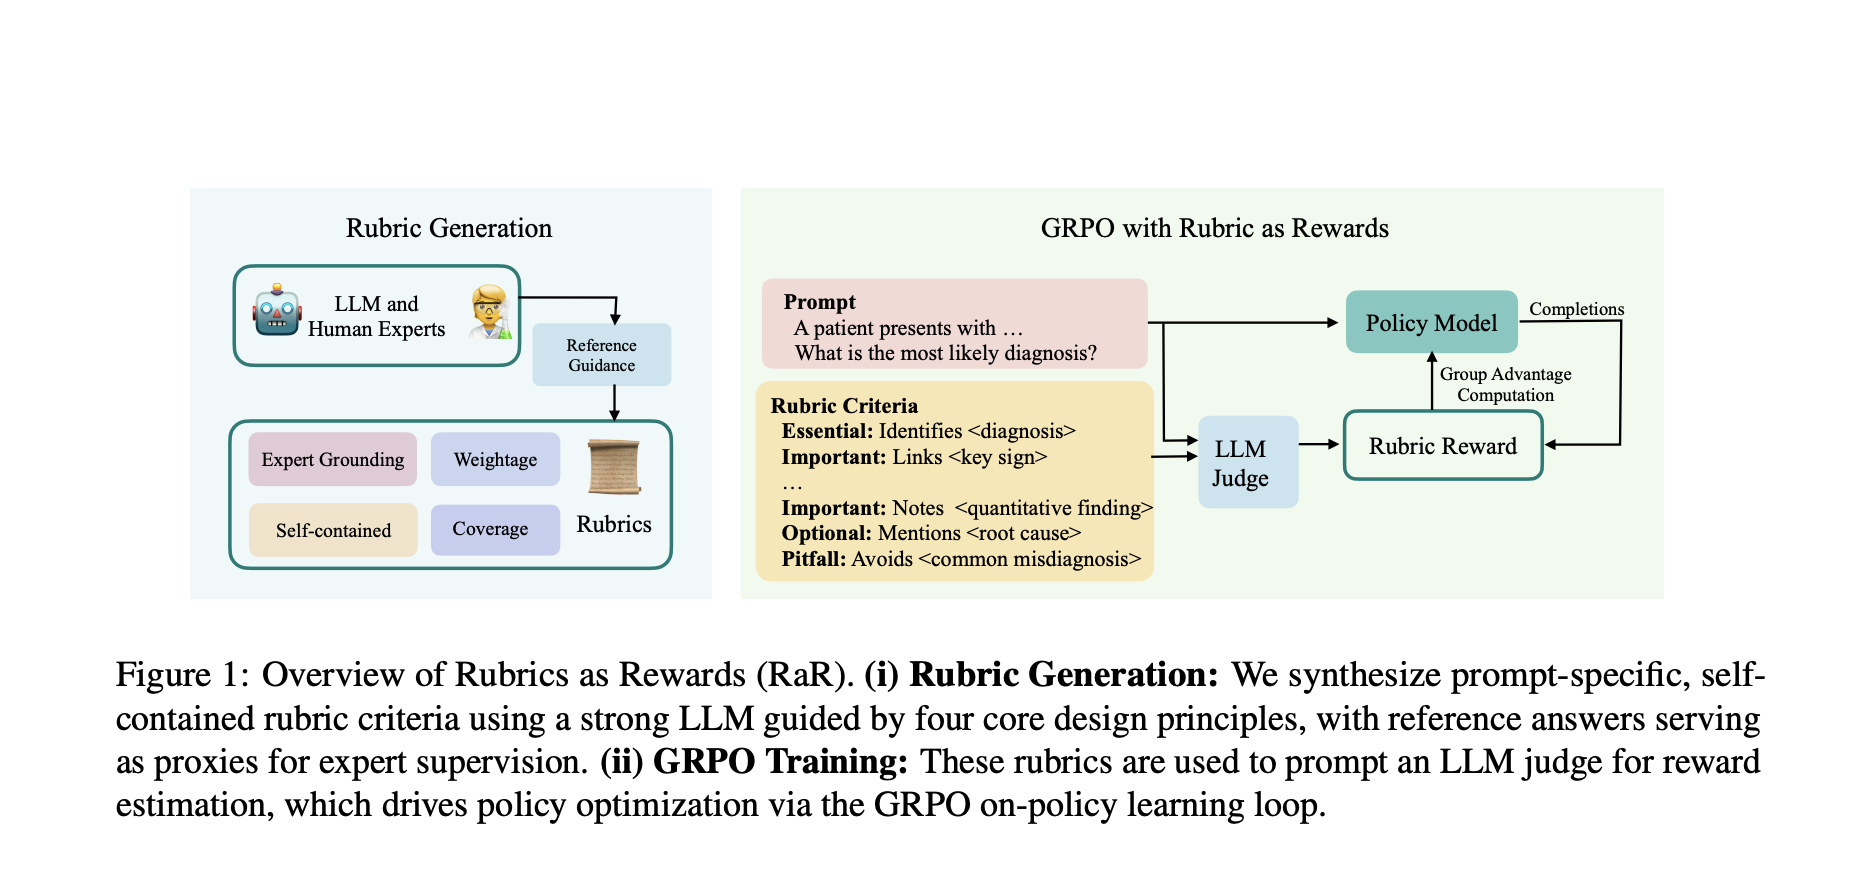
Researchers from Scale AI have proposed Rubrics as Rewards (RaR), an on-policy reinforcement learning framework that utilizes checklist-style rubrics to guide multi-criteria tasks.     The method generates prompt-specific rubrics based on carefully designed principles, where each rubric outlines clear standards for high-quality responses and provides human-interpretable supervision signals. Moreover, it is applied to medicine and science domains, resulting in two specialized training datasets, RaR-Medicine-20k and RaR-Science-20k. RaR enables smaller judge models to achieve superior alignment with human preferences by transforming rubrics into structured reward signals while maintaining robust performance across different model scales.
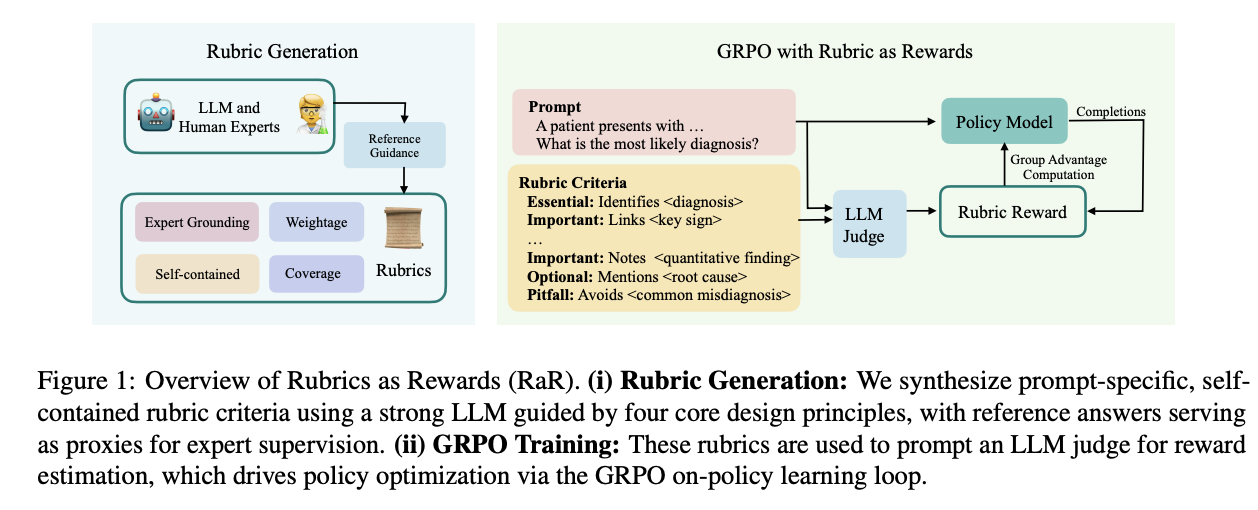
Researchers used LLMs as expert proxies to generate these rubrics, ensuring adherence to the following desiderata: grounded in expert guidance, comprehensive coverage, semantic weighting, and self-contained evaluation. For each domain, specialized prompts instruct the LLM to generate 7-20 rubric items based on the complexity of the input question. Each item is assigned categorical weights, such as Essential Criteria or Important Criteria, to determine its significance for correct answers. The training utilizes the GRPO algorithm with Qwen2.5-7B as the base policy model. Moreover, the training pipeline operates through three core components: Response Generation, Reward Computation, and Policy Update. 

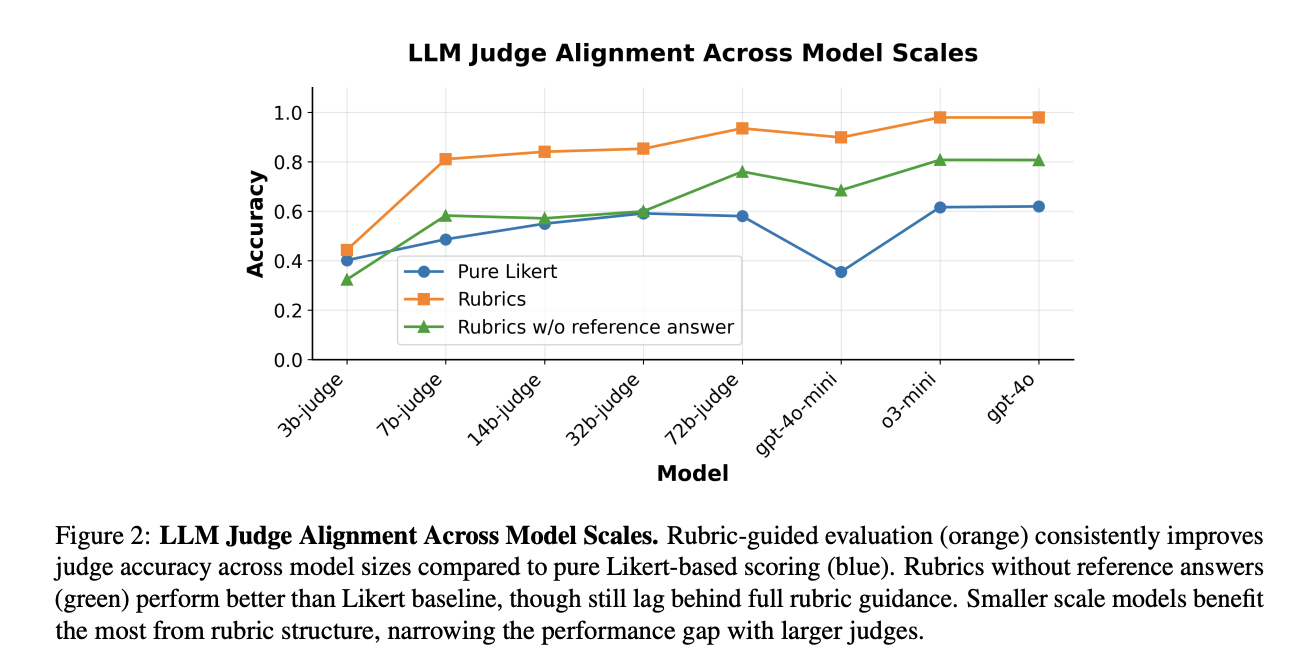
The RaR-Implicit method outperforms baseline methods such as Simple-Likert, with the best variant achieving up to 28% relative improvement on HealthBench-1k and 13% on GPQA.   It also outperforms both base and instruction-tuned policy models, showing the effectiveness of rubric-guided training for nuanced response evaluation while matching or exceeding Reference-Likert baseline performance. Beyond raw metrics, rubric-guided evaluations provide clearer and more accurate signals across model scales, achieving higher accuracy when preferred responses receive appropriate ratings. Moreover, expert guidance proves essential for synthetic rubric generation, with rubrics developed using reference answers achieving higher accuracy than those without human insights.
In summary, researchers introduced RaR that advances post-training of language models by using structured, checklist-style rubrics as reward signals. It offers stable training signals, maintaining human interpretability and alignment. However, this research remains limited to medical and science domains, requiring validation across tasks such as open-ended dialogue. Researchers explored only two reward aggregation strategies, implicit and explicit, leaving the alternative weighting schemes. Moreover, they did not conduct a controlled analysis of reward hacking risks, and the reliance on off-the-shelf LLMs as judges suggests future work could benefit from dedicated evaluators with enhanced reasoning capabilities.


Check out the Paper here. All credit for this research goes to the researchers of this project. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.

Sajjad Ansari is a final year undergraduate from IIT Kharagpur. As a Tech enthusiast, he delves into the practical applications of AI with a focus on understanding the impact of AI technologies and their real-world implications. He aims to articulate complex AI concepts in a clear and accessible manner.
Credit: Source link

ShareTweetSendSharePin

Related Posts

Here’s Why Apple’s Mac Studio Has Become So Expensive
AI & Technology

Here’s Why Apple’s Mac Studio Has Become So Expensive

September 21, 2026
Tesla Will Soon Roll Out FSD Supervised In The Czech Republic
AI & Technology

Tesla Will Soon Roll Out FSD Supervised In The Czech Republic

September 21, 2026
Alibaba Qwen Releases Qwen-Image-2.1: A 7B Open-Weight Model for Image Generation and Editing
AI & Technology

Alibaba Qwen Releases Qwen-Image-2.1: A 7B Open-Weight Model for Image Generation and Editing

September 21, 2026
Collaboration Must Sit At the Heart of Manufacturing’s Multi-Agentic AI Approach. Here’s How. – Unite.AI
AI & Technology

Collaboration Must Sit At the Heart of Manufacturing’s Multi-Agentic AI Approach. Here’s How. – Unite.AI

September 21, 2026
Next Post
Wisconsin couple speaks on winning wife-carrying competition

Wisconsin couple speaks on winning wife-carrying competition

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
iPhone 18 Pro Review: The Standard Setter

iPhone 18 Pro Review: The Standard Setter

September 16, 2026
Duane Davis found guilty of murder in Tupac’s death

Duane Davis found guilty of murder in Tupac’s death

September 20, 2026
Kathmandu hospital walls fill with missing faces following Nepal floods

Kathmandu hospital walls fill with missing faces following Nepal floods

September 21, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!