• bitcoinBitcoin(BTC)$84,276.00-2.31%
  • ethereumEthereum(ETH)$2,671.45-2.82%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$765.28-2.52%
  • rippleXRP(XRP)$1.49-5.77%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$114.12-3.24%
  • tronTRON(TRX)$0.340375-0.39%
  • zcashZcash(ZEC)$1,497.66-1.53%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-1.06%
  • HyperliquidHyperliquid(HYPE)$92.66-3.85%
  • dogecoinDogecoin(DOGE)$0.091981-8.02%
  • moneroMonero(XMR)$552.21-2.48%
  • whitebitWhiteBIT Coin(WBT)$84.49-2.55%
  • USDSUSDS(USDS)$1.00-0.01%
  • chainlinkChainlink(LINK)$12.22-5.59%
  • cardanoCardano(ADA)$0.236878-6.08%
  • RainRain(RAIN)$0.012235-6.51%
  • leo-tokenLEO Token(LEO)$8.97-0.12%
  • stellarStellar(XLM)$0.200842-6.83%
  • bitcoin-cashBitcoin Cash(BCH)$336.69-1.22%
  • uniswapUniswap(UNI)$9.14-2.49%
  • nearNEAR Protocol(NEAR)$4.330.74%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • litecoinLitecoin(LTC)$60.95-2.25%
  • daiDai(DAI)$1.000.00%
  • avalanche-2Avalanche(AVAX)$10.29-6.61%
  • USD1USD1(USD1)$1.000.02%
  • CantonCanton(CC)$0.108993-3.73%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.41-3.05%
  • hedera-hashgraphHedera(HBAR)$0.089913-9.60%
  • suiSui(SUI)$0.96-5.00%
  • shiba-inuShiba Inu(SHIB)$0.000006-7.60%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • BittensorBittensor(TAO)$286.17-7.09%
  • crypto-com-chainCronos(CRO)$0.061215-7.61%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • BitwayBitway(BTW)$1.0217.43%
  • MemeCoreMemeCore(M)$1.21-7.30%
  • tether-goldTether Gold(XAUT)$4,286.62-1.62%
  • okbOKB(OKB)$117.89-3.80%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.04%
  • mantleMantle(MNT)$0.65-2.56%
  • aaveAave(AAVE)$137.94-4.48%
  • EthenaEthena(ENA)$0.204358-2.16%
  • OndoOndo(ONDO)$0.410056-5.61%
  • Pump.funPump.fun(PUMP)$0.004013-10.50%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Researchers from Princeton and Meta AI Introduce ‘Lory’: A Fully-Differentiable MoE Model Designed for Autoregressive Language Model Pre-Training

May 12, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Researchers from Princeton and Meta AI Introduce ‘Lory’: A Fully-Differentiable MoE Model Designed for Autoregressive Language Model Pre-Training
ShareShareShareShareShare

Mixture-of-experts (MoE) architectures use sparse activation to initial the scaling of model sizes while preserving high training and inference efficiency. However, training the router network creates the challenge of optimizing a non-differentiable, discrete objective despite the efficient scaling by MoE models. Recently, an MoE architecture called SMEAR was introduced, which is fully non-differentiable and merges experts gently in the parameter space. SMEAR is very efficient, but its effectiveness is limited to small-scale fine-tuning experiments on downstream classification tasks.

Sparsely activated MoE models have emerged as a useful method to scale up model sizes efficiently. The sparse MoE architecture is adapted into transformer models to achieve better performance on machine translation. Traditional MoE models are trained to route input data to expert modules, resulting in a non-differentiable, discrete decision-learning problem problem. Further, top-1 or top-2 routing strategies are used to train these existing models based on a designed load-balancing objective. MoE models are complicated when trained, creating the problem of training instability, expert under-specialization, and inefficient training.

Researchers from Princeton University and Meta AI introduced Lory, a method to scale MoE architectures to autoregressive language model pre-training. Lory consists of two main techniques: (a) a casual segment routing strategy that is efficient in expert merging operations while maintaining the autoregressive nature of language models (LMs), and (b) a similarity-based data batching method that supports expert specialization by creating groups for similar documents during training. Also, Lory models outperform state-of-the-art MoE models with the help of token-level routing instead of segment-level routing.

Casual segment routing, the first technique, is split into smaller segments with a fixed length for a sequence of input tokens. The original segment is used to get the router’s weight and evaluate the merged expert for the subsequent segment. The segment-level routing made using prompts during inference can lead to insufficient specialization of experts because the text data for pre-training language models usually merges random sets of documents. So, the second technique, i.e., similarity-based data batching for MoE training, overcomes this challenge by grouping similar documents to create sequential segments. This technique is used to train LMs, which results in efficient training for expert routing.

Lory shows outstanding results for various factors. They are:

  • Training efficiency and convergence: Lory achieves an equivalent loss level with less than half of the training tokens for 0.3B and 1.5B models, indicating better performance with the same training compute. 
  • Language modeling: Proposed MoE models outperform the dense baseline in all domains, leading to a decrease in perplexity. For example, compared to the 0.3B dense model, 0.3B/32E  models achieve a relative improvement of 13.9% on Books.
  • Downstream tasks: The 0.3B/32E model achieves an average performance increase of +3.7% in common sense reasoning, +3.3% in reading comprehension, +1.5% in reading comprehension, and +11.1% in text classification.

In conclusion, Princeton University and Meta AI researchers proposed Lory, a fully differentiable MoE model designed for autoregressive language model pre-training. Lory consists of two main techniques: a casual segment routing strategy and a similarity-based data batching method. The proposed method outperforms its dense counterpart on language modeling and downstream tasks, and the trained experts are highly specialized and capable of capturing domain-level information. Future work includes scaling up Lory and integrating token and segment-level routing by developing efficient decoding methods for Lory.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 42k+ ML SubReddit

YOU MAY ALSO LIKE

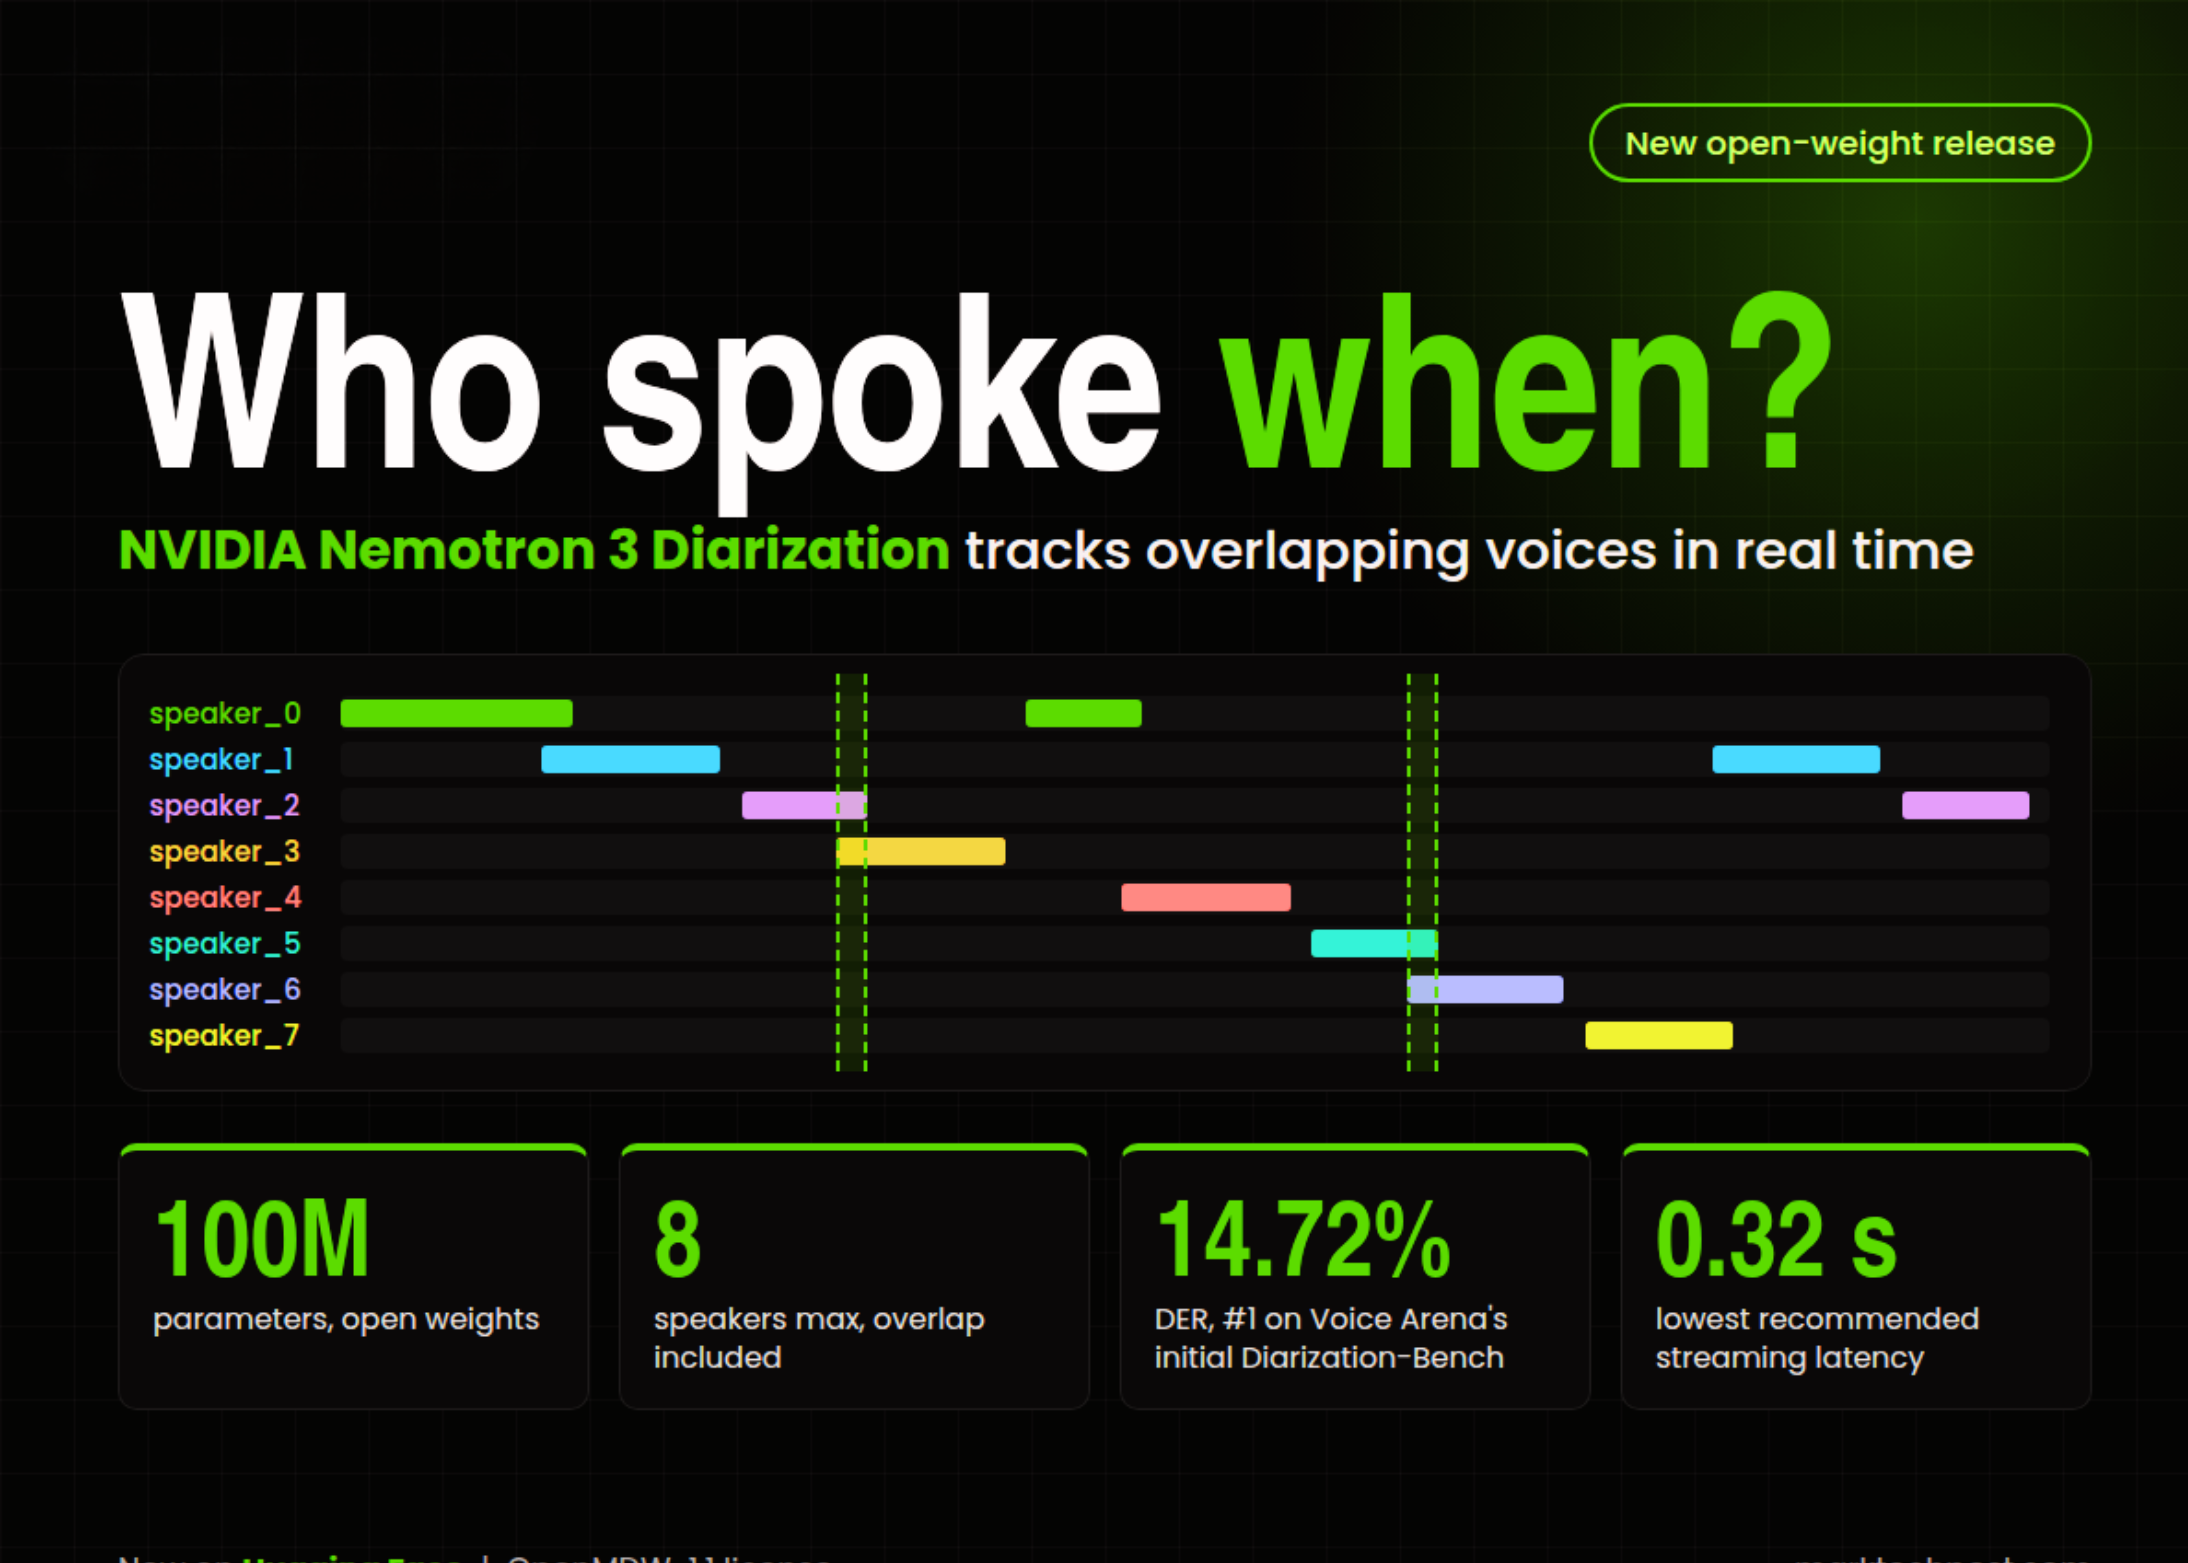
NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time

Disney+ And Hulu Are Getting Even More Expensive (Again)

Sajjad Ansari is a final year undergraduate from IIT Kharagpur. As a Tech enthusiast, he delves into the practical applications of AI with a focus on understanding the impact of AI technologies and their real-world implications. He aims to articulate complex AI concepts in a clear and accessible manner.


[Recommended Read] Rightsify’s GCX: Your Go-To Source for High-Quality, Ethically Sourced, Copyright-Cleared AI Music Training Datasets with Rich Metadata


Credit: Source link

ShareTweetSendSharePin

Related Posts

NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time
AI & Technology

NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time

September 23, 2026
Disney+ And Hulu Are Getting Even More Expensive (Again)
AI & Technology

Disney+ And Hulu Are Getting Even More Expensive (Again)

September 23, 2026
Logitech’s Yeti 2 Brings The 17-Year-Old USB Mic Into The Modern Age
AI & Technology

Logitech’s Yeti 2 Brings The 17-Year-Old USB Mic Into The Modern Age

September 23, 2026
Never Use ChatGPT For These Five Tasks
AI & Technology

Never Use ChatGPT For These Five Tasks

September 23, 2026
Next Post
Scalping Master Class: Make 0 a Day in 90 Minutes

Scalping Master Class: Make $250 a Day in 90 Minutes

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Thieves steal royal necklace from Vienna museum

Thieves steal royal necklace from Vienna museum

September 20, 2026
Europe’s EU Kids Act Would Ban Social Media Access For Children Under 13

Europe’s EU Kids Act Would Ban Social Media Access For Children Under 13

September 17, 2026
New Jev Model Acts in Real Time… Minecraft Broke It

New Jev Model Acts in Real Time… Minecraft Broke It

September 19, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!