NVIDIA has released its Streaming Sortformer, a breakthrough in real-time speaker diarization that instantly identifies and labels participants in meetings, calls, and voice-enabled applications—even in noisy, multi-speaker environments. Designed for low-latency, GPU-powered inference, the model is optimized for English and Mandarin, and can track up to four simultaneous speakers with millisecond-level precision. This innovation marks a major step forward in conversational AI, enabling a new generation of productivity, compliance, and interactive voice applications.
Core Capabilities: Real-Time, Multi-Speaker Tracking
Unlike traditional diarization systems that require batch processing or expensive, specialized hardware, Streaming Sortformer performs frame-level diarization in real time. That means every utterance is tagged with a speaker label (e.g., spk_0, spk_1) and a precise timestamp as the conversation unfolds. The model is low-latency, processing audio in small, overlapping chunks—a critical feature for live transcriptions, smart assistants, and contact center analytics where every millisecond counts.
- Labels 2–4+ speakers on the fly: Robustly tracks up to four participants per conversation, assigning consistent labels as each speaker enters the stream.
- GPU-accelerated inference: Fully optimized for NVIDIA GPUs, integrating seamlessly with the NVIDIA NeMo and NVIDIA Riva platforms for scalable, production deployment.
- Multilingual support: While tuned for English, the model shows strong results on Mandarin meeting data and even non-English datasets like CALLHOME, indicating broad language compatibility beyond its core targets.
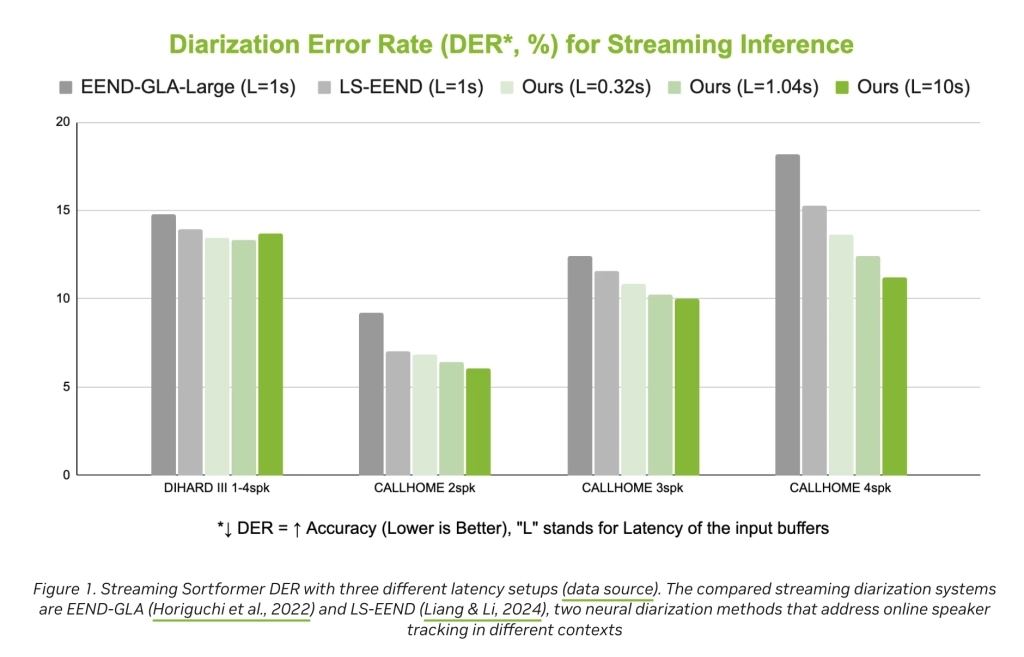
- Precision and reliability: Delivers a competitive Diarization Error Rate (DER), outperforming recent alternatives like EEND-GLA and LS-EEND in real-world benchmarks.
These capabilities make Streaming Sortformer immediately useful for live meeting transcripts, contact center compliance logs, voicebot turn-taking, media editing, and enterprise analytics—all scenarios where knowing “who said what, when” is essential.
Architecture and Innovation
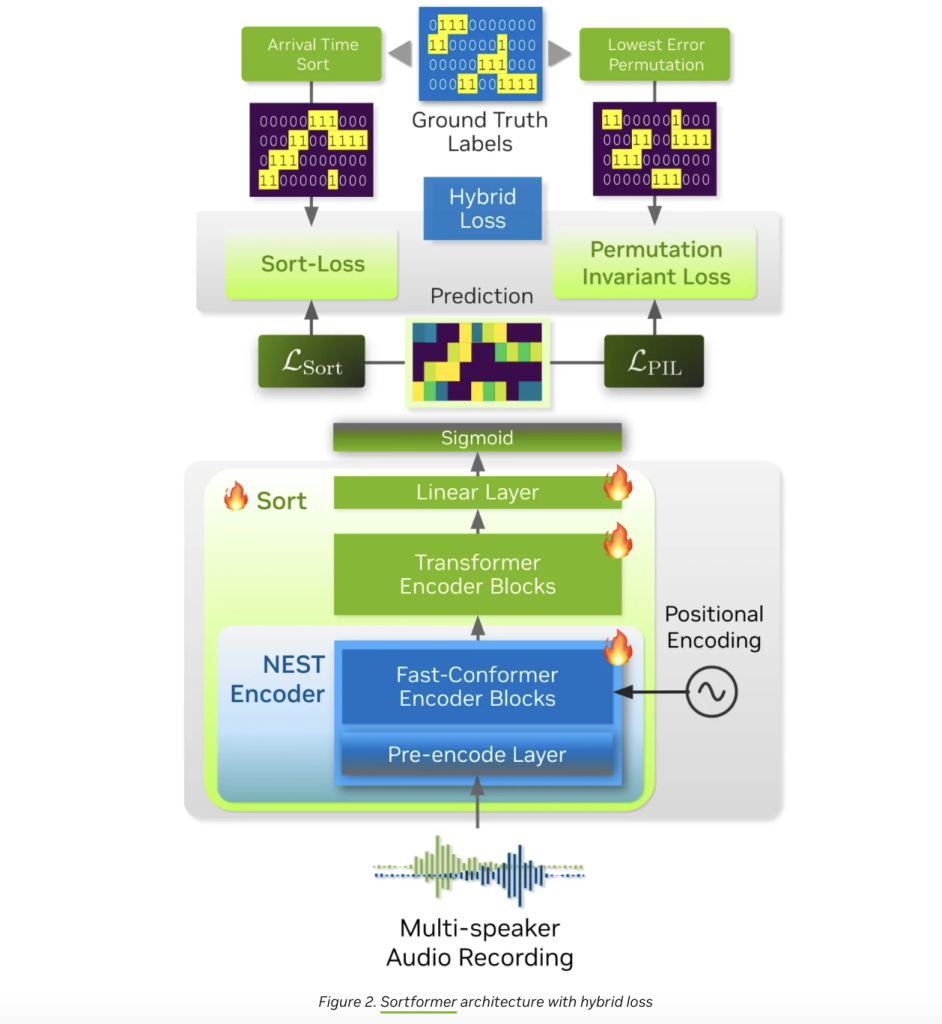
At its core, Streaming Sortformer is a hybrid neural architecture, combining the strengths of Convolutional Neural Networks (CNNs), Conformers, and Transformers. Here’s how it works:
- Audio pre-processing: A convolutional pre-encode module compresses raw audio into a compact representation, preserving critical acoustic features while reducing computational overhead.
- Context-aware sorting: A multi-layer Fast-Conformer encoder (17 layers in the streaming variant) processes these features, extracting speaker-specific embeddings. These are then fed into an 18-layer Transformer encoder with a hidden size of 192, followed by two feedforward layers with sigmoid outputs for each frame.
- Arrival-Order Speaker Cache (AOSC): The real magic happens here. Streaming Sortformer maintains a dynamic memory buffer—AOSC—that stores embeddings of all speakers detected so far. As new audio chunks arrive, the model compares them against this cache, ensuring that each participant retains a consistent label throughout the conversation. This elegant solution to the “speaker permutation problem” is what enables real-time, multi-speaker tracking without expensive recomputation.
- End-to-end training: Unlike some diarization pipelines that rely on separate voice activity detection and clustering steps, Sortformer is trained end-to-end, unifying speaker separation and labeling in a single neural network.
Integration and Deployment
Streaming Sortformer is open, production-grade, and ready for integration into existing workflows. Developers can deploy it via NVIDIA NeMo or Riva, making it a drop-in replacement for legacy diarization systems. The model accepts standard 16kHz mono-channel audio (WAV files) and outputs a matrix of speaker activity probabilities for each frame—ideal for building custom analytics or transcription pipelines.
Real-World Applications
The practical impact of Streaming Sortformer is vast:
- Meetings and productivity: Generate live, speaker-tagged transcripts and summaries, making it easier to follow discussions and assign action items.
- Contact centers: Separate agent and customer audio streams for compliance, quality assurance, and real-time coaching.
- Voicebots and AI assistants: Enable more natural, context-aware dialogues by accurately tracking speaker identity and turn-taking patterns.
- Media and broadcast: Automatically label speakers in recordings for editing, transcription, and moderation workflows.
- Enterprise compliance: Create auditable, speaker-resolved logs for regulatory and legal requirements.
Benchmark Performance and Limitations
In benchmarks, Streaming Sortformer achieves a lower Diarization Error Rate (DER) than recent streaming diarization systems, indicating higher accuracy in real-world conditions. However, the model is currently optimized for scenarios with up to four speakers; expanding to larger groups remains an area for future research. Performance may also vary in challenging acoustic environments or with underrepresented languages, though the architecture’s flexibility suggests room for adaptation as new training data becomes available.
Technical Highlights at a Glance
| Feature | Streaming Sortformer |
|---|---|
| Max speakers | 2–4+ |
| Latency | Low (real-time, frame-level) |
| Languages | English (optimized), Mandarin (validated), others possible |
| Architecture | CNN + Fast-Conformer + Transformer + AOSC |
| Integration | NVIDIA NeMo, NVIDIA Riva, Hugging Face |
| Output | Frame-level speaker labels, precise timestamps |
| GPU Support | Yes (NVIDIA GPUs required) |
| Open Source | Yes (pre-trained models, codebase) |
Looking Ahead
NVIDIA’s Streaming Sortformer is not just a technical demo—it’s a production-ready tool already changing how enterprises, developers, and service providers handle multi-speaker audio. With GPU acceleration, seamless integration, and robust performance across languages, it’s poised to become the de facto standard for real-time speaker diarization in 2025 and beyond.
For AI managers, content creators, and digital marketers focused on conversational analytics, cloud infrastructure, or voice applications, Streaming Sortformer is a must-evaluate platform. Its combination of speed, accuracy, and ease of deployment makes it a compelling choice for anyone building the next generation of voice-enabled products.
Summary
NVIDIA’s Streaming Sortformer delivers instant, GPU-accelerated speaker diarization for up to four participants, with proven results in English and Mandarin. Its novel architecture and open accessibility position it as a foundational technology for real-time voice analytics—a leap forward for meetings, contact centers, AI assistants, and beyond.
FAQs: NVIDIA Streaming Sortformer
How does Streaming Sortformer handle multiple speakers in real time?
Streaming Sortformer processes audio in small, overlapping chunks and assigns consistent labels (e.g., spk_0–spk_3) as each speaker enters the conversation. It maintains a lightweight memory of detected speakers, enabling instant, frame-level diarization without waiting for the full recording. This supports fluid, low-latency experiences for live transcripts, contact centers, and voice assistants.
What hardware and setup are recommended for best performance?
It’s designed for NVIDIA GPUs to achieve low-latency inference. A typical setup uses 16 kHz mono audio input, with integration paths through NVIDIA’s speech AI stacks (e.g., NeMo/Riva) or the available pretrained models. For production workloads, allocate a recent NVIDIA GPU and ensure streaming-friendly audio buffering (e.g., 20–40 ms frames with slight overlap).
Does it support languages beyond English, and how many speakers can it track?
The current release targets English with validated performance on Mandarin and can label two to four speakers on the fly. While it can generalize to other languages to some extent, accuracy depends on acoustic conditions and training coverage. For scenarios with more than four concurrent speakers, consider segmenting the session or evaluating pipeline adjustments as model variants evolve.
Check out the Model on Hugging Face and Technical details here. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.
Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
Credit: Source link