• bitcoinBitcoin(BTC)$84,380.00-2.42%
  • ethereumEthereum(ETH)$2,687.13-2.61%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$772.91-2.47%
  • rippleXRP(XRP)$1.51-5.31%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$115.40-2.47%
  • tronTRON(TRX)$0.343467-0.29%
  • zcashZcash(ZEC)$1,519.13-6.02%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.040.37%
  • HyperliquidHyperliquid(HYPE)$92.83-4.30%
  • dogecoinDogecoin(DOGE)$0.093944-9.10%
  • moneroMonero(XMR)$556.02-1.74%
  • whitebitWhiteBIT Coin(WBT)$84.74-2.40%
  • USDSUSDS(USDS)$1.000.00%
  • chainlinkChainlink(LINK)$12.38-5.30%
  • cardanoCardano(ADA)$0.240288-5.92%
  • RainRain(RAIN)$0.012227-6.86%
  • leo-tokenLEO Token(LEO)$8.95-0.27%
  • stellarStellar(XLM)$0.202557-7.33%
  • bitcoin-cashBitcoin Cash(BCH)$342.280.15%
  • uniswapUniswap(UNI)$9.39-12.61%
  • nearNEAR Protocol(NEAR)$4.381.24%
  • litecoinLitecoin(LTC)$65.964.82%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • daiDai(DAI)$1.000.01%
  • avalanche-2Avalanche(AVAX)$10.32-8.10%
  • USD1USD1(USD1)$1.00-0.01%
  • CantonCanton(CC)$0.109750-4.05%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.42-3.04%
  • hedera-hashgraphHedera(HBAR)$0.090891-9.44%
  • suiSui(SUI)$0.97-5.37%
  • shiba-inuShiba Inu(SHIB)$0.000006-7.33%
  • BittensorBittensor(TAO)$289.24-7.47%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • crypto-com-chainCronos(CRO)$0.061637-9.72%
  • BitwayBitway(BTW)$1.0415.65%
  • MemeCoreMemeCore(M)$1.24-4.97%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,291.46-1.00%
  • okbOKB(OKB)$119.56-3.68%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.16%
  • mantleMantle(MNT)$0.66-4.15%
  • aaveAave(AAVE)$139.41-6.01%
  • EthenaEthena(ENA)$0.208247-3.76%
  • OndoOndo(ONDO)$0.418043-5.18%
  • AsterAster(ASTER)$0.70-4.63%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Metron: A Holistic AI Framework for Evaluating User-Facing Performance in LLM Inference Systems

July 14, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Metron: A Holistic AI Framework for Evaluating User-Facing Performance in LLM Inference Systems
ShareShareShareShareShare

Evaluating the performance of large language model (LLM) inference systems using conventional metrics presents significant challenges. Metrics such as Time To First Token (TTFT) and Time Between Tokens (TBT) do not capture the complete user experience during real-time interactions. This gap is critical in applications like chat and translation, where responsiveness directly affects user satisfaction. There is a need for a more nuanced evaluation framework that fully encapsulates the intricacies of LLM inference to ensure optimal deployment and performance in real-world scenarios.

Current methods for evaluating LLM inference performance include TTFT, TBT, normalized latency, and Time Per Output Token (TPOT). These metrics assess various aspects of latency and throughput but fall short in providing a comprehensive view of the user experience. For example, TTFT and TBT focus on individual token latencies without considering end-to-end throughput, while normalized metrics obscure issues like inter-token jitter and scheduling delays. These limitations hinder their effectiveness in real-time applications where maintaining a smooth and consistent token generation rate is crucial.

YOU MAY ALSO LIKE

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model

Everything Announced At Meta Connect 2026

A team of researchers from Georgia Institute of Technology, Microsoft Research India, and Intel AI Lab propose Metron, a comprehensive performance evaluation framework. Metron introduces novel metrics such as the fluidity-index and fluid token generation rate, which capture the nuances of real-time, streaming LLM interactions. These metrics consider the temporal aspects of token generation, ensuring a more accurate reflection of user-facing performance. By setting token-level deadlines and measuring the fraction of deadlines met, the fluidity-index provides a precise definition of user experience constraints. This approach represents a significant contribution by offering a more accurate and user-centric evaluation method.

Metron’s fluidity-index metric sets deadlines for token generation based on desired TTFT and TBT values, adjusting these based on prompt length and observed system performance. This method accounts for scheduling delays and variable token generation rates, ensuring smooth output. The framework evaluates both open-source and proprietary LLM inference systems, applying the fluidity-index to measure the percentage of deadlines met and dynamically adjusting deadlines based on real-time performance. This method offers a comprehensive view of the system’s capacity to handle user requests without compromising responsiveness.

Metron provides a more accurate evaluation of LLM inference systems compared to conventional metrics. The fluidity-index and fluid token generation rate reveal significant differences in user experience that are not captured by TTFT or TBT alone. For example, the evaluation of systems like vLLM and Sarathi-Serve demonstrated that Sarathi-Serve achieved fewer deadline misses and higher fluidity. The findings show that Sarathi-Serve maintained a fluidity-index > 0.9 for 99% of requests, achieving a throughput of 600 tokens per second, while vLLM showed a 3x worse tail TBT due to generation stalls. This demonstrates Metron’s effectiveness in revealing performance differences and ensuring better user experiences in real-world applications.
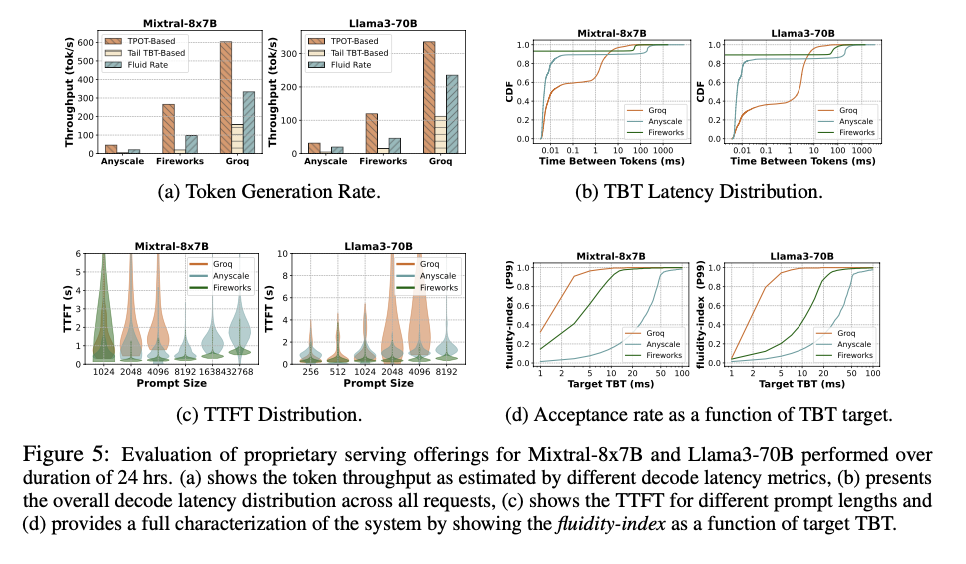
In conclusion, this proposed method, Metron, introduces a novel evaluation framework, including the fluidity-index and fluid token generation rate metrics, to better assess LLM inference performance. This approach overcomes the limitations of conventional metrics by providing a user-centric evaluation that captures the intricacies of real-time token generation. The findings demonstrate Metron’s effectiveness in revealing performance differences and its potential impact on improving LLM serving frameworks, ensuring better user experiences in real-world applications.


Check out the Paper and GitHub. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 46k+ ML SubReddit

Aswin AK is a consulting intern at MarkTechPost. He is pursuing his Dual Degree at the Indian Institute of Technology, Kharagpur. He is passionate about data science and machine learning, bringing a strong academic background and hands-on experience in solving real-life cross-domain challenges.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model
AI & Technology

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model

September 24, 2026
Everything Announced At Meta Connect 2026
AI & Technology

Everything Announced At Meta Connect 2026

September 24, 2026
Meta Brings FDA-Cleared Hearing Enhancement To Its Smart Glasses
AI & Technology

Meta Brings FDA-Cleared Hearing Enhancement To Its Smart Glasses

September 23, 2026
Microsoft’s New Surface Pro 12 And Surface Laptop 13 Feature Snapdragon X2 Plus Chips
AI & Technology

Microsoft’s New Surface Pro 12 And Surface Laptop 13 Feature Snapdragon X2 Plus Chips

September 23, 2026
Next Post
Arena Learning: Transforming Post-Training of Large Language Models with AI-Powered Simulated Battles for Enhanced Efficiency and Performance in Natural Language Processing

Arena Learning: Transforming Post-Training of Large Language Models with AI-Powered Simulated Battles for Enhanced Efficiency and Performance in Natural Language Processing

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Financial Winter Ahead? Stocks to Buy and Trim Now

Financial Winter Ahead? Stocks to Buy and Trim Now

September 17, 2026
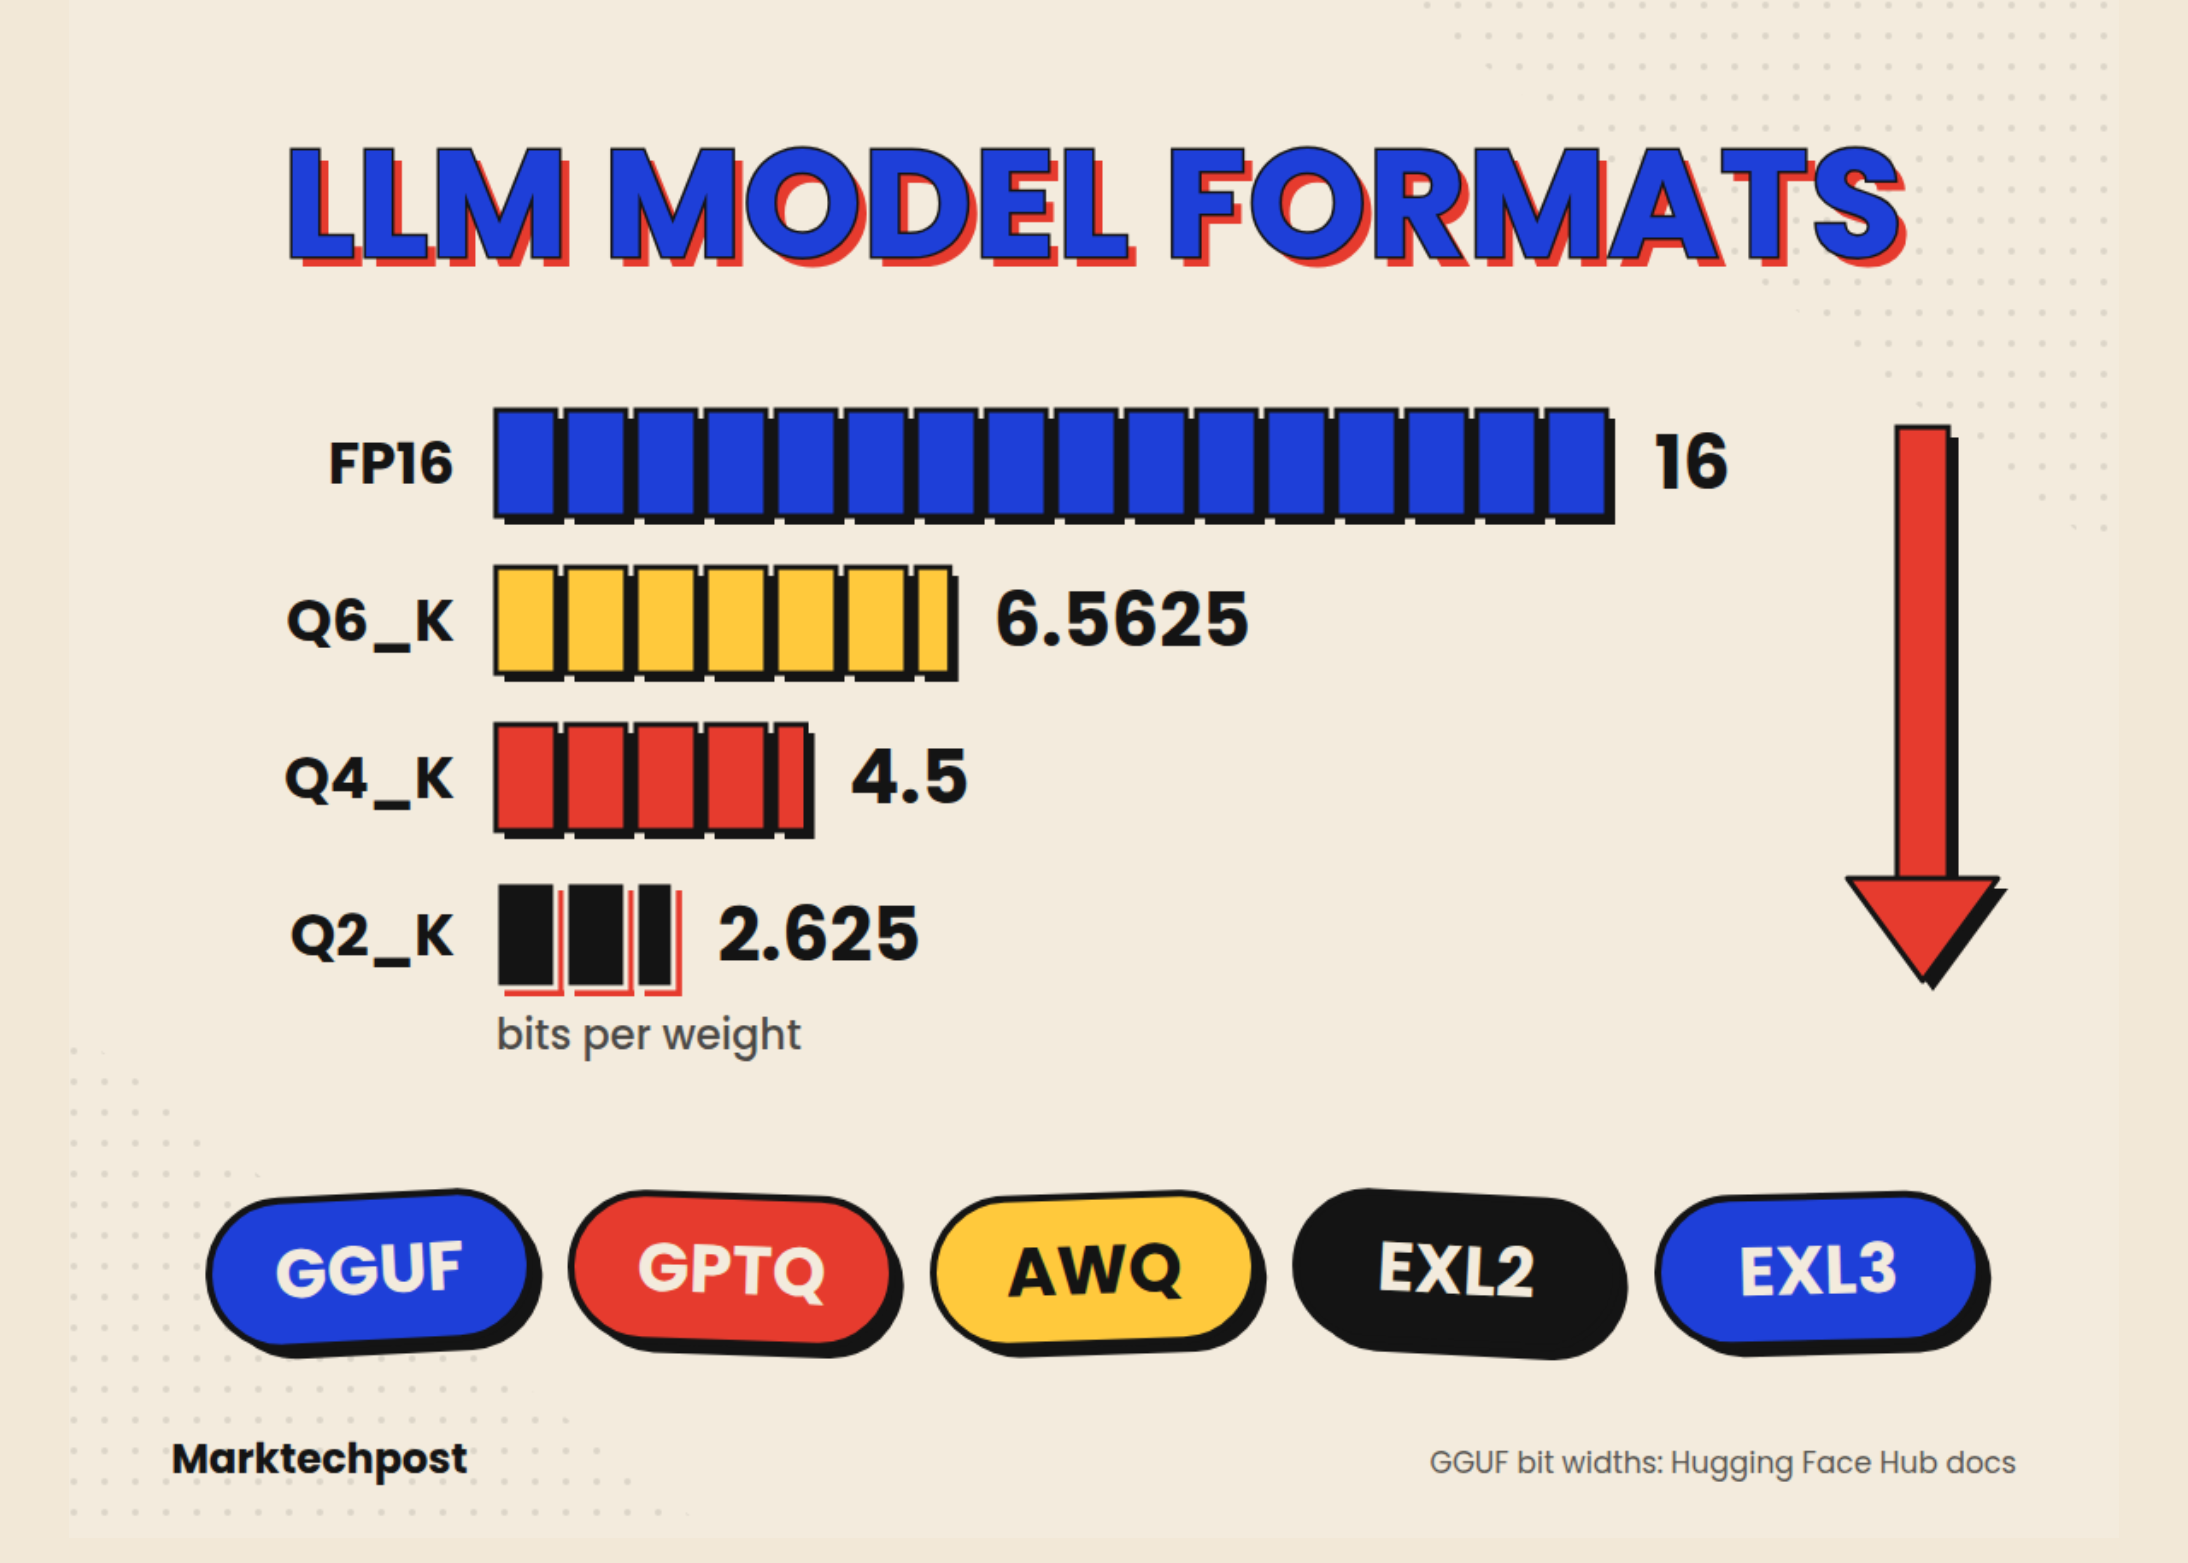
GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

September 19, 2026
How vote breakdown of Clancy jury will influence legal strategy in retrial

How vote breakdown of Clancy jury will influence legal strategy in retrial

September 17, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!