
• bitcoinBitcoin(BTC)$77,069.000.21%
  • ethereumEthereum(ETH)$2,264.560.42%
  • tetherTether(USDT)$1.000.03%
  • binancecoinBNB(BNB)$693.68-0.88%
  • rippleXRP(XRP)$1.260.76%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$91.92-0.33%
  • tronTRON(TRX)$0.3216110.62%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.20%
  • zcashZcash(ZEC)$1,206.034.50%
  • HyperliquidHyperliquid(HYPE)$84.380.04%
  • moneroMonero(XMR)$628.153.46%
  • dogecoinDogecoin(DOGE)$0.0744250.02%
  • USDSUSDS(USDS)$1.00-0.01%
  • whitebitWhiteBIT Coin(WBT)$74.060.19%
  • leo-tokenLEO Token(LEO)$9.30-1.09%
  • chainlinkChainlink(LINK)$10.92-2.34%
  • cardanoCardano(ADA)$0.188152-0.75%
  • stellarStellar(XLM)$0.159758-1.88%
  • bitcoin-cashBitcoin Cash(BCH)$272.62-1.63%
  • nearNEAR Protocol(NEAR)$3.81-2.13%
  • RainRain(RAIN)$0.006613-3.64%
  • Ethena USDeEthena USDe(USDE)$1.000.11%
  • daiDai(DAI)$1.000.03%
  • uniswapUniswap(UNI)$7.150.08%
  • litecoinLitecoin(LTC)$53.62-0.82%
  • CantonCanton(CC)$0.0959191.80%
  • USD1USD1(USD1)$1.000.12%
  • avalanche-2Avalanche(AVAX)$8.450.23%
  • suiSui(SUI)$0.880.64%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.17-1.31%
  • tether-goldTether Gold(XAUT)$3,930.21-0.28%
  • hedera-hashgraphHedera(HBAR)$0.068990-1.20%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • quant-networkQuant(QNT)$190.82-2.04%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.02%
  • shiba-inuShiba Inu(SHIB)$0.000005-0.15%
  • BittensorBittensor(TAO)$223.45-0.48%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • crypto-com-chainCronos(CRO)$0.049959-0.54%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.01%
  • EthenaEthena(ENA)$0.170587-0.89%
  • okbOKB(OKB)$107.25-2.25%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.000005-0.06%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • MemeCoreMemeCore(M)$0.861.08%
  • Pump.funPump.fun(PUMP)$0.0042606.50%
  • aaveAave(AAVE)$126.03-0.71%
  • OndoOndo(ONDO)$0.384879-1.20%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Korean AI startup Motif reveals 4 big lessons for training enterprise LLMs

December 15, 2025
in AI & Technology
Reading Time: 3 mins read
A A
Korean AI startup Motif reveals 4 big lessons for training enterprise LLMs
ShareShareShareShareShare

We’ve heard (and written, here at VentureBeat) lots about the generative AI race between the U.S. and China, as those have been the countries with the groups most active in fielding new models (with a shoutout to Cohere in Canada and Mistral in France).

YOU MAY ALSO LIKE

Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI

Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’

But now a Korean startup is making waves: last week, the firm known as Motif Technologies released Motif-2-12.7B-Reasoning, another small parameter open-weight model that boasts impressive benchmark scores, quickly becoming the most performant model from that country according to independent benchmarking lab Artificial Analysis (beating even regular GPT-5.1 from U.S. leader OpenAI).

But more importantly for enterprise AI teams, the company has published a white paper on arxiv.org with a concrete, reproducible training recipe that exposes where reasoning performance actually comes from — and where common internal LLM efforts tend to fail.

For organizations building or fine-tuning their own models behind the firewall, the paper offers a set of practical lessons about data alignment, long-context infrastructure, and reinforcement learning stability that are directly applicable to enterprise environments. Here they are:

1. Reasoning gains come from data distribution, not model size

One of Motif’s most relevant findings for enterprise teams is that synthetic reasoning data only helps when its structure matches the target model’s reasoning style.

The paper shows measurable differences in downstream coding performance depending on which “teacher” model generated the reasoning traces used during supervised fine-tuning.

For enterprises, this undermines a common shortcut: generating large volumes of synthetic chain-of-thought data from a frontier model and assuming it will transfer cleanly. Motif’s results suggest that misaligned reasoning traces can actively hurt performance, even if they look high quality.

The takeaway is operational, not academic: teams should validate that their synthetic data reflects the format, verbosity, and step granularity they want at inference time. Internal evaluation loops matter more than copying external datasets.

2. Long-context training is an infrastructure problem first

Motif trains at 64K context, but the paper makes clear that this is not simply a tokenizer or checkpointing tweak.

The model relies on hybrid parallelism, careful sharding strategies, and aggressive activation checkpointing to make long-context training feasible on Nvidia H100-class hardware.

For enterprise builders, the message is sobering but useful: long-context capability cannot be bolted on late.

If retrieval-heavy or agentic workflows are core to the business use case, context length has to be designed into the training stack from the start. Otherwise, teams risk expensive retraining cycles or unstable fine-tunes.

3. RL fine-tuning fails without data filtering and reuse

Motif’s reinforcement learning fine-tuning (RLFT) pipeline emphasizes difficulty-aware filtering — keeping tasks whose pass rates fall within a defined band — rather than indiscriminately scaling reward training.

This directly addresses a pain point many enterprise teams encounter when experimenting with RL: performance regressions, mode collapse, or brittle gains that vanish outside benchmarks. Motif also reuses trajectories across policies and expands clipping ranges, trading theoretical purity for training stability.

The enterprise lesson is clear: RL is a systems problem, not just a reward model problem. Without careful filtering, reuse, and multi-task balancing, RL can destabilize models that are otherwise production-ready.

4. Memory optimization determines what is even possible

Motif’s use of kernel-level optimizations to reduce RL memory pressure highlights an often-overlooked constraint in enterprise settings: memory, not compute, is frequently the bottleneck. Techniques like loss-function-level optimization determine whether advanced training stages are viable at all.

For organizations running shared clusters or regulated environments, this reinforces the need for low-level engineering investment, not just model architecture experimentation.

Why this matters for enterprise AI teams

Motif-2-12.7B-Reasoning is positioned as competitive with much larger models, but its real value lies in the transparency of how those results were achieved. The paper argues — implicitly but persuasively — that reasoning performance is earned through disciplined training design, not model scale alone.

For enterprises building proprietary LLMs, the lesson is pragmatic: invest early in data alignment, infrastructure, and training stability, or risk spending millions fine-tuning models that never reliably reason in production.

Credit: Source link

ShareTweetSendSharePin

Related Posts

Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI
AI & Technology

Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI

November 3, 2026
Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’
AI & Technology

Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’

November 3, 2026
Traversal Raises 0M Series B at B Valuation to Expand AI SRE – Unite.AI
AI & Technology

Traversal Raises $120M Series B at $1B Valuation to Expand AI SRE – Unite.AI

November 3, 2026
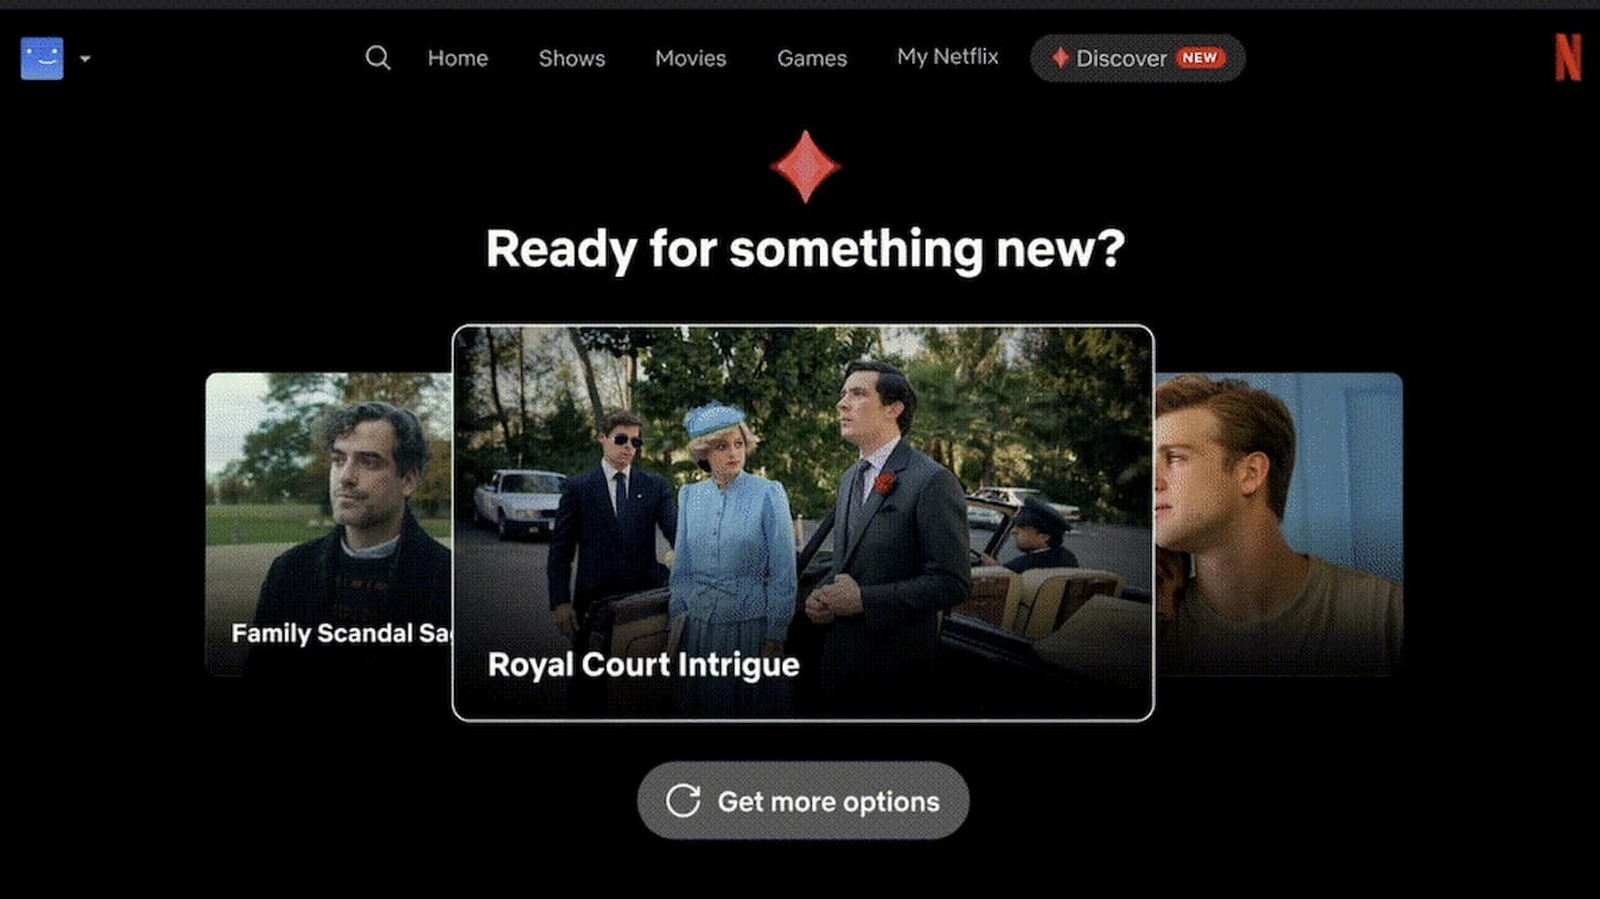
Netflix Thinks AI Might Save You From Scrolling Aimlessly For Something To Watch
AI & Technology

Netflix Thinks AI Might Save You From Scrolling Aimlessly For Something To Watch

November 3, 2026
Next Post
The 12 best last-minute Christmas gifts for 2025 that will arrive by December 24

The 12 best last-minute Christmas gifts for 2025 that will arrive by December 24

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Could Tennessee try to execute Christa Pike again?

Could Tennessee try to execute Christa Pike again?

October 29, 2026
Xi’s Corruption Purges Upend Hunt for China’s Next Top Leaders – Bloomberg.com

Xi’s Corruption Purges Upend Hunt for China’s Next Top Leaders – Bloomberg.com

October 28, 2026
Fact Checking Trump’s Drug Price Claims; Will Putin Use a Stalemate To Push Beyond Ukraine? – Oct. 8

Fact Checking Trump’s Drug Price Claims; Will Putin Use a Stalemate To Push Beyond Ukraine? – Oct. 8

October 29, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!