• bitcoinBitcoin(BTC)$85,217.004.40%
  • ethereumEthereum(ETH)$2,724.602.45%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$784.991.57%
  • rippleXRP(XRP)$1.515.07%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$116.304.02%
  • tronTRON(TRX)$0.3482961.53%
  • zcashZcash(ZEC)$1,493.18-0.29%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.011.29%
  • HyperliquidHyperliquid(HYPE)$94.16-0.04%
  • dogecoinDogecoin(DOGE)$0.09899310.77%
  • moneroMonero(XMR)$574.38-5.82%
  • whitebitWhiteBIT Coin(WBT)$85.712.85%
  • RainRain(RAIN)$0.013660-2.30%
  • chainlinkChainlink(LINK)$12.852.45%
  • USDSUSDS(USDS)$1.000.00%
  • cardanoCardano(ADA)$0.2441514.91%
  • leo-tokenLEO Token(LEO)$8.950.40%
  • stellarStellar(XLM)$0.2113815.77%
  • nearNEAR Protocol(NEAR)$4.310.34%
  • uniswapUniswap(UNI)$8.862.93%
  • bitcoin-cashBitcoin Cash(BCH)$264.593.23%
  • Ethena USDeEthena USDe(USDE)$1.00-0.06%
  • CantonCanton(CC)$0.1191335.26%
  • avalanche-2Avalanche(AVAX)$10.66-3.51%
  • litecoinLitecoin(LTC)$60.603.70%
  • daiDai(DAI)$1.000.01%
  • USD1USD1(USD1)$1.00-0.03%
  • suiSui(SUI)$1.015.60%
  • hedera-hashgraphHedera(HBAR)$0.0935397.61%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.432.35%
  • BittensorBittensor(TAO)$316.3517.33%
  • shiba-inuShiba Inu(SHIB)$0.0000067.70%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • crypto-com-chainCronos(CRO)$0.0651644.76%
  • MemeCoreMemeCore(M)$1.36-11.47%
  • paypal-usdPayPal USD(PYUSD)$1.000.01%
  • tether-goldTether Gold(XAUT)$4,324.16-0.62%
  • okbOKB(OKB)$121.301.94%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.02%
  • aaveAave(AAVE)$141.251.82%
  • BitwayBitway(BTW)$0.808.92%
  • pepePepe(PEPE)$0.00000528.42%
  • mantleMantle(MNT)$0.645.95%
  • EthenaEthena(ENA)$0.209563-2.12%
  • OndoOndo(ONDO)$0.4312460.07%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Google AI Introduces MaMMUT: A Simple Architecture for Joint Learning for MultiModal Tasks

May 11, 2023
in AI & Technology
Reading Time: 4 mins read
A A
Google AI Introduces MaMMUT: A Simple Architecture for Joint Learning for MultiModal Tasks
ShareShareShareShareShare

The idea on which vision-language fundamental models are constructed is that a single pre-training can be used to adapt to a wide variety of downstream activities. There are two widely used but distinct training scenarios: 

  • Contrastive learning in the style of CLIP. It trains the model to predict if image-text pairs correctly match, effectively building visual and text representations for the corresponding image and text inputs. It enables image-text and text-image retrieval tasks like selecting the image that best matches a specific description.
  • Next-token prediction: It learns to generate text by predicting the most probable next token in a sequence. It supports text-generative tasks like Image Captioning and Visual Question Answering (VQA) while contrastive learning.

While both methods have shown promising results, pre-trained models not transferable to other tasks tend to perform poorly on text-generation tasks and vice versa. It’s also common for complex or inefficient approaches to be used while adapting to new tasks.

To train jointly for these competing aims and to provide the groundwork for numerous vision-language tasks either directly or by easy adaptation, a recent Google study presents MaMMUT, a simple architecture for joint learning for multimodal tasks. MaMMUT is a condensed multimodal model with only 2B parameters, and it may be trained to achieve contrastive, text-generating, and localization-aware goals. Its simple design—just one image encoder and one text decoder—makes it easy to recycle the two independently. 

🚀 JOIN the fastest ML Subreddit Community

The proposed model comprises a single visual encoder and a single text-decoder linked via cross-attention and trains concurrently on contrastive and text-generative types of losses. Previous work either doesn’t address image-text retrieval tasks or just applies some losses to select aspects of the model. Jointly training contrastive losses and text-generative captioning-like losses is necessary to enable multimodal tasks and fully use the decoder-only model.

There is a considerable performance gain with a smaller model size (nearly half the parameters) for decoder-only models in language learning. One of the biggest obstacles to using them in multimodal situations is reconciling contrastive learning (which relies on unconditional sequence-level representation) and captioning (which optimizes the likelihood of a token based on the tokens that came before it). The researchers offer a two-pass technique to learn these incompatible text representations within the decoder jointly.

Their initial run at learning the caption generation challenge uses cross-attention and causal masking so that the text features can pay attention to the image features and make sequential token predictions. They turn off cross-attention and causal masking to learn the contrastive task on the second pass. While the picture features will remain hidden from the text features, the text features will be able to attend in both directions on all text tokens simultaneously. Both tasks, which were previously difficult to reconcile, may now be handled by the same decoder thanks to the two-pass technique. Even though this model architecture is quite simple, it can serve as a basis for various multimodal tasks.

Since the architecture is trained for several separate tasks, it may be easily integrated into many applications, including image-text and text-image retrieval, visual quality assessment, and captioning. The researchers use sparse video tubes to directly access spatiotemporal information from video for lightweight adaptation. Training to detect bounding boxes via an object-detection head is also required to transfer the model to Open-Vocabulary Detection.

Despite its compact design, MaMMUT provides superior or competitive results in various areas, including image-text and text-image retrieval, video question answering (VideoQA), video captioning, open-vocabulary identification, and VQA. The team highlights that their model achieves better results than much larger models like Flamingo, which is tailored to image+video pre-training and already pre-trained on image-text and video-text data.


Check out the Paper and Google blog. Don’t forget to join our 21k+ ML SubReddit, Discord Channel, and Email Newsletter, where we share the latest AI research news, cool AI projects, and more. If you have any questions regarding the above article or if we missed anything, feel free to email us at [email protected]

🚀 Check Out 100’s AI Tools in AI Tools Club


YOU MAY ALSO LIKE

NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%

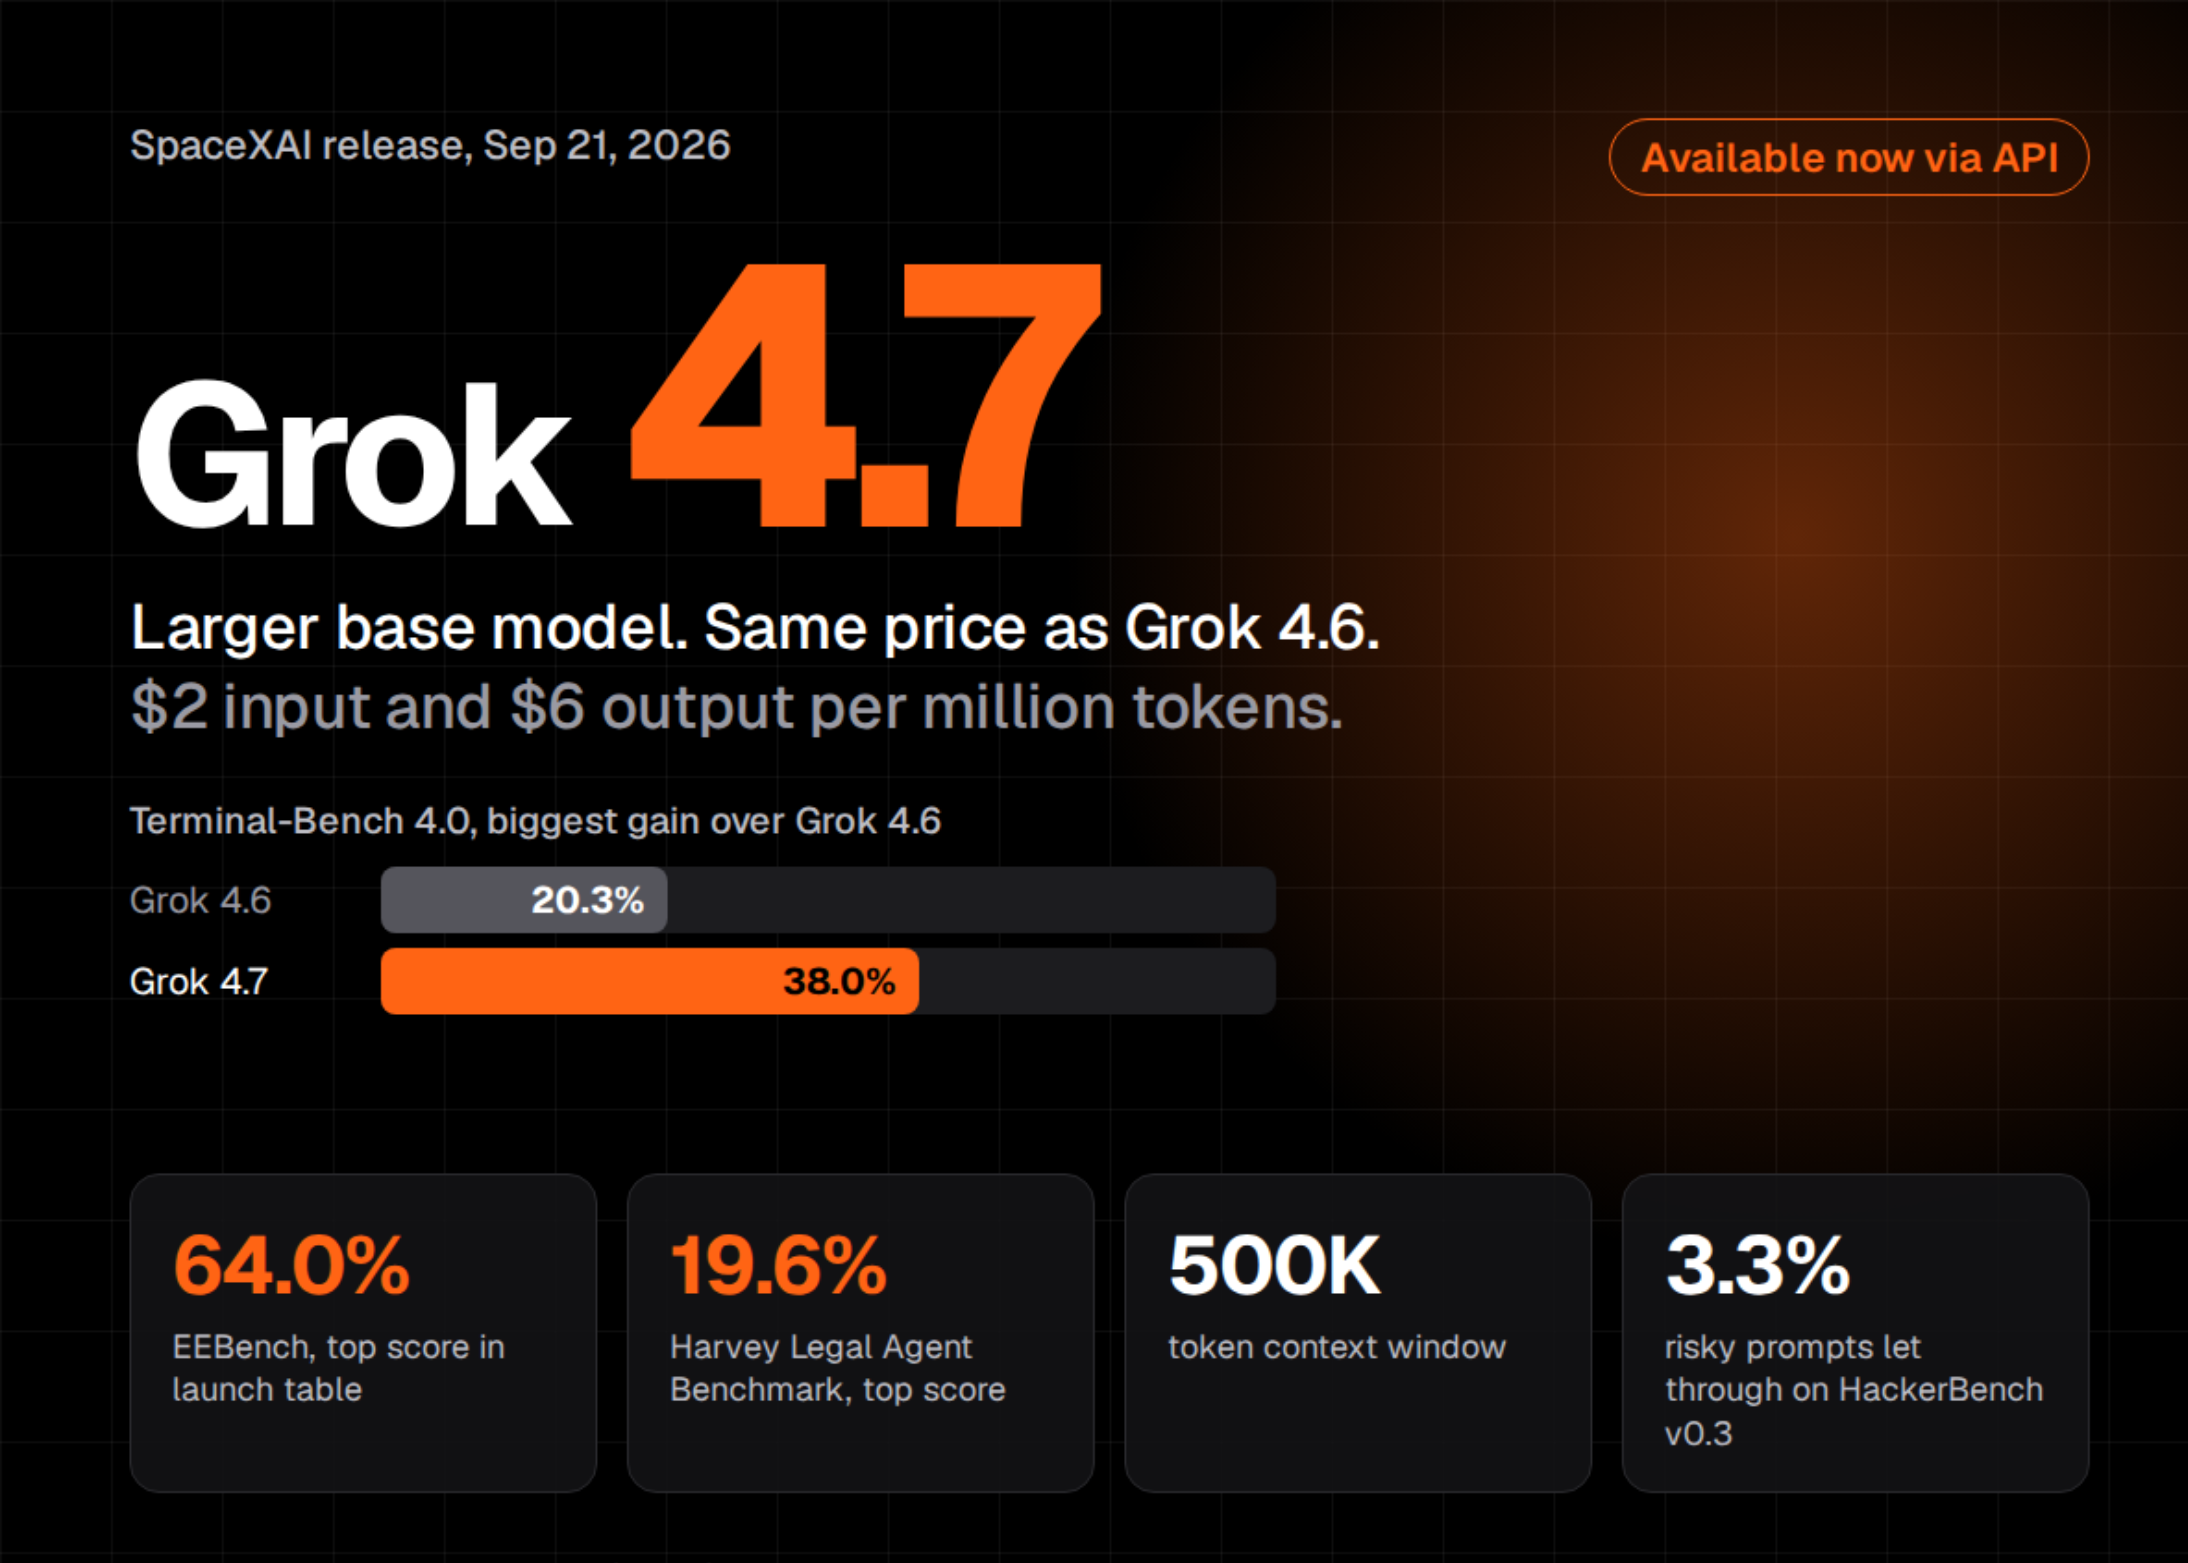
SpaceXAI Releases Grok 4.7: A Larger Base Model at the Same $2/$6 Price as Grok 4.6

Tanushree Shenwai is a consulting intern at MarktechPost. She is currently pursuing her B.Tech from the Indian Institute of Technology(IIT), Bhubaneswar. She is a Data Science enthusiast and has a keen interest in the scope of application of artificial intelligence in various fields. She is passionate about exploring the new advancements in technologies and their real-life application.


Credit: Source link

ShareTweetSendSharePin

Related Posts

NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%
AI & Technology

NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%

September 22, 2026
SpaceXAI Releases Grok 4.7: A Larger Base Model at the Same / Price as Grok 4.6
AI & Technology

SpaceXAI Releases Grok 4.7: A Larger Base Model at the Same $2/$6 Price as Grok 4.6

September 22, 2026
Why It’s Important To Unplug Your PC During A Power Outage
AI & Technology

Why It’s Important To Unplug Your PC During A Power Outage

September 22, 2026
Why Is Your Laptop Fan So Loud?
AI & Technology

Why Is Your Laptop Fan So Loud?

September 22, 2026
Next Post
‘Bloomberg Technology’ Full Show (11/11/2022)

'Bloomberg Technology' Full Show (11/11/2022)

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Clancy jury unable to come to unanimous decision, judge signals mistrial

Clancy jury unable to come to unanimous decision, judge signals mistrial

September 17, 2026
Ted Cruz says ‘there will be a time’ to make a decision on a 2028 run for president

Ted Cruz says ‘there will be a time’ to make a decision on a 2028 run for president

September 21, 2026
Berkshire Hathaway names Warren Buffett as chairman emeritus

Berkshire Hathaway names Warren Buffett as chairman emeritus

September 18, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!