• bitcoinBitcoin(BTC)$77,740.001.29%
  • ethereumEthereum(ETH)$2,283.501.46%
  • tetherTether(USDT)$1.000.04%
  • binancecoinBNB(BNB)$700.100.28%
  • rippleXRP(XRP)$1.282.48%
  • usd-coinUSDC(USDC)$1.000.03%
  • solanaSolana(SOL)$93.201.42%
  • tronTRON(TRX)$0.3213410.81%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.13%
  • zcashZcash(ZEC)$1,231.228.48%
  • HyperliquidHyperliquid(HYPE)$85.481.79%
  • moneroMonero(XMR)$630.413.94%
  • dogecoinDogecoin(DOGE)$0.0754081.65%
  • USDSUSDS(USDS)$1.000.00%
  • whitebitWhiteBIT Coin(WBT)$74.701.27%
  • leo-tokenLEO Token(LEO)$9.30-1.07%
  • chainlinkChainlink(LINK)$11.07-0.38%
  • cardanoCardano(ADA)$0.1906711.17%
  • stellarStellar(XLM)$0.162560-0.14%
  • bitcoin-cashBitcoin Cash(BCH)$275.08-0.44%
  • nearNEAR Protocol(NEAR)$3.86-0.10%
  • RainRain(RAIN)$0.006585-3.13%
  • Ethena USDeEthena USDe(USDE)$1.000.12%
  • daiDai(DAI)$1.000.01%
  • uniswapUniswap(UNI)$7.262.50%
  • litecoinLitecoin(LTC)$54.471.49%
  • CantonCanton(CC)$0.0966002.65%
  • avalanche-2Avalanche(AVAX)$8.561.93%
  • USD1USD1(USD1)$1.000.20%
  • suiSui(SUI)$0.902.73%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.18-1.04%
  • tether-goldTether Gold(XAUT)$3,921.30-0.25%
  • hedera-hashgraphHedera(HBAR)$0.0697910.09%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • quant-networkQuant(QNT)$192.74-0.84%
  • shiba-inuShiba Inu(SHIB)$0.0000051.47%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • BittensorBittensor(TAO)$226.891.69%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • crypto-com-chainCronos(CRO)$0.0503070.56%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.04%
  • EthenaEthena(ENA)$0.1761143.34%
  • okbOKB(OKB)$108.23-1.00%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.0000052.97%
  • Pump.funPump.fun(PUMP)$0.00439310.92%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • MemeCoreMemeCore(M)$0.861.78%
  • aaveAave(AAVE)$127.520.86%
  • OndoOndo(ONDO)$0.3920881.43%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Google AI Described New Machine Learning Methods for Generating Differentially Private Synthetic Data

May 19, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Google AI Described New Machine Learning Methods for Generating Differentially Private Synthetic Data
ShareShareShareShareShare

Google AI researchers describe their novel approach to addressing the challenge of generating high-quality synthetic datasets that preserve user privacy, which are essential for training predictive models without compromising sensitive information. As machine learning models increasingly rely on large datasets, ensuring the privacy of individuals whose data contributes to these models becomes crucial. Differentially private synthetic data is synthesized by creating new datasets that reflect the key characteristics of the original data but are entirely artificial, thus protecting user privacy while enabling robust model training.

Current methods for privacy-preserving data generation involve training models directly with differentially private machine learning (DP-ML) algorithms, which provide strong privacy guarantees. However, when working with high-dimensional datasets utilized for a variety of tasks, this method can be computationally demanding and may only sometimes produce high-quality results. Previous models, such as Harnessing large-language models, have leveraged large-language models (LLMs) combined with differentially private stochastic gradient descent (DP-SGD) to generate private synthetic data. This method involves fine-tuning an LLM trained on public data using DP-SGD on a sensitive dataset, ensuring that the generated synthetic data does not reveal any specific information about the individuals in the sensitive dataset.

Google’s researchers proposed an enhanced approach to generating differentially private synthetic data by leveraging parameter-efficient fine-tuning techniques, such as LoRa (Low-Rank Adaptation) and prompt fine-tuning. These techniques aim to modify a smaller number of parameters during the private training process, which reduces computational overhead and potentially improves the quality of the synthetic data.

The first step of the approach is to train LLM on a large corpus of public data. The LLM is then fine-tuned using DP-SGD on the sensitive dataset, with the fine-tuning process restricted to a subset of the model’s parameters. LoRa fine-tuning involves replacing each W in the model with W + LR, where L and R are low-rank matrices, and only trains L and R. Prompt fine-tuning, on the other hand, involves inserting a “prompt tensor” at the start of the network and only trains its weights, effectively modifying only the input prompt used by the LLM.

Empirical results showed that LoRa fine-tuning, which modifies roughly 20 million parameters, outperforms both full-parameter fine-tuning and prompt-based tuning, which modifies only about 41 thousand parameters. This suggests that there is an optimal number of parameters that balances the trade-off between computational efficiency and data quality. Classifiers trained on synthetic data generated by LoRa fine-tuned LLMs outperformed those trained on synthetic data from other fine-tuning methods, and in some cases, classifiers trained directly on the original sensitive data using DP-SGD. In an experiment to evaluate the proposed approach, a decoder-only LLM (Lamda-8B) was trained on public data and then privately fine-tuned on three publicly available datasets, namely IMDB, Yelp, and AG News, and treated as sensitive. The synthetic data generated was used to train classifiers on tasks such as sentiment analysis and topic classification. The classifiers’ performance on held-out subsets of the original data demonstrated the efficacy of the proposed method.

In conclusion, Google’s approach to generating differentially private synthetic data using parameter-efficient fine-tuning techniques has outperformed existing methods. By fine-tuning a smaller subset of parameters, the method reduces computational requirements and improves the quality of the synthetic data. This approach not only preserves privacy but also maintains high utility for training predictive models, making it a valuable tool for organizations looking to leverage sensitive data without compromising user privacy. The empirical results demonstrate the effectiveness of the proposed method, suggesting its potential for broader applications in privacy-preserving machine learning.


Check out the Paper and Blog. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 42k+ ML SubReddit


YOU MAY ALSO LIKE

Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI

Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’

Pragati Jhunjhunwala is a consulting intern at MarktechPost. She is currently pursuing her B.Tech from the Indian Institute of Technology(IIT), Kharagpur. She is a tech enthusiast and has a keen interest in the scope of software and data science applications. She is always reading about the developments in different field of AI and ML.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI
AI & Technology

Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI

November 3, 2026
Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’
AI & Technology

Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’

November 3, 2026
Traversal Raises 0M Series B at B Valuation to Expand AI SRE – Unite.AI
AI & Technology

Traversal Raises $120M Series B at $1B Valuation to Expand AI SRE – Unite.AI

November 3, 2026
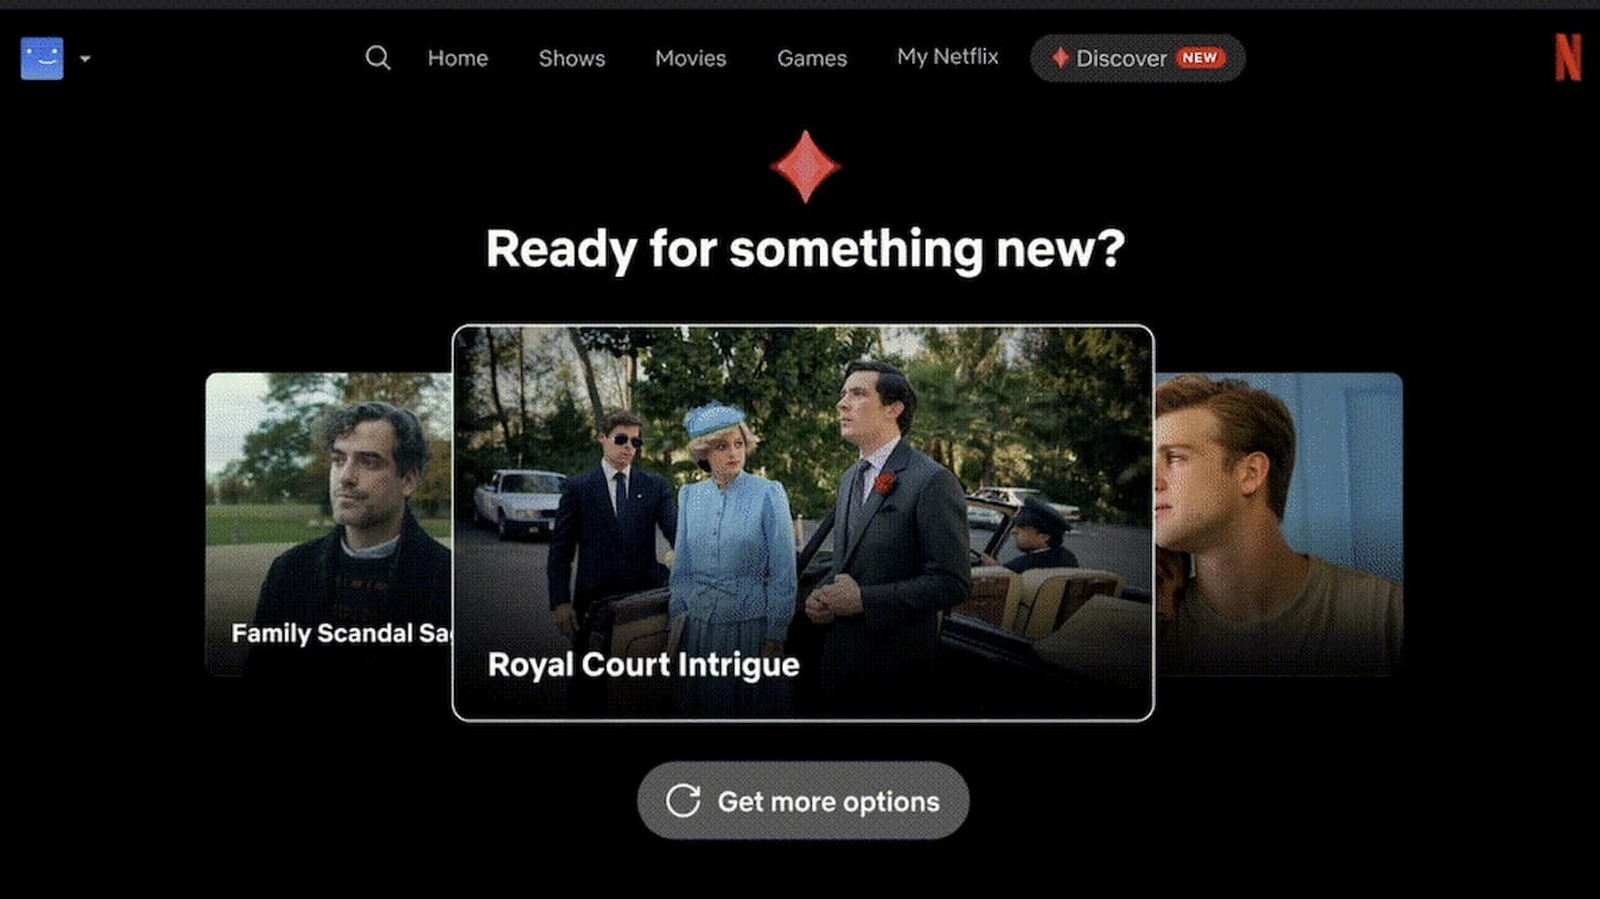
Netflix Thinks AI Might Save You From Scrolling Aimlessly For Something To Watch
AI & Technology

Netflix Thinks AI Might Save You From Scrolling Aimlessly For Something To Watch

November 3, 2026
Next Post
How wind and solar are leading the future of clean energy

How wind and solar are leading the future of clean energy

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
She Lost Child Support And Can’t Pay Her Bills Now

She Lost Child Support And Can’t Pay Her Bills Now

November 3, 2026
Could a new treatment cure Type 1 diabetes?

Could a new treatment cure Type 1 diabetes?

November 1, 2026
Marvell in Talks to Buy Nvidia-Backed Lumentum

Marvell in Talks to Buy Nvidia-Backed Lumentum

October 29, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!