• bitcoinBitcoin(BTC)$82,767.00-2.54%
  • ethereumEthereum(ETH)$2,647.47-2.47%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$760.31-2.49%
  • rippleXRP(XRP)$1.48-3.54%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$118.00-5.11%
  • tronTRON(TRX)$0.3342080.25%
  • zcashZcash(ZEC)$1,549.68-7.07%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.060.00%
  • HyperliquidHyperliquid(HYPE)$89.61-3.69%
  • dogecoinDogecoin(DOGE)$0.092691-5.32%
  • chainlinkChainlink(LINK)$13.61-5.09%
  • moneroMonero(XMR)$528.10-5.44%
  • whitebitWhiteBIT Coin(WBT)$82.58-2.57%
  • USDSUSDS(USDS)$1.00-0.03%
  • cardanoCardano(ADA)$0.243832-4.83%
  • RainRain(RAIN)$0.012607-0.71%
  • leo-tokenLEO Token(LEO)$9.01-0.12%
  • stellarStellar(XLM)$0.210957-2.89%
  • nearNEAR Protocol(NEAR)$5.02-4.81%
  • bitcoin-cashBitcoin Cash(BCH)$307.84-9.49%
  • CantonCanton(CC)$0.1399242.07%
  • uniswapUniswap(UNI)$8.88-11.25%
  • litecoinLitecoin(LTC)$70.37-2.04%
  • hedera-hashgraphHedera(HBAR)$0.11341819.65%
  • Ethena USDeEthena USDe(USDE)$1.000.00%
  • avalanche-2Avalanche(AVAX)$10.41-6.27%
  • suiSui(SUI)$1.17-6.89%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.674.77%
  • daiDai(DAI)$1.000.01%
  • USD1USD1(USD1)$1.00-0.01%
  • BitwayBitway(BTW)$1.3924.94%
  • BittensorBittensor(TAO)$299.99-9.85%
  • shiba-inuShiba Inu(SHIB)$0.000006-5.59%
  • quant-networkQuant(QNT)$225.2829.05%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • crypto-com-chainCronos(CRO)$0.063745-6.79%
  • tether-goldTether Gold(XAUT)$4,161.56-2.78%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.02%
  • MemeCoreMemeCore(M)$1.16-4.65%
  • EthenaEthena(ENA)$0.258529-4.26%
  • OndoOndo(ONDO)$0.51-5.45%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • okbOKB(OKB)$117.09-3.93%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.05%
  • aaveAave(AAVE)$147.11-5.64%
  • Pump.funPump.fun(PUMP)$0.0047636.41%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Diagnosing and Self- Correcting LLM Agent Failures: A Technical Deep Dive into τ-Bench Findings with Atla’s EvalToolbox

April 30, 2025
in AI & Technology
Reading Time: 4 mins read
A A
Diagnosing and Self- Correcting LLM Agent Failures: A Technical Deep Dive into τ-Bench Findings with Atla’s EvalToolbox
ShareShareShareShareShare

Deploying large language model (LLM)-based agents in production settings often reveals critical reliability issues. Accurately identifying the causes of agent failures and implementing proactive self-correction mechanisms is essential. Recent analysis by Atla on the publicly available τ-Bench benchmark provides granular insights into agent failures, moving beyond traditional aggregate success metrics and highlighting Atla’s EvalToolbox approach.

Conventional evaluation practices typically rely on aggregate success rates, offering minimal actionable insights into actual performance reliability. These methods necessitate manual reviews of extensive logs to diagnose issues—an impractical approach as deployments scale. Relying solely on success rates, such as 50%, provides insufficient clarity regarding the nature of the remaining unsuccessful interactions, complicating the troubleshooting process.

YOU MAY ALSO LIKE

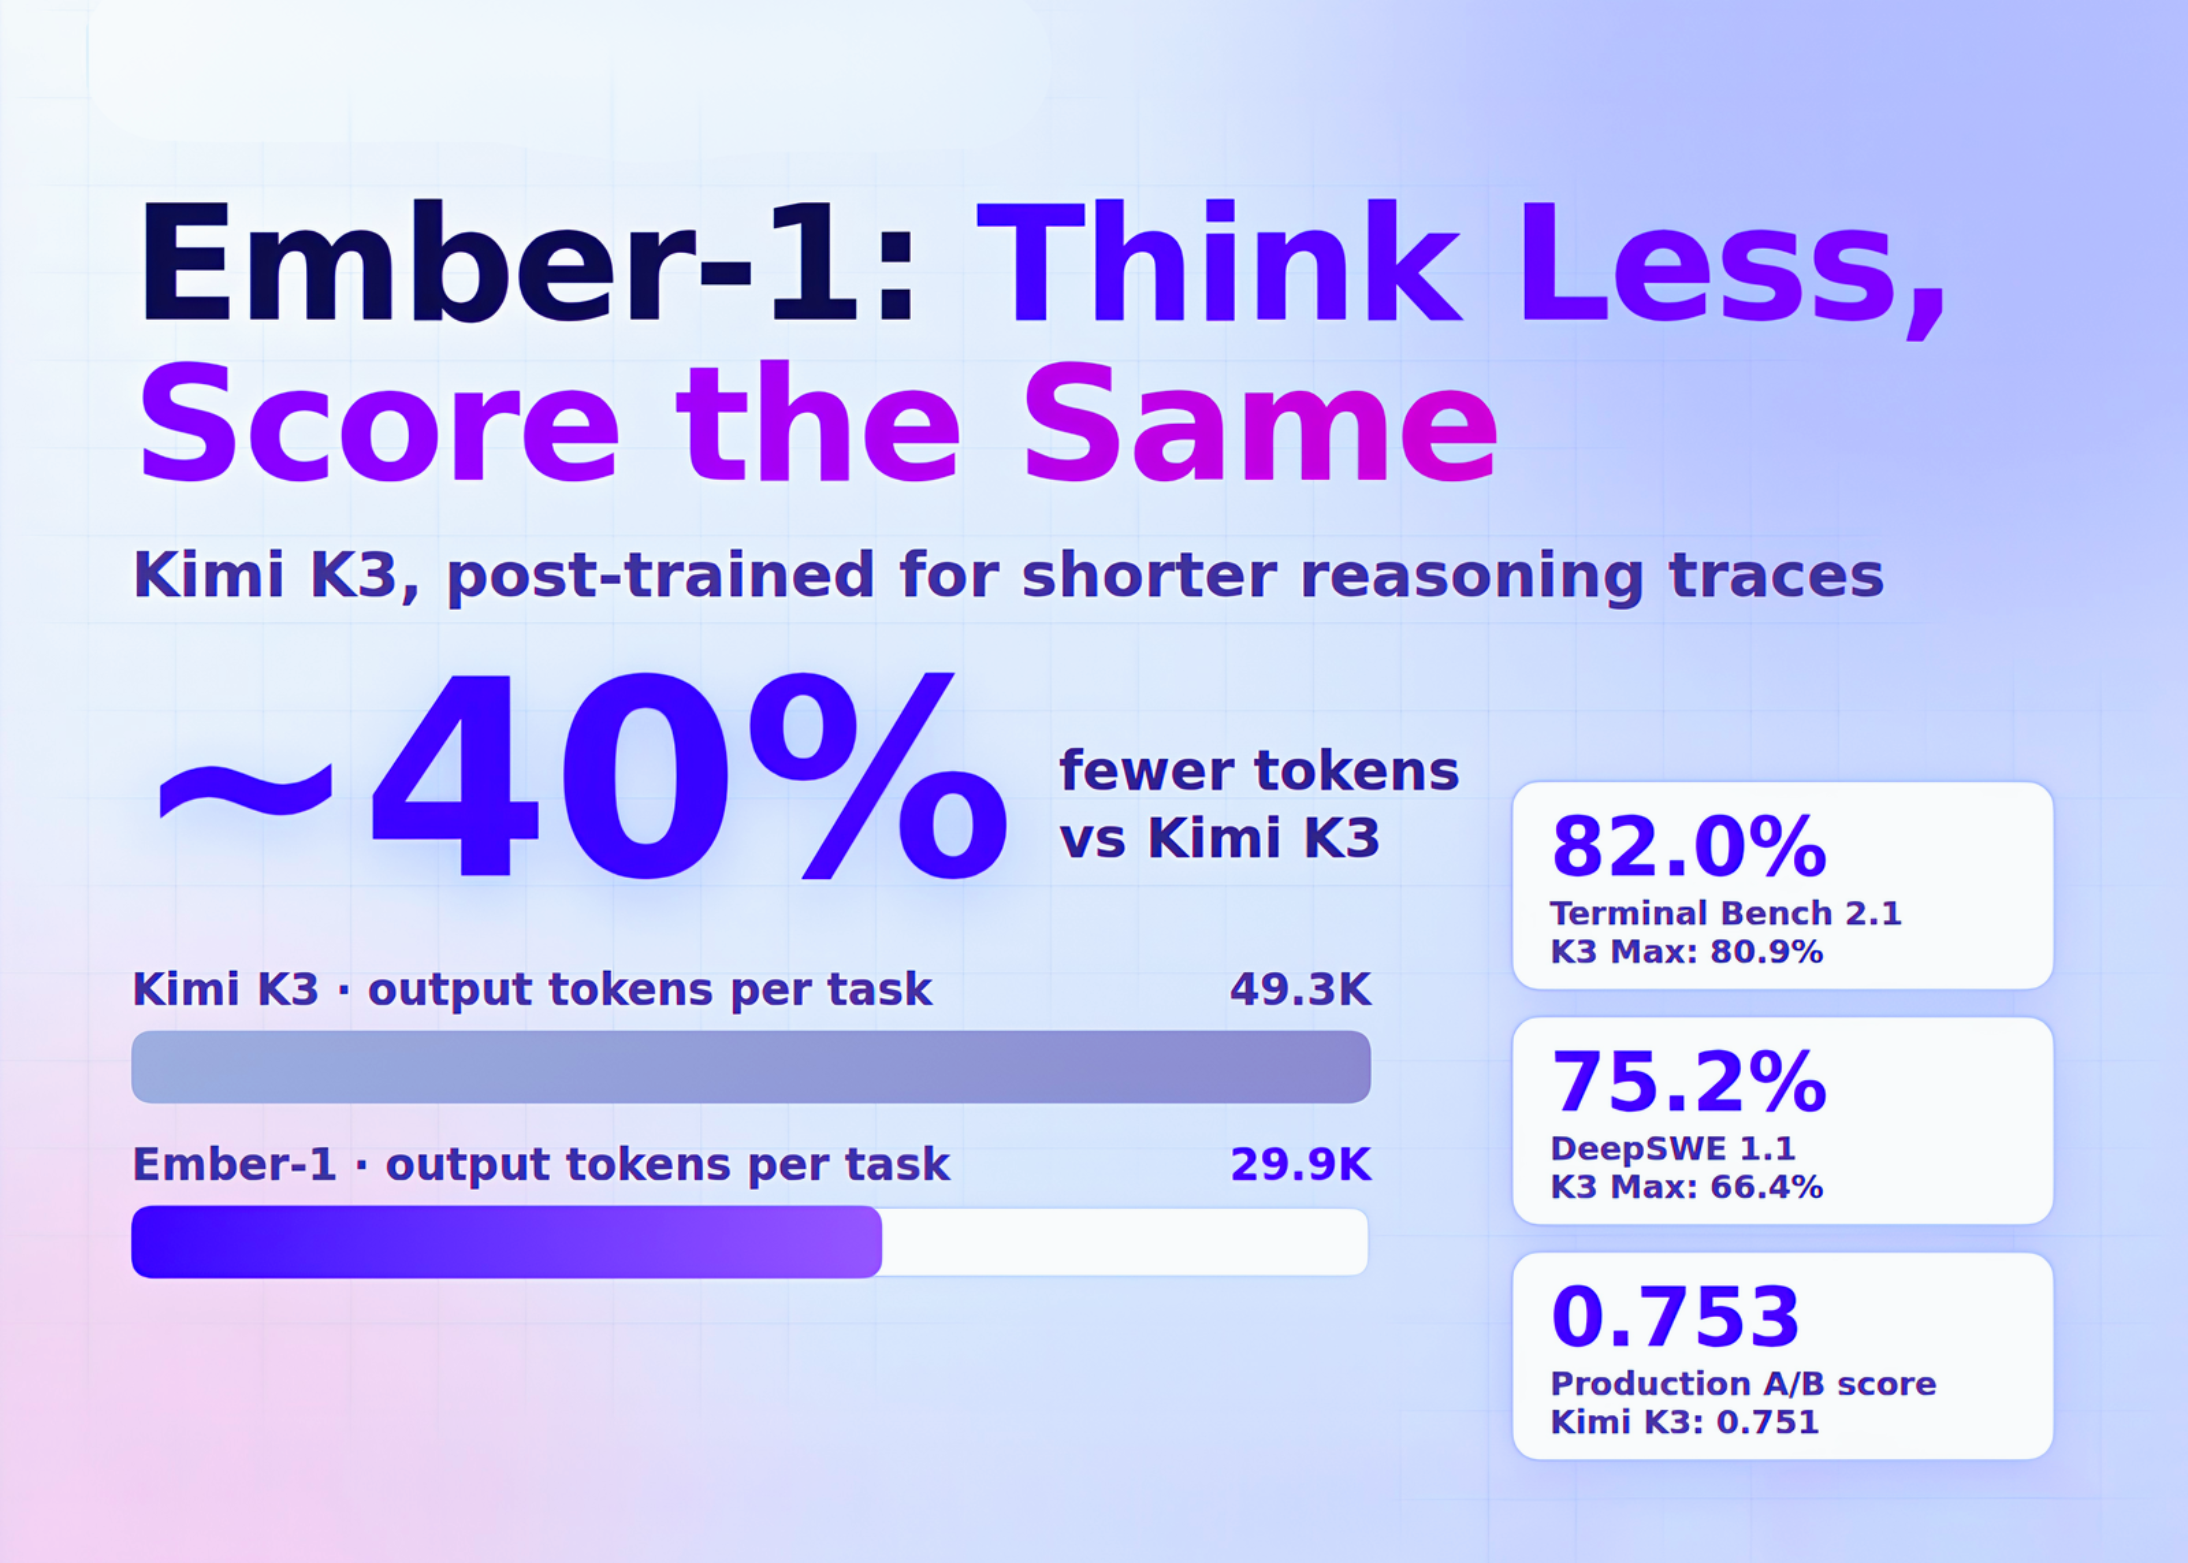
Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens

You Can Now Preorder The Tiny Boox Picco Ereader

To address these evaluation gaps, Atla conducted a detailed analysis of τ-Bench—a benchmark specifically designed to examine tool-agent-user interactions. This analysis systematically identified and categorized agent workflow failures within τ-retail, a subset focusing on retail customer service interactions.

Explore a preview of the Atla EvalToolbox (launching soon) here, and sign up to join Atla’s user community. If you would like to learn more, book a call with the Atla team.

A detailed evaluation of τ-retail highlighted key failure categories:

  • Workflow Errors, predominantly characterized by “Wrong Action” scenarios, where agents failed to execute necessary tasks.
  • User Interaction Errors, particularly the provision of “Wrong Information,” emerged as the most frequent failure type.
  • Tool Errors, where correct tools were utilized incorrectly due to erroneous parameters, constituted another significant failure mode.

A critical distinction from this benchmark is the categorization of errors into terminal failures (irrecoverable) and recoverable failures. Terminal failures significantly outnumber recoverable errors, illustrating the limitations inherent in agent self-correction without guided intervention.

Here’s an example where an agent makes a “wrong information” failure:

To address these challenges, Atla integrated Selene, an evaluation model directly embedded into agent workflows. Selene actively monitors each interaction step, identifying and correcting errors in real-time. Practical demonstrations show marked improvements when employing Selene: agents successfully corrected initial errors promptly, enhancing overall accuracy and user experience.

Illustratively, in scenarios involving “Wrong Information”:

  • Agents operating without Selene consistently failed to recover from initial errors, resulting in low user satisfaction.
  • Selene-equipped agents effectively identified and rectified errors, significantly enhancing user satisfaction and accuracy of responses.

EvalToolbox thus transitions from manual, retrospective error assessments toward automated, immediate detection and correction. It accomplishes this through:

  1. Automated categorization and identification of common failure modes.
  2. Real-time, actionable feedback upon detecting errors.
  3. Dynamic self-correction facilitated by incorporating real-time feedback directly into agent workflows.

Future enhancements include broader applicability across diverse agent functions such as coding tasks, specialized domain implementations, and the establishment of standardized evaluation-in-the-loop protocols.

Integrating evaluation directly within agent workflows through τ-Bench analysis and EvalToolbox represents a practical, automated approach to mitigating reliability issues in LLM-based agents.


Note: Thanks to the ATLA AI team for the thought leadership/ Resources for this article. ATLA AI team has supported us for this content/article.

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
Credit: Source link

ShareTweetSendSharePin

Related Posts

Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens
AI & Technology

Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens

September 28, 2026
You Can Now Preorder The Tiny Boox Picco Ereader
AI & Technology

You Can Now Preorder The Tiny Boox Picco Ereader

September 28, 2026
20 Agentic Use Cases of TypeSafe AI’s Jev
AI & Technology

20 Agentic Use Cases of TypeSafe AI’s Jev

September 28, 2026
Google Research Introduces an AI Video Co-Director: 4 Agentic Frameworks for Coherent, Minutes-Long Video Generation
AI & Technology

Google Research Introduces an AI Video Co-Director: 4 Agentic Frameworks for Coherent, Minutes-Long Video Generation

September 28, 2026
Next Post
People cheer as power is restored in Madrid

People cheer as power is restored in Madrid

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Americans are drinking less since the pandemic began, but one group bucks the trend – washingtonpost.com

Americans are drinking less since the pandemic began, but one group bucks the trend – washingtonpost.com

September 23, 2026
Apple customers can now submit claims for 0M settlement in deceptive marketing suit

Apple customers can now submit claims for $250M settlement in deceptive marketing suit

September 21, 2026
American tourists among hundreds missing after deadly floods in Nepal

American tourists among hundreds missing after deadly floods in Nepal

September 23, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!