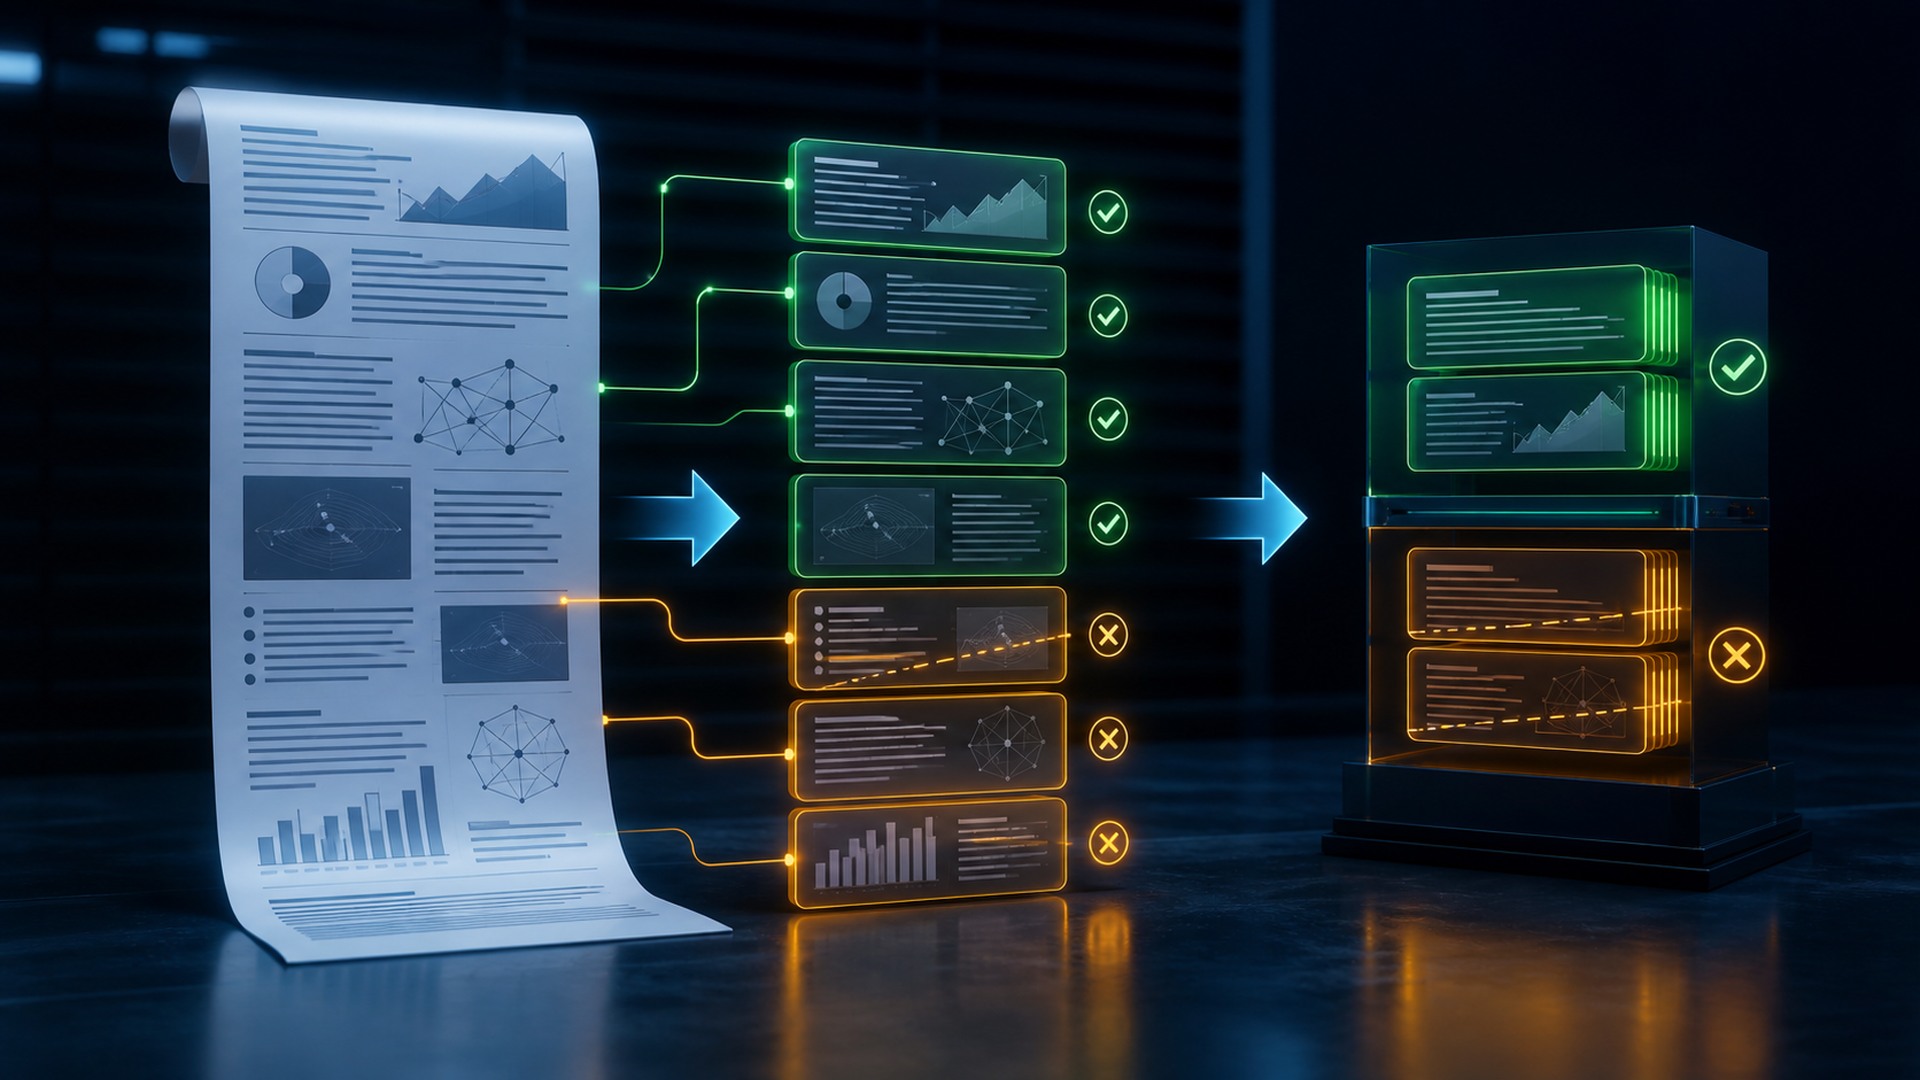

Chunking divides source material into retrievable units whose boundaries and metadata strongly influence what evidence a RAG system can find and present together.
RAG chunking deserves a precise explanation because its name identifies a particular information flow, training choice, runtime mechanism, or governance boundary. Treating it as a synonym for “advanced AI” makes claims impossible to test. This guide follows the concept from its input and assumptions through its observable result, then tests the shortcut most likely to be confused with it.
RAG Chunking: Definition, Boundary, and Purpose
Chunking divides source material into retrievable units whose boundaries and metadata strongly influence what evidence a RAG system can find and present together. The definition contains three practical commitments: there is an identifiable input, a transformation or decision that is characteristic of RAG chunking, and an outcome that can be evaluated against a stated objective. If one of those elements is missing, the label may describe an aspiration rather than an implemented mechanism.
Retrieval systems are pipelines. Parsing, representation, indexing, candidate generation, ranking, context assembly, and answer generation can each create or remove evidence. For RAG chunking, this system view matters because performance can be determined by the surrounding data, interfaces, hardware, permissions, and people even when the underlying model is unchanged. A useful explanation therefore separates the model’s learned behavior from the product that decides when, where, and with what authority that behavior is used.
The nearest misleading shortcut is placing an entire document or every sentence into the index unchanged. It may share a visible feature with RAG chunking, yet it changes the causal story: different evidence would establish success, different resources would dominate cost, and different controls would prevent harm. The boundary is therefore operational rather than terminological.
A Five-Stage Operating Map of RAG Chunking
01Parse the document’s real structure
02Choose chunk size and overlap
03Preserve titles, sections, and source
04Embed and index each unit
05Evaluate retrieval on answer-bearing spans
The diagram is a compact causal map for RAG chunking, not a claim that every implementation uses five software components. Some systems combine stages and others repeat them in a loop. The map remains useful because it forces each change in information or authority to have an owner, an input, an output, and a test.
1. Parse the Document’s Real Structure: Input and Assumptions in RAG Chunking
At this stage of RAG chunking, the system must parse the document’s real structure. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from placing an entire document or every sentence into the index unchanged and reproduce its result under the same stated conditions.
The handoff into this RAG chunking stage begins with the stated objective and should end with a result that can support choose chunk size and overlap. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether chunks can sever context, duplicate noise, or combine unrelated subjects before the same weakness reaches a consequential output.
2. Choose Chunk Size and Overlap: Representation or Decision in RAG Chunking
At this stage of RAG chunking, the system must choose chunk size and overlap. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from placing an entire document or every sentence into the index unchanged and reproduce its result under the same stated conditions.
The handoff into this RAG chunking stage begins with parse the document’s real structure and should end with a result that can support preserve titles, sections, and source metadata. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether chunks can sever context, duplicate noise, or combine unrelated subjects before the same weakness reaches a consequential output.
3. Preserve Titles, Sections, and Source Metadata: Distinctive Transformation in RAG Chunking
At this stage of RAG chunking, the system must preserve titles, sections, and source metadata. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from placing an entire document or every sentence into the index unchanged and reproduce its result under the same stated conditions.
The handoff into this RAG chunking stage begins with choose chunk size and overlap and should end with a result that can support embed and index each unit. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether chunks can sever context, duplicate noise, or combine unrelated subjects before the same weakness reaches a consequential output.
4. Embed and Index Each Unit: Constraint and Verification Boundary in RAG Chunking
At this stage of RAG chunking, the system must embed and index each unit. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from placing an entire document or every sentence into the index unchanged and reproduce its result under the same stated conditions.
The handoff into this RAG chunking stage begins with preserve titles, sections, and source metadata and should end with a result that can support evaluate retrieval on answer-bearing spans. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether chunks can sever context, duplicate noise, or combine unrelated subjects before the same weakness reaches a consequential output.
5. Evaluate Retrieval on Answer-Bearing Spans: Output, Feedback, and Stop Rule in RAG Chunking
At this stage of RAG chunking, the system must evaluate retrieval on answer-bearing spans. The useful question is not merely whether that operation occurs, but which information it consumes, which state it changes, and what evidence proves that the change was valid. A reviewer should be able to distinguish the operation from placing an entire document or every sentence into the index unchanged and reproduce its result under the same stated conditions.
The handoff into this RAG chunking stage begins with embed and index each unit and should end with a result that can support monitoring or a final decision. Record uncertainty, rejected alternatives, resource use, and any human or software control applied at the boundary. That trace is where teams can detect whether chunks can sever context, duplicate noise, or combine unrelated subjects before the same weakness reaches a consequential output.
Read the RAG chunking map forward to understand production and backward to diagnose failure. Forward analysis asks how one stage supplies the next. Backward analysis starts from an incorrect, slow, expensive, or unsafe result and traces which earlier assumption allowed it. The reverse path is often where a team discovers that the decisive error occurred before the model produced anything.
A Worked RAG Chunking Example
A legal index should keep a clause with its heading and exceptions rather than slicing at an arbitrary character count.
This example is informative because RAG chunking can be tied to observable inputs, intermediate states, and an outcome rather than judged through a polished demonstration. A rigorous test would build ordinary, difficult, and deliberately misleading cases around the scenario, preserve a baseline without the technique, and record both average performance and the severity of individual failures.
Change one assumption in the RAG chunking example and repeat the analysis. Remove a required input, introduce a conflicting signal, limit compute, alter the user population, or force the system to abstain. A mechanism that only succeeds under one carefully arranged demonstration has not established that it generalizes to the operating environment.
RAG Chunking vs. Its Most Common Shortcut
RAG chunking is often reduced to placing an entire document or every sentence into the index unchanged. That reduction removes the very boundary that defines the concept. It can lead buyers to compare unlike products, researchers to overstate what an experiment demonstrates, and operators to monitor the wrong signal after deployment.
RAG chunking
Core transformation
Measured outcome
placing an entire document or
Skips core boundary
chunks can sever context, duplicate
| Lens | Practical answer |
|---|---|
| Definition | Chunking divides source material into retrievable units whose boundaries and metadata strongly influence what evidence a RAG system can find and present together. |
| Confusion | placing an entire document or every sentence into the index unchanged. |
| Risk | chunks can sever context, duplicate noise, or combine unrelated subjects. |
The comparison should also identify the unit of analysis. A paper about RAG chunking may isolate a model or algorithm, while a deployed service adds retrieval, routing, caching, policy, identity, user interfaces, and monitoring. Two products can use the same headline term while implementing different parts of that stack. Ask which component performs the defining transformation and which other components are necessary for the reported outcome.
Why RAG Chunking Matters in Current AI Systems
RAG chunking matters now because AI systems are being given larger contexts, more modalities, more runtime compute, broader tool access, and deeper connections to organizational decisions. Under those conditions, what once looked like a research detail can determine latency, security, accessibility, environmental cost, product quality, or legal accountability.
The relevant measure is not whether RAG chunking can produce one impressive result. It is whether the technique improves an outcome that matters across representative conditions and does so more effectively than a simpler baseline. Report distributions, failure categories, tail latency, resource use, and affected subgroups rather than compressing every result into one average.
Evaluate retrieval separately from generation with answer-bearing documents, then evaluate the combined system for groundedness, citation correctness, abstention, freshness, access control, latency, and cost. Applied specifically to RAG chunking, that discipline makes the evidence portable: another team can judge whether the claimed gain is likely to survive a different model, language, hardware platform, dataset, user population, or risk tolerance.
Benefits RAG Chunking Can Deliver
The strongest reason to use RAG chunking is that it can address its intended bottleneck directly. Depending on the implementation, the benefit may appear as better grounding, a more faithful representation, improved generalization, lower latency, reduced memory movement, clearer accountability, or a safer boundary between a model proposal and a real action.
Benefits should be expressed as decisions and measurements. “More intelligent” is not an acceptance criterion for RAG chunking. A useful target might specify error rate on hard cases, recovery after conflicting evidence, cost at a percentile of traffic, human-review time, calibration, or the percentage of actions kept within a defined authority limit.
The Failure Mode That Defines RAG Chunking
The central limitation is that chunks can sever context, duplicate noise, or combine unrelated subjects. This failure is not an afterthought to list once development is complete. It should shape data collection, architecture, permissions, evaluation, release gates, and monitoring for RAG chunking from the beginning.
02Retrieve candidates
Failure to prevent: chunks can sever context, duplicate noise, or combine unrelated subjects.
A control for RAG chunking is useful only if it acts before an expensive or irreversible consequence. Identify the earliest observable precursor to the failure, set a threshold or rule, assign an accountable owner, and test recovery. Depending on the use case, recovery may mean abstaining, falling back to a simpler system, requesting more evidence, escalating to a person, rolling back a model, or stopping an action entirely.
An Evaluation Plan for RAG Chunking
Begin evaluation of RAG chunking by writing the decision the evidence must support. Define the operating population, consequence of a wrong result, information actually available at decision time, and the simplest credible alternative. This prevents a benchmark from becoming the goal simply because it is easy to run.
Use an untouched test set for controlled comparisons, then validate RAG chunking in a staged operating environment. Offline evaluation makes variants comparable; shadow mode, canaries, rate limits, or approval gates reveal how real traffic, feedback loops, and people change behavior. The deployment stage should have an explicit stop condition rather than assuming every improvement deserves full rollout.
Version the inputs needed to reproduce RAG chunking: source data, preprocessing, tokenizer or encoder, model weights, configuration, prompt or policy, retrieval index, evaluation set, hardware assumptions, and serving code as applicable. Without lineage, a team cannot tell whether a changed result came from the technique, the environment, or an unnoticed pipeline edit.
Finally, ask what finding would falsify the claim that RAG chunking helps. If no result could reverse the adoption decision, the evaluation is marketing. Precommitted acceptance thresholds and a preserved confirmation set turn the exercise into evidence.
Questions to Ask Before Adopting RAG Chunking
- Objective: Which measurable bottleneck is RAG chunking intended to solve?
- Mechanism: Which of the five stages contains the distinctive transformation?
- Baseline: How does it compare with placing an entire document or every sentence into the index unchanged or another simpler alternative?
- Evidence: Which ordinary, difficult, adversarial, and subgroup cases were tested?
- Operations: What latency, memory, compute, energy, maintenance, and review costs appear at scale?
- Risk: How will the team detect that chunks can sever context, duplicate noise, or combine unrelated subjects?
- Recovery: Can the system abstain, fall back, roll back, or escalate before harm?
Primary Sources for Studying RAG Chunking
Authoritative starting points for the part of the AI stack surrounding RAG chunking include Retrieval-Augmented Generation paper, FAISS similarity search research, Microsoft GraphRAG. Read them alongside the documentation for the exact model, dataset, hardware, and jurisdiction involved. A general source can define the mechanism, but only deployment-specific evidence can establish that a particular implementation is suitable.
What to Remember About RAG Chunking
RAG chunking is a defined mechanism inside a larger sociotechnical system. Its value comes from improving a specific outcome under explicit conditions, not from the label itself. The five-stage map makes its information flow visible, the comparison identifies what it is not, and the control path shows where a responsible operator can intervene.
The practical rule for RAG chunking is to define the objective, compare against a credible baseline, test the failure that matters most, and retain the evidence needed to monitor change. With those pieces in place, the concept becomes an engineering and governance choice that can be evaluated. Without them, it remains a promising name attached to an unknown operating risk.
Credit: Source link