• bitcoinBitcoin(BTC)$77,844.001.58%
  • ethereumEthereum(ETH)$2,513.771.57%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$721.990.96%
  • rippleXRP(XRP)$1.404.56%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$101.772.06%
  • tronTRON(TRX)$0.340006-0.20%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.000.00%
  • zcashZcash(ZEC)$1,137.714.32%
  • HyperliquidHyperliquid(HYPE)$80.273.65%
  • dogecoinDogecoin(DOGE)$0.0843281.00%
  • RainRain(RAIN)$0.015110-1.63%
  • USDSUSDS(USDS)$1.00-0.01%
  • moneroMonero(XMR)$514.73-4.64%
  • whitebitWhiteBIT Coin(WBT)$80.631.46%
  • chainlinkChainlink(LINK)$11.400.87%
  • leo-tokenLEO Token(LEO)$8.96-1.03%
  • cardanoCardano(ADA)$0.2109303.25%
  • stellarStellar(XLM)$0.1917757.93%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • daiDai(DAI)$1.000.01%
  • bitcoin-cashBitcoin Cash(BCH)$223.440.17%
  • USD1USD1(USD1)$1.000.00%
  • litecoinLitecoin(LTC)$53.760.18%
  • uniswapUniswap(UNI)$6.320.79%
  • CantonCanton(CC)$0.0960911.16%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.350.17%
  • hedera-hashgraphHedera(HBAR)$0.0768802.32%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • avalanche-2Avalanche(AVAX)$7.391.02%
  • nearNEAR Protocol(NEAR)$2.414.80%
  • shiba-inuShiba Inu(SHIB)$0.0000051.06%
  • suiSui(SUI)$0.732.24%
  • crypto-com-chainCronos(CRO)$0.0590730.96%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • BittensorBittensor(TAO)$236.471.91%
  • tether-goldTether Gold(XAUT)$4,301.86-1.04%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • MemeCoreMemeCore(M)$1.11-3.57%
  • okbOKB(OKB)$114.140.68%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.09%
  • aaveAave(AAVE)$126.562.14%
  • AsterAster(ASTER)$0.701.61%
  • mantleMantle(MNT)$0.572.04%
  • pax-goldPAX Gold(PAXG)$4,303.86-1.08%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.057330-0.56%
  • OndoOndo(ONDO)$0.3557593.54%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Can Large-Scale Language Models Replace Humans in Text Evaluation Tasks? This AI Paper Proposes to Use LLM for Evaluating the Quality of Texts to Serve as an Alternative to Human Evaluation

August 12, 2023
in AI & Technology
Reading Time: 4 mins read
A A
Can Large-Scale Language Models Replace Humans in Text Evaluation Tasks? This AI Paper Proposes to Use LLM for Evaluating the Quality of Texts to Serve as an Alternative to Human Evaluation
ShareShareShareShareShare

Human evaluation has been used to evaluate the performance of natural language processing models and algorithms for denoting text quality. Still, human evaluation is only sometimes consistent and may not be reproducible as it is hard to recruit the same human evaluators and return the same evaluation as the evaluator uses a different number of factors, including the subjectivity or differences in their interpretation of the evaluation criteria.

The researchers from National Taiwan University have studied the use of “large-scale language models” (models trained to model human language. They are trained using large amounts of textual data accessible on the Web, and as a result, they learn how to use a person’s language) as a new evaluation method to address this reproducibility issue. The researchers presented the LLMs with the same instructions, samples to be evaluated, and questions used to conduct human evaluation and then asked the LLMs to generate responses to those questions. They used human and LLM evaluation to evaluate the texts in two NLP tasks: open-ended story generation and adversarial attacks.

In “open-ended story generation,” they checked the quality of stories generated by a human and a generative model (GPT-2) evaluated by a large-scale language model and a human to verify whether the large-scale language model can rate human-written stories higher than those generated by the generative model.

To do so, they first generated a questionnaire(evaluation instructions, generated story fragments, and evaluation questions) prepared and rated on a Likert scale (5 levels) based on four different attributes (grammatical accuracy, consistency, liking, and relevance), respectively.

In human evaluation, the user responds to the prepared questionnaire as is. For the evaluation by the large-scale language model, they input the questionnaire as a prompt and obtain the output by the large-scale language model. The researchers used four large language models T0, text-curie-001, text-davinci-003, and ChatGPT. For the human evaluation, the researchers used renowned English teachers. These large-scale language models and English teachers evaluated 200 human-written and 200 GPT-2 generated stories.
Ratings given by English teachers show a preference for all four attributes (Grammaticality, Cohesiveness, Likability, and Relevance) for human-written stories. This shows that English teachers can distinguish the difference in quality between stories written by the generative model and those written by humans. But, T0 and text-curie-001 show no clear preference for human-written stories. This indicates that large-scale language models are less competent than human experts in evaluating open-ended story generation. On the other hand, text-davinci-003 shows a clear preference for human-written stories and English teachers. Further, ChatGPT also showed a higher rating for human-written stories.

Build your personal brand with Taplio! 🚀 The 1st AI-powered tool to grow on LinkedIn (Sponsored)

They examined a task for adversarial attacks that test the AI’s ability to classify sentences. They tested the ability to classify a sentence on some kind of hostile attack ( using synonyms to slightly change the sentence). They then evaluated how the attack affects the AI’s ability to classify the sentences. They performed this by using a large-scale language model (ChatGPT) and a human.

For adversarial attacks, English teachers (Human evaluation) rated sentences produced by hostile attacks lower than the original sentences on fluency and preservation of meaning. Further, ChatGPT gave higher ratings to hostile-attack sentences than English teachers. Also, ChatGPT rated hostile-attack sentences lower than the original sentences, and overall, the large-scale language models evaluated the quality of hostile-attack sentences and original sentences in the same way as humans.

The researchers noted the following four advantages of evaluation by large-scale language models: Reproducibility, Independence, Cost efficiency and speed, and Reduced exposure to objectionable content.
However, Large-scale language models are also susceptible to misinterpretation of facts, and the learning method can introduce biases. Moreover, the absence of emotions in these models might limit their efficacy in assessing tasks that involve emotions. Human evaluations and assessments from extensive language models have distinct strengths and weaknesses. Their optimal utility is likely to be achieved through a combination of humans and these large-scale models.


Check out the Paper. All Credit For This Research Goes To the Researchers on This Project. Also, don’t forget to join our 28k+ ML SubReddit, 40k+ Facebook Community, Discord Channel, and Email Newsletter, where we share the latest AI research news, cool AI projects, and more.


YOU MAY ALSO LIKE

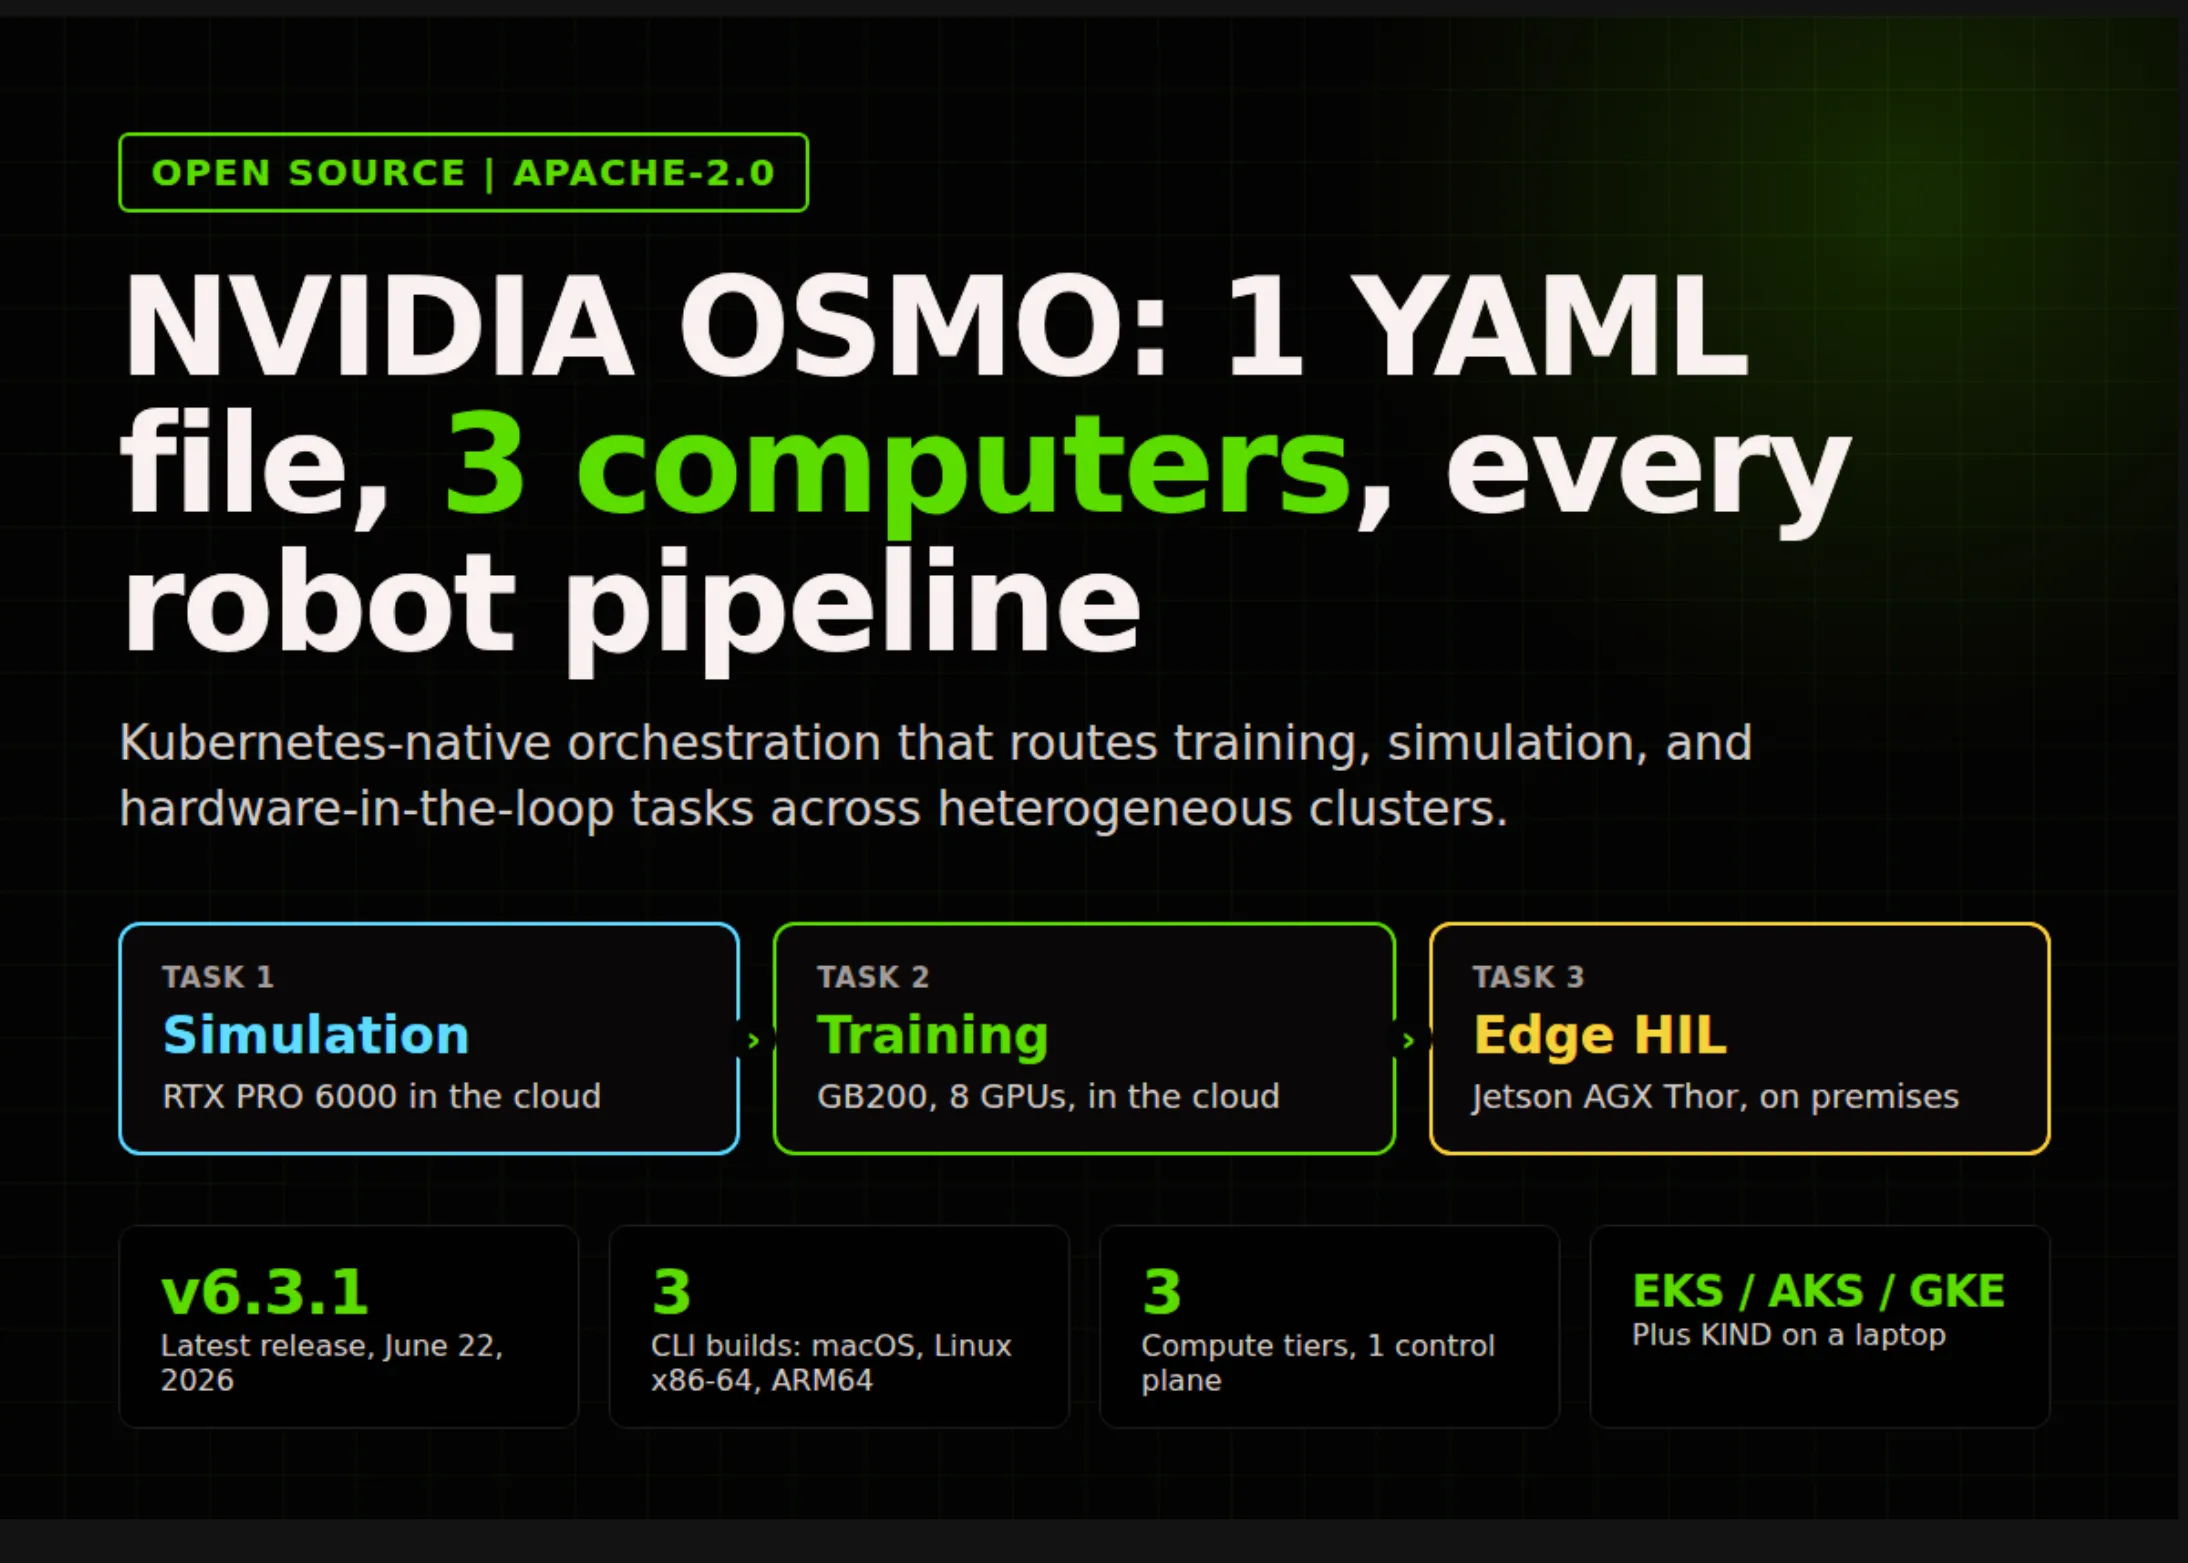
NVIDIA Open-Sources OSMO: One YAML Orchestrates Physical AI Training, Simulation, and Robot Testing

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?

Rachit Ranjan is a consulting intern at MarktechPost . He is currently pursuing his B.Tech from Indian Institute of Technology(IIT) Patna . He is actively shaping his career in the field of Artificial Intelligence and Data Science and is passionate and dedicated for exploring these fields.


🔥 Use SQL to predict the future (Sponsored)

Credit: Source link

ShareTweetSendSharePin

Related Posts

NVIDIA Open-Sources OSMO: One YAML Orchestrates Physical AI Training, Simulation, and Robot Testing
AI & Technology

NVIDIA Open-Sources OSMO: One YAML Orchestrates Physical AI Training, Simulation, and Robot Testing

September 14, 2026
Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?
AI & Technology

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?

September 14, 2026
Which Is Better For Charging Your MacBook?
AI & Technology

Which Is Better For Charging Your MacBook?

September 14, 2026
At What Length Do Ethernet Cables Drop To Lower Speeds?
AI & Technology

At What Length Do Ethernet Cables Drop To Lower Speeds?

September 14, 2026
Next Post
iRobot’s poop-detecting Roomba j7+ is at an all-time low price right now

iRobot’s poop-detecting Roomba j7+ is at an all-time low price right now

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Hurricane Lowell passing just west of Hawaii, bringing heavy rain, strong winds, punishing waves – CBS News

Hurricane Lowell passing just west of Hawaii, bringing heavy rain, strong winds, punishing waves – CBS News

September 8, 2026
Anthropic Details Disrupted Claude Misuse Across Seven Harm Areas – Unite.AI

Anthropic Details Disrupted Claude Misuse Across Seven Harm Areas – Unite.AI

September 10, 2026
Dante Moore struggles as Oregon loses to 24-point underdog Oklahoma State – NBC Sports

Dante Moore struggles as Oregon loses to 24-point underdog Oklahoma State – NBC Sports

September 12, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!