• bitcoinBitcoin(BTC)$77,069.000.21%
  • ethereumEthereum(ETH)$2,264.560.42%
  • tetherTether(USDT)$1.000.03%
  • binancecoinBNB(BNB)$693.68-0.88%
  • rippleXRP(XRP)$1.260.76%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$91.92-0.33%
  • tronTRON(TRX)$0.3216110.62%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.20%
  • zcashZcash(ZEC)$1,206.034.50%
  • HyperliquidHyperliquid(HYPE)$84.380.04%
  • moneroMonero(XMR)$628.153.46%
  • dogecoinDogecoin(DOGE)$0.0744250.02%
  • USDSUSDS(USDS)$1.00-0.01%
  • whitebitWhiteBIT Coin(WBT)$74.060.19%
  • leo-tokenLEO Token(LEO)$9.30-1.09%
  • chainlinkChainlink(LINK)$10.92-2.34%
  • cardanoCardano(ADA)$0.188152-0.75%
  • stellarStellar(XLM)$0.159758-1.88%
  • bitcoin-cashBitcoin Cash(BCH)$272.62-1.63%
  • nearNEAR Protocol(NEAR)$3.81-2.13%
  • RainRain(RAIN)$0.006613-3.64%
  • Ethena USDeEthena USDe(USDE)$1.000.11%
  • daiDai(DAI)$1.000.03%
  • uniswapUniswap(UNI)$7.150.08%
  • litecoinLitecoin(LTC)$53.62-0.82%
  • CantonCanton(CC)$0.0959191.80%
  • USD1USD1(USD1)$1.000.12%
  • avalanche-2Avalanche(AVAX)$8.450.23%
  • suiSui(SUI)$0.880.64%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.17-1.31%
  • tether-goldTether Gold(XAUT)$3,930.21-0.28%
  • hedera-hashgraphHedera(HBAR)$0.068990-1.20%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • quant-networkQuant(QNT)$190.82-2.04%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.02%
  • shiba-inuShiba Inu(SHIB)$0.000005-0.15%
  • BittensorBittensor(TAO)$223.45-0.48%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • crypto-com-chainCronos(CRO)$0.049959-0.54%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.01%
  • EthenaEthena(ENA)$0.170587-0.89%
  • okbOKB(OKB)$107.25-2.25%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.000005-0.06%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • MemeCoreMemeCore(M)$0.861.08%
  • Pump.funPump.fun(PUMP)$0.0042606.50%
  • aaveAave(AAVE)$126.03-0.71%
  • OndoOndo(ONDO)$0.384879-1.20%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

AI Interview Series #5: Prompt Caching

January 5, 2026
in AI & Technology
Reading Time: 7 mins read
A A
AI Interview Series #5: Prompt Caching
ShareShareShareShareShare

Question:

Imagine your company’s LLM API costs suddenly doubled last month. A deeper analysis shows that while user inputs look different at a text level, many of them are semantically similar. As an engineer, how would you identify and reduce this redundancy without impacting response quality?

What is Prompt Caching?

Prompt caching is an optimization technique used in AI systems to improve speed and reduce cost. Instead of sending the same long instructions, documents, or examples to the model repeatedly, the system reuses previously processed prompt content such as static instructions, prompt prefixes, or shared context. This helps save both input and output tokens while keeping responses consistent.

Consider a travel planning assistant where users frequently ask questions like “Create a 5-day itinerary for Paris focused on museums and food.” Even if different users phrase it slightly differently, the core intent and structure of the request remains the same. Without any optimization, the model has to read and process the full prompt every time, repeating the same computation and increasing both latency and cost.

With prompt caching, once the assistant processes this request the first time, the repeated parts of the prompt—such as the itinerary structure, constraints, and common instructions—are stored. When a similar request is sent again, the system reuses the previously processed content instead of starting from scratch. This results in faster responses and lower API costs, while still delivering accurate and consistent outputs.

What Gets Cached and Where It’s Stored

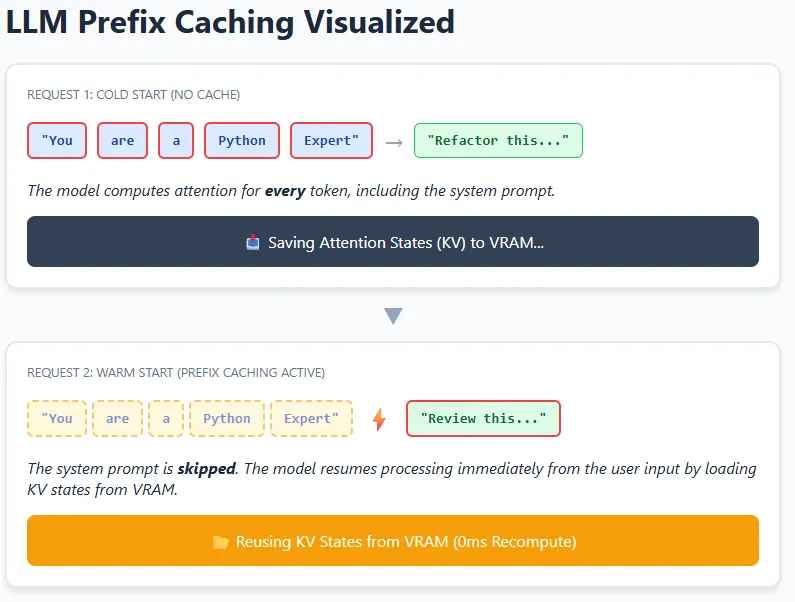
At a high level, caching in LLM systems can happen at different layers—ranging from simple token-level reuse to more advanced reuse of internal model states. In practice, modern LLMs mainly rely on Key–Value (KV) caching, where the model stores intermediate attention states in GPU memory (VRAM) so it doesn’t have to recompute them again.

Think of a coding assistant with a fixed system instruction like “You are an expert Python code reviewer.” This instruction appears in every request. When the model processes it once, the attention relationships (keys and values) between its tokens are stored. For future requests, the model can reuse these stored KV states and only compute attention for the new user input, such as the actual code snippet.

This idea is extended across requests using prefix caching. If multiple prompts start with the exact same prefix—same text, formatting, and spacing—the model can skip recomputing that entire prefix and resume from the cached point. This is especially effective in chatbots, agents, and RAG pipelines where system prompts and long instructions rarely change. The result is lower latency and reduced compute cost, while still allowing the model to fully understand and respond to new context.

Structuring Prompts for High Cache Efficiency

  • Place system instructions, roles, and shared context at the beginning of the prompt, and move user-specific or changing content to the end.
  • Avoid adding dynamic elements like timestamps, request IDs, or random formatting in the prefix, as even small changes reduce reuse.
  • Ensure structured data (for example, JSON context) is serialized in a consistent order and format to prevent unnecessary cache misses.
  • Regularly monitor cache hit rates and group similar requests together to maximize efficiency at scale.

Conclusion

In this situation, the goal is to reduce repeated computation while preserving response quality. An effective approach is to analyze incoming requests to identify shared structure, intent, or common prefixes, and then restructure prompts so that reusable context remains consistent across calls. This allows the system to avoid reprocessing the same information repeatedly, leading to lower latency and reduced API costs without changing the final output. 

For applications with long and repetitive prompts, prefix-based reuse can deliver significant savings, but it also introduces practical constraints—KV caches consume GPU memory, which is finite. As usage scales, cache eviction strategies or memory tiering become essential to balance performance gains with resource limits.

I am a Civil Engineering Graduate (2022) from Jamia Millia Islamia, New Delhi, and I have a keen interest in Data Science, especially Neural Networks and their application in various areas.

YOU MAY ALSO LIKE

Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI

Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’

Credit: Source link

ShareTweetSendSharePin

Related Posts

Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI
AI & Technology

Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI

November 3, 2026
Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’
AI & Technology

Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’

November 3, 2026
Traversal Raises 0M Series B at B Valuation to Expand AI SRE – Unite.AI
AI & Technology

Traversal Raises $120M Series B at $1B Valuation to Expand AI SRE – Unite.AI

November 3, 2026
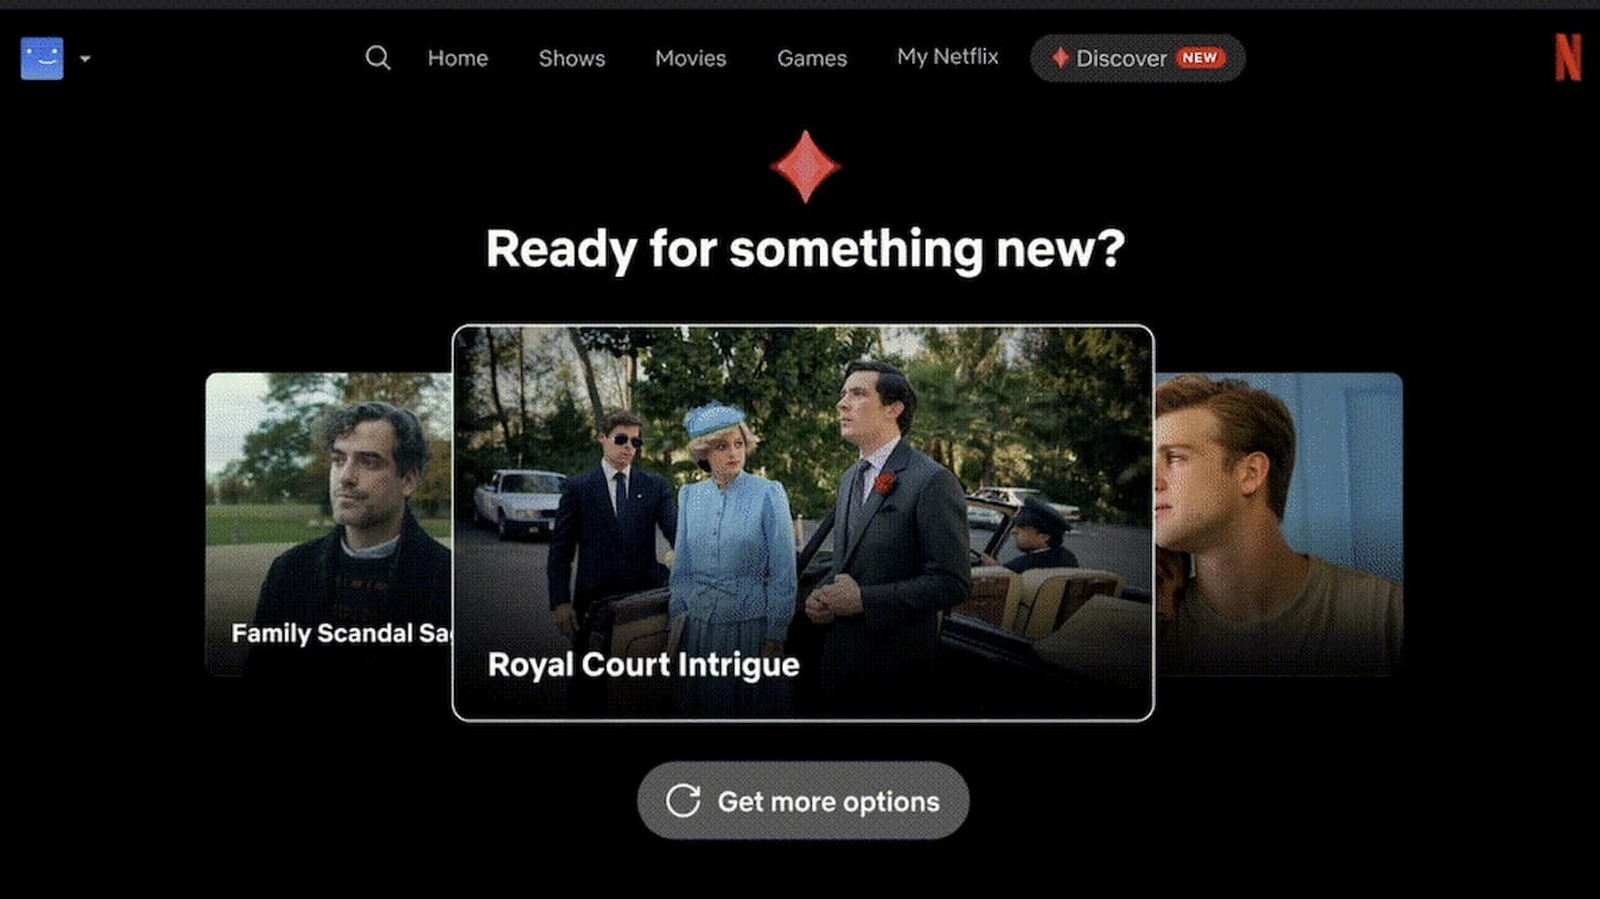
Netflix Thinks AI Might Save You From Scrolling Aimlessly For Something To Watch
AI & Technology

Netflix Thinks AI Might Save You From Scrolling Aimlessly For Something To Watch

November 3, 2026
Next Post
Ukraine launches sea drone attack on Russian submarine

Ukraine launches sea drone attack on Russian submarine

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Google DeepMind Introduces Gemini 4 Carbon, Its Top Model for Cyber Defense and Coding

Google DeepMind Introduces Gemini 4 Carbon, Its Top Model for Cyber Defense and Coding

October 28, 2026
Residents stock up on essentials as Hurricane Isaias approaches Southeast

Residents stock up on essentials as Hurricane Isaias approaches Southeast

October 29, 2026
Trump appears to clarify earlier remarks on L.A., San Diego

Trump appears to clarify earlier remarks on L.A., San Diego

October 29, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!