Introduction: The Rising Need for AI Guardrails
As large language models (LLMs) grow in capability and deployment scale, the risk of unintended behavior, hallucinations, and harmful outputs increases. The recent surge in real-world AI integrations across healthcare, finance, education, and defense sectors amplifies the demand for robust safety mechanisms. AI guardrails—technical and procedural controls ensuring alignment with human values and policies—have emerged as a critical area of focus.
The Stanford 2025 AI Index reported a 56.4% jump in AI-related incidents in 2024—233 cases in total—highlighting the urgency for robust guardrails. Meanwhile, the Future of Life Institute rated major AI firms poorly on AGI safety planning, with no firm receiving a rating higher than C+.
What Are AI Guardrails?
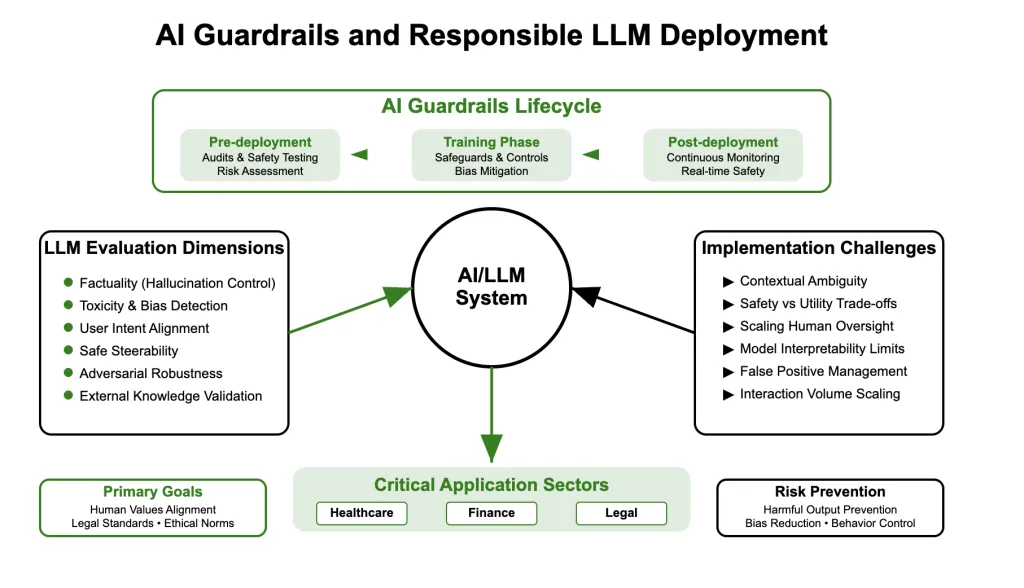
AI guardrails refer to system-level safety controls embedded within the AI pipeline. These are not merely output filters, but include architectural decisions, feedback mechanisms, policy constraints, and real-time monitoring. They can be classified into:
- Pre-deployment Guardrails: Dataset audits, model red-teaming, policy fine-tuning. For example, Aegis 2.0 includes 34,248 annotated interactions across 21 safety-relevant categories.
- Training-time Guardrails: Reinforcement learning with human feedback (RLHF), differential privacy, bias mitigation layers. Notably, overlapping datasets can collapse these guardrails and enable jailbreaks.
- Post-deployment Guardrails: Output moderation, continuous evaluation, retrieval-augmented validation, fallback routing. Unit 42’s June 2025 benchmark revealed high false positives in moderation tools.
Trustworthy AI: Principles and Pillars
Trustworthy AI is not a single technique but a composite of key principles:
- Robustness: The model should behave reliably under distributional shift or adversarial input.
- Transparency: The reasoning path must be explainable to users and auditors.
- Accountability: There should be mechanisms to trace model actions and failures.
- Fairness: Outputs should not perpetuate or amplify societal biases.
- Privacy Preservation: Techniques like federated learning and differential privacy are critical.
Legislative focus on AI governance has risen: in 2024 alone, U.S. agencies issued 59 AI-related regulations across 75 countries. UNESCO has also established global ethical guidelines.
LLM Evaluation: Beyond Accuracy
Evaluating LLMs extends far beyond traditional accuracy benchmarks. Key dimensions include:
- Factuality: Does the model hallucinate?
- Toxicity & Bias: Are the outputs inclusive and non-harmful?
- Alignment: Does the model follow instructions safely?
- Steerability: Can it be guided based on user intent?
- Robustness: How well does it resist adversarial prompts?
Evaluation Techniques
- Automated Metrics: BLEU, ROUGE, perplexity are still used but insufficient alone.
- Human-in-the-Loop Evaluations: Expert annotations for safety, tone, and policy compliance.
- Adversarial Testing: Using red-teaming techniques to stress test guardrail effectiveness.
- Retrieval-Augmented Evaluation: Fact-checking answers against external knowledge bases.
Multi-dimensional tools such as HELM (Holistic Evaluation of Language Models) and HolisticEval are being adopted.
Architecting Guardrails into LLMs
The integration of AI guardrails must begin at the design stage. A structured approach includes:
- Intent Detection Layer: Classifies potentially unsafe queries.
- Routing Layer: Redirects to retrieval-augmented generation (RAG) systems or human review.
- Post-processing Filters: Uses classifiers to detect harmful content before final output.
- Feedback Loops: Includes user feedback and continuous fine-tuning mechanisms.
Open-source frameworks like Guardrails AI and RAIL provide modular APIs to experiment with these components.
Challenges in LLM Safety and Evaluation
Despite advancements, major obstacles remain:
- Evaluation Ambiguity: Defining harmfulness or fairness varies across contexts.
- Adaptability vs. Control: Too many restrictions reduce utility.
- Scaling Human Feedback: Quality assurance for billions of generations is non-trivial.
- Opaque Model Internals: Transformer-based LLMs remain largely black-box despite interpretability efforts.
Recent studies show over-restricting guardrails often results in high false positives or unusable outputs (source).
Conclusion: Toward Responsible AI Deployment
Guardrails are not a final fix but an evolving safety net. Trustworthy AI must be approached as a systems-level challenge, integrating architectural robustness, continuous evaluation, and ethical foresight. As LLMs gain autonomy and influence, proactive LLM evaluation strategies will serve as both an ethical imperative and a technical necessity.
Organizations building or deploying AI must treat safety and trustworthiness not as afterthoughts, but as central design objectives. Only then can AI evolve as a reliable partner rather than an unpredictable risk.
FAQs on AI Guardrails and Responsible LLM Deployment
1. What exactly are AI guardrails, and why are they important?
AI guardrails are comprehensive safety measures embedded throughout the AI development lifecycle—including pre-deployment audits, training safeguards, and post-deployment monitoring—that help prevent harmful outputs, biases, and unintended behaviors. They are crucial for ensuring AI systems align with human values, legal standards, and ethical norms, especially as AI is increasingly used in sensitive sectors like healthcare and finance.
2. How are large language models (LLMs) evaluated beyond just accuracy?
LLMs are evaluated on multiple dimensions such as factuality (how often they hallucinate), toxicity and bias in outputs, alignment to user intent, steerability (ability to be guided safely), and robustness against adversarial prompts. This evaluation combines automated metrics, human reviews, adversarial testing, and fact-checking against external knowledge bases to ensure safer and more reliable AI behavior.
3. What are the biggest challenges in implementing effective AI guardrails?
Key challenges include ambiguity in defining harmful or biased behavior across different contexts, balancing safety controls with model utility, scaling human oversight for massive interaction volumes, and the inherent opacity of deep learning models which limits explainability. Overly restrictive guardrails can also lead to high false positives, frustrating users and limiting AI usefulness.

Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.
Credit: Source link