• bitcoinBitcoin(BTC)$85,739.006.33%
  • ethereumEthereum(ETH)$2,733.875.88%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$795.975.60%
  • rippleXRP(XRP)$1.498.11%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$117.918.89%
  • tronTRON(TRX)$0.344794-0.08%
  • zcashZcash(ZEC)$1,521.855.94%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.020.00%
  • HyperliquidHyperliquid(HYPE)$93.973.17%
  • dogecoinDogecoin(DOGE)$0.0935949.87%
  • moneroMonero(XMR)$576.076.47%
  • whitebitWhiteBIT Coin(WBT)$86.255.25%
  • RainRain(RAIN)$0.0140929.31%
  • chainlinkChainlink(LINK)$12.976.86%
  • USDSUSDS(USDS)$1.000.00%
  • cardanoCardano(ADA)$0.2421399.15%
  • leo-tokenLEO Token(LEO)$8.990.59%
  • stellarStellar(XLM)$0.2086568.85%
  • uniswapUniswap(UNI)$8.863.09%
  • bitcoin-cashBitcoin Cash(BCH)$267.778.88%
  • nearNEAR Protocol(NEAR)$4.1011.31%
  • avalanche-2Avalanche(AVAX)$11.192.76%
  • Ethena USDeEthena USDe(USDE)$1.000.01%
  • litecoinLitecoin(LTC)$62.489.34%
  • daiDai(DAI)$1.000.00%
  • CantonCanton(CC)$0.1147298.62%
  • USD1USD1(USD1)$1.000.01%
  • suiSui(SUI)$1.0425.67%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.434.27%
  • hedera-hashgraphHedera(HBAR)$0.0910313.72%
  • MemeCoreMemeCore(M)$1.50-3.02%
  • shiba-inuShiba Inu(SHIB)$0.0000067.43%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • BittensorBittensor(TAO)$283.3312.39%
  • crypto-com-chainCronos(CRO)$0.0639529.40%
  • paypal-usdPayPal USD(PYUSD)$1.000.01%
  • tether-goldTether Gold(XAUT)$4,336.16-0.75%
  • okbOKB(OKB)$122.545.25%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • BitwayBitway(BTW)$0.9025.28%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.140.48%
  • EthenaEthena(ENA)$0.22296510.86%
  • aaveAave(AAVE)$145.157.93%
  • OndoOndo(ONDO)$0.4474189.15%
  • mantleMantle(MNT)$0.636.14%
  • AsterAster(ASTER)$0.763.46%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Researchers at Google Deepmind Introduce BOND: A Novel RLHF Method that Fine-Tunes the Policy via Online Distillation of the Best-of-N Sampling Distribution

July 24, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Researchers at Google Deepmind Introduce BOND: A Novel RLHF Method that Fine-Tunes the Policy via Online Distillation of the Best-of-N Sampling Distribution
ShareShareShareShareShare

Reinforcement learning from human feedback RLHF is essential for ensuring quality and safety in LLMs. State-of-the-art LLMs like Gemini and GPT-4 undergo three training stages: pre-training on large corpora, SFT, and RLHF to refine generation quality. RLHF involves training a reward model (RM) based on human preferences and optimizing the LLM to maximize predicted rewards. This process is challenging due to forgetting pre-trained knowledge and reward hacking. A practical approach to enhance generation quality is Best-of-N sampling, which selects the best output from N-generated candidates, effectively balancing reward and computational cost.

Researchers at Google DeepMind have introduced Best-of-N Distillation (BOND), an innovative RLHF algorithm designed to replicate the performance of Best-of-N sampling without its high computational cost. BOND is a distribution matching algorithm that aligns the policy’s output with the Best-of-N distribution. Using Jeffreys divergence, which balances mode-covering and mode-seeking behaviors, BOND iteratively refines the policy through a moving anchor approach. Experiments on abstractive summarization and Gemma models show that BOND, particularly its variant J-BOND, outperforms other RLHF algorithms by enhancing KL-reward trade-offs and benchmark performance.

YOU MAY ALSO LIKE

A Laptop That Works Better With Your Android Phone

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI

Best-of-N sampling optimizes language generation against a reward function but is computationally expensive. Recent studies have refined its theoretical foundations, provided reward estimators, and explored its connections to KL-constrained reinforcement learning. Various methods have been proposed to match the Best-of-N strategy, such as supervised fine-tuning on Best-of-N data and preference optimization. BOND introduces a novel approach using Jeffreys divergence and iterative distillation with a dynamic anchor to efficiently achieve the benefits of Best-of-N sampling. This method focuses on investing resources during training to reduce inference-time computational demands, aligning with principles of iterated amplification.

The BOND approach involves two main steps. First, it derives an analytical expression for the Best-of-N (BoN) distribution. Second, it frames the task as a distribution matching problem, aiming to align the policy with the BoN distribution. The analytical expression shows that BoN reweights the reference distribution, discouraging poor generations as N increases. The BOND objective seeks to minimize divergence between the policy and BoN distribution. The Jeffreys divergence, balancing forward and backward KL divergences, is proposed for robust distribution matching. Iterative BOND refines the policy by repeatedly applying the BoN distillation with a small N, enhancing performance and stability.

J-BOND is a practical implementation of the BOND algorithm designed for fine-tuning policies with minimal sample complexity. It iteratively refines the policy to align with the Best-of-2 samples using the Jeffreys divergence. The process involves generating samples, calculating gradients for forward and backward KL components, and updating policy weights. The anchor policy is updated using an Exponential Moving Average (EMA), which enhances training stability and improves the reward/KL trade-off. Experiments show that J-BOND outperforms traditional RLHF methods, demonstrating effectiveness and better performance without needing a fixed regularization level.

BOND is a new RLHF method that fine-tunes policies through the online distillation of the Best-of-N sampling distribution. The J-BOND algorithm enhances practicality and efficiency by integrating Monte-Carlo quantile estimation, combining forward and backward KL divergence objectives, and using an iterative procedure with an exponential moving average anchor. This approach improves the KL-reward Pareto front and outperforms state-of-the-art baselines. By emulating the Best-of-N strategy without its computational overhead, BOND aligns policy distributions closer to the Best-of-N distribution, demonstrating its effectiveness in experiments on abstractive summarization and Gemma models.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter..

Don’t Forget to join our 47k+ ML SubReddit

Find Upcoming AI Webinars here

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.


Credit: Source link

ShareTweetSendSharePin

Related Posts

A Laptop That Works Better With Your Android Phone
AI & Technology

A Laptop That Works Better With Your Android Phone

September 21, 2026
How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI
AI & Technology

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI

September 21, 2026
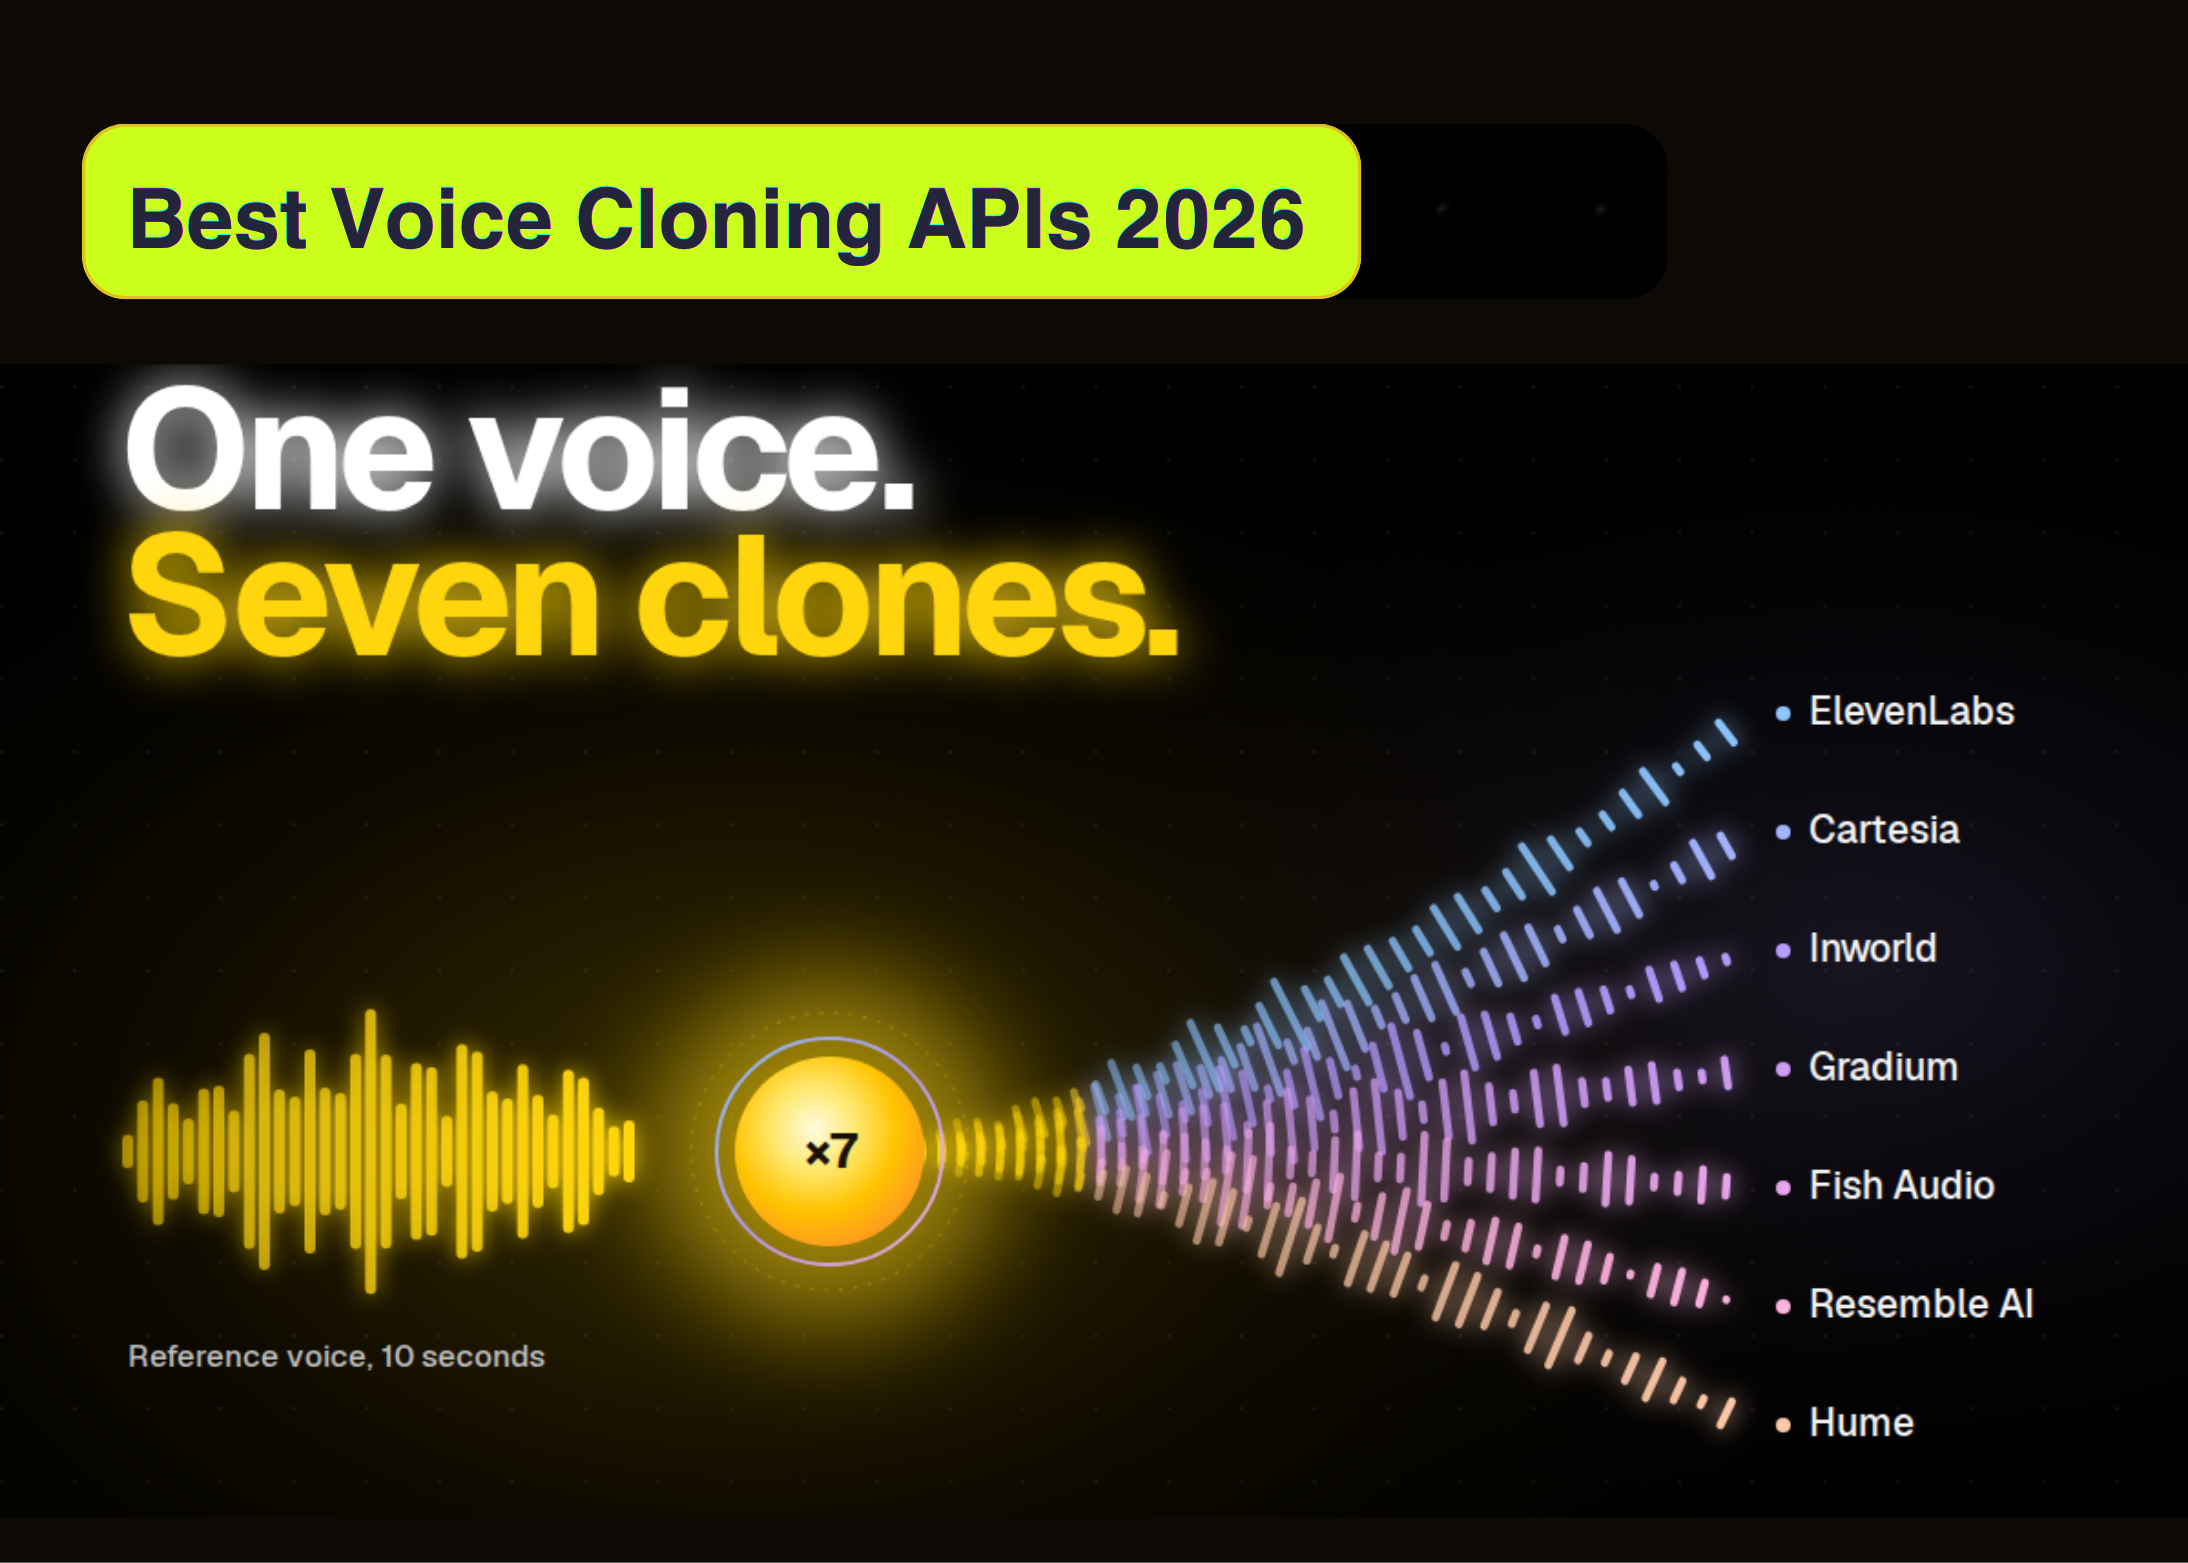
Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters
AI & Technology

Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters

September 21, 2026
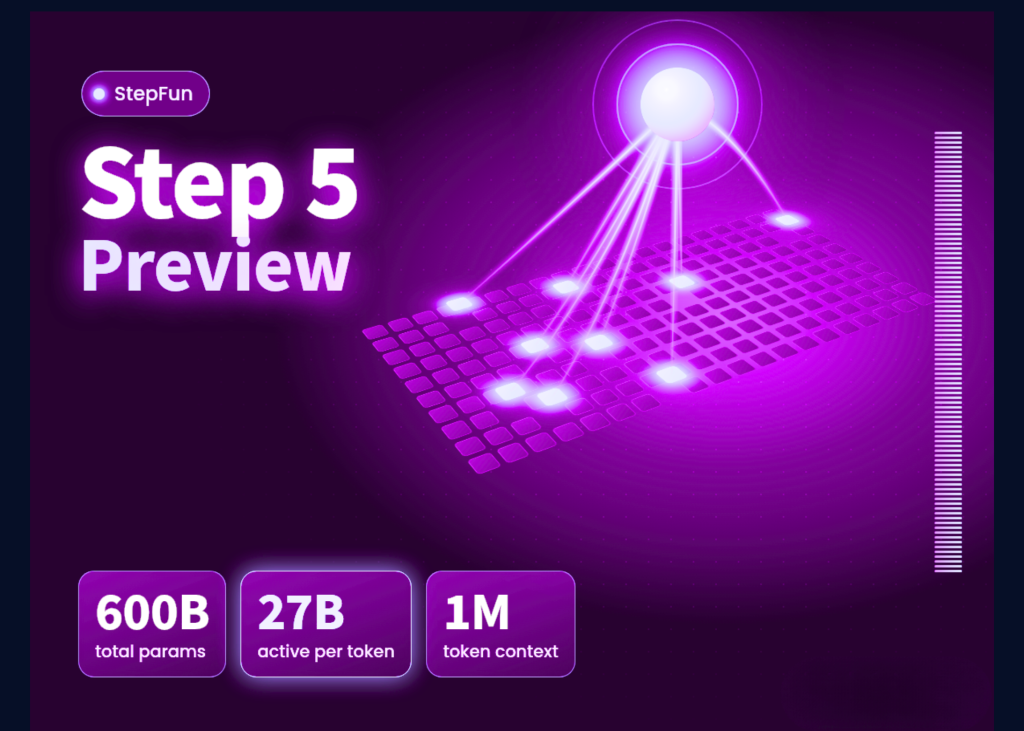
StepFun Launches Step 5 Preview: A 600B-Total, 27B-Active MoE Model With 1M Context for Long-Horizon Agentic Work
AI & Technology

StepFun Launches Step 5 Preview: A 600B-Total, 27B-Active MoE Model With 1M Context for Long-Horizon Agentic Work

September 21, 2026
Next Post
Home goods retailer Conn’s files for bankruptcy, closing over 70 stores

Home goods retailer Conn's files for bankruptcy, closing over 70 stores

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Raskin says its more important for Democrats to address healthcare

Raskin says its more important for Democrats to address healthcare

September 16, 2026
New AI Glasses, A Mixed Reality Headset And More

New AI Glasses, A Mixed Reality Headset And More

September 18, 2026
Is There Any Benefit To Keeping Your Smart TV In Standby Mode?

Is There Any Benefit To Keeping Your Smart TV In Standby Mode?

September 20, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!