• bitcoinBitcoin(BTC)$85,413.006.07%
  • ethereumEthereum(ETH)$2,732.595.95%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$790.815.30%
  • rippleXRP(XRP)$1.498.22%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$117.899.06%
  • tronTRON(TRX)$0.344722-0.50%
  • zcashZcash(ZEC)$1,536.636.52%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.020.00%
  • HyperliquidHyperliquid(HYPE)$94.784.23%
  • dogecoinDogecoin(DOGE)$0.0933969.98%
  • moneroMonero(XMR)$575.506.85%
  • whitebitWhiteBIT Coin(WBT)$86.035.06%
  • RainRain(RAIN)$0.0141026.79%
  • chainlinkChainlink(LINK)$13.028.01%
  • USDSUSDS(USDS)$1.000.00%
  • cardanoCardano(ADA)$0.24473010.46%
  • leo-tokenLEO Token(LEO)$8.990.81%
  • stellarStellar(XLM)$0.2091479.70%
  • uniswapUniswap(UNI)$8.924.20%
  • bitcoin-cashBitcoin Cash(BCH)$268.959.31%
  • nearNEAR Protocol(NEAR)$4.1412.40%
  • avalanche-2Avalanche(AVAX)$11.266.40%
  • Ethena USDeEthena USDe(USDE)$1.000.00%
  • litecoinLitecoin(LTC)$62.519.71%
  • daiDai(DAI)$1.000.02%
  • CantonCanton(CC)$0.1149869.78%
  • USD1USD1(USD1)$1.000.02%
  • suiSui(SUI)$1.0427.06%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.433.95%
  • hedera-hashgraphHedera(HBAR)$0.0909696.07%
  • shiba-inuShiba Inu(SHIB)$0.0000067.08%
  • MemeCoreMemeCore(M)$1.48-3.82%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • BittensorBittensor(TAO)$285.6913.68%
  • crypto-com-chainCronos(CRO)$0.0636349.03%
  • paypal-usdPayPal USD(PYUSD)$1.000.01%
  • tether-goldTether Gold(XAUT)$4,349.01-0.45%
  • okbOKB(OKB)$122.365.43%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BitwayBitway(BTW)$0.8625.17%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • EthenaEthena(ENA)$0.22496411.54%
  • aaveAave(AAVE)$145.668.98%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.02%
  • OndoOndo(ONDO)$0.45187111.12%
  • mantleMantle(MNT)$0.636.93%
  • AsterAster(ASTER)$0.763.83%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

This AI Paper from China Propose ‘Magnus’: Revolutionizing Efficient LLM Serving for LMaaS with Semantic-Based Request Length Prediction

June 14, 2024
in AI & Technology
Reading Time: 4 mins read
A A
This AI Paper from China Propose ‘Magnus’: Revolutionizing Efficient LLM Serving for LMaaS with Semantic-Based Request Length Prediction
ShareShareShareShareShare

Transformer-based generative Large Language Models (LLMs) have shown considerable strength in a broad range of Natural Language Processing (NLP) tasks. Numerous applications benefit from its wide applicability; however, for most developers, the expense of training and implementing these models is frequently prohibitive. For this, top AI firms like OpenAI, Google, and Baidu offer a language model-as-a-service (LMaaS) by granting access to their LLMs through APIs.

Application developers provide the LLM service with user input messages and particular instructions in an LMaaS scenario. To provide better quality of service (QoS) and support more customers, service providers strive to decrease response times and boost throughput. However, there are inefficiencies in the way that current systems, such as TensorFlow Serving and Triton Inference Server, handle queries. They do it in a first-come, first-served (FCFS) fashion with a predetermined batch size. These systems employ limited batch sizes, which restricts the GPUs’ capacity for parallel computation to prevent out-of-memory (OOM) issues.

Continuous batching has been suggested to address this, which dynamically eliminates finished requests and adds new ones while processing. This approach frequently uses conservative GPU memory management techniques, which limit throughput by not taking full advantage of the GPUs’ parallel processing capacity. Although they promise to reduce memory, other strategies like model quantization and pruning may lower the caliber of the generated output.

It has been noted that in many applications, there is a positive correlation between the length of the text that is created and the text that is entered by the user. This is particularly true for jobs like code translation, bug patching, text detoxification, grammatical correction, multilingual machine translation, and code commenting. The duration of the user’s input and the output that is produced are discovered to be strongly positively correlated by examining the requests made by these applications. The batching process can be made more efficient by using this correlation to forecast the duration of created requests.

A team of AI researchers from China has proposed Magnus, a system that employs application-level and user-level semantic information in conjunction with the length of the user’s input to forecast request generation lengths properly. Four parts make up Magnus: a batch scheduler, an adaptive batcher, a serving time estimator, and a generation length predictor. The generation length predictor estimates request lengths based on user input, application-level semantic characteristics, and user-level semantic features using a random forest regressor. In order to minimize computational waste, the adaptive batcher groups requests with similar projected lengths and chooses the right batch size.

The batch scheduler chooses batches based on the highest response ratio next (HRRN) policy, minimizing request queue times and reducing response times, and the serving time estimator employs KNN regression to predict batch serving times in order to further improve QoS. 

When Magnus’ prototype system was tested using ChatGLM-6B instances on NVIDIA V100 GPUs, it showed notable gains over the baselines in terms of serving latency, request throughput, and serving efficiency. The testbed’s experimental results showed that, in comparison to baseline approaches, Magnus increases request throughput by up to 234% and reduces response times by up to 89.7%. This enhancement demonstrates how well batch serving in LMaaS can be optimized by employing generation length estimates.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 44k+ ML SubReddit


YOU MAY ALSO LIKE

A Laptop That Works Better With Your Android Phone

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI

Tanya Malhotra is a final year undergrad from the University of Petroleum & Energy Studies, Dehradun, pursuing BTech in Computer Science Engineering with a specialization in Artificial Intelligence and Machine Learning.
She is a Data Science enthusiast with good analytical and critical thinking, along with an ardent interest in acquiring new skills, leading groups, and managing work in an organized manner.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

A Laptop That Works Better With Your Android Phone
AI & Technology

A Laptop That Works Better With Your Android Phone

September 21, 2026
How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI
AI & Technology

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI

September 21, 2026
Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters
AI & Technology

Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters

September 21, 2026
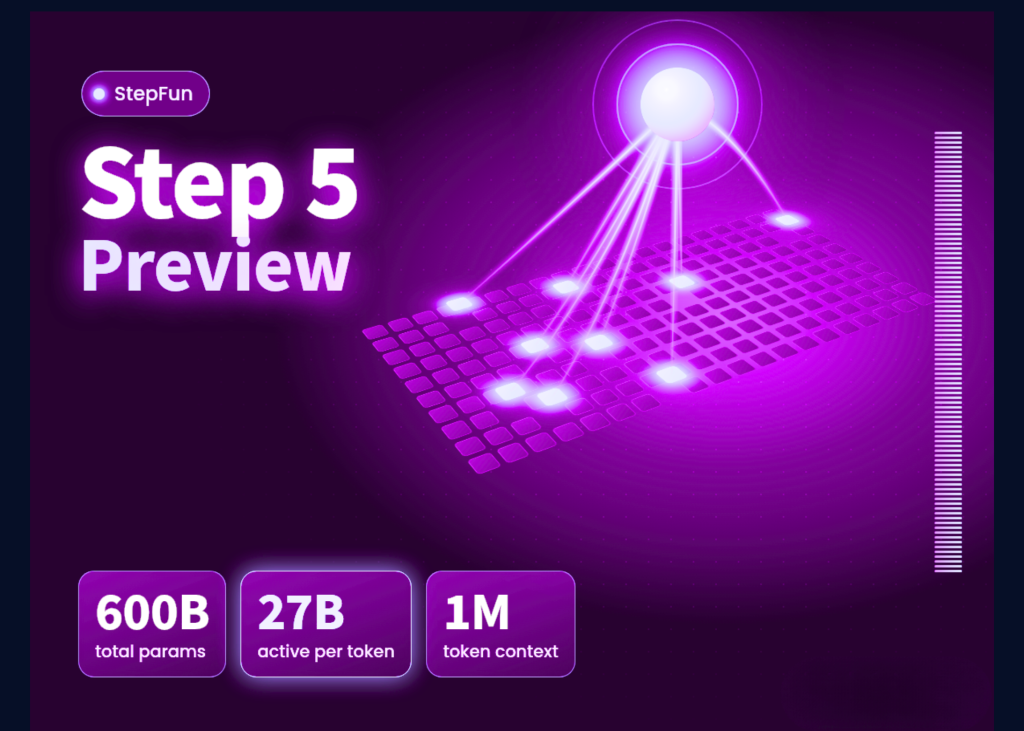
StepFun Launches Step 5 Preview: A 600B-Total, 27B-Active MoE Model With 1M Context for Long-Horizon Agentic Work
AI & Technology

StepFun Launches Step 5 Preview: A 600B-Total, 27B-Active MoE Model With 1M Context for Long-Horizon Agentic Work

September 21, 2026
Next Post
Mark Meadows appeals ruling to move Georgia election case to federal court

Mark Meadows appeals ruling to move Georgia election case to federal court

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
A first of its kind organ transplant technique tried on a human subject

A first of its kind organ transplant technique tried on a human subject

September 17, 2026
President Trump calls Clancy case a ‘horrible tragedy’

President Trump calls Clancy case a ‘horrible tragedy’

September 17, 2026
Z.ai Details GLM-5.3-Flash Inference Build on 100,000 Chinese Chips – Unite.AI

Z.ai Details GLM-5.3-Flash Inference Build on 100,000 Chinese Chips – Unite.AI

September 17, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!