• bitcoinBitcoin(BTC)$80,426.00-1.01%
  • ethereumEthereum(ETH)$2,573.88-2.43%
  • tetherTether(USDT)$1.00-0.02%
  • binancecoinBNB(BNB)$751.12-2.00%
  • rippleXRP(XRP)$1.38-3.64%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$108.30-3.16%
  • tronTRON(TRX)$0.3421521.29%
  • zcashZcash(ZEC)$1,442.84-6.78%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.02-1.32%
  • HyperliquidHyperliquid(HYPE)$91.04-1.26%
  • dogecoinDogecoin(DOGE)$0.084856-3.76%
  • moneroMonero(XMR)$523.92-11.24%
  • whitebitWhiteBIT Coin(WBT)$81.77-1.59%
  • USDSUSDS(USDS)$1.00-0.02%
  • RainRain(RAIN)$0.013189-5.36%
  • chainlinkChainlink(LINK)$12.04-3.84%
  • cardanoCardano(ADA)$0.220506-2.46%
  • leo-tokenLEO Token(LEO)$8.950.48%
  • stellarStellar(XLM)$0.189782-2.09%
  • uniswapUniswap(UNI)$8.75-3.89%
  • bitcoin-cashBitcoin Cash(BCH)$245.89-2.31%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • nearNEAR Protocol(NEAR)$3.59-2.35%
  • daiDai(DAI)$1.000.01%
  • avalanche-2Avalanche(AVAX)$10.037.87%
  • litecoinLitecoin(LTC)$57.04-1.11%
  • USD1USD1(USD1)$1.00-0.03%
  • CantonCanton(CC)$0.103879-6.37%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.37-0.06%
  • hedera-hashgraphHedera(HBAR)$0.0808070.58%
  • suiSui(SUI)$0.82-4.98%
  • MemeCoreMemeCore(M)$1.4713.89%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.000005-2.39%
  • crypto-com-chainCronos(CRO)$0.057857-3.42%
  • BittensorBittensor(TAO)$250.33-7.58%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.02%
  • tether-goldTether Gold(XAUT)$4,368.36-0.11%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • okbOKB(OKB)$115.50-4.77%
  • Ripple USDRipple USD(RLUSD)$1.00-0.02%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.41%
  • aaveAave(AAVE)$135.32-5.62%
  • EthenaEthena(ENA)$0.2050197.43%
  • OndoOndo(ONDO)$0.4118350.18%
  • AsterAster(ASTER)$0.73-4.27%
  • mantleMantle(MNT)$0.59-3.08%
  • BitwayBitway(BTW)$0.7214.88%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

This AI Paper from China Propose ‘Magnus’: Revolutionizing Efficient LLM Serving for LMaaS with Semantic-Based Request Length Prediction

June 14, 2024
in AI & Technology
Reading Time: 4 mins read
A A
This AI Paper from China Propose ‘Magnus’: Revolutionizing Efficient LLM Serving for LMaaS with Semantic-Based Request Length Prediction
ShareShareShareShareShare

Transformer-based generative Large Language Models (LLMs) have shown considerable strength in a broad range of Natural Language Processing (NLP) tasks. Numerous applications benefit from its wide applicability; however, for most developers, the expense of training and implementing these models is frequently prohibitive. For this, top AI firms like OpenAI, Google, and Baidu offer a language model-as-a-service (LMaaS) by granting access to their LLMs through APIs.

Application developers provide the LLM service with user input messages and particular instructions in an LMaaS scenario. To provide better quality of service (QoS) and support more customers, service providers strive to decrease response times and boost throughput. However, there are inefficiencies in the way that current systems, such as TensorFlow Serving and Triton Inference Server, handle queries. They do it in a first-come, first-served (FCFS) fashion with a predetermined batch size. These systems employ limited batch sizes, which restricts the GPUs’ capacity for parallel computation to prevent out-of-memory (OOM) issues.

Continuous batching has been suggested to address this, which dynamically eliminates finished requests and adds new ones while processing. This approach frequently uses conservative GPU memory management techniques, which limit throughput by not taking full advantage of the GPUs’ parallel processing capacity. Although they promise to reduce memory, other strategies like model quantization and pruning may lower the caliber of the generated output.

It has been noted that in many applications, there is a positive correlation between the length of the text that is created and the text that is entered by the user. This is particularly true for jobs like code translation, bug patching, text detoxification, grammatical correction, multilingual machine translation, and code commenting. The duration of the user’s input and the output that is produced are discovered to be strongly positively correlated by examining the requests made by these applications. The batching process can be made more efficient by using this correlation to forecast the duration of created requests.

A team of AI researchers from China has proposed Magnus, a system that employs application-level and user-level semantic information in conjunction with the length of the user’s input to forecast request generation lengths properly. Four parts make up Magnus: a batch scheduler, an adaptive batcher, a serving time estimator, and a generation length predictor. The generation length predictor estimates request lengths based on user input, application-level semantic characteristics, and user-level semantic features using a random forest regressor. In order to minimize computational waste, the adaptive batcher groups requests with similar projected lengths and chooses the right batch size.

The batch scheduler chooses batches based on the highest response ratio next (HRRN) policy, minimizing request queue times and reducing response times, and the serving time estimator employs KNN regression to predict batch serving times in order to further improve QoS. 

When Magnus’ prototype system was tested using ChatGLM-6B instances on NVIDIA V100 GPUs, it showed notable gains over the baselines in terms of serving latency, request throughput, and serving efficiency. The testbed’s experimental results showed that, in comparison to baseline approaches, Magnus increases request throughput by up to 234% and reduces response times by up to 89.7%. This enhancement demonstrates how well batch serving in LMaaS can be optimized by employing generation length estimates.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 44k+ ML SubReddit


YOU MAY ALSO LIKE

How China Is Changing AI

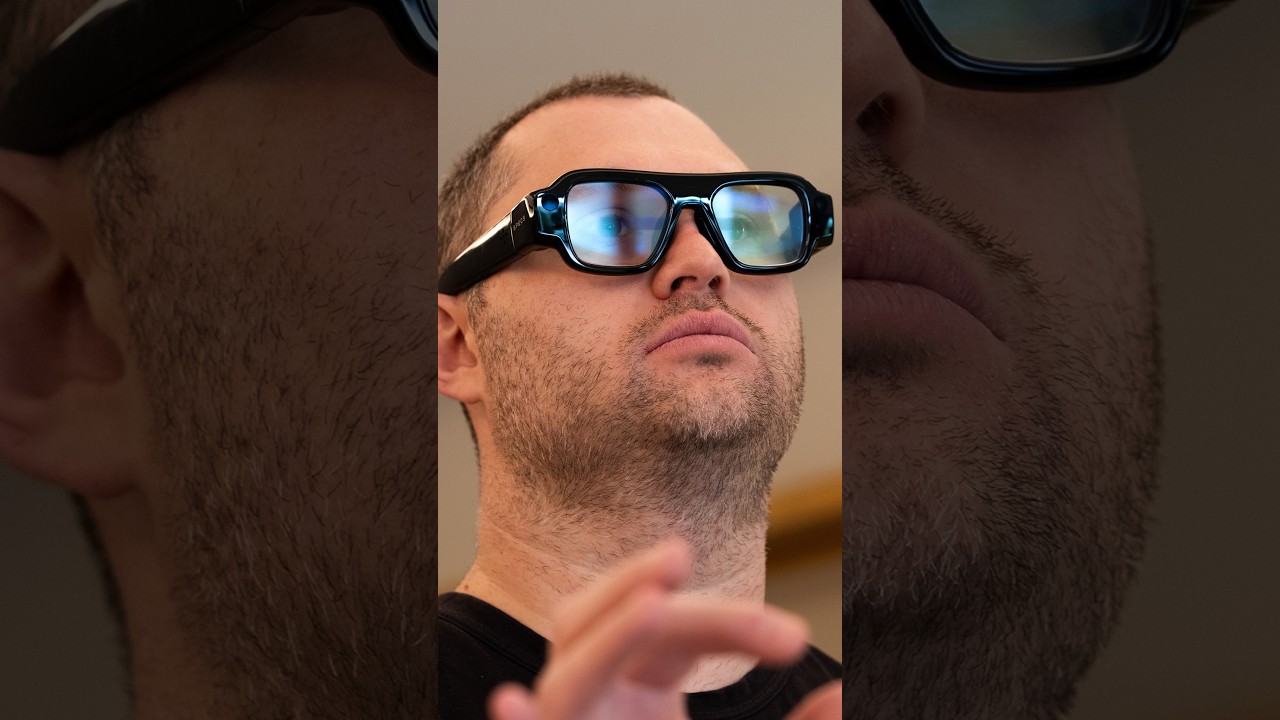
Snap Makes Its Case for Wearing A Computer On Your Face

Tanya Malhotra is a final year undergrad from the University of Petroleum & Energy Studies, Dehradun, pursuing BTech in Computer Science Engineering with a specialization in Artificial Intelligence and Machine Learning.
She is a Data Science enthusiast with good analytical and critical thinking, along with an ardent interest in acquiring new skills, leading groups, and managing work in an organized manner.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

How China Is Changing AI
AI & Technology

How China Is Changing AI

September 20, 2026
Snap Makes Its Case for Wearing A Computer On Your Face
AI & Technology

Snap Makes Its Case for Wearing A Computer On Your Face

September 20, 2026
Trump Opposes AI Guardrails Amid Chip Selloff
AI & Technology

Trump Opposes AI Guardrails Amid Chip Selloff

September 20, 2026
Anthropic’s Claude Takes Bigger Role in Building AI
AI & Technology

Anthropic’s Claude Takes Bigger Role in Building AI

September 20, 2026
Next Post
Mark Meadows appeals ruling to move Georgia election case to federal court

Mark Meadows appeals ruling to move Georgia election case to federal court

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Staten Island barge fire kills one

Staten Island barge fire kills one

September 14, 2026
King Charles says Harry and Meghan will not return as working royals

King Charles says Harry and Meghan will not return as working royals

September 16, 2026
1984 track champ preps South LA bakery for 2028 Olympics

1984 track champ preps South LA bakery for 2028 Olympics

September 15, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!