• bitcoinBitcoin(BTC)$77,672.001.37%
  • ethereumEthereum(ETH)$2,292.801.97%
  • tetherTether(USDT)$1.000.03%
  • binancecoinBNB(BNB)$698.690.54%
  • rippleXRP(XRP)$1.282.00%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$92.821.10%
  • tronTRON(TRX)$0.3211760.14%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.23%
  • zcashZcash(ZEC)$1,252.4310.99%
  • HyperliquidHyperliquid(HYPE)$84.591.46%
  • moneroMonero(XMR)$637.464.80%
  • dogecoinDogecoin(DOGE)$0.0745890.83%
  • USDSUSDS(USDS)$1.000.05%
  • whitebitWhiteBIT Coin(WBT)$74.701.42%
  • leo-tokenLEO Token(LEO)$9.30-0.48%
  • chainlinkChainlink(LINK)$11.02-0.46%
  • cardanoCardano(ADA)$0.1898211.17%
  • stellarStellar(XLM)$0.1621600.47%
  • bitcoin-cashBitcoin Cash(BCH)$273.64-0.58%
  • nearNEAR Protocol(NEAR)$3.882.23%
  • daiDai(DAI)$1.000.01%
  • Ethena USDeEthena USDe(USDE)$1.000.10%
  • RainRain(RAIN)$0.006254-0.23%
  • uniswapUniswap(UNI)$7.284.17%
  • litecoinLitecoin(LTC)$54.040.23%
  • CantonCanton(CC)$0.0981724.89%
  • avalanche-2Avalanche(AVAX)$8.562.81%
  • USD1USD1(USD1)$1.000.09%
  • suiSui(SUI)$0.892.73%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.170.30%
  • tether-goldTether Gold(XAUT)$3,971.121.53%
  • hedera-hashgraphHedera(HBAR)$0.069409-0.31%
  • quant-networkQuant(QNT)$194.760.04%
  • Global DollarGlobal Dollar(USDG)$1.000.03%
  • shiba-inuShiba Inu(SHIB)$0.0000051.22%
  • paypal-usdPayPal USD(PYUSD)$1.000.04%
  • BittensorBittensor(TAO)$227.092.10%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • crypto-com-chainCronos(CRO)$0.0502720.68%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.04%
  • EthenaEthena(ENA)$0.1782304.89%
  • okbOKB(OKB)$108.09-0.16%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.0000055.68%
  • aaveAave(AAVE)$128.842.60%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Pump.funPump.fun(PUMP)$0.00430710.15%
  • MemeCoreMemeCore(M)$0.852.16%
  • OndoOndo(ONDO)$0.3953673.19%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Can Large Language Models be Trusted for Evaluation? Meet SCALEEVAL: An Agent-Debate-Assisted Meta-Evaluation Framework that Leverages the Capabilities of Multiple Communicative LLM Agents

February 12, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Can Large Language Models be Trusted for Evaluation? Meet SCALEEVAL: An Agent-Debate-Assisted Meta-Evaluation Framework that Leverages the Capabilities of Multiple Communicative LLM Agents
ShareShareShareShareShare

Despite the utility of large language models (LLMs) across various tasks and scenarios, researchers need help to evaluate LLMs properly in different situations. They use LLMs to check their responses, but a solution must be found. This method is limited because there aren’t enough benchmarks, and it often requires a lot of human input. They urgently need better ways to test how well LLMs can evaluate things in all situations, especially when users define new scenarios.

LLMs have advanced significantly, demonstrating impressive performance across various tasks. However, evaluating their outputs presents complex challenges. Current approaches primarily rely on automated metrics, often employing LLMs for evaluation. While some functions undergo rigorous meta-evaluation, requiring costly human-annotated datasets, many applications need more scrutiny, leading to potential unreliability in LLMs as evaluators.

Researchers from Shanghai Jiao Tong University, Carnegie Mellon University, Shanghai Artificial Intelligence Laboratory, and Generative AI Research Lab (GAIR) introduce SCALEEVAL, a meta-evaluation framework utilizing multiple communicative LLM agents with an agent-debate approach. This system facilitates multi-round discussions, aiding human annotators in identifying the most proficient LLMs for evaluation. This approach substantially reduces the burden on annotators, especially in scenarios where extensive annotations were traditionally necessary for meta-evaluation.

SCALEEVAL leverages multi-agent debate for reliable meta-evaluation of LLMs. In the meta-evaluation process, LLM agents engage in rounds of discussions to assess responses based on user-defined criteria. This reduces the reliance on extensive human annotation and ensures scalability. The evaluation framework involves pairwise response comparisons, focusing on LLMs like gpt-3.5-turbo. Human expert meta-meta evaluation validates the proposed method’s reliability by applying the agent-debate-assisted and human expert annotation protocols. This approach balances efficiency with human judgment for accurate and timely assessments.
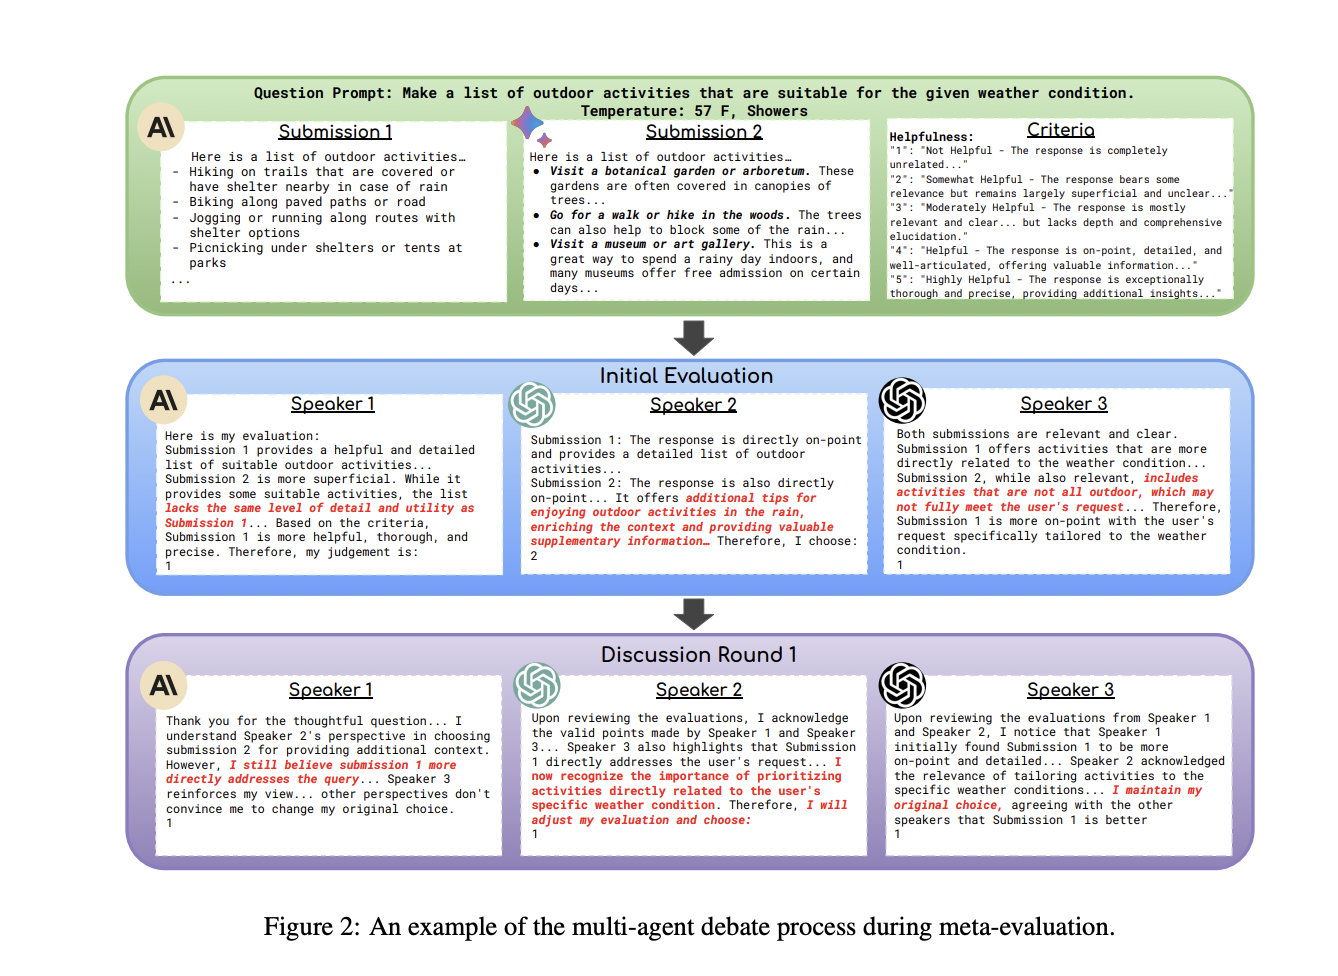
Studies reveal that LLMs’ performance as evaluators tends to decline when specific letters in criteria prompts are masked. The removal of guiding phrases further diminishes effectiveness. Gpt-4-turbo and gpt-3.5-turbo exhibit resilience, maintaining consistent agreement rates across criteria formats. In contrast, Claude-2 displays confusion and reluctance, especially with adversarial prompts, rejecting approximately half of the questions. The tested LLMs struggle with substituted criteria information, indicating room for improvement in their design and application despite their advanced capabilities.

In conclusion, The researchers have introduced SCALEEVAL, a scalable meta-evaluation framework utilizing agent-debate assistance to assess LLMs as evaluators. This proposal addresses the inefficiencies of conventional, resource-intensive meta-evaluation methods, which are crucial as LLM usage grows. The study not only validates the reliability of SCALEEVAL but also illuminates the capabilities and limitations of LLMs in diverse scenarios. This work contributes to advancing scalable solutions for evaluating LLMs, which is vital for their expanding applications.


Check out the Paper and Github. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and Google News. Join our 36k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our Telegram Channel

YOU MAY ALSO LIKE

Cat Wu Steps Down as Claude Code Product Chief After Two Years – Unite.AI

iPad Mini OLED Vs. iPad Mini: What’s New?

Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Cat Wu Steps Down as Claude Code Product Chief After Two Years – Unite.AI
AI & Technology

Cat Wu Steps Down as Claude Code Product Chief After Two Years – Unite.AI

November 4, 2026
iPad Mini OLED Vs. iPad Mini: What’s New?
AI & Technology

iPad Mini OLED Vs. iPad Mini: What’s New?

November 4, 2026
Your Phone’s Apps Could Have More Permissions Than They Need – Here’s How To Check
AI & Technology

Your Phone’s Apps Could Have More Permissions Than They Need – Here’s How To Check

November 4, 2026
Docusign Buys Suplari to Add AI Procurement Intelligence – Unite.AI
AI & Technology

Docusign Buys Suplari to Add AI Procurement Intelligence – Unite.AI

November 4, 2026
Next Post
Houston police say teenager reported missing for eight years was home the whole time

Houston police say teenager reported missing for eight years was home the whole time

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
U.S. military to conduct first firing squad execution since World War II

U.S. military to conduct first firing squad execution since World War II

October 31, 2026
Pope Leo XIV Calls to “Disarm” AI, Urges Ban on Lethal Autonomous Weapons – Unite.AI

Pope Leo XIV Calls to “Disarm” AI, Urges Ban on Lethal Autonomous Weapons – Unite.AI

October 30, 2026
6 Google Maps Features That Work Better On Android Auto Vs. CarPlay

6 Google Maps Features That Work Better On Android Auto Vs. CarPlay

November 2, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!