• bitcoinBitcoin(BTC)$77,616.000.53%
  • ethereumEthereum(ETH)$2,514.88-0.24%
  • tetherTether(USDT)$1.00-0.02%
  • binancecoinBNB(BNB)$723.09-0.47%
  • rippleXRP(XRP)$1.380.92%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$101.09-0.55%
  • tronTRON(TRX)$0.338537-0.25%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.000.00%
  • zcashZcash(ZEC)$1,124.68-1.02%
  • HyperliquidHyperliquid(HYPE)$79.981.00%
  • dogecoinDogecoin(DOGE)$0.084079-0.73%
  • RainRain(RAIN)$0.015186-3.74%
  • moneroMonero(XMR)$526.70-1.93%
  • USDSUSDS(USDS)$1.00-0.01%
  • whitebitWhiteBIT Coin(WBT)$80.480.29%
  • chainlinkChainlink(LINK)$11.40-0.80%
  • leo-tokenLEO Token(LEO)$9.03-0.36%
  • cardanoCardano(ADA)$0.2071300.18%
  • stellarStellar(XLM)$0.1821941.32%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • daiDai(DAI)$1.000.00%
  • bitcoin-cashBitcoin Cash(BCH)$223.89-0.66%
  • USD1USD1(USD1)$1.000.00%
  • litecoinLitecoin(LTC)$54.171.02%
  • uniswapUniswap(UNI)$6.410.58%
  • CantonCanton(CC)$0.096263-1.66%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.35-1.18%
  • hedera-hashgraphHedera(HBAR)$0.0763161.63%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • avalanche-2Avalanche(AVAX)$7.410.15%
  • nearNEAR Protocol(NEAR)$2.401.89%
  • shiba-inuShiba Inu(SHIB)$0.000005-0.57%
  • suiSui(SUI)$0.72-0.50%
  • crypto-com-chainCronos(CRO)$0.058285-2.56%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,329.57-0.48%
  • MemeCoreMemeCore(M)$1.16-2.34%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • okbOKB(OKB)$114.20-0.04%
  • BittensorBittensor(TAO)$236.230.51%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.00%
  • aaveAave(AAVE)$126.64-0.63%
  • BitwayBitway(BTW)$0.7231.05%
  • AsterAster(ASTER)$0.700.19%
  • pax-goldPAX Gold(PAXG)$4,333.36-0.50%
  • mantleMantle(MNT)$0.560.82%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0574380.47%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Can Large Language Models be Trusted for Evaluation? Meet SCALEEVAL: An Agent-Debate-Assisted Meta-Evaluation Framework that Leverages the Capabilities of Multiple Communicative LLM Agents

February 12, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Can Large Language Models be Trusted for Evaluation? Meet SCALEEVAL: An Agent-Debate-Assisted Meta-Evaluation Framework that Leverages the Capabilities of Multiple Communicative LLM Agents
ShareShareShareShareShare

Despite the utility of large language models (LLMs) across various tasks and scenarios, researchers need help to evaluate LLMs properly in different situations. They use LLMs to check their responses, but a solution must be found. This method is limited because there aren’t enough benchmarks, and it often requires a lot of human input. They urgently need better ways to test how well LLMs can evaluate things in all situations, especially when users define new scenarios.

LLMs have advanced significantly, demonstrating impressive performance across various tasks. However, evaluating their outputs presents complex challenges. Current approaches primarily rely on automated metrics, often employing LLMs for evaluation. While some functions undergo rigorous meta-evaluation, requiring costly human-annotated datasets, many applications need more scrutiny, leading to potential unreliability in LLMs as evaluators.

Researchers from Shanghai Jiao Tong University, Carnegie Mellon University, Shanghai Artificial Intelligence Laboratory, and Generative AI Research Lab (GAIR) introduce SCALEEVAL, a meta-evaluation framework utilizing multiple communicative LLM agents with an agent-debate approach. This system facilitates multi-round discussions, aiding human annotators in identifying the most proficient LLMs for evaluation. This approach substantially reduces the burden on annotators, especially in scenarios where extensive annotations were traditionally necessary for meta-evaluation.

SCALEEVAL leverages multi-agent debate for reliable meta-evaluation of LLMs. In the meta-evaluation process, LLM agents engage in rounds of discussions to assess responses based on user-defined criteria. This reduces the reliance on extensive human annotation and ensures scalability. The evaluation framework involves pairwise response comparisons, focusing on LLMs like gpt-3.5-turbo. Human expert meta-meta evaluation validates the proposed method’s reliability by applying the agent-debate-assisted and human expert annotation protocols. This approach balances efficiency with human judgment for accurate and timely assessments.
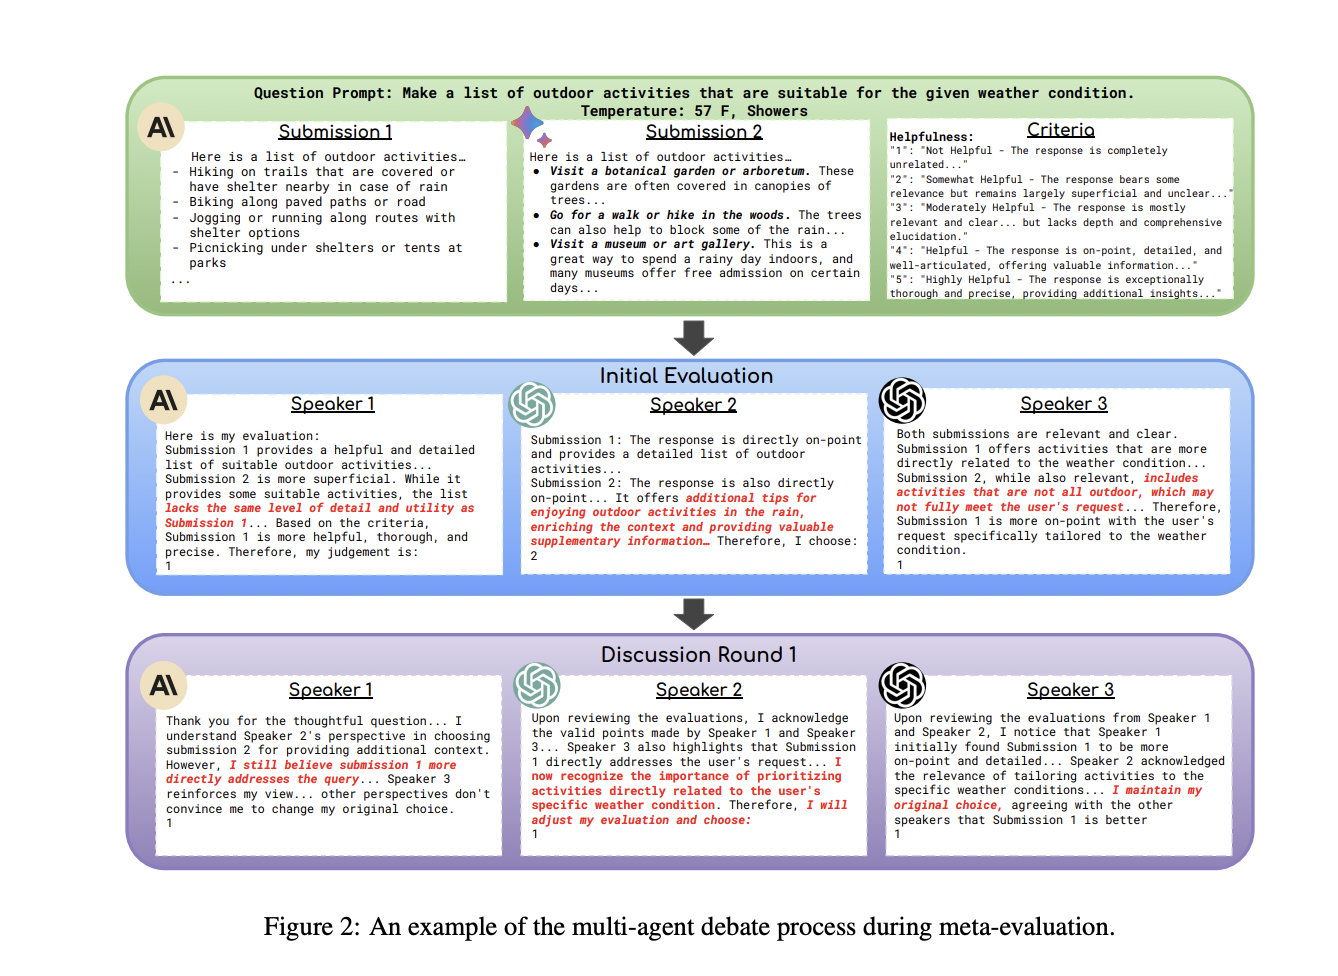
Studies reveal that LLMs’ performance as evaluators tends to decline when specific letters in criteria prompts are masked. The removal of guiding phrases further diminishes effectiveness. Gpt-4-turbo and gpt-3.5-turbo exhibit resilience, maintaining consistent agreement rates across criteria formats. In contrast, Claude-2 displays confusion and reluctance, especially with adversarial prompts, rejecting approximately half of the questions. The tested LLMs struggle with substituted criteria information, indicating room for improvement in their design and application despite their advanced capabilities.

In conclusion, The researchers have introduced SCALEEVAL, a scalable meta-evaluation framework utilizing agent-debate assistance to assess LLMs as evaluators. This proposal addresses the inefficiencies of conventional, resource-intensive meta-evaluation methods, which are crucial as LLM usage grows. The study not only validates the reliability of SCALEEVAL but also illuminates the capabilities and limitations of LLMs in diverse scenarios. This work contributes to advancing scalable solutions for evaluating LLMs, which is vital for their expanding applications.


Check out the Paper and Github. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and Google News. Join our 36k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our Telegram Channel

YOU MAY ALSO LIKE

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?

Which Is Better For Charging Your MacBook?

Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?
AI & Technology

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?

September 14, 2026
Which Is Better For Charging Your MacBook?
AI & Technology

Which Is Better For Charging Your MacBook?

September 14, 2026
At What Length Do Ethernet Cables Drop To Lower Speeds?
AI & Technology

At What Length Do Ethernet Cables Drop To Lower Speeds?

September 14, 2026
Nadella Announces Public Consultation on Microsoft’s MAI Model Rules – Unite.AI
AI & Technology

Nadella Announces Public Consultation on Microsoft’s MAI Model Rules – Unite.AI

September 13, 2026
Next Post
Houston police say teenager reported missing for eight years was home the whole time

Houston police say teenager reported missing for eight years was home the whole time

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
74-year old aviation mystery finally solved

74-year old aviation mystery finally solved

September 7, 2026
GDMN: Gold And Gold Miners Finally Set Up Well Into Q4 (Rating Upgrade)

GDMN: Gold And Gold Miners Finally Set Up Well Into Q4 (Rating Upgrade)

September 13, 2026
Reggie Scales, President and Head of Business Unit Applications at Vonage – Interview Series – Unite.AI

Reggie Scales, President and Head of Business Unit Applications at Vonage – Interview Series – Unite.AI

September 11, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!