
Why Document OCR Still Remains a Hard Engineering Problem? What does it take to make OCR useful for real documents instead of clean demo images? And can a compact multimodal model handle parsing, tables, formulas, and structured extraction without turning inference into a resource bonfire?
That is the problem targeted by GLM-OCR, introduced by researchers from Zhipu AI and Tsinghua University. The research team presents GLM-OCR as a 0.9B-parameter compact multimodal model for document understanding. It combines a 0.4B CogViT visual encoder, a lightweight cross-modal connector, and a 0.5B GLM language decoder. The stated goal is to balance document recognition quality with lower latency and lower computational cost than larger multimodal systems.
Traditional OCR systems are often good at plain text transcription, but they struggle when documents contain mixed layouts, tables, formulas, code blocks, seals, and structured fields. Recent multimodal large language models improve document understanding, but the research team argue that their size and standard autoregressive decoding make them expensive for edge deployment and large-scale production. GLM-OCR is positioned as a smaller system built for these deployment constraints rather than as a general-purpose vision-language model adapted to OCR as an afterthought.
A Compact Architecture Built for OCR Workloads
A key technical point for this research is the use of Multi-Token Prediction (MTP). Standard autoregressive decoding predicts one token at a time, which is not ideal for OCR-style tasks where outputs are often deterministic and locally structured. GLM-OCR instead predicts multiple tokens per step. The model is trained to predict 10 tokens per step and generates 5.2 tokens per decoding step on average at inference time, yielding about 50% throughput improvement. To keep memory overhead manageable, the implementation uses a parameter-sharing scheme across the draft models.
Two-Stage Layout Parsing Instead of Flat Page Reading
At the system level, GLM-OCR adopts a two-stage pipeline. The first stage uses PP-DocLayout-V3 for layout analysis, which detects structured regions on the page. The second stage performs parallel region-level recognition over those detected areas. This is important because the model is not simply reading a whole page left-to-right as a generic vision-language model might. It first breaks down the page into semantically meaningful regions, which improves efficiency and makes the system more robust on documents with complicated layouts.
Document Parsing and KIE Use Different Output Paths
The architecture also separates two related document tasks. For document parsing, the pipeline uses layout detection and region processing to produce structured outputs such as Markdown and JSON. For Key Information Extraction (KIE), the research team describes a different path: the full document image is fed to the model with a task prompt, and the model directly generates JSON containing the extracted fields. That distinction matters because GLM-OCR is not presented as a single monolithic page-to-text model. It is a structured generation system with different operating modes depending on the task.
A Four-Stage Training Pipeline with Task-Specific Rewards
The training recipe is split into 4 stages. Stage 1 trains the vision encoder on image-text pairs and grounding or retrieval data. Stage 2.1 performs multimodal pretraining on image-text, document parsing, grounding, and VQA data. Stage 2.2 adds the MTP objective. Stage 3 is supervised fine-tuning on OCR-specific tasks including text recognition, formula transcription, table structure recovery, and KIE. Stage 4 applies reinforcement learning using GRPO. The reward design is task-specific: Normalized Edit Distance for text recognition, CDM score for formula recognition, TEDS score for table recognition, and field-level F1 for KIE, along with structural penalties such as repetition penalties, malformed structure penalties, and JSON validation constraints.
Benchmark Results Show Strong Performance, With Important Caveats
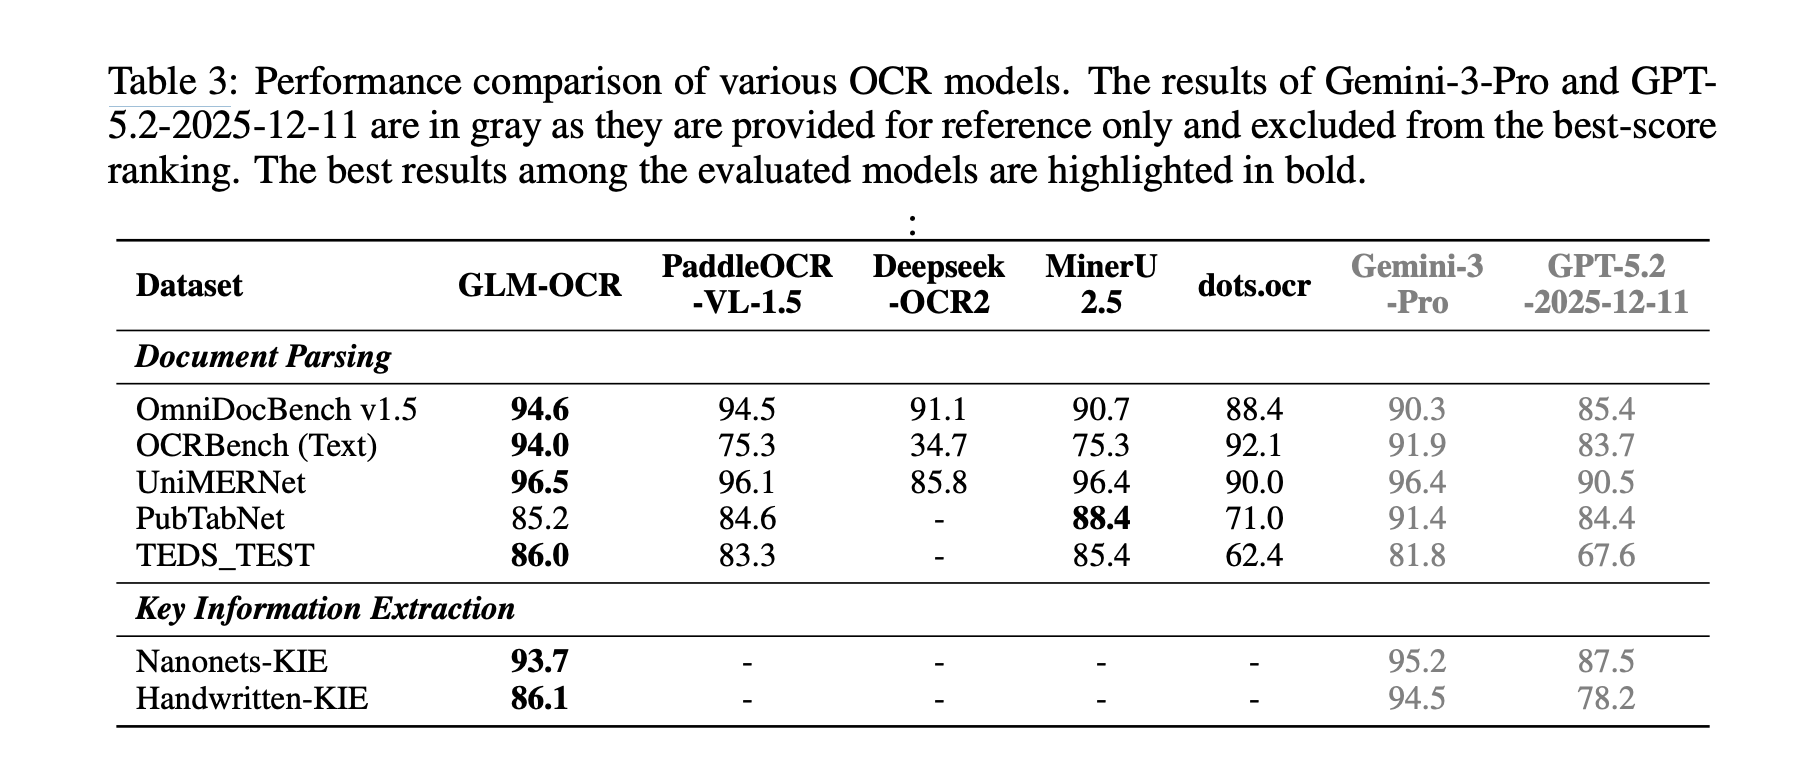
On public benchmarks, GLM-OCR reports strong results across several document tasks. It scores 94.6 on OmniDocBench v1.5, 94.0 on OCRBench (Text), 96.5 on UniMERNet, 85.2 on PubTabNet, and 86.0 on TEDS_TEST. For KIE, it reports 93.7 on Nanonets-KIE and 86.1 on Handwritten-KIE. The research team notes that results for Gemini-3-Pro and GPT-5.2-2025-12-11 are shown only for reference and are excluded from the best-score ranking, which is an important detail when interpreting claims about model leadership.
The benchmark story is strong, but it needs careful phrasing. GLM-OCR achieves the highest reported scores among the evaluated non-reference models on OmniDocBench v1.5, OCRBench (Text), UniMERNet, and TEDS_TEST. On PubTabNet, however, it does not lead overall; MinerU 2.5 reports 88.4 versus GLM-OCR’s 85.2. For KIE, GLM-OCR outperforms the listed open-source competitors in the above table, but Gemini-3-Pro scores higher on both Nanonets-KIE and Handwritten-KIE in the reference column. So the reserach team supports a strong competitive claim, but not a blanket ‘best at everything’ claim.
Deployment Details
The research team state that GLM-OCR supports vLLM, SGLang, and Ollama, and can be fine-tuned through LLaMA-Factory. They also report throughput of 0.67 images/s and 1.86 PDF pages/s under their evaluation setup. In addition, they describe a MaaS API priced at 0.2 RMB per million tokens, with example cost estimates for scanned images and simple-layout PDFs. These details suggest that GLM-OCR is being framed as both a research model and a deployable system.
Key Takeaways
- GLM-OCR is a compact 0.9B multimodal OCR model built with a 0.4B CogViT encoder and 0.5B GLM decoder.
- It uses Multi-Token Prediction (MTP) to improve decoding efficiency, reaching 5.2 tokens per step on average and about 50% higher throughput.
- The model uses a two-stage pipeline: PP-DocLayout-V3 handles layout analysis, then GLM-OCR performs parallel region-level recognition.
- It supports both document parsing and KIE: parsing outputs Markdown/JSON, while KIE directly generates JSON from the full document image.
- Benchmark results are strong but not universal wins: GLM-OCR leads several reported non-reference benchmarks, but MinerU 2.5 is higher on PubTabNet, and Gemini-3-Pro is higher on the reference-only KIE scores.
Check out Paper, Repo and Model Page. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
The post Zhipu AI Introduces GLM-OCR: A 0.9B Multimodal OCR Model for Document Parsing and Key Information Extraction (KIE) appeared first on MarkTechPost.
Credit: Source link