• bitcoinBitcoin(BTC)$81,320.004.18%
  • ethereumEthereum(ETH)$2,639.835.43%
  • tetherTether(USDT)$1.000.05%
  • binancecoinBNB(BNB)$765.922.10%
  • rippleXRP(XRP)$1.438.00%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$111.875.99%
  • tronTRON(TRX)$0.3377560.17%
  • zcashZcash(ZEC)$1,539.605.19%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.00%
  • HyperliquidHyperliquid(HYPE)$92.032.41%
  • dogecoinDogecoin(DOGE)$0.0881763.58%
  • moneroMonero(XMR)$587.509.21%
  • whitebitWhiteBIT Coin(WBT)$83.173.43%
  • RainRain(RAIN)$0.0139338.45%
  • USDSUSDS(USDS)$1.000.01%
  • chainlinkChainlink(LINK)$12.516.40%
  • cardanoCardano(ADA)$0.2259615.92%
  • leo-tokenLEO Token(LEO)$8.89-0.29%
  • stellarStellar(XLM)$0.1938894.79%
  • uniswapUniswap(UNI)$9.113.85%
  • bitcoin-cashBitcoin Cash(BCH)$250.831.66%
  • Ethena USDeEthena USDe(USDE)$1.000.04%
  • nearNEAR Protocol(NEAR)$3.655.30%
  • daiDai(DAI)$1.00-0.02%
  • litecoinLitecoin(LTC)$57.274.06%
  • CantonCanton(CC)$0.1104213.39%
  • USD1USD1(USD1)$1.000.06%
  • avalanche-2Avalanche(AVAX)$9.2816.76%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.370.52%
  • suiSui(SUI)$0.869.92%
  • hedera-hashgraphHedera(HBAR)$0.0804644.83%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • shiba-inuShiba Inu(SHIB)$0.0000051.76%
  • BittensorBittensor(TAO)$271.1711.07%
  • crypto-com-chainCronos(CRO)$0.0597481.21%
  • MemeCoreMemeCore(M)$1.301.46%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • tether-goldTether Gold(XAUT)$4,373.44-0.11%
  • okbOKB(OKB)$121.886.92%
  • Circle USYCCircle USYC(USYC)$1.140.03%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.30%
  • aaveAave(AAVE)$143.306.93%
  • AsterAster(ASTER)$0.772.08%
  • OndoOndo(ONDO)$0.4146687.67%
  • mantleMantle(MNT)$0.613.01%
  • Pump.funPump.fun(PUMP)$0.004150-1.11%
  • EthenaEthena(ENA)$0.19046517.21%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

What is Dataset Distillation Learning? A Comprehensive Overview

June 9, 2024
in AI & Technology
Reading Time: 4 mins read
A A
What is Dataset Distillation Learning? A Comprehensive Overview
ShareShareShareShareShare

Dataset distillation is an innovative approach that addresses the challenges posed by the ever-growing size of datasets in machine learning. This technique focuses on creating a compact, synthetic dataset that encapsulates the essential information of a larger dataset, enabling efficient and effective model training. Despite its promise, the intricacies of how distilled data retains its utility and information content have yet to be fully understood. Let’s delve into the fundamental aspects of dataset distillation, exploring its mechanisms, advantages, and limitations.

Dataset distillation aims to overcome the limitations of large datasets by generating a smaller, information-dense dataset. Traditional data compression methods often fail due to the limited number of representative data points they can select. In contrast, dataset distillation synthesizes a new set of data points that can effectively replace the original dataset for training purposes. This process compares real and distilled images from the CIFAR-10 dataset, showing how distilled images, though different in appearance, can train high-accuracy classifiers.

Key Questions and Findings

The study presented addresses three critical questions about the nature of distilled data:

  1. Substitution for Real Data: The effectiveness of distilled data as a replacement for real data varies. Distilled data retains high task performance by compressing information related to the early training dynamics of models trained on real data. However, mixing distilled data with real data during training can decrease the performance of the final classifier, indicating that distilled data should not be treated as a direct substitute for real data outside the typical evaluation setting of dataset distillation.
  2. Information Content: Distilled data captures information analogous to what is learned from real data early in the training process. This is evidenced by strong parallels in predictions between models trained on distilled data and those trained on real data with early stopping. The loss curvature analysis further shows that the information in distilled data rapidly decreases loss curvature during training, highlighting that distilled data effectively compresses the early training dynamics.
  3. Semantic Information: Individual distilled data points contain meaningful semantic information. This was demonstrated using influence functions, which quantify the impact of individual data points on a model’s predictions. The study showed that distilled images can influence real images semantically consistently, indicating that distilled data points encapsulate specific, recognizable semantic attributes.

The study utilized the CIFAR-10 dataset for analysis, employing various dataset distillation methods, including meta-model matching, distribution matching, gradient matching, and trajectory matching. The experiments demonstrated that models trained on distilled data could recognize classes in real data, suggesting that distilled data encodes transferable semantics. However, adding real data to distilled data during training often could have improved and sometimes even decreased model accuracy, underscoring the unique nature of distilled data.

The study concludes that while distilled data behaves like real data at inference time, it is highly sensitive to the training procedure and should not be used as a drop-in replacement for real data. Dataset distillation effectively captures the early learning dynamics of real models and contains meaningful semantic information at the individual data point level. These insights are crucial for the future design and application of dataset distillation methods.

Dataset distillation holds promise for creating more efficient and accessible datasets. Still, it raises questions about potential biases and how distilled data can be generalized across different model architectures and training settings. Further research is needed to address these challenges and fully harness the potential of dataset distillation in machine learning.


Source: https://arxiv.org/pdf/2406.04284


YOU MAY ALSO LIKE

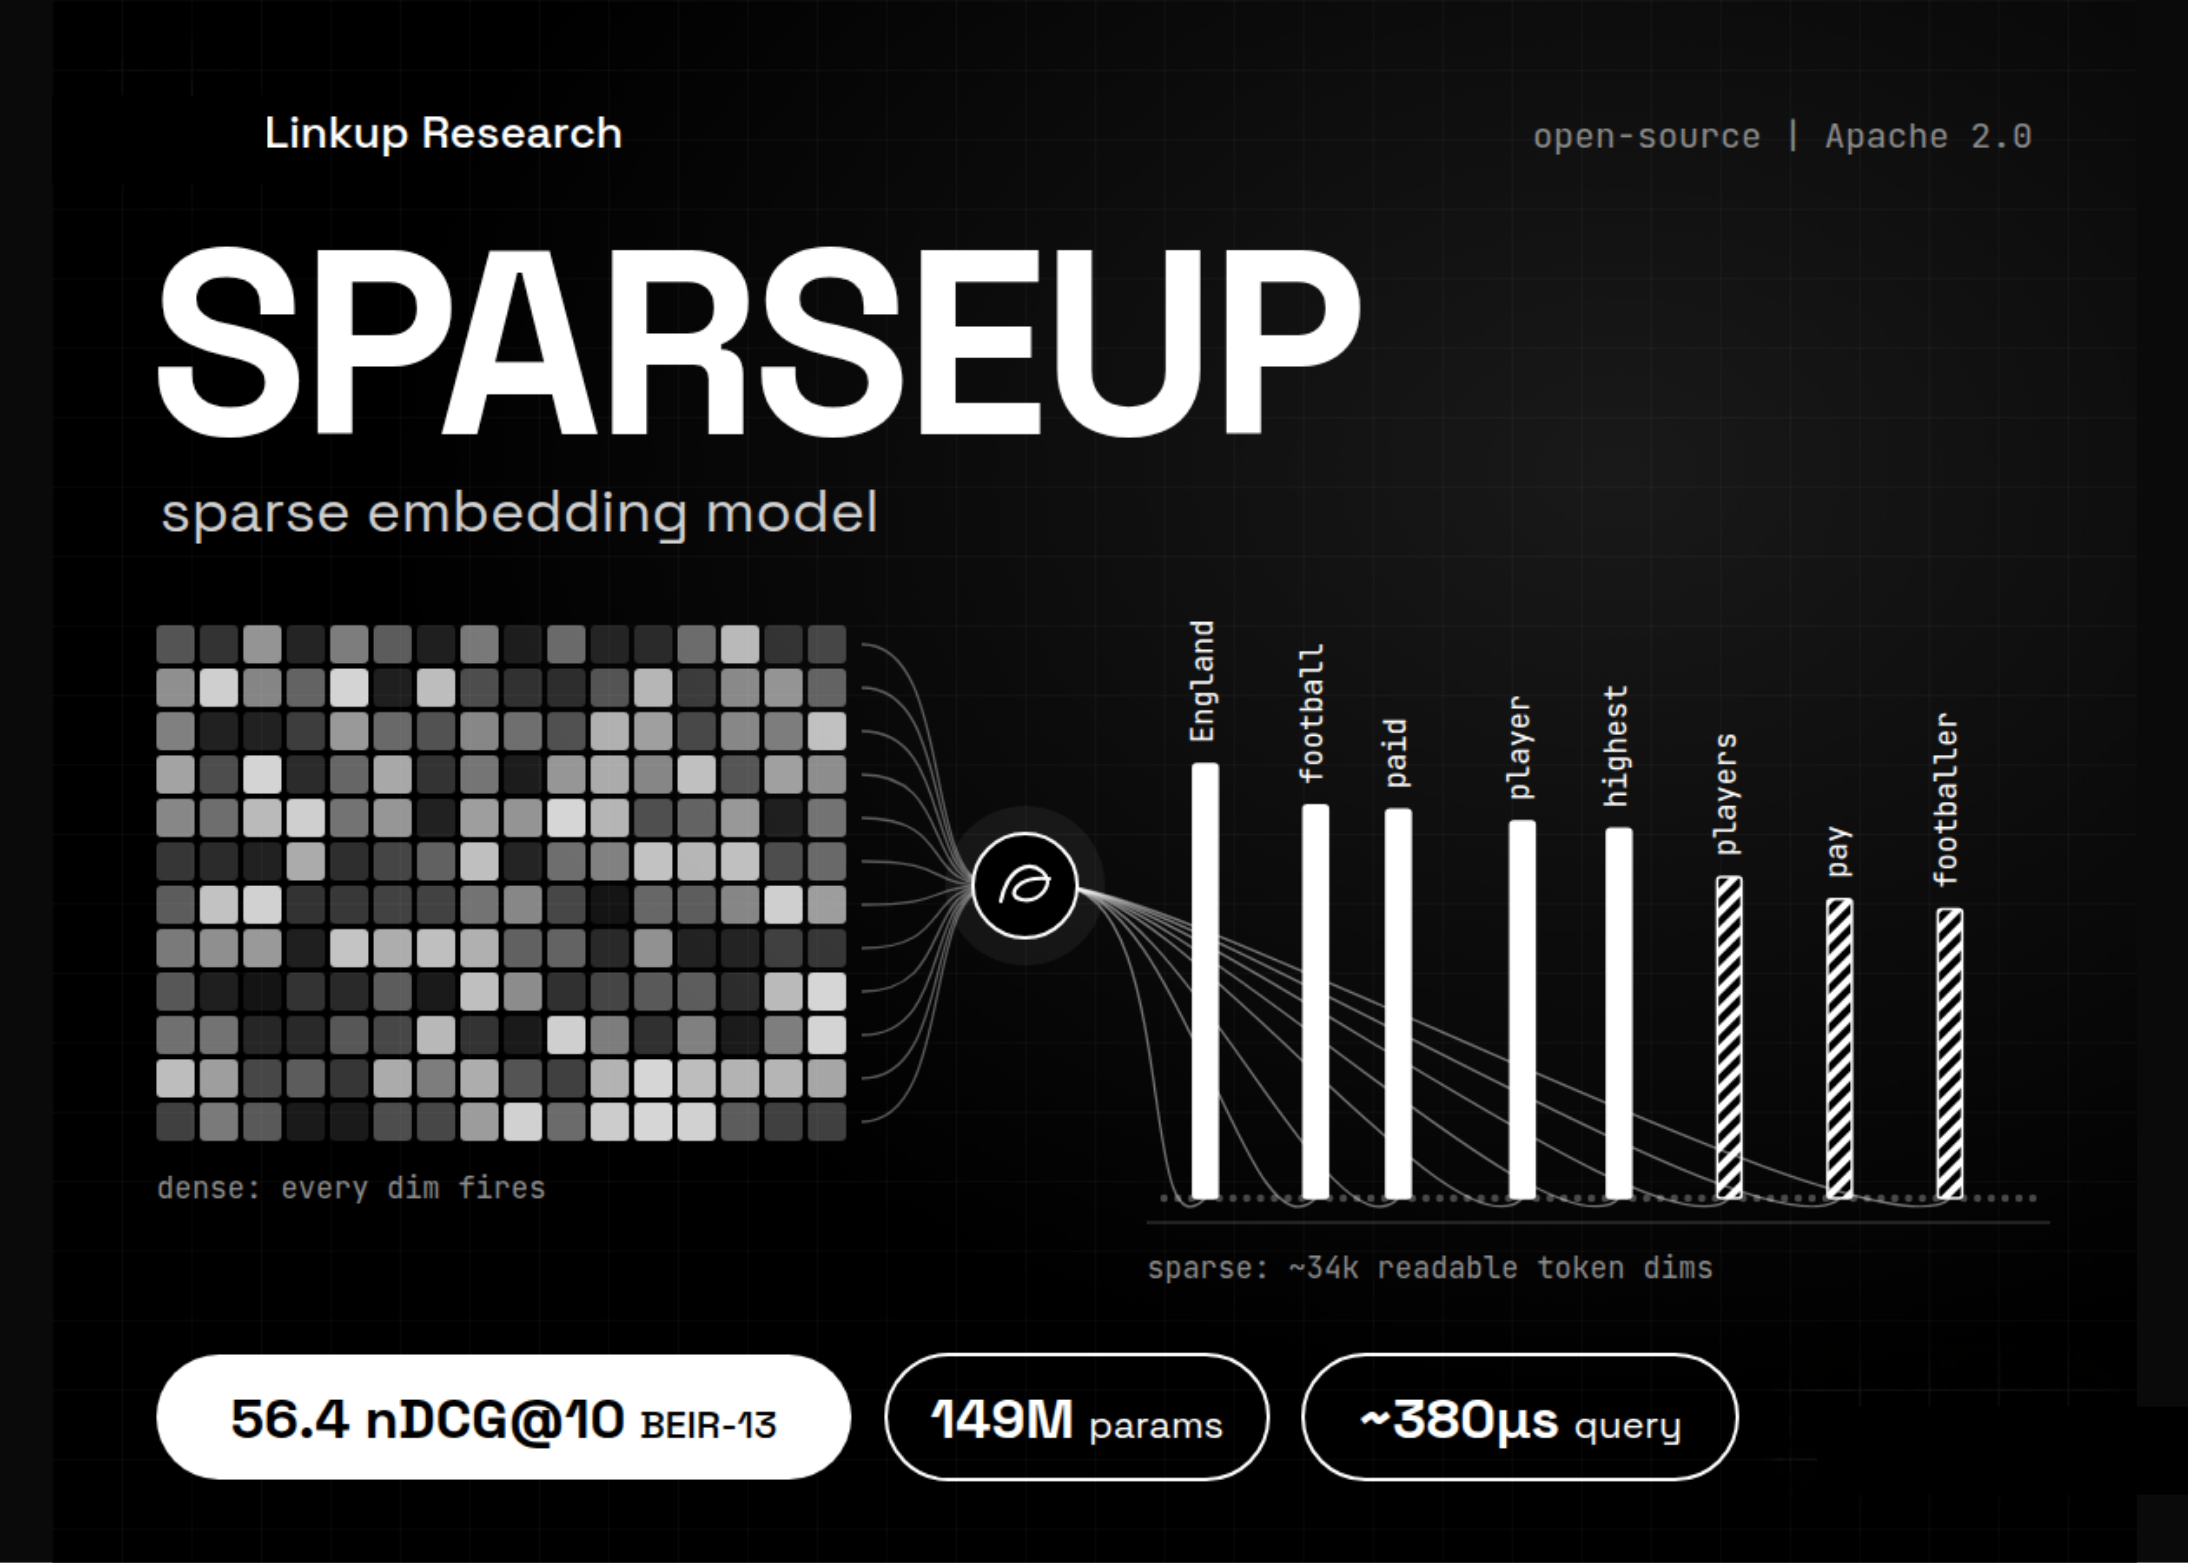
Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

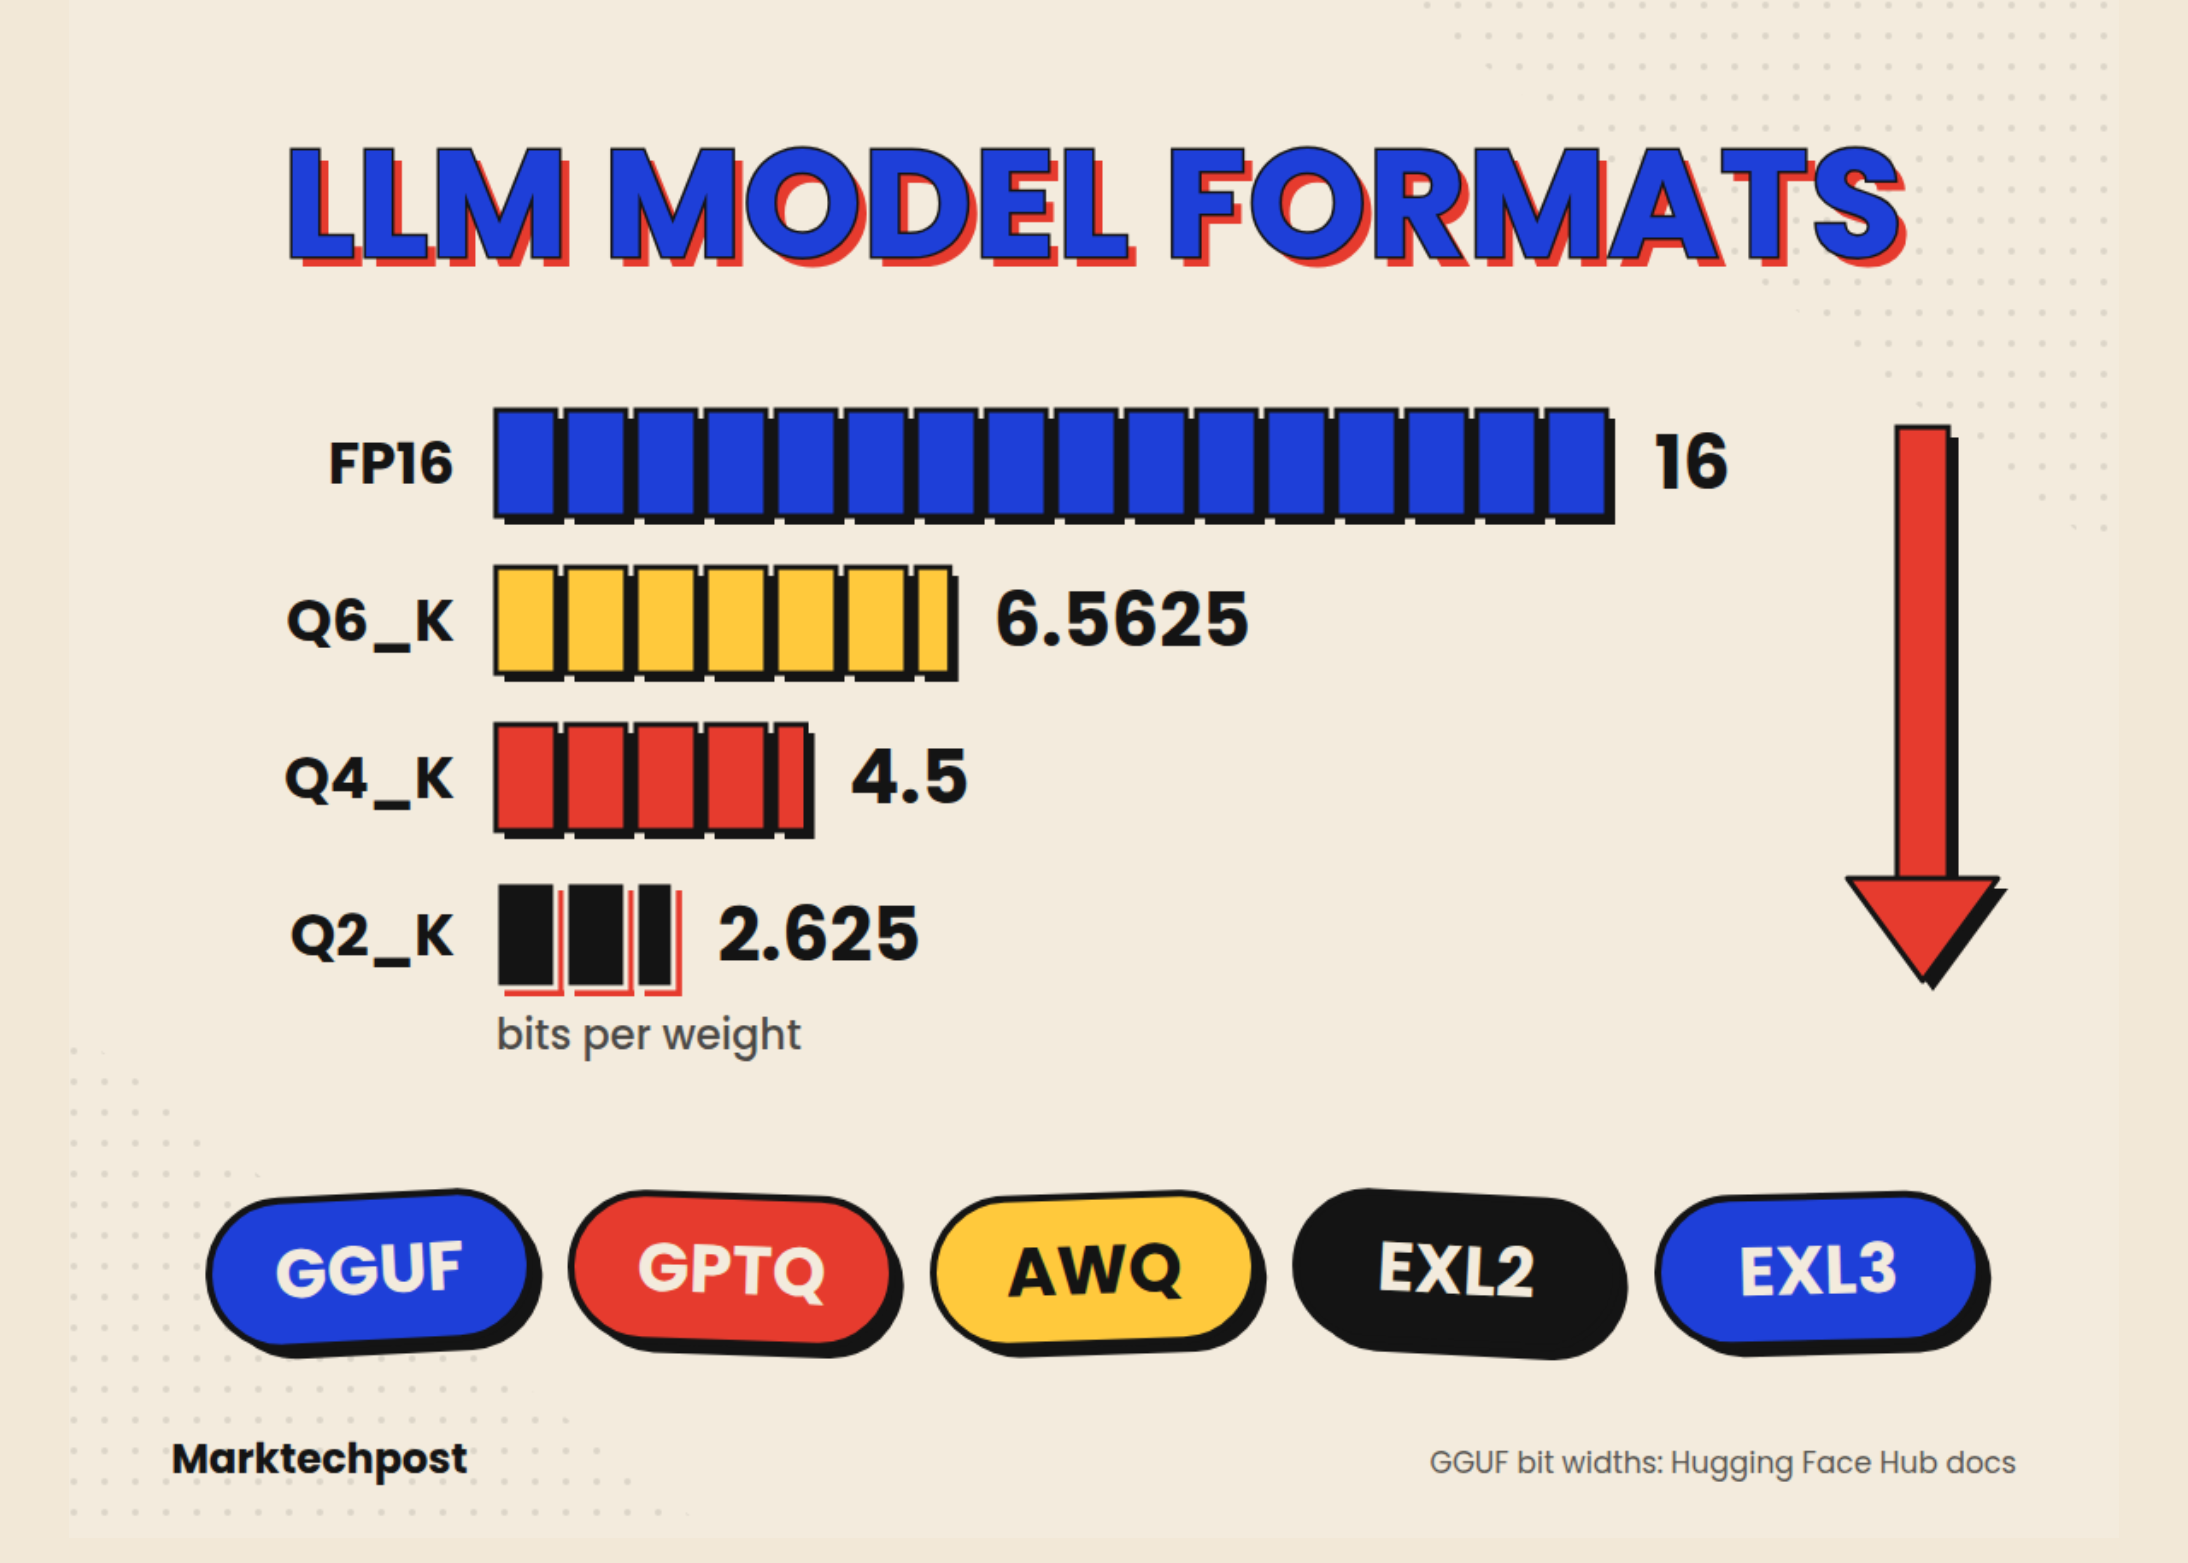
GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

Aswin AK is a consulting intern at MarkTechPost. He is pursuing his Dual Degree at the Indian Institute of Technology, Kharagpur. He is passionate about data science and machine learning, bringing a strong academic background and hands-on experience in solving real-life cross-domain challenges.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…

Credit: Source link

ShareTweetSendSharePin

Related Posts

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model
AI & Technology

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

September 19, 2026
GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)
AI & Technology

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

September 19, 2026
Consumers Sue Anthropic, OpenAI, SpaceXAI and Google Over Alleged AI Pact – Unite.AI
AI & Technology

Consumers Sue Anthropic, OpenAI, SpaceXAI and Google Over Alleged AI Pact – Unite.AI

September 19, 2026
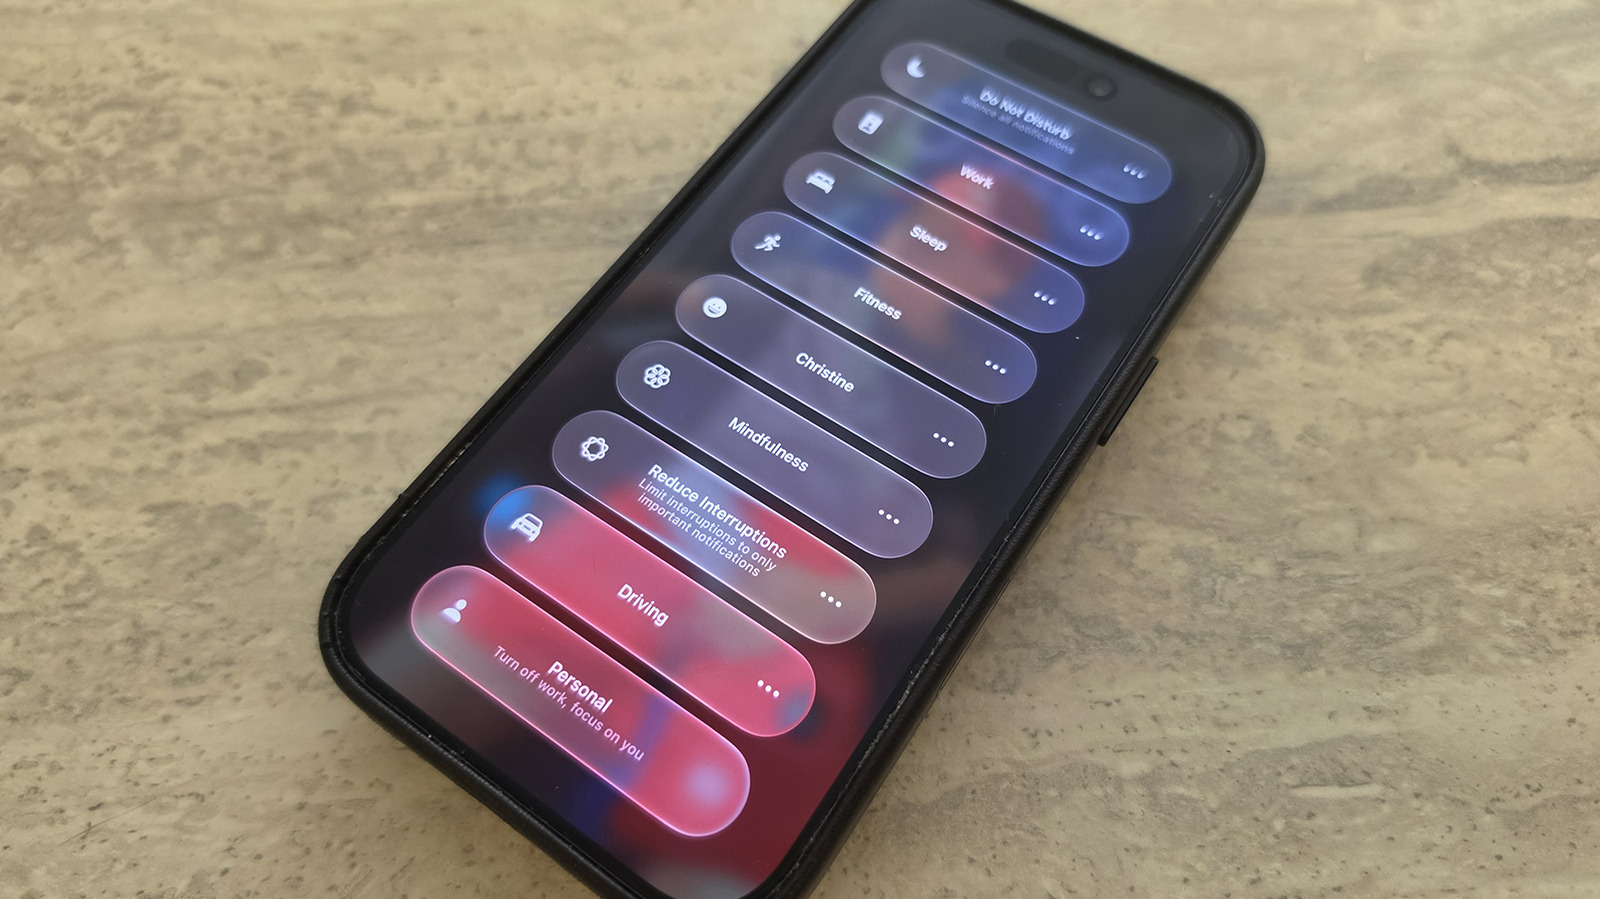
How Focus Mode Has Changed In iOS 27
AI & Technology

How Focus Mode Has Changed In iOS 27

September 18, 2026
Next Post
Michael Mosley: Body found in search for missing TV presenter

Michael Mosley: Body found in search for missing TV presenter

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Comedian debuts surprise documentary on Theranos founder

Comedian debuts surprise documentary on Theranos founder

September 16, 2026
DoorDash and Uber Eats to offer Costco delivery across the US

DoorDash and Uber Eats to offer Costco delivery across the US

September 17, 2026
Iconic firefighters photo from 9/11: Where are they now?

Iconic firefighters photo from 9/11: Where are they now?

September 12, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!