
• bitcoinBitcoin(BTC)$84,854.000.81%
  • ethereumEthereum(ETH)$2,707.750.68%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$779.170.45%
  • rippleXRP(XRP)$1.54-0.91%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$123.812.09%
  • tronTRON(TRX)$0.334200-0.82%
  • zcashZcash(ZEC)$1,661.477.77%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.063.69%
  • HyperliquidHyperliquid(HYPE)$93.080.97%
  • dogecoinDogecoin(DOGE)$0.097772-0.05%
  • chainlinkChainlink(LINK)$14.30-0.31%
  • moneroMonero(XMR)$554.180.09%
  • whitebitWhiteBIT Coin(WBT)$84.630.70%
  • USDSUSDS(USDS)$1.00-0.01%
  • cardanoCardano(ADA)$0.256553-0.41%
  • RainRain(RAIN)$0.0126803.43%
  • leo-tokenLEO Token(LEO)$9.061.12%
  • stellarStellar(XLM)$0.217650-1.00%
  • bitcoin-cashBitcoin Cash(BCH)$338.70-0.09%
  • nearNEAR Protocol(NEAR)$5.174.58%
  • uniswapUniswap(UNI)$9.983.55%
  • litecoinLitecoin(LTC)$71.63-2.25%
  • CantonCanton(CC)$0.1367501.62%
  • suiSui(SUI)$1.244.90%
  • Ethena USDeEthena USDe(USDE)$1.000.02%
  • avalanche-2Avalanche(AVAX)$10.970.31%
  • daiDai(DAI)$1.000.00%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.6311.29%
  • USD1USD1(USD1)$1.000.00%
  • hedera-hashgraphHedera(HBAR)$0.0947060.29%
  • BittensorBittensor(TAO)$329.832.52%
  • shiba-inuShiba Inu(SHIB)$0.0000060.16%
  • crypto-com-chainCronos(CRO)$0.0687404.60%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • BitwayBitway(BTW)$1.1524.96%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • EthenaEthena(ENA)$0.274823-2.06%
  • MemeCoreMemeCore(M)$1.21-1.50%
  • tether-goldTether Gold(XAUT)$4,280.13-0.02%
  • OndoOndo(ONDO)$0.55-1.78%
  • okbOKB(OKB)$121.880.04%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • aaveAave(AAVE)$156.231.27%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • quant-networkQuant(QNT)$165.1058.08%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • mantleMantle(MNT)$0.69-2.67%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.16%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

VLM2Vec-V2: A Unified Computer Vision Framework for Multimodal Embedding Learning Across Images, Videos, and Visual Documents

July 27, 2025
in AI & Technology
Reading Time: 4 mins read
A A
VLM2Vec-V2: A Unified Computer Vision Framework for Multimodal Embedding Learning Across Images, Videos, and Visual Documents
ShareShareShareShareShare

Embedding models act as bridges between different data modalities by encoding diverse multimodal information into a shared dense representation space. There have been advancements in embedding models in recent years, driven by progress in large foundation models. However, existing multimodal embedding models are trained on datasets such as MMEB and M-BEIR, with most focus only on natural images and photographs sourced from the MSCOCO, Flickr, and ImageNet datasets. These datasets fail to cover larger forms of visual information, including documents, PDFs, websites, videos, and slides. This causes existing embedding models to underperform on realistic tasks such as article searching, website searching, and YouTube video search.

Multimodal embedding benchmarks such as MSCOCO, Flickr30K, and Conceptual Captions initially focused on static image-text pairs for tasks like image captioning and retrieval. More recent benchmarks, such as M-BEIR and MMEB, introduced multi-task evaluations, but remain limited to static images and short contexts. Video representation learning has evolved through models like VideoCLIP and VideoCoCa, integrating contrastive learning with captioning objectives. Visual document representation learning advanced through models like ColPali and VisRAG, which use VLMs for document retrieval. Unified modality retrieval methods like GME and Uni-Retrieval achieve strong performance on universal benchmarks. However, none can unify image, video, and visual document retrieval within a single framework.

YOU MAY ALSO LIKE

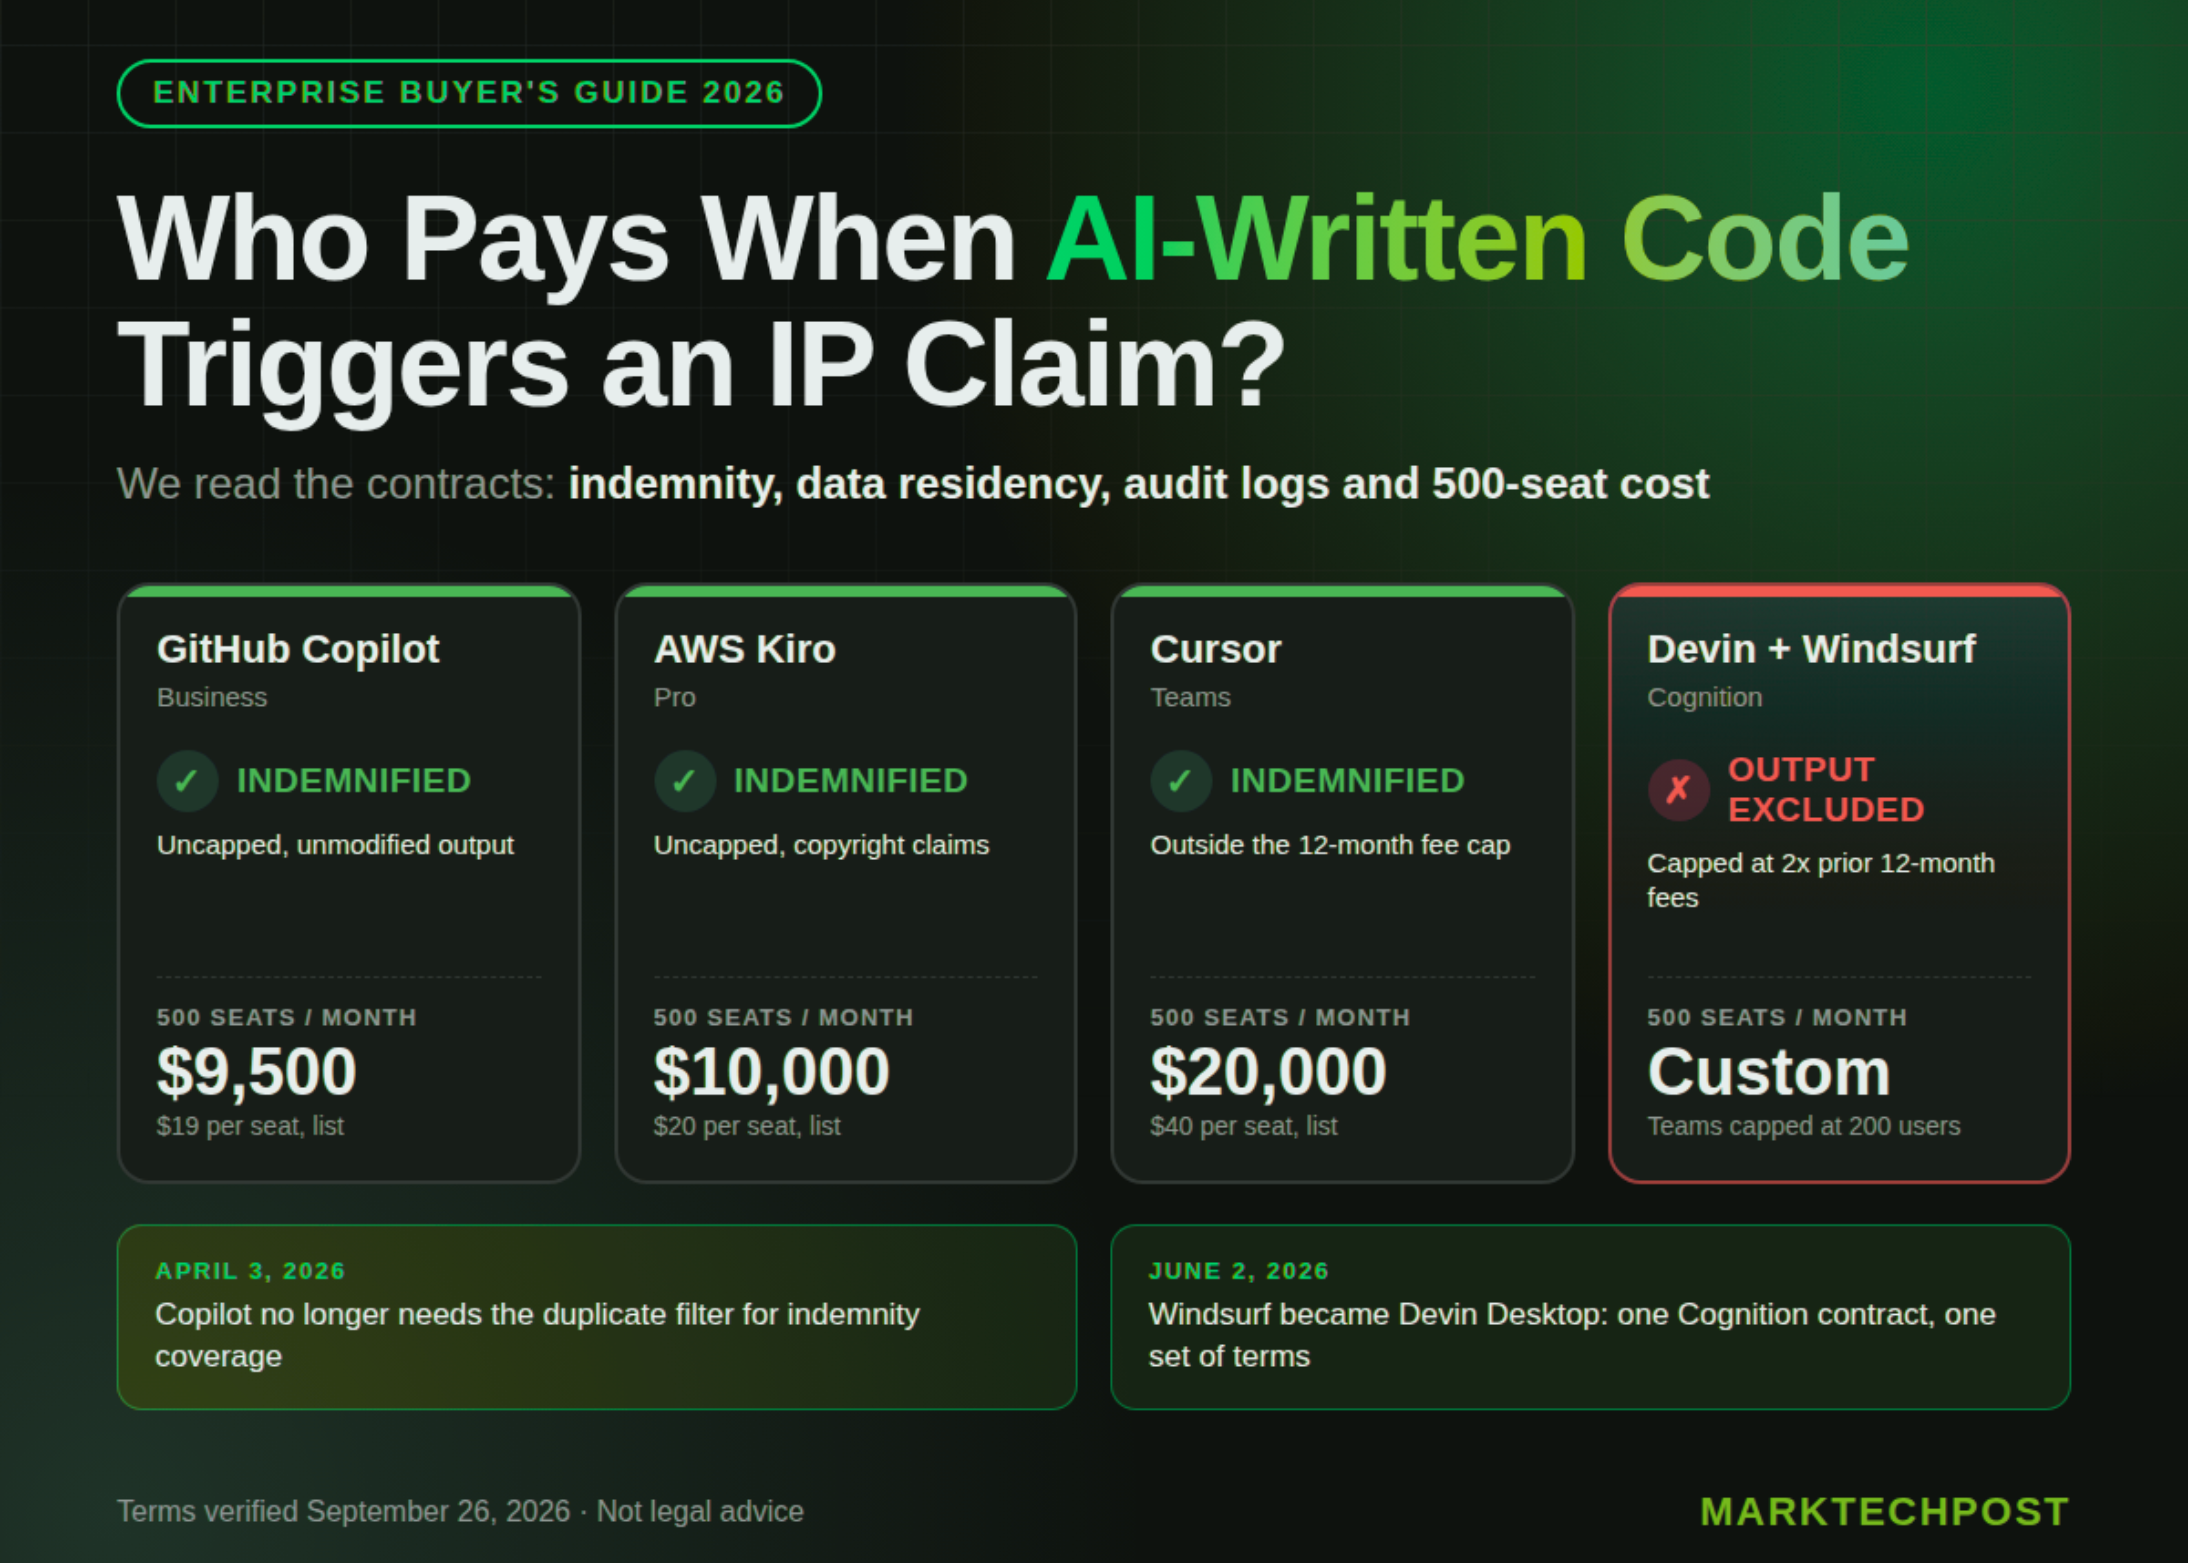
AI Coding Agents for Enterprise: IP Indemnity, Data Residency and 500-Seat Cost Compared

A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation

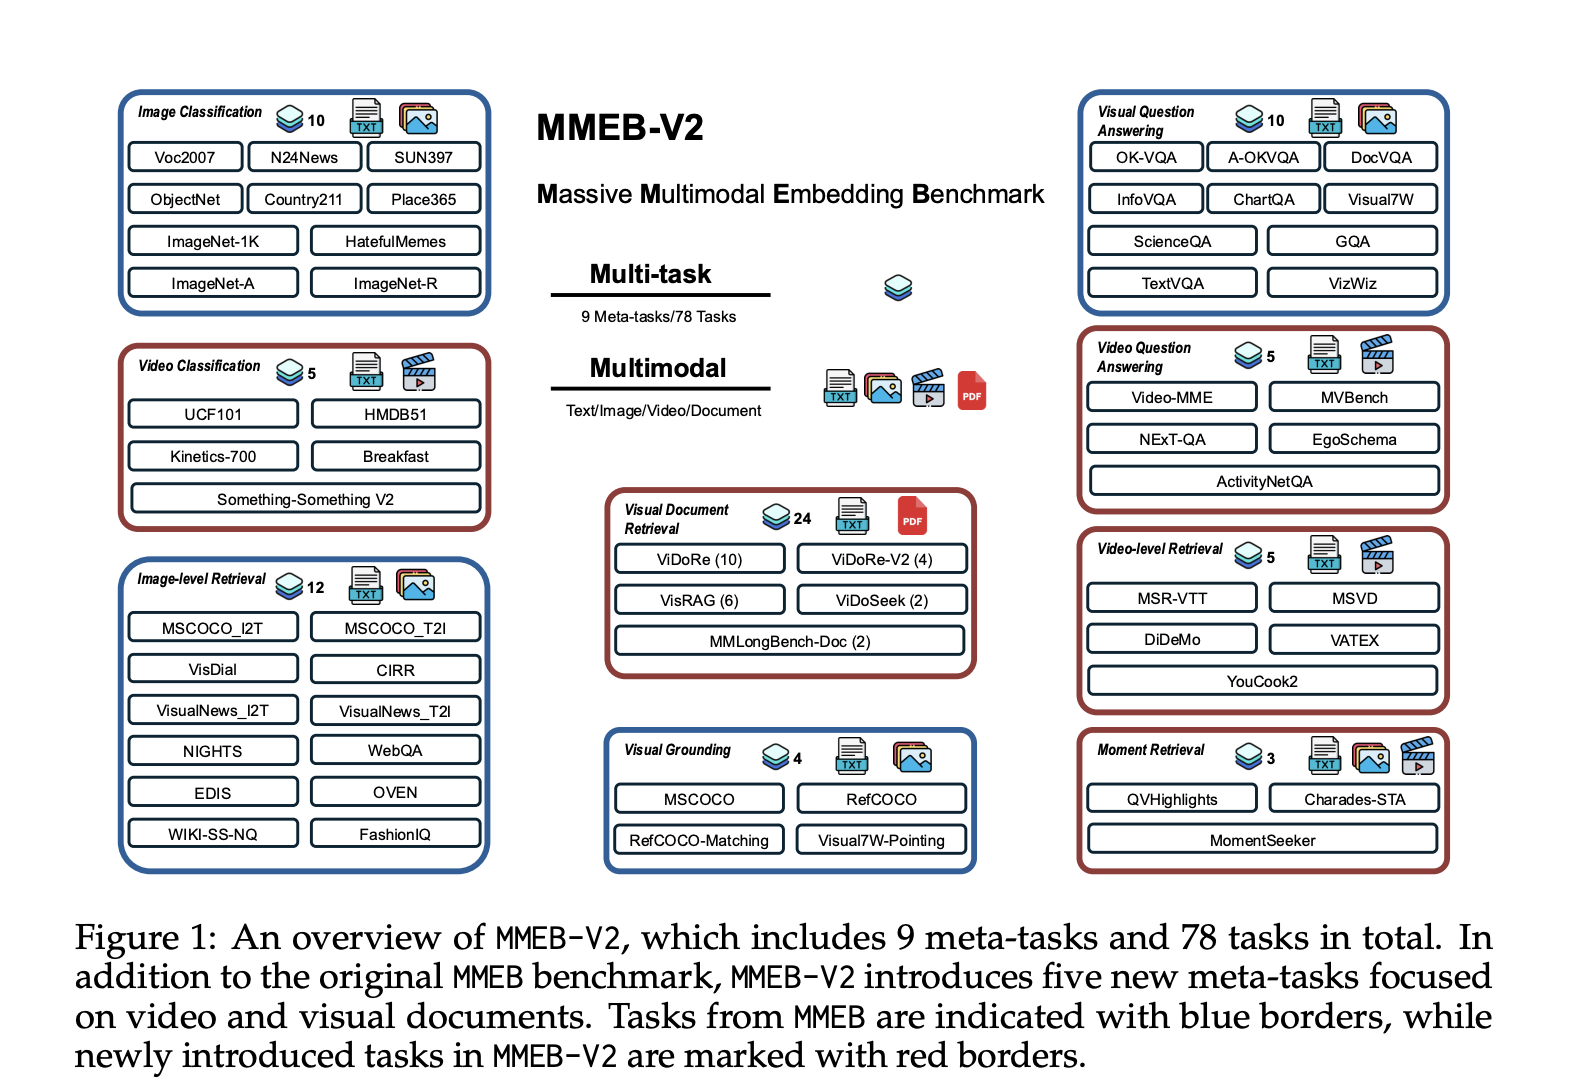
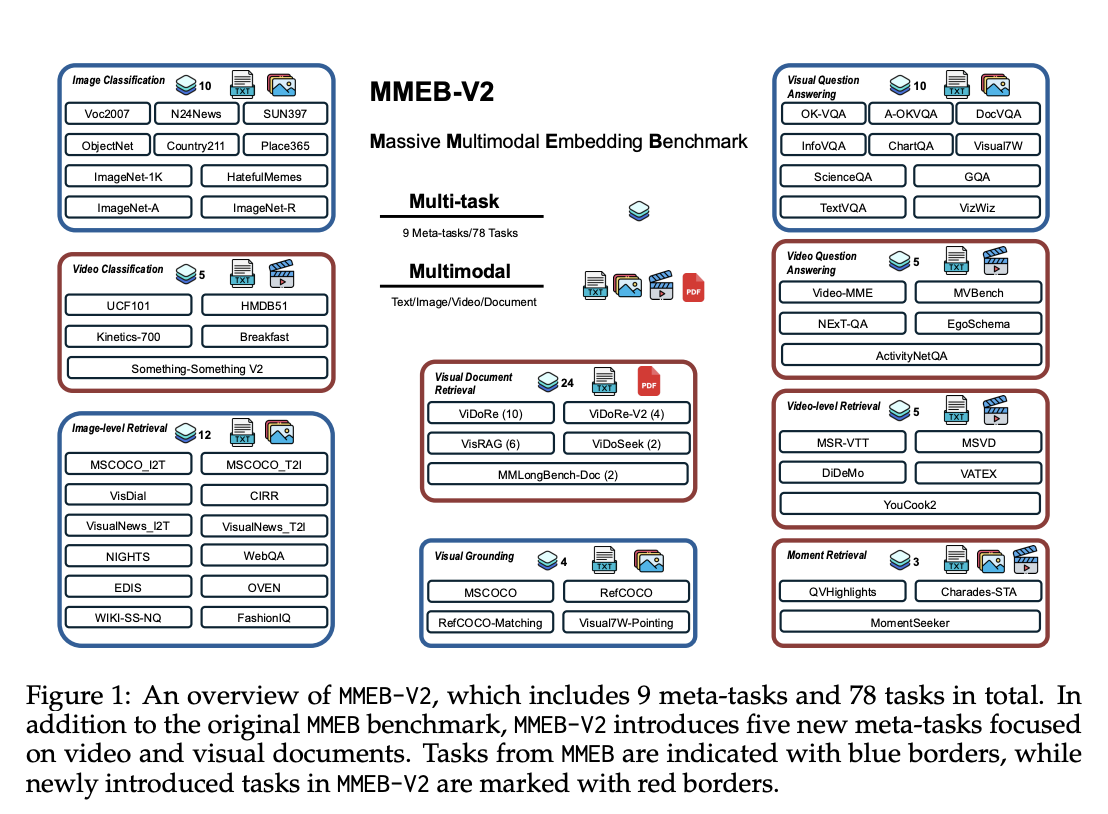
Researchers from Salesforce Research, UC Santa Barbara, University of Waterloo, and Tsinghua University have proposed VLM2Vec-V2 to unify image, video, and visual document retrieval within a single framework. Firstly, researchers developed MMEB-V2, a benchmark that extends MMEB with five new task types, including visual document retrieval, video retrieval, temporal grounding, video classification, and video question answering. Secondly, VLM2Vec-V2 serves as a general-purpose embedding model that supports multiple input modalities while demonstrating strong performance on both newly introduced tasks and original image benchmarks. This establishes a foundation for more scalable and flexible representation learning in both research and practical applications.
VLM2Vec-V2 utilizes Qwen2-VL as its backbone, selected for its specialized capabilities in multimodal processing. Qwen2-VL offers three critical features that support unified embedding learning: Naive Dynamic Resolution, Multimodal Rotary Position Embedding (M-RoPE), and a unified framework that combines 2D and 3D convolutions. To enable effective multi-task training across diverse data sources, VLM2Vec-V2 introduces a flexible data sampling pipeline with two key components: (a) on-the-fly batch mixing based on predefined sampling weight tables that control the relative probabilities of each dataset, and (b) an interleaved sub-batching strategy that splits full batches into independently sampled sub-batches, improving the stability of contrastive learning.

VLM2Vec-V2 achieves the highest overall average score of 58.0 across 78 datasets covering image, video, and visual document tasks, outperforming strong baselines including GME, LamRA, and VLM2Vec built on the same Qwen2-VL backbone. On image tasks, VLM2Vec-V2 outperforms most baselines by significant margins and achieves performance comparable to VLM2Vec-7B despite being only 2B parameters in size. For video tasks, the model achieves competitive performance despite training on relatively small amounts of video data. In visual document retrieval, VLM2Vec-V2 outperforms all VLM2Vec variants, but still lags behind ColPali, which is specifically optimized for visual document tasks.

In conclusion, researchers introduced VLM2Vec-V2, a strong baseline model trained through contrastive learning across diverse tasks and modality combinations. VLM2Vec-V2 is built upon MMEB-V2 and uses Qwen2-VL as its backbone model. MMEB-V2 is a benchmark designed by researchers to assess multimodal embedding models across various modalities, including text, images, videos, and visual documents. The experimental evaluation demonstrates the effectiveness of VLM2Vec-V2 in achieving balanced performance across multiple modalities while highlighting the diagnostic value of MMEB-V2 for future research.


Check out the Paper, GitHub Page and Model on Hugging Face. All credit for this research goes to the researchers of this project. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.

Sajjad Ansari is a final year undergraduate from IIT Kharagpur. As a Tech enthusiast, he delves into the practical applications of AI with a focus on understanding the impact of AI technologies and their real-world implications. He aims to articulate complex AI concepts in a clear and accessible manner.
Credit: Source link

ShareTweetSendSharePin

Related Posts

AI Coding Agents for Enterprise: IP Indemnity, Data Residency and 500-Seat Cost Compared
AI & Technology

AI Coding Agents for Enterprise: IP Indemnity, Data Residency and 500-Seat Cost Compared

September 27, 2026
A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation
AI & Technology

A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation

September 27, 2026
Why We Won’t Know How Visible The iPhone Duo’s Crease Is For A Long Time
AI & Technology

Why We Won’t Know How Visible The iPhone Duo’s Crease Is For A Long Time

September 27, 2026
How Powerful Of A Power Bank Do You Need To Safely Charge A Laptop?
AI & Technology

How Powerful Of A Power Bank Do You Need To Safely Charge A Laptop?

September 27, 2026
Next Post
Historic Grand Canyon lodge lost to wildfire

Historic Grand Canyon lodge lost to wildfire

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Line forms outside Lindsay Clancy trial

Line forms outside Lindsay Clancy trial

September 22, 2026
Crews recover SpaceX’s Starship from Indian Ocean

Crews recover SpaceX’s Starship from Indian Ocean

September 21, 2026
‘America’s Bishop’ Was Beatified. 50,000 Catholics Showed Up. – The New York Times

‘America’s Bishop’ Was Beatified. 50,000 Catholics Showed Up. – The New York Times

September 25, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!