• bitcoinBitcoin(BTC)$85,439.004.41%
  • ethereumEthereum(ETH)$2,729.132.39%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$785.992.10%
  • rippleXRP(XRP)$1.525.39%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$116.343.55%
  • tronTRON(TRX)$0.3485561.57%
  • zcashZcash(ZEC)$1,518.121.70%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.011.29%
  • HyperliquidHyperliquid(HYPE)$94.720.52%
  • dogecoinDogecoin(DOGE)$0.0988679.71%
  • moneroMonero(XMR)$572.95-2.77%
  • whitebitWhiteBIT Coin(WBT)$85.902.82%
  • RainRain(RAIN)$0.013626-2.58%
  • chainlinkChainlink(LINK)$12.902.70%
  • USDSUSDS(USDS)$1.000.00%
  • cardanoCardano(ADA)$0.2455925.51%
  • leo-tokenLEO Token(LEO)$8.980.70%
  • stellarStellar(XLM)$0.2121315.97%
  • nearNEAR Protocol(NEAR)$4.372.44%
  • uniswapUniswap(UNI)$8.933.42%
  • bitcoin-cashBitcoin Cash(BCH)$267.544.53%
  • Ethena USDeEthena USDe(USDE)$1.00-0.04%
  • avalanche-2Avalanche(AVAX)$10.73-2.38%
  • CantonCanton(CC)$0.1194495.49%
  • litecoinLitecoin(LTC)$60.693.76%
  • daiDai(DAI)$1.000.01%
  • USD1USD1(USD1)$1.00-0.02%
  • hedera-hashgraphHedera(HBAR)$0.0952039.28%
  • suiSui(SUI)$1.014.46%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.431.68%
  • BittensorBittensor(TAO)$315.7915.19%
  • shiba-inuShiba Inu(SHIB)$0.0000066.97%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • crypto-com-chainCronos(CRO)$0.0656115.28%
  • MemeCoreMemeCore(M)$1.35-12.45%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,307.34-0.98%
  • okbOKB(OKB)$122.122.36%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.140.33%
  • BitwayBitway(BTW)$0.813.78%
  • aaveAave(AAVE)$141.371.92%
  • pepePepe(PEPE)$0.00000526.66%
  • EthenaEthena(ENA)$0.212922-1.15%
  • Pump.funPump.fun(PUMP)$0.0045532.99%
  • mantleMantle(MNT)$0.645.90%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Unlocking the Language of Proteins: How Large Language Models Are Revolutionizing Protein Sequence Understanding

June 14, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Unlocking the Language of Proteins: How Large Language Models Are Revolutionizing Protein Sequence Understanding
ShareShareShareShareShare

Researchers have drawn parallels between protein sequences and natural language due to their sequential structures, leading to advancements in deep learning models for both fields. LLMs have excelled in NLP tasks, and this success has inspired attempts to adapt them to understanding proteins. However, this adaptation faces a challenge: existing datasets need more direct correlations between protein sequences and text descriptions, hindering effective training and evaluation of LLMs for protein comprehension. Despite advances in MMLMs, the absence of comprehensive datasets integrating protein sequences with textual content limits the full utilization of these models in protein science.

Researchers from several institutions, including Johns Hopkins and UNSW Sydney, have created ProteinLMDataset to enhance LLMs’ understanding of protein sequences. This dataset contains 17.46 billion tokens for self-supervised pretraining and 893K instructions for supervised fine-tuning. They also developed ProteinLMBench, the first benchmark with 944 manually verified multiple-choice questions for evaluating protein comprehension in LLMs. The dataset and benchmark aim to bridge the gap in protein-text data integration, enabling LLMs to understand protein sequences without extra encoders and to generate accurate protein knowledge using the novel Enzyme Chain of Thought (ECoT) approach.

The literature review highlights key limitations in existing datasets and NLP and protein sequence benchmarks. There need to be more comprehensive, multi-task, and multi-domain evaluations for Chinese-English datasets, with existing benchmarks often restricted geographically and needing more interpretability. In protein sequence datasets, major resources like UniProtKB and RefSeq face challenges in fully representing protein diversity and accurately annotating data, with biases and errors from community contributions and automated systems. While comprehensive, protein design databases like KEGG and STRING are limited by biases, resource-intensive curation, and difficulties in integrating diverse data sources.

The ProteinLMDataset is divided into self-supervised and supervised components. The self-supervised dataset includes Chinese-English scientific texts, protein sequence-English text pairs from PubMed and UniProtKB, and extensive entries from the PMC database, providing over 10 billion tokens. The supervised fine-tuning component consists of 893,000 instructions across seven segments, such as enzyme functionality and disease involvement, mainly sourced from UniProtKB. ProteinLMBench, the evaluation benchmark, contains 944 meticulously curated multiple-choice questions on protein properties and sequences. This dataset collection method ensures comprehensive representation, filtering, and tokenization for effective training and evaluation of LLMs in protein science.

The ProteinLMDataset and ProteinLMBench are designed for comprehensive protein sequence understanding. The dataset is diverse, with tokens ranging from 21 to over 2 million characters, collected from multiple sources, including Chinese-English text pairs, PubMed abstracts, and UniProtKB. The self-supervised data primarily consists of protein sequences and scientific texts. At the same time, the supervised fine-tuning dataset covers seven segments like enzyme functionality and disease involvement, with token lengths from 65 to 70,500. The ProteinLMBench includes 944 balanced multiple-choice questions to evaluate model performance. Rigorous safety checks and filtering ensure data quality and integrity. Experiment results show that combining self-supervised learning with fine-tuning enhances model accuracy, underscoring the dataset’s efficacy.

In conclusion, The ProteinLMDataset and ProteinLMBench provide a robust framework for training and evaluating language models on protein sequences and bilingual texts. By encompassing diverse sources and including Chinese-English text pairs, the dataset enhances multilingual and cross-lingual understanding of protein characteristics. Experiments demonstrate significant improvements in model accuracy with fine-tuning, especially when using both self-supervised and supervised datasets. This work bridges the gap in adapting LLMs for protein science, showcasing the potential to transform biological research and applications. The InternLM2-7B model, when trained on this dataset, surpasses GPT-4 in protein comprehension tasks.

issues.


Check out the Paper and Dataset. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 44k+ ML SubReddit

YOU MAY ALSO LIKE

NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%

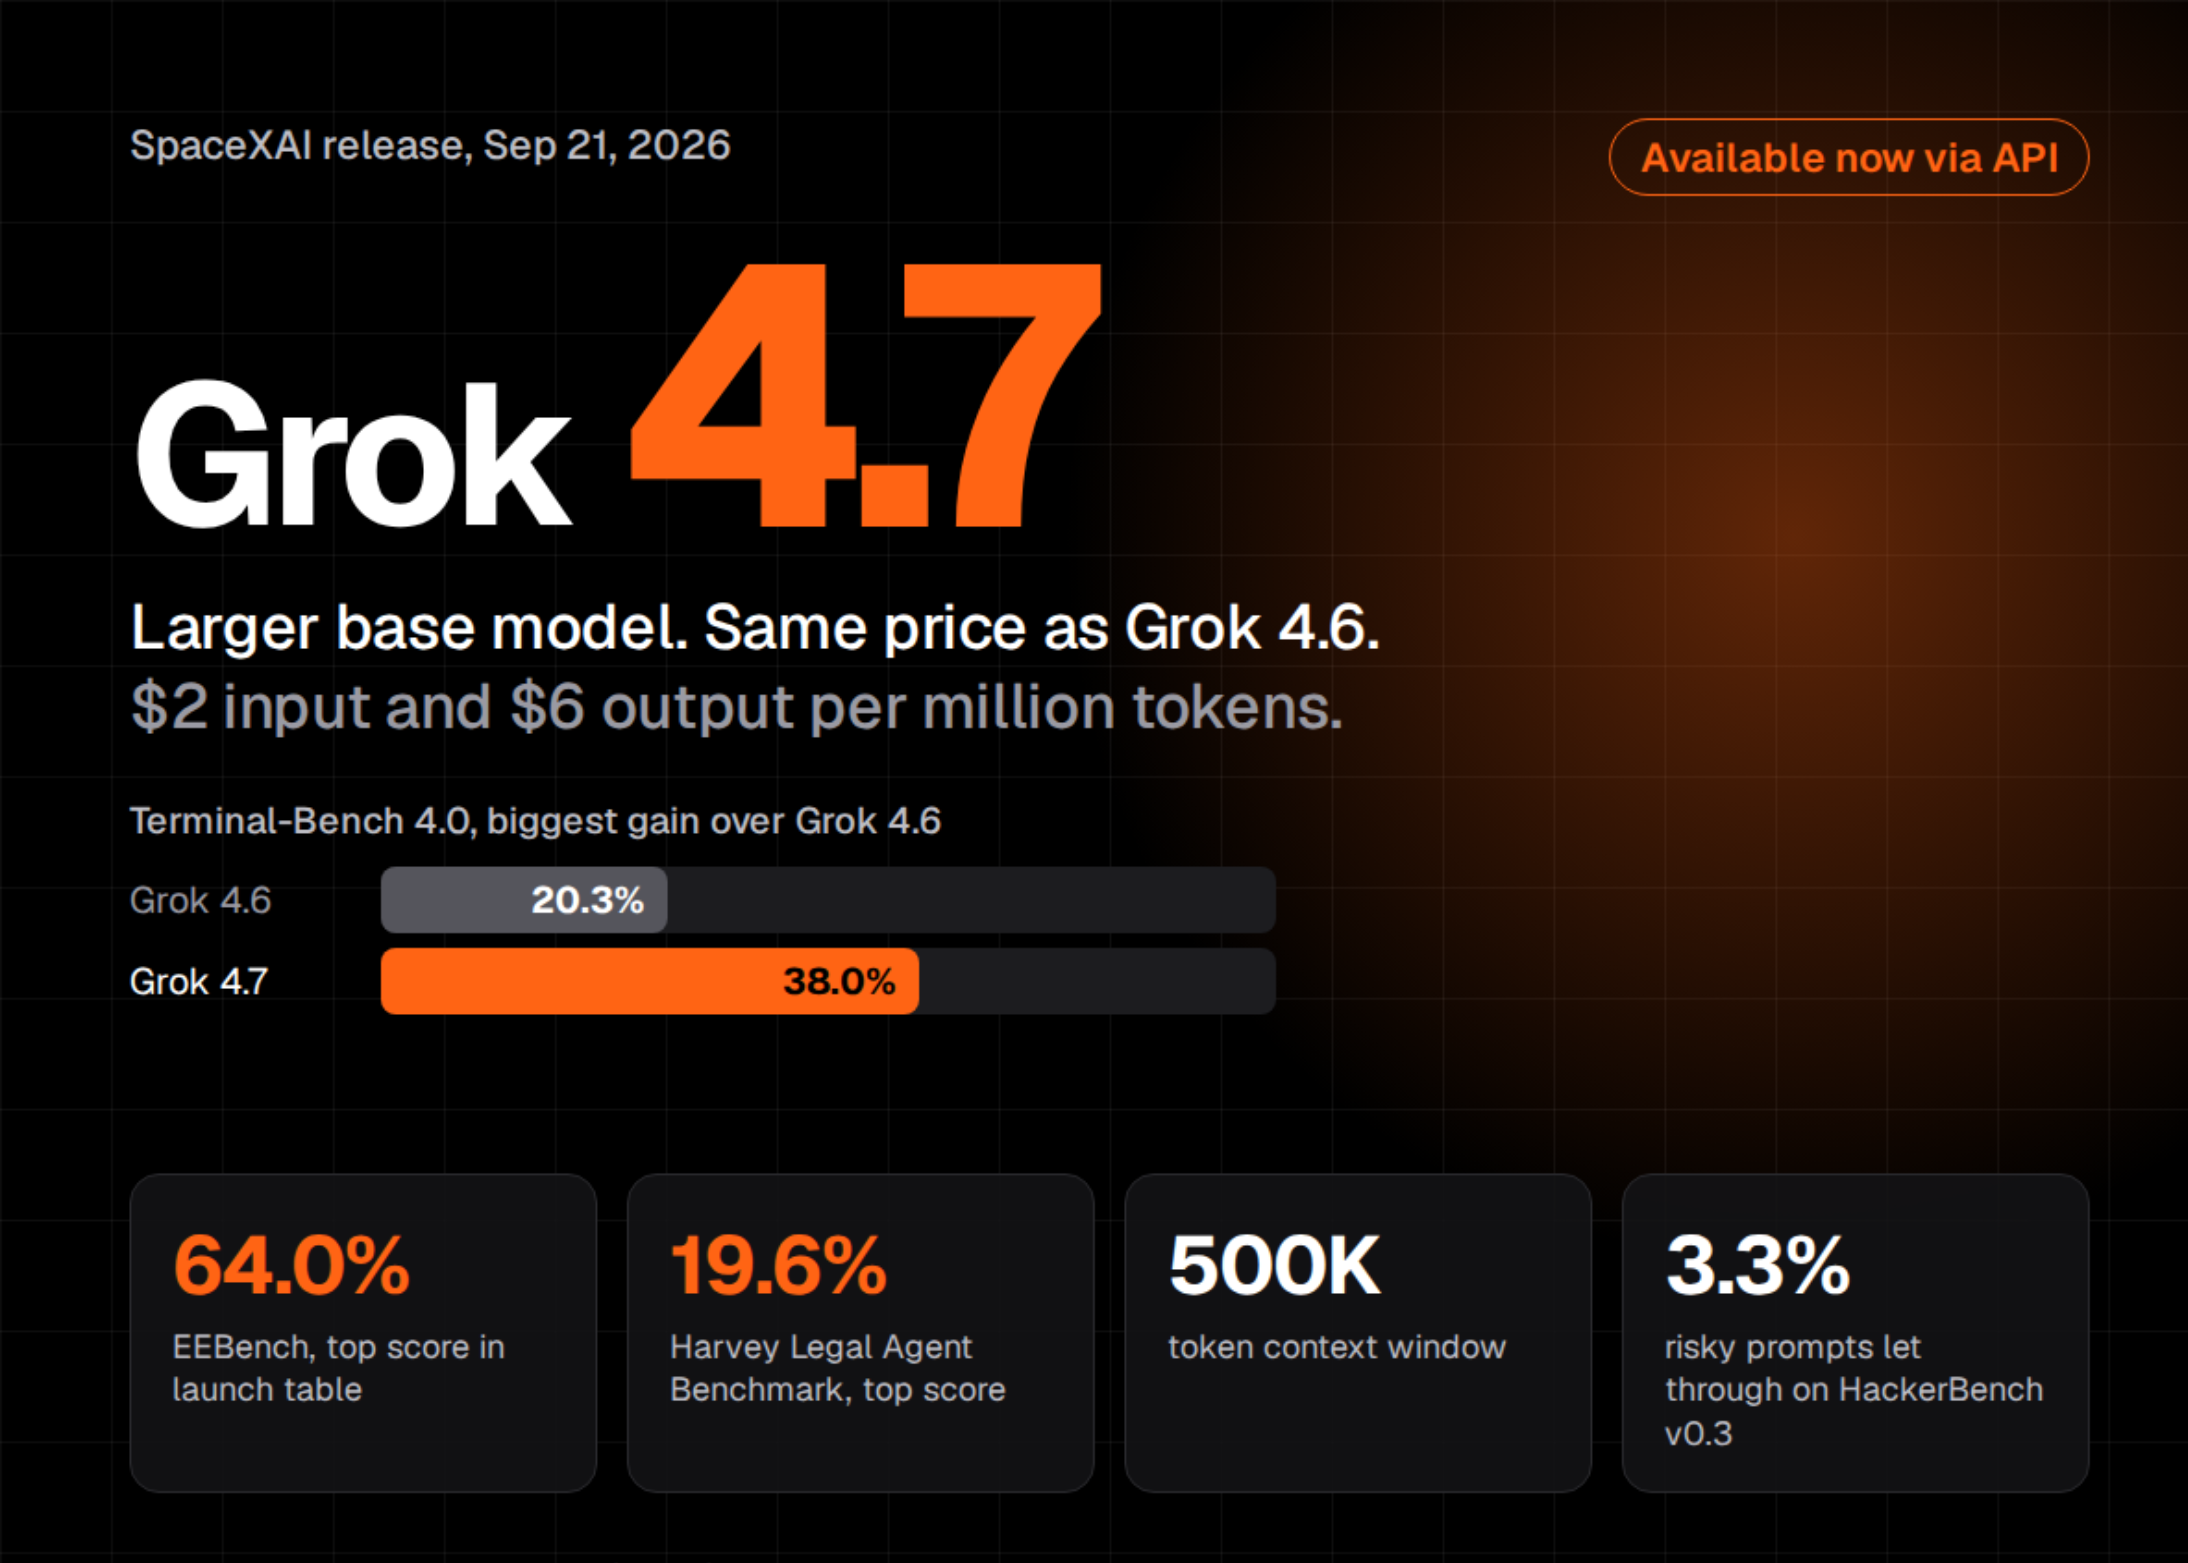
SpaceXAI Releases Grok 4.7: A Larger Base Model at the Same $2/$6 Price as Grok 4.6

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%
AI & Technology

NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%

September 22, 2026
SpaceXAI Releases Grok 4.7: A Larger Base Model at the Same / Price as Grok 4.6
AI & Technology

SpaceXAI Releases Grok 4.7: A Larger Base Model at the Same $2/$6 Price as Grok 4.6

September 22, 2026
Why It’s Important To Unplug Your PC During A Power Outage
AI & Technology

Why It’s Important To Unplug Your PC During A Power Outage

September 22, 2026
Why Is Your Laptop Fan So Loud?
AI & Technology

Why Is Your Laptop Fan So Loud?

September 22, 2026
Next Post
Baseball’s biggest star Shohei Ohtani signs 0 million deal with LA Dodgers

Baseball’s biggest star Shohei Ohtani signs $700 million deal with LA Dodgers

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Harbor Transformative Technologies ETF Q2 2026 Commentary

Harbor Transformative Technologies ETF Q2 2026 Commentary

September 20, 2026
Don’t Panic! How To Prepare For The FOMC Rate Decision!

Don’t Panic! How To Prepare For The FOMC Rate Decision!

September 17, 2026
Special report: Five dead after Amazon cargo plane overruns runway at Miami airport

Special report: Five dead after Amazon cargo plane overruns runway at Miami airport

September 16, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!