• bitcoinBitcoin(BTC)$84,866.001.01%
  • ethereumEthereum(ETH)$2,714.621.20%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$779.661.12%
  • rippleXRP(XRP)$1.54-0.29%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$124.303.58%
  • tronTRON(TRX)$0.333614-0.93%
  • zcashZcash(ZEC)$1,661.549.07%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.063.69%
  • HyperliquidHyperliquid(HYPE)$93.201.63%
  • dogecoinDogecoin(DOGE)$0.0978140.72%
  • chainlinkChainlink(LINK)$14.382.76%
  • moneroMonero(XMR)$558.021.06%
  • whitebitWhiteBIT Coin(WBT)$84.711.04%
  • USDSUSDS(USDS)$1.00-0.01%
  • cardanoCardano(ADA)$0.2567271.01%
  • RainRain(RAIN)$0.0127188.51%
  • leo-tokenLEO Token(LEO)$9.061.09%
  • stellarStellar(XLM)$0.2177450.47%
  • nearNEAR Protocol(NEAR)$5.299.93%
  • bitcoin-cashBitcoin Cash(BCH)$340.671.06%
  • uniswapUniswap(UNI)$10.074.54%
  • litecoinLitecoin(LTC)$71.86-3.13%
  • CantonCanton(CC)$0.1367251.02%
  • suiSui(SUI)$1.268.29%
  • Ethena USDeEthena USDe(USDE)$1.000.02%
  • avalanche-2Avalanche(AVAX)$11.085.02%
  • daiDai(DAI)$1.000.01%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.6011.09%
  • USD1USD1(USD1)$1.000.01%
  • hedera-hashgraphHedera(HBAR)$0.0949871.43%
  • BittensorBittensor(TAO)$332.426.44%
  • shiba-inuShiba Inu(SHIB)$0.0000061.59%
  • crypto-com-chainCronos(CRO)$0.0684754.60%
  • Global DollarGlobal Dollar(USDG)$1.00-0.02%
  • BitwayBitway(BTW)$1.1021.55%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • MemeCoreMemeCore(M)$1.21-0.80%
  • EthenaEthena(ENA)$0.269795-2.47%
  • tether-goldTether Gold(XAUT)$4,279.720.01%
  • OndoOndo(ONDO)$0.54-0.34%
  • quant-networkQuant(QNT)$177.0468.37%
  • okbOKB(OKB)$122.010.98%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • aaveAave(AAVE)$156.312.23%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.23%
  • mantleMantle(MNT)$0.69-2.78%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

This AI Paper Introduces DyCoke: Dynamic Token Compression for Efficient and High-Performance Video Large Language Models

November 28, 2024
in AI & Technology
Reading Time: 5 mins read
A A
This AI Paper Introduces DyCoke: Dynamic Token Compression for Efficient and High-Performance Video Large Language Models
ShareShareShareShareShare

Video large language models (VLLMs) have emerged as transformative tools for analyzing video content. These models excel in multimodal reasoning, integrating visual and textual data to interpret and respond to complex video scenarios. Their applications range from question-answering about videos to summarization and video description. With their capacity to process large-scale inputs and provide detailed outputs, they are crucial in tasks requiring advanced comprehension of visual dynamics.

One key challenge in VLLMs is managing the computational costs of processing vast visual data from video inputs. Videos inherently carry high redundancy as frames often capture overlapping information. These frames generate thousands of tokens when processed, leading to significant memory consumption and slower inference speeds. Addressing this issue is critical for making VLLMs efficient without compromising their ability to perform complex reasoning tasks.

YOU MAY ALSO LIKE

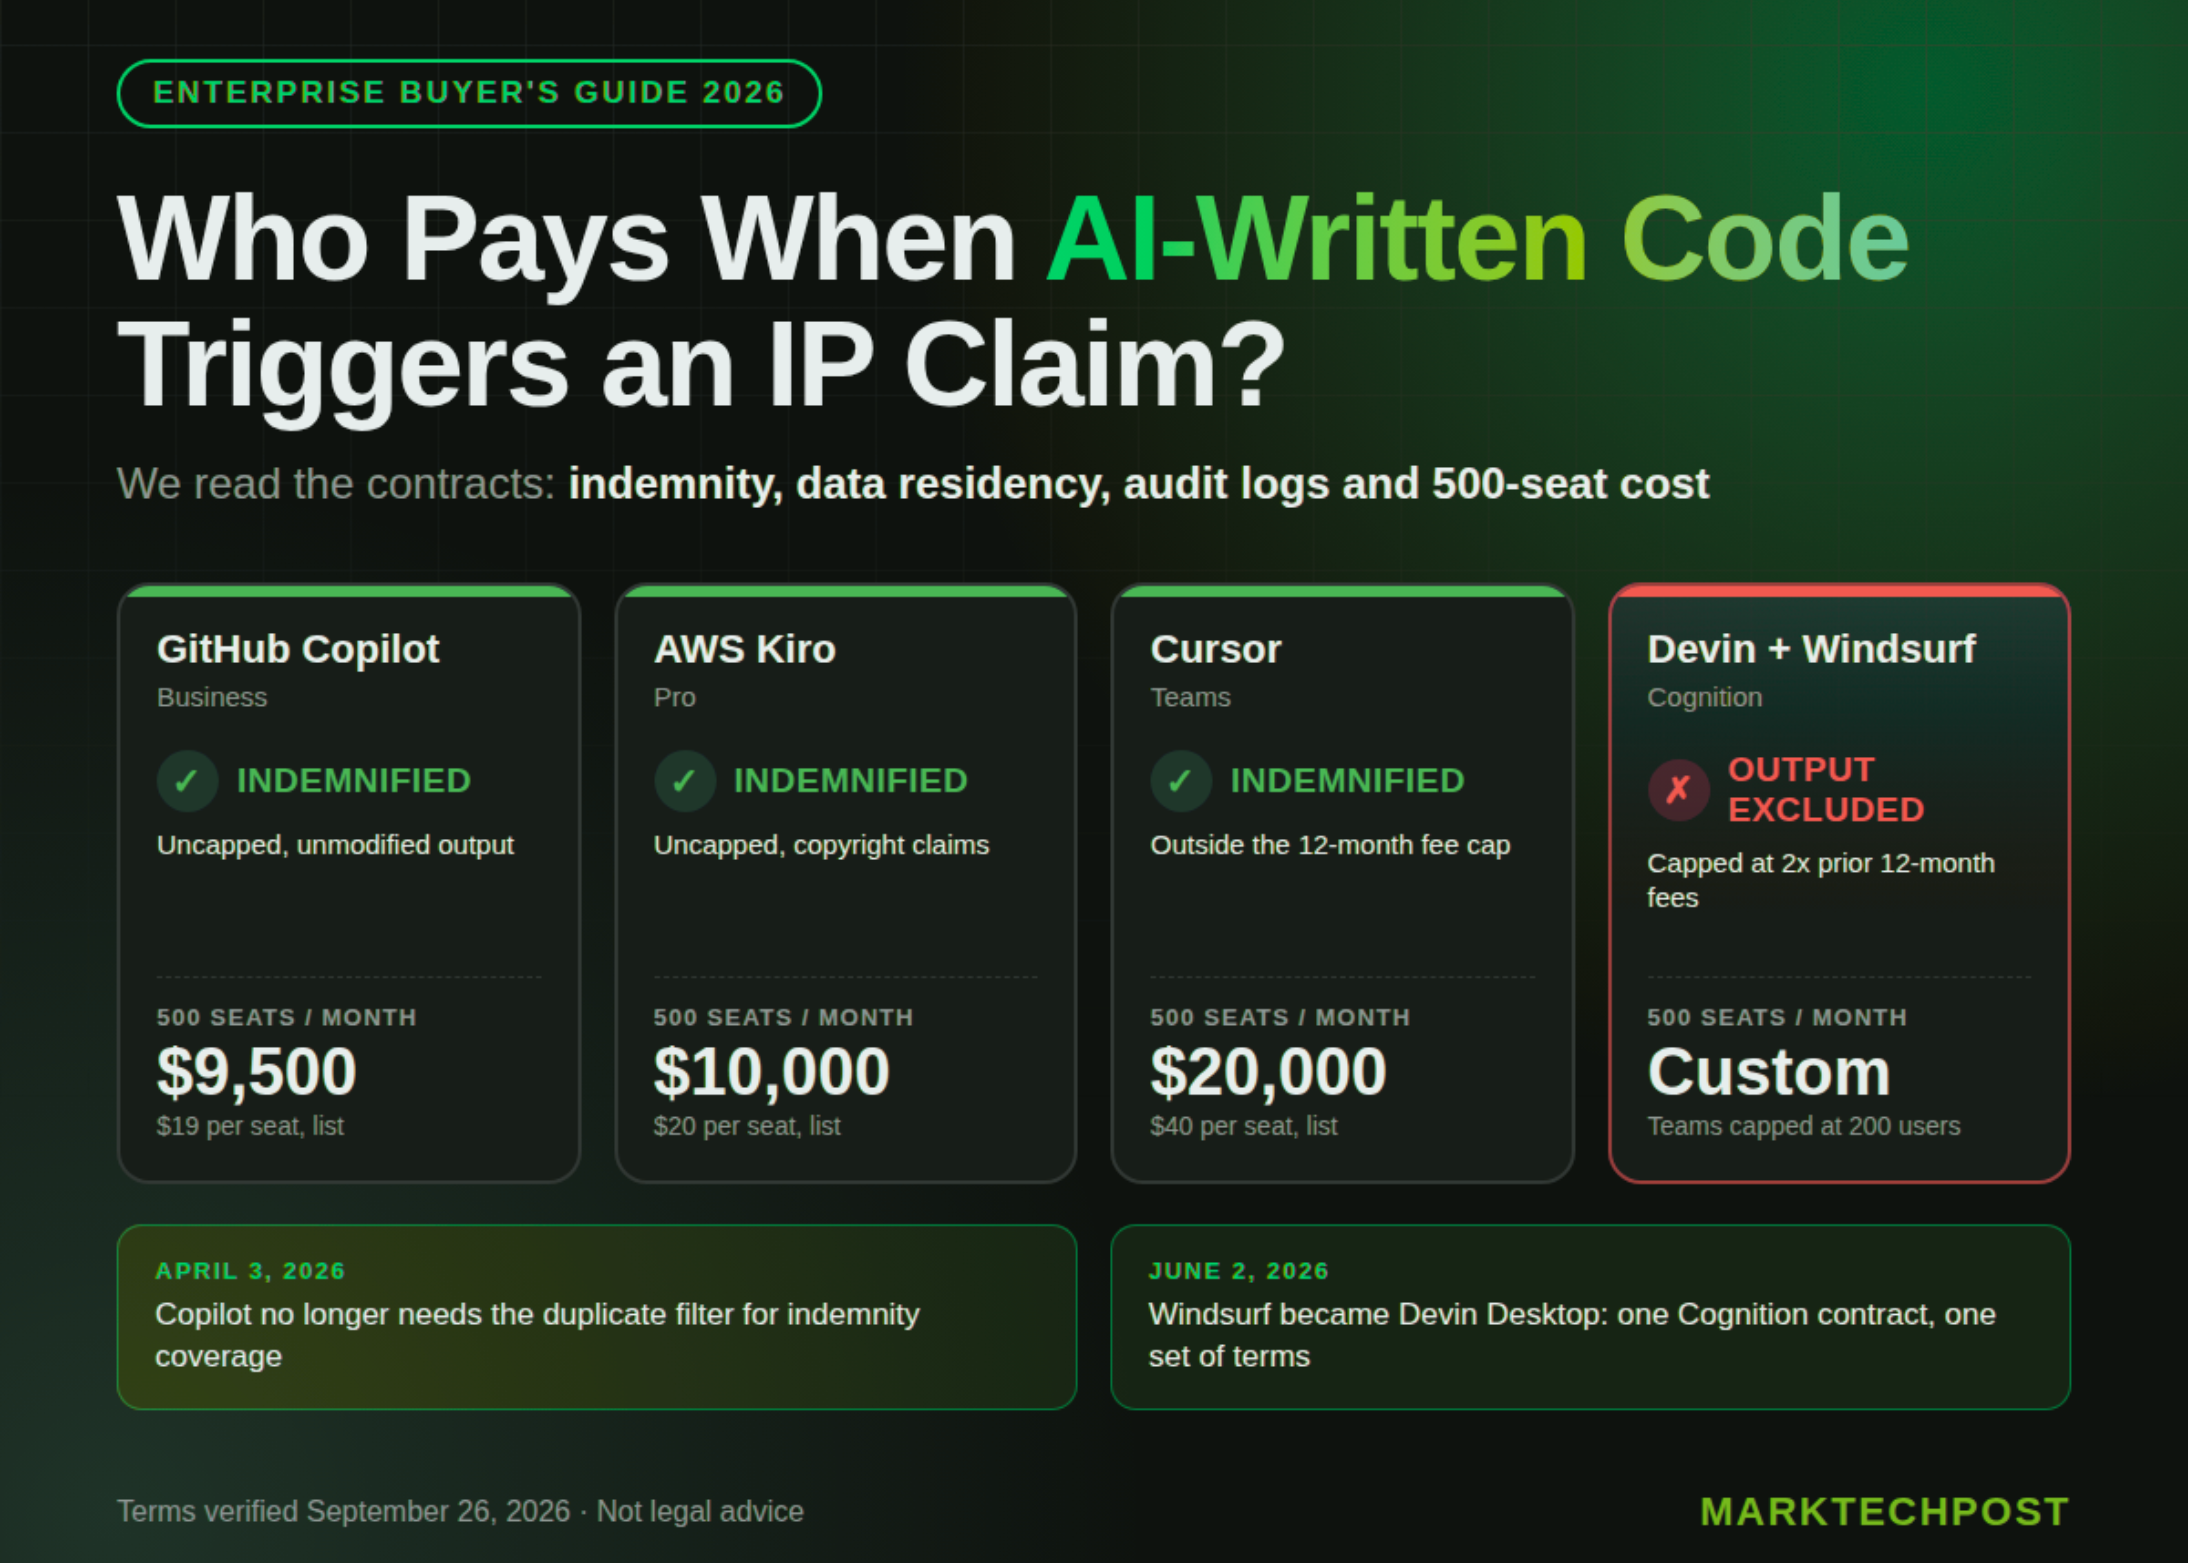
AI Coding Agents for Enterprise: IP Indemnity, Data Residency and 500-Seat Cost Compared

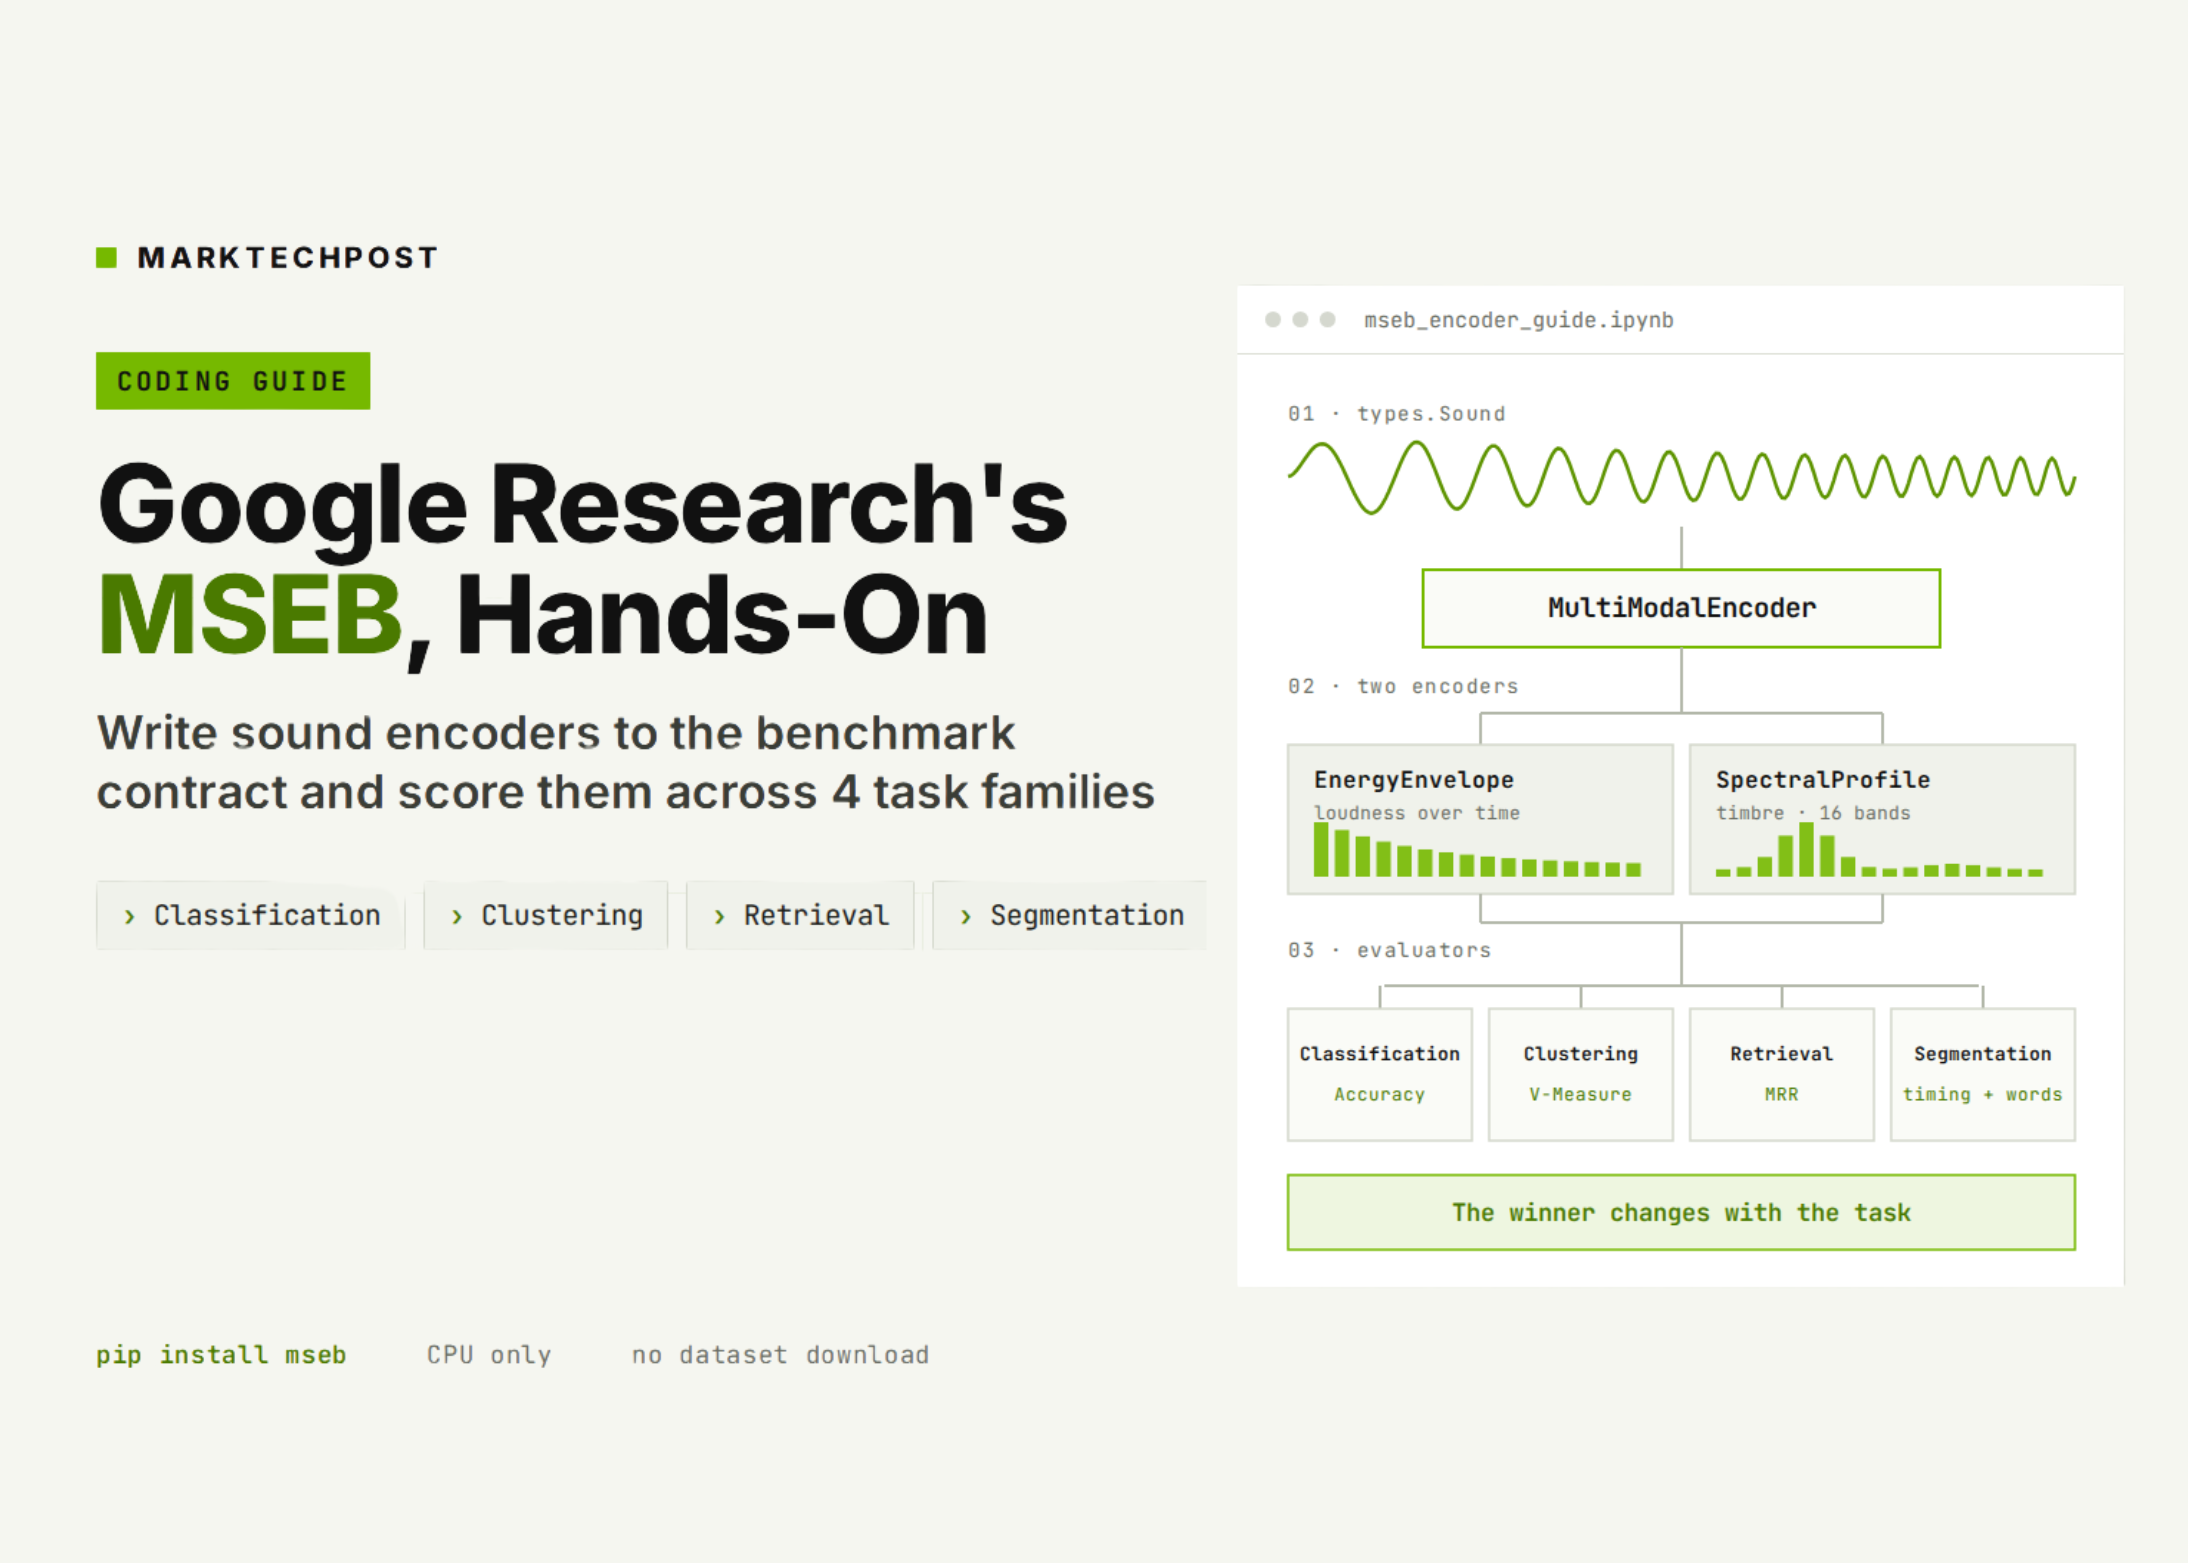
A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation

Current methods have attempted to mitigate computational constraints by introducing token pruning techniques and designing lightweight models. For example, pruning methods like FastV leverage attention scores to reduce less relevant tokens. However, these approaches often rely on static one-shot pruning strategies, which can inadvertently remove critical tokens necessary for maintaining high accuracy. Moreover, parameter reduction techniques frequently compromise the reasoning capabilities of the models, limiting their application to demanding tasks.

Researchers from Westlake University, Salesforce AI Research, Apple AI/ML, and Rice University introduced DyCoke, a novel method designed to dynamically compress tokens in large video language models. DyCoke adopts a training-free approach, distinguishing itself by addressing temporal and spatial redundancies in video inputs. By implementing dynamic and adaptive pruning mechanisms, the method optimizes computational efficiency while preserving high performance. This innovation aims to make VLLMs scalable for real-world applications without requiring fine-tuning or additional training.

DyCoke employs a two-stage process for token compression. Temporal token merging consolidates redundant tokens across adjacent video frames in the first stage. This module groups frames into sampling windows and identifies overlapping information, merging tokens to retain only distinct and representative ones. For instance, visual redundancy in static backgrounds or repeated actions is effectively reduced. During the decoding phase, the second stage employs a dynamic pruning technique in the key-value (KV) cache. Tokens are dynamically evaluated and retained based on their attention scores. This step ensures that only the most critical tokens remain, while irrelevant tokens are stored in a dynamic pruning cache for potential reuse. By iteratively refining the KV cache at each decoding step, DyCoke aligns computational load with the actual significance of tokens.
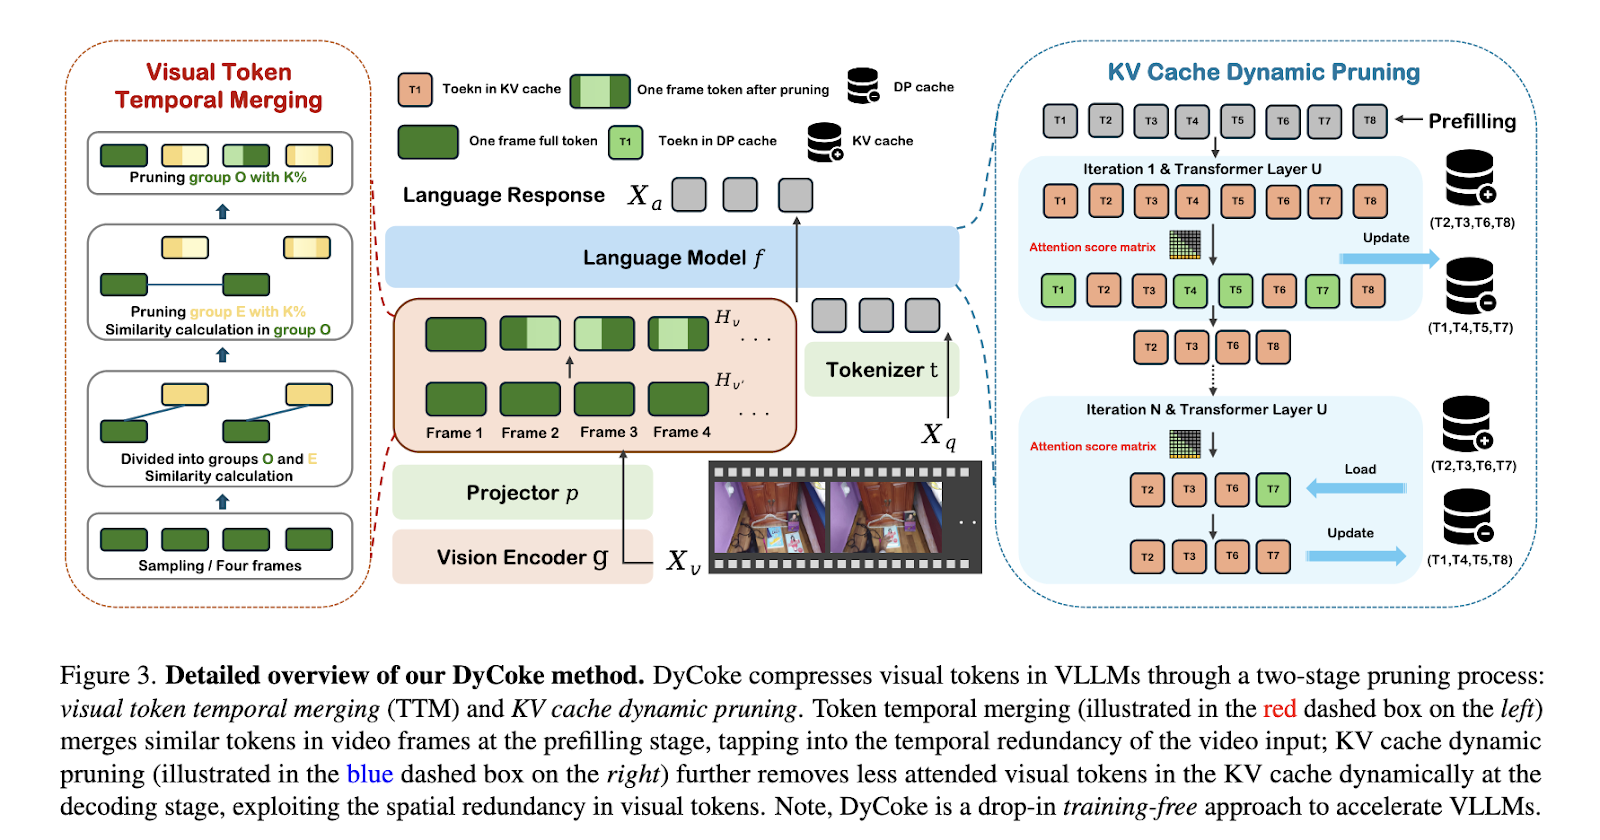
The results of DyCoke highlight its efficiency and robustness. On benchmarks such as MVBench, which includes 20 complex tasks like action recognition and object interaction, DyCoke achieved up to 1.5× inference speedup and a 1.4× reduction in memory usage compared to baseline models. Specifically, the method reduced the number of retained tokens to as low as 14.25% in some configurations, with minimal performance degradation. On the VideoMME dataset, DyCoke excelled in processing long video sequences, demonstrating superior efficiency while maintaining or surpassing uncompressed models’ accuracy. For example, with a pruning rate 0.5, it achieved a latency reduction of up to 47%. It outperformed state-of-the-art methods like FastV in maintaining accuracy across tasks such as episodic reasoning and egocentric navigation.

DyCoke’s contribution extends beyond speed and memory efficiency. It simplifies video reasoning tasks by reducing temporal and spatial redundancy in visual inputs, effectively balancing performance and resource utilization. Unlike previous methods that required extensive training, DyCoke operates as a plug-and-play solution, making it accessible for a wide range of video language models. Its ability to dynamically adjust token retention ensures that critical information is preserved, even in demanding inference scenarios.
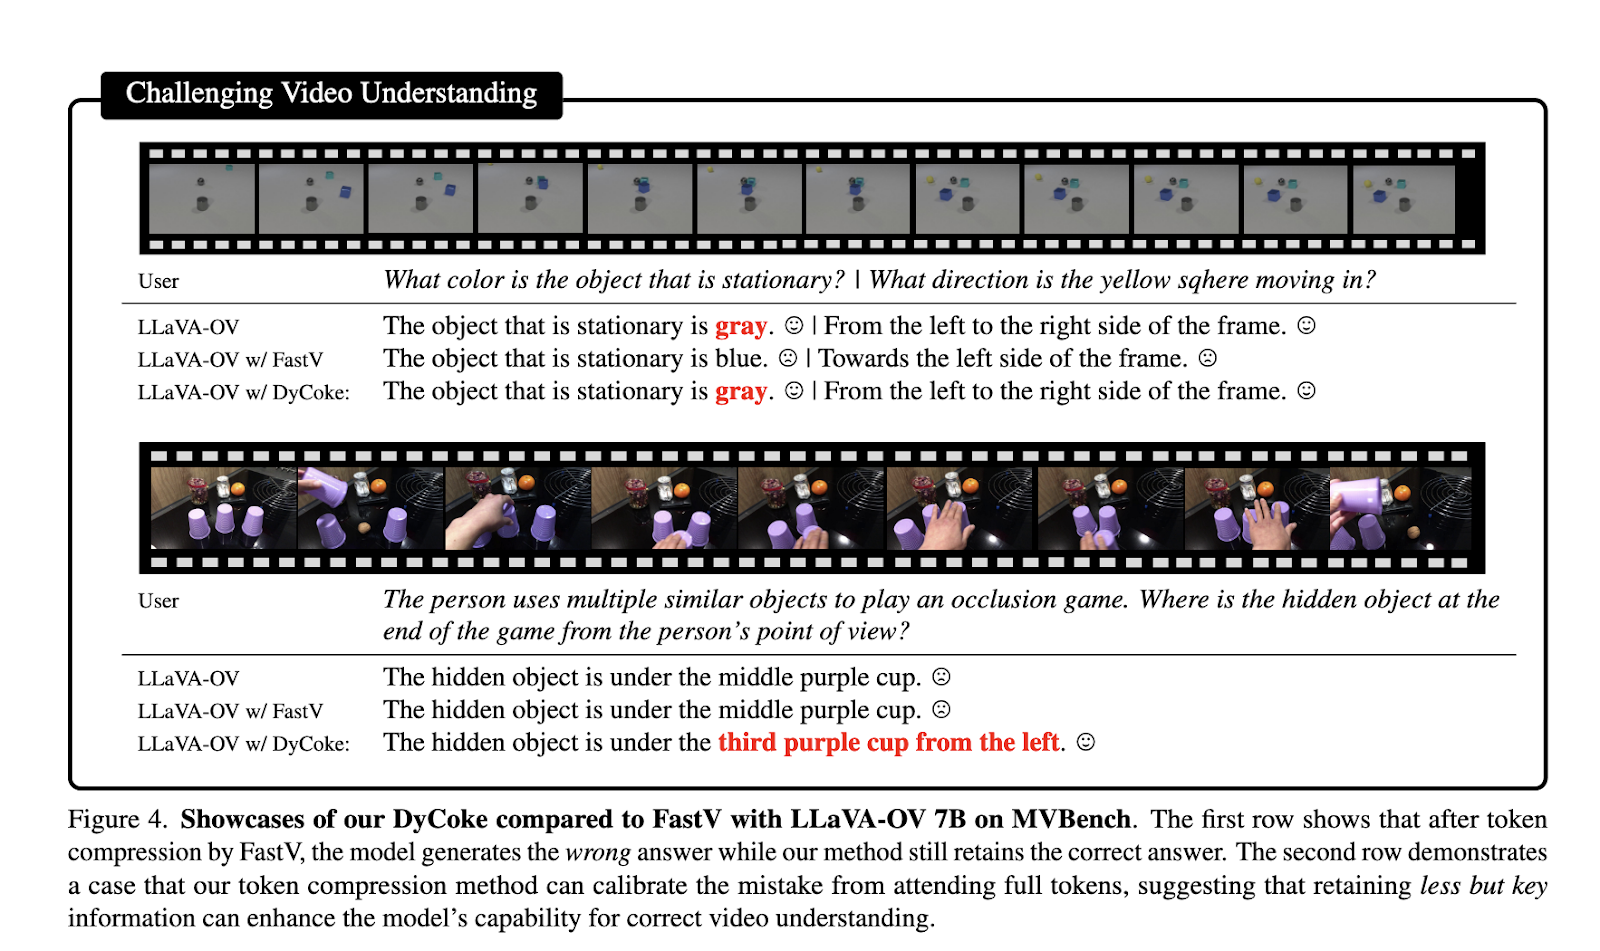
Overall, DyCoke represents a significant step forward in the evolution of VLLMs. Addressing the computational challenges inherent in video processing enables these models to operate more efficiently without compromising their reasoning capabilities. This innovation advances state-of-the-art video understanding and opens new possibilities for deploying VLLMs in real-world scenarios where computational resources are often limited.


Check out the Paper and GitHub. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter.. Don’t Forget to join our 55k+ ML SubReddit.

🎙️ 🚨 ‘Evaluation of Large Language Model Vulnerabilities: A Comparative Analysis of Red Teaming Techniques’ Read the Full Report (Promoted)

Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in Materials at the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast who is always researching applications in fields like biomaterials and biomedical science. With a strong background in Material Science, he is exploring new advancements and creating opportunities to contribute.

🧵🧵 [Download] Evaluation of Large Language Model Vulnerabilities Report (Promoted)


Credit: Source link

ShareTweetSendSharePin

Related Posts

AI Coding Agents for Enterprise: IP Indemnity, Data Residency and 500-Seat Cost Compared
AI & Technology

AI Coding Agents for Enterprise: IP Indemnity, Data Residency and 500-Seat Cost Compared

September 27, 2026
A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation
AI & Technology

A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation

September 27, 2026
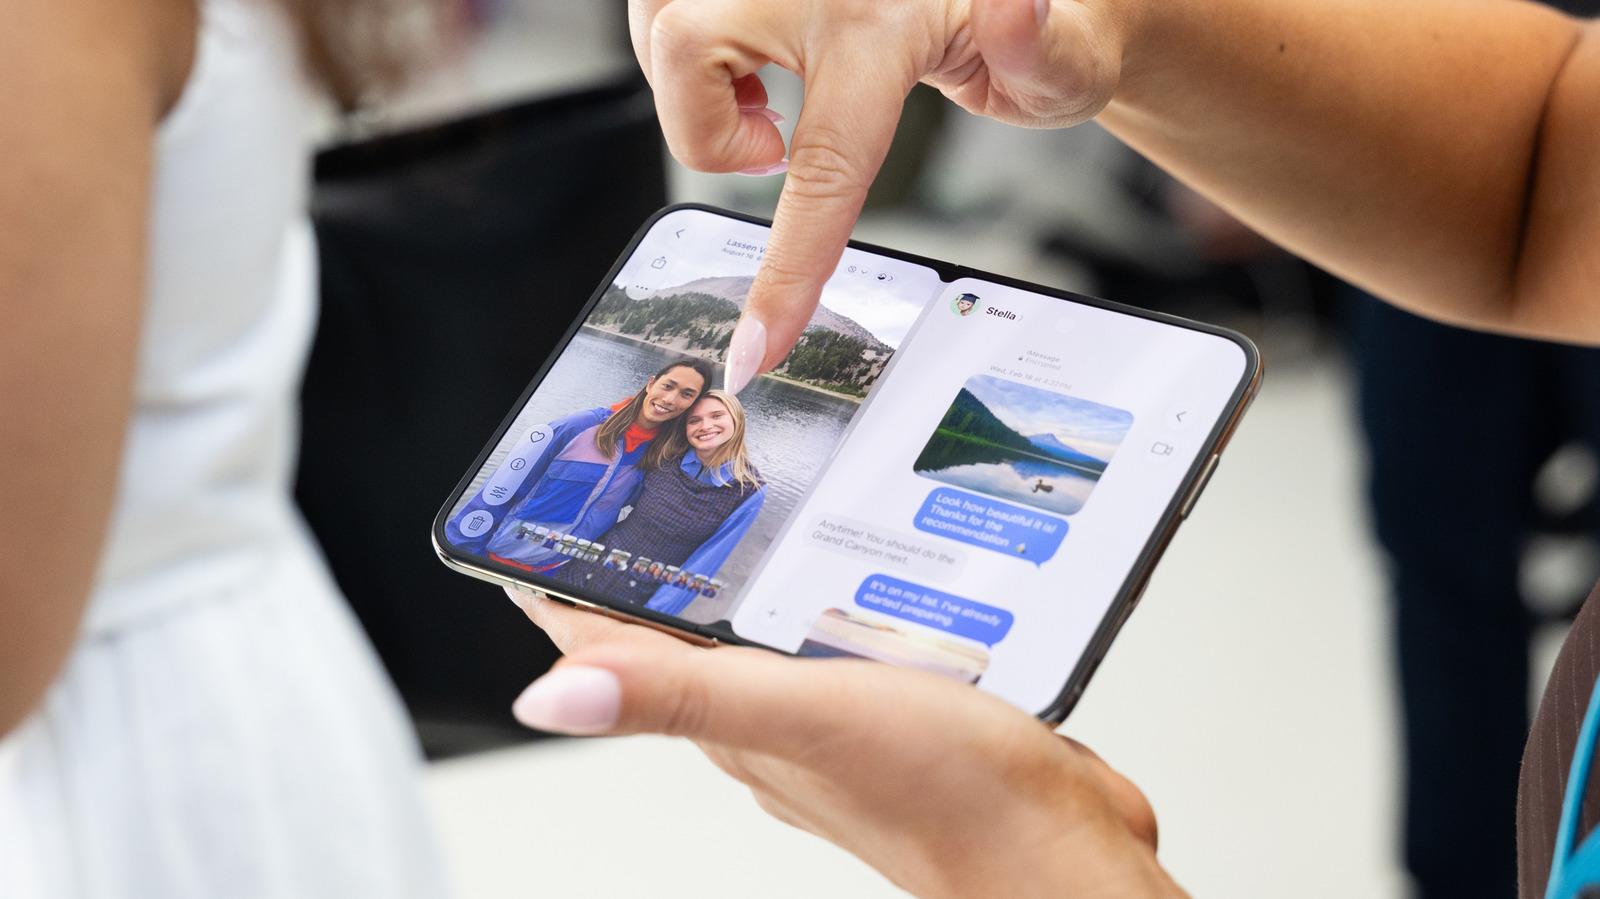
Why We Won’t Know How Visible The iPhone Duo’s Crease Is For A Long Time
AI & Technology

Why We Won’t Know How Visible The iPhone Duo’s Crease Is For A Long Time

September 27, 2026
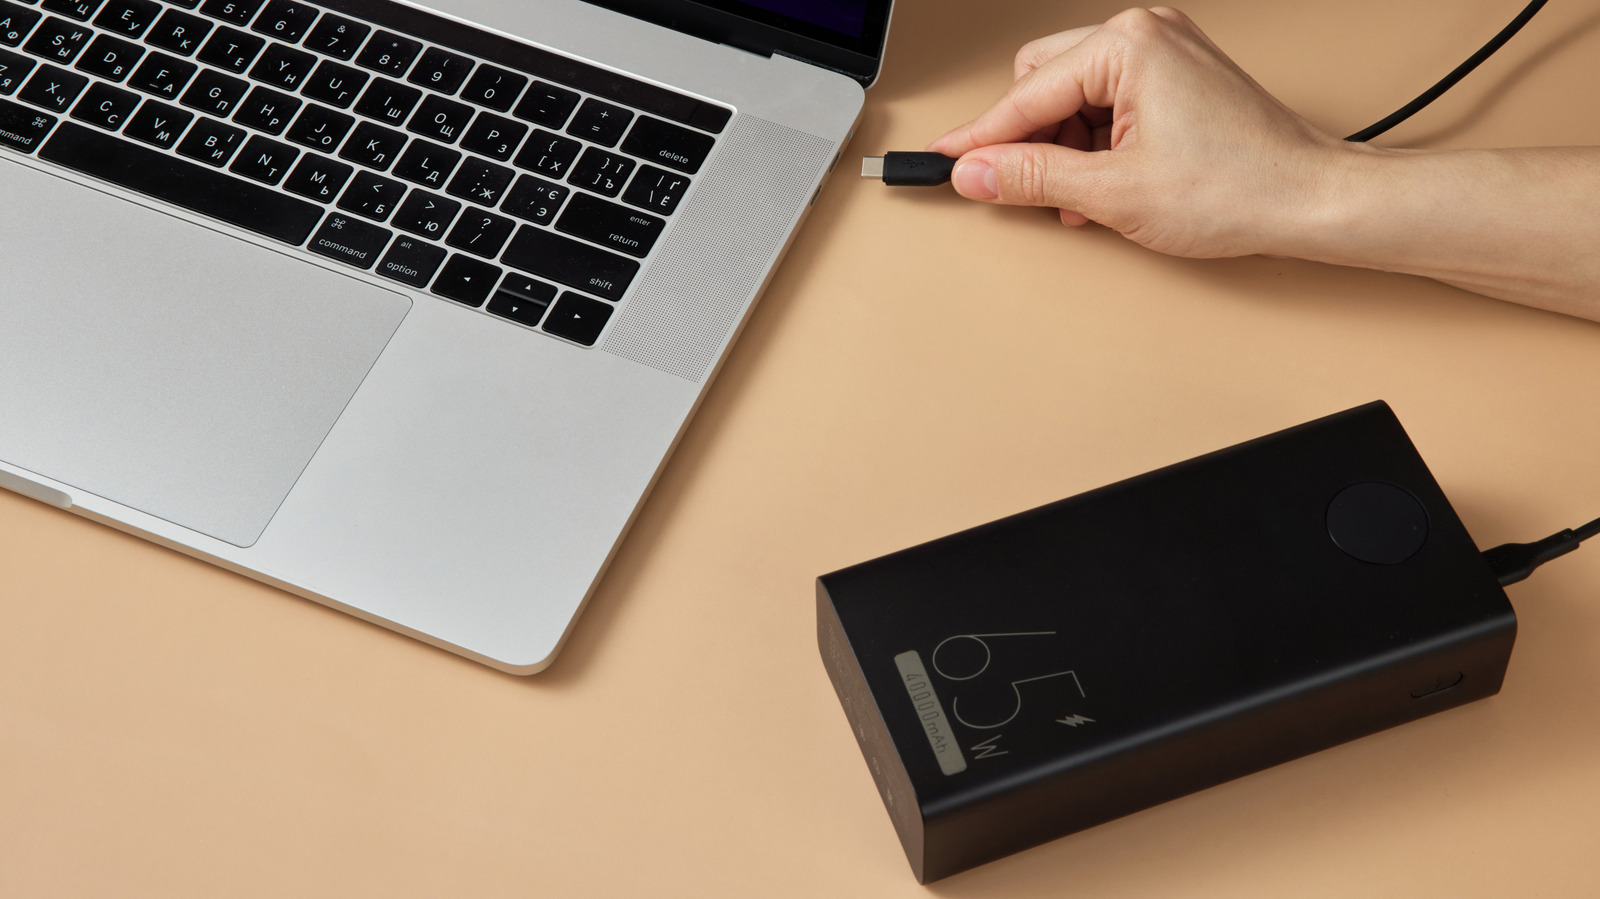
How Powerful Of A Power Bank Do You Need To Safely Charge A Laptop?
AI & Technology

How Powerful Of A Power Bank Do You Need To Safely Charge A Laptop?

September 27, 2026
Next Post
35 Best Black Friday TV Deals: Up to ,200 Off Top TVs From Samsung, Roku, Sony, LG, Hisense, TCL and More – CNET

35 Best Black Friday TV Deals: Up to $1,200 Off Top TVs From Samsung, Roku, Sony, LG, Hisense, TCL and More - CNET

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
She Was Attacked By A Shark!? And Survived!? What’s Going On?

She Was Attacked By A Shark!? And Survived!? What’s Going On?

September 23, 2026
Live Updates: Mamdani and Trump Discuss Immigration and Affordability at Gracie Mansion – The New York Times

Live Updates: Mamdani and Trump Discuss Immigration and Affordability at Gracie Mansion – The New York Times

September 21, 2026
Mother and son charged in teen death

Mother and son charged in teen death

September 25, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!