• bitcoinBitcoin(BTC)$84,505.000.55%
  • ethereumEthereum(ETH)$2,703.270.37%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$773.27-0.33%
  • rippleXRP(XRP)$1.53-2.79%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$121.51-0.34%
  • tronTRON(TRX)$0.333506-1.18%
  • zcashZcash(ZEC)$1,641.526.62%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.063.40%
  • HyperliquidHyperliquid(HYPE)$93.401.23%
  • dogecoinDogecoin(DOGE)$0.096664-2.31%
  • chainlinkChainlink(LINK)$14.312.32%
  • moneroMonero(XMR)$558.120.11%
  • whitebitWhiteBIT Coin(WBT)$84.260.38%
  • USDSUSDS(USDS)$1.000.01%
  • cardanoCardano(ADA)$0.253187-3.25%
  • RainRain(RAIN)$0.01280219.95%
  • leo-tokenLEO Token(LEO)$8.981.03%
  • stellarStellar(XLM)$0.215737-2.47%
  • bitcoin-cashBitcoin Cash(BCH)$335.64-1.92%
  • nearNEAR Protocol(NEAR)$5.093.71%
  • uniswapUniswap(UNI)$9.792.37%
  • litecoinLitecoin(LTC)$71.93-1.48%
  • CantonCanton(CC)$0.1357910.92%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • suiSui(SUI)$1.180.41%
  • avalanche-2Avalanche(AVAX)$10.82-0.83%
  • daiDai(DAI)$1.000.01%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.6010.32%
  • USD1USD1(USD1)$1.000.01%
  • hedera-hashgraphHedera(HBAR)$0.093238-1.90%
  • BittensorBittensor(TAO)$322.132.05%
  • shiba-inuShiba Inu(SHIB)$0.000006-1.48%
  • crypto-com-chainCronos(CRO)$0.0676971.63%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • MemeCoreMemeCore(M)$1.230.23%
  • BitwayBitway(BTW)$1.0313.56%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • EthenaEthena(ENA)$0.2697700.70%
  • tether-goldTether Gold(XAUT)$4,280.30-0.09%
  • OndoOndo(ONDO)$0.54-0.69%
  • quant-networkQuant(QNT)$176.8676.41%
  • okbOKB(OKB)$121.13-0.58%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • aaveAave(AAVE)$156.350.92%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.00%
  • mantleMantle(MNT)$0.691.40%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

This AI Paper from UC Santa Cruz and the University of Edinburgh Introduces CLIPS: An Enhanced CLIP Framework for Learning with Synthetic Captions

December 9, 2024
in AI & Technology
Reading Time: 5 mins read
A A
This AI Paper from UC Santa Cruz and the University of Edinburgh Introduces CLIPS: An Enhanced CLIP Framework for Learning with Synthetic Captions
ShareShareShareShareShare

Web-crawled image-text datasets are critical for training vision-language models, enabling advancements in tasks such as image captioning and visual question answering.  However, these datasets often suffer from noise and low quality, with inconsistent associations between images and text that limit the capabilities of the models. This limitation prevents achieving strong and accurate results, particularly in cross-modal retrieval tasks. Moreover, the computational costs of handling such large datasets are very prohibitive, making it very important to have a better methodology for training.

To address these limitations, researchers have explored synthetic captions generated by multimodal large language models (MLLMs) as replacements for raw web-crawled captions. Synthetic captions improve models’ performance, such as that demonstrated by VeCLIP and Recap-DataComp-1B. Still, current approaches face significant problems: the computational costs for processing whole captions, the issue of scalability especially with complex architectures, and inefficiency in making use of the entire information in synthetic captions.

YOU MAY ALSO LIKE

Why We Won’t Know How Visible The iPhone Duo’s Crease Is For A Long Time

Your Old GPU Could Be Worth More Than You Think

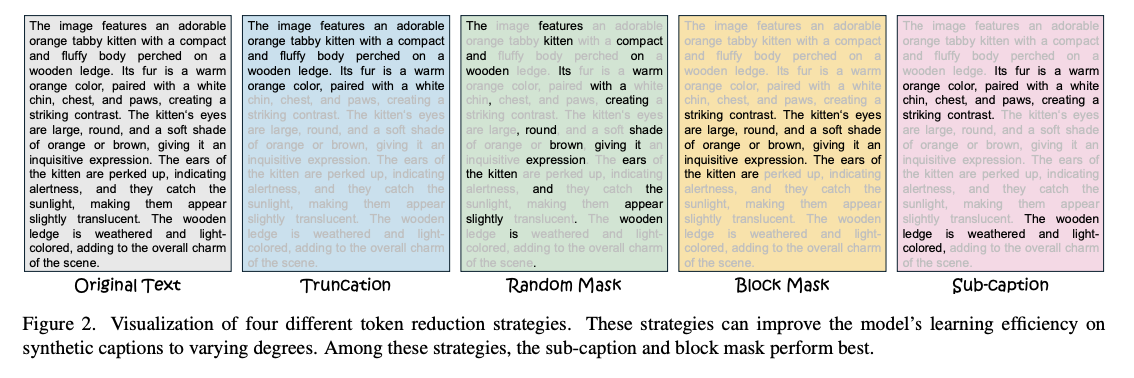
Researchers from UC Santa Cruz and the University of Edinburgh introduce CLIPS, an enhanced vision-language training framework that maximizes the utility of synthetic captions through two innovative designs. It uses a strategy that focuses on partial synthetic captions for contrastive learning. Through the sampling of a part of synthetic captions, CLIPS shortens the input token length while either improving or retaining performance, consistent with principles derived from the inverse scaling law observed during CLIP training. This methodology not only improves retrieval accuracy but also significantly reduces computational costs. In addition, CLIPS incorporates an autoregressive caption generator that generates whole synthetic captions based on web-crawled captions and their corresponding images. This method follows the recaptioning mechanism found in MLLMs and ensures that synthetically captioned content is well utilized, enriching the semantic alignment between image and text.

The technical implementation involves preprocessing synthetic captions using a sub-caption masking strategy, retaining approximately 32 tokens—about one or two sentences—for the text encoder. This approach is coupled with a multi-positive contrastive loss, aligning both original and shortened captions for improved efficiency and effectiveness. In parallel, the generative framework uses an autoregressive decoder that takes web-crawled image attributes and captions as input, guided by a specially designed combination mask to allow for optimal token interaction. The decoder produces outputs that align with complete synthetic captions, and this training is consistent with using a generative loss function. This training is carried out on extensive datasets like DataComp-1B, and evaluations are made against benchmarks like MSCOCO and Flickr30K. Performance metrics include recall at 1 (R@1) for retrieval tasks and zero-shot classification accuracy.
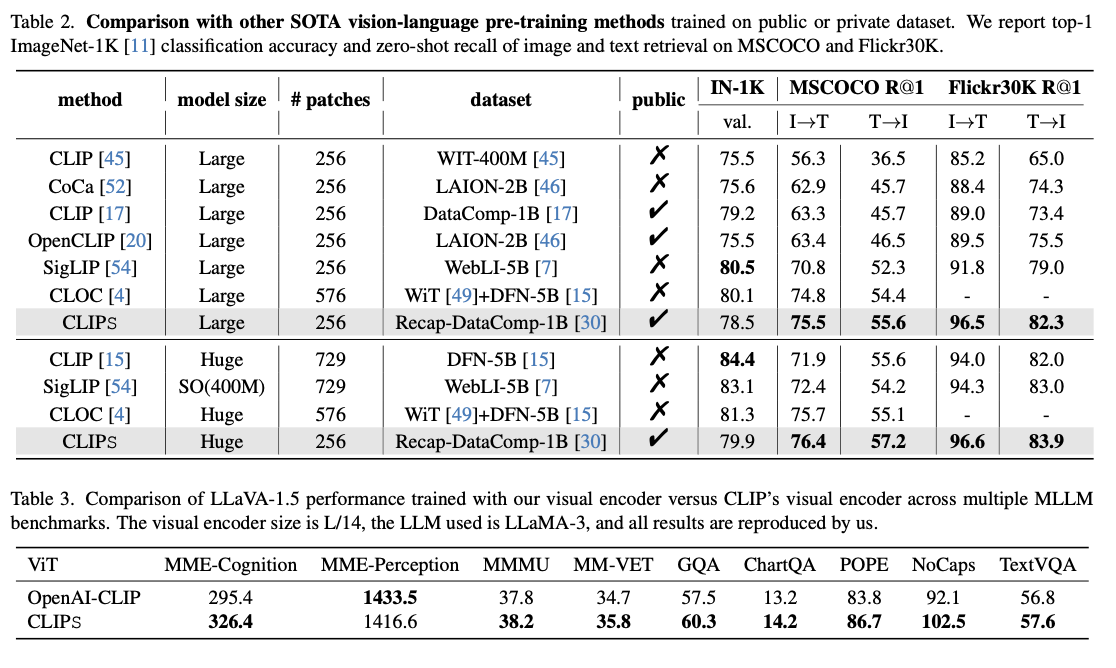
Evaluations show that CLIPS achieves state-of-the-art performance on a range of tasks. For MSCOCO, it achieves an improvement of more than 5% in text-to-image retrieval accuracy and more than 3% in image-to-text retrieval compared to previous approaches. Similarly, on Flickr30K, the model shows better retrieval accuracy in both directions compared to competing frameworks. The effectiveness of this framework is further emphasized by its scalability, where smaller models trained using CLIPS outperform larger models obtained from competing approaches. In addition to retrieval tasks, the incorporation of the CLIPS visual encoder within multimodal large language models markedly improves their efficacy across various benchmarks, highlighting the flexibility and adaptability of this training framework. Moreover, ablation studies provide further corroboration of the generative modeling method’s effectiveness, demonstrating significant improvements in both alignment and retrieval metrics while preserving computational efficiency.
In conclusion, CLIPS transforms vision-language training over the challenges of previous attempts. It establishes new high benchmarks in cross-modal retrieval tasks by using synthetic captions and novel learning methodologies, providing scalability, computational efficacy, and improved multimodal understanding. This framework works as a major step that has been taken in attempting to pursue artificial intelligence through multimodal applications.


Check out the Paper, Code, and Model on Hugging Face. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter.. Don’t Forget to join our 60k+ ML SubReddit.

🚨 [Must Attend Webinar]: ‘Transform proofs-of-concept into production-ready AI applications and agents’ (Promoted)

Aswin AK is a consulting intern at MarkTechPost. He is pursuing his Dual Degree at the Indian Institute of Technology, Kharagpur. He is passionate about data science and machine learning, bringing a strong academic background and hands-on experience in solving real-life cross-domain challenges.

🚨🚨FREE AI WEBINAR: ‘Fast-Track Your LLM Apps with deepset & Haystack'(Promoted)


Credit: Source link

ShareTweetSendSharePin

Related Posts

Why We Won’t Know How Visible The iPhone Duo’s Crease Is For A Long Time
AI & Technology

Why We Won’t Know How Visible The iPhone Duo’s Crease Is For A Long Time

September 27, 2026
Your Old GPU Could Be Worth More Than You Think
AI & Technology

Your Old GPU Could Be Worth More Than You Think

September 26, 2026
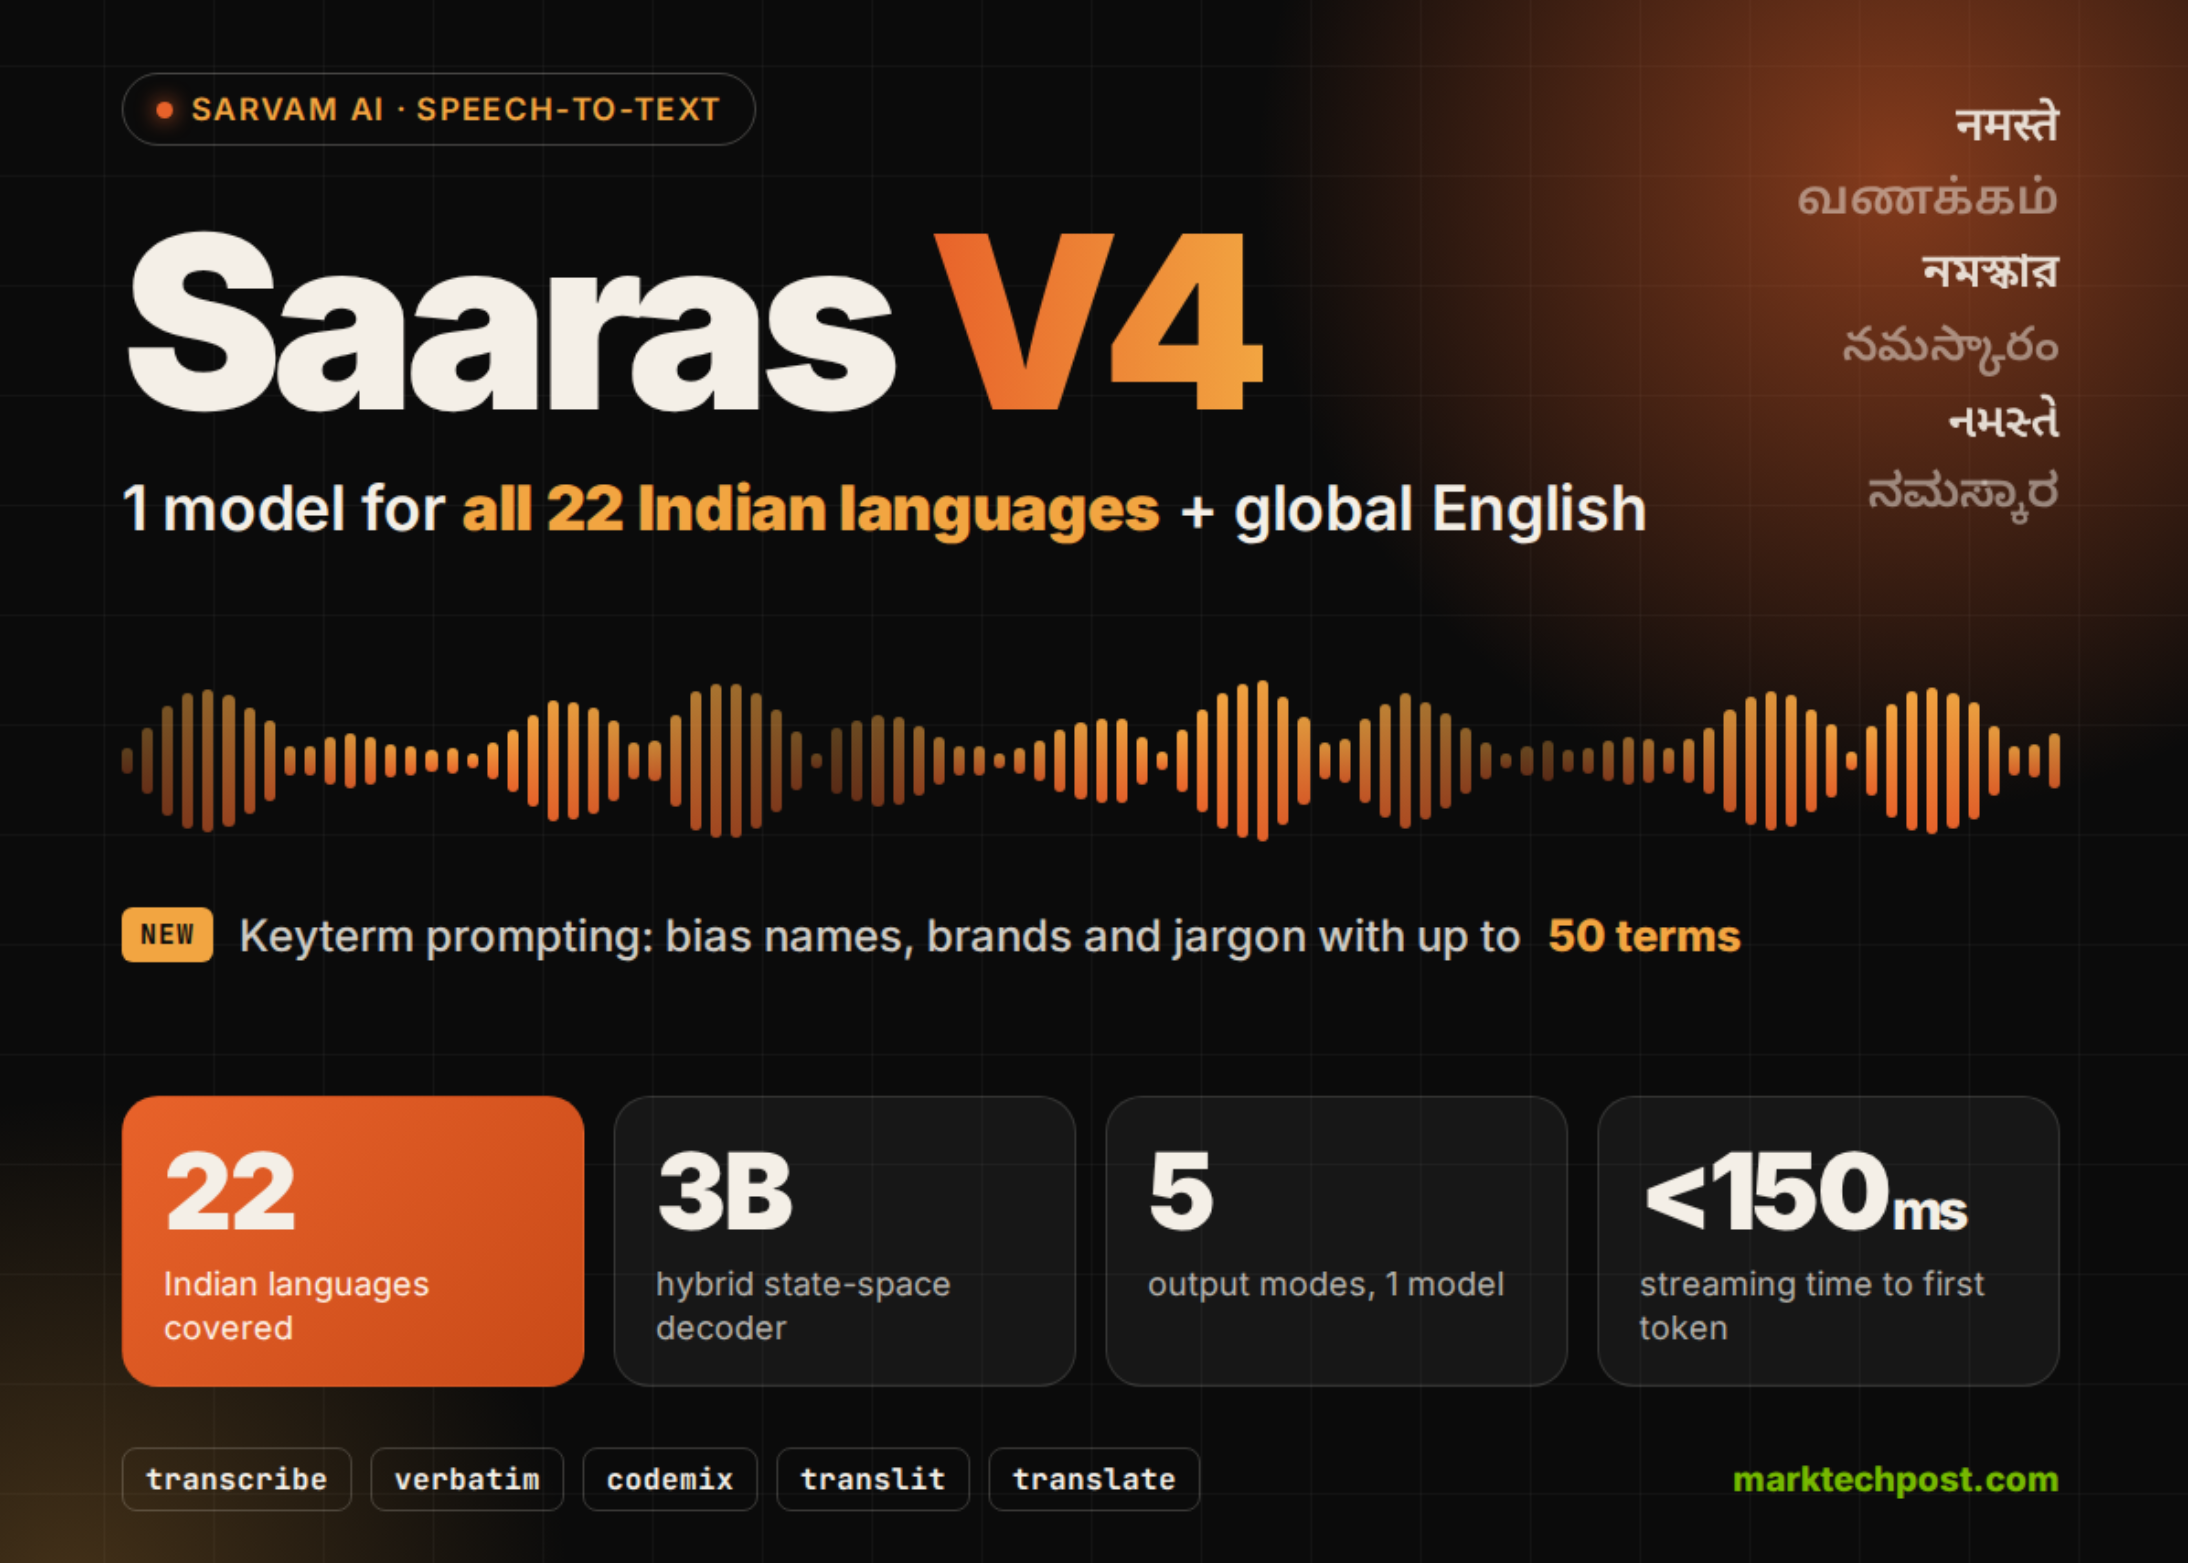
Sarvam AI Releases Saaras V4: A Speech-to-Text Model for All 22 Indian Languages and Global English
AI & Technology

Sarvam AI Releases Saaras V4: A Speech-to-Text Model for All 22 Indian Languages and Global English

September 26, 2026
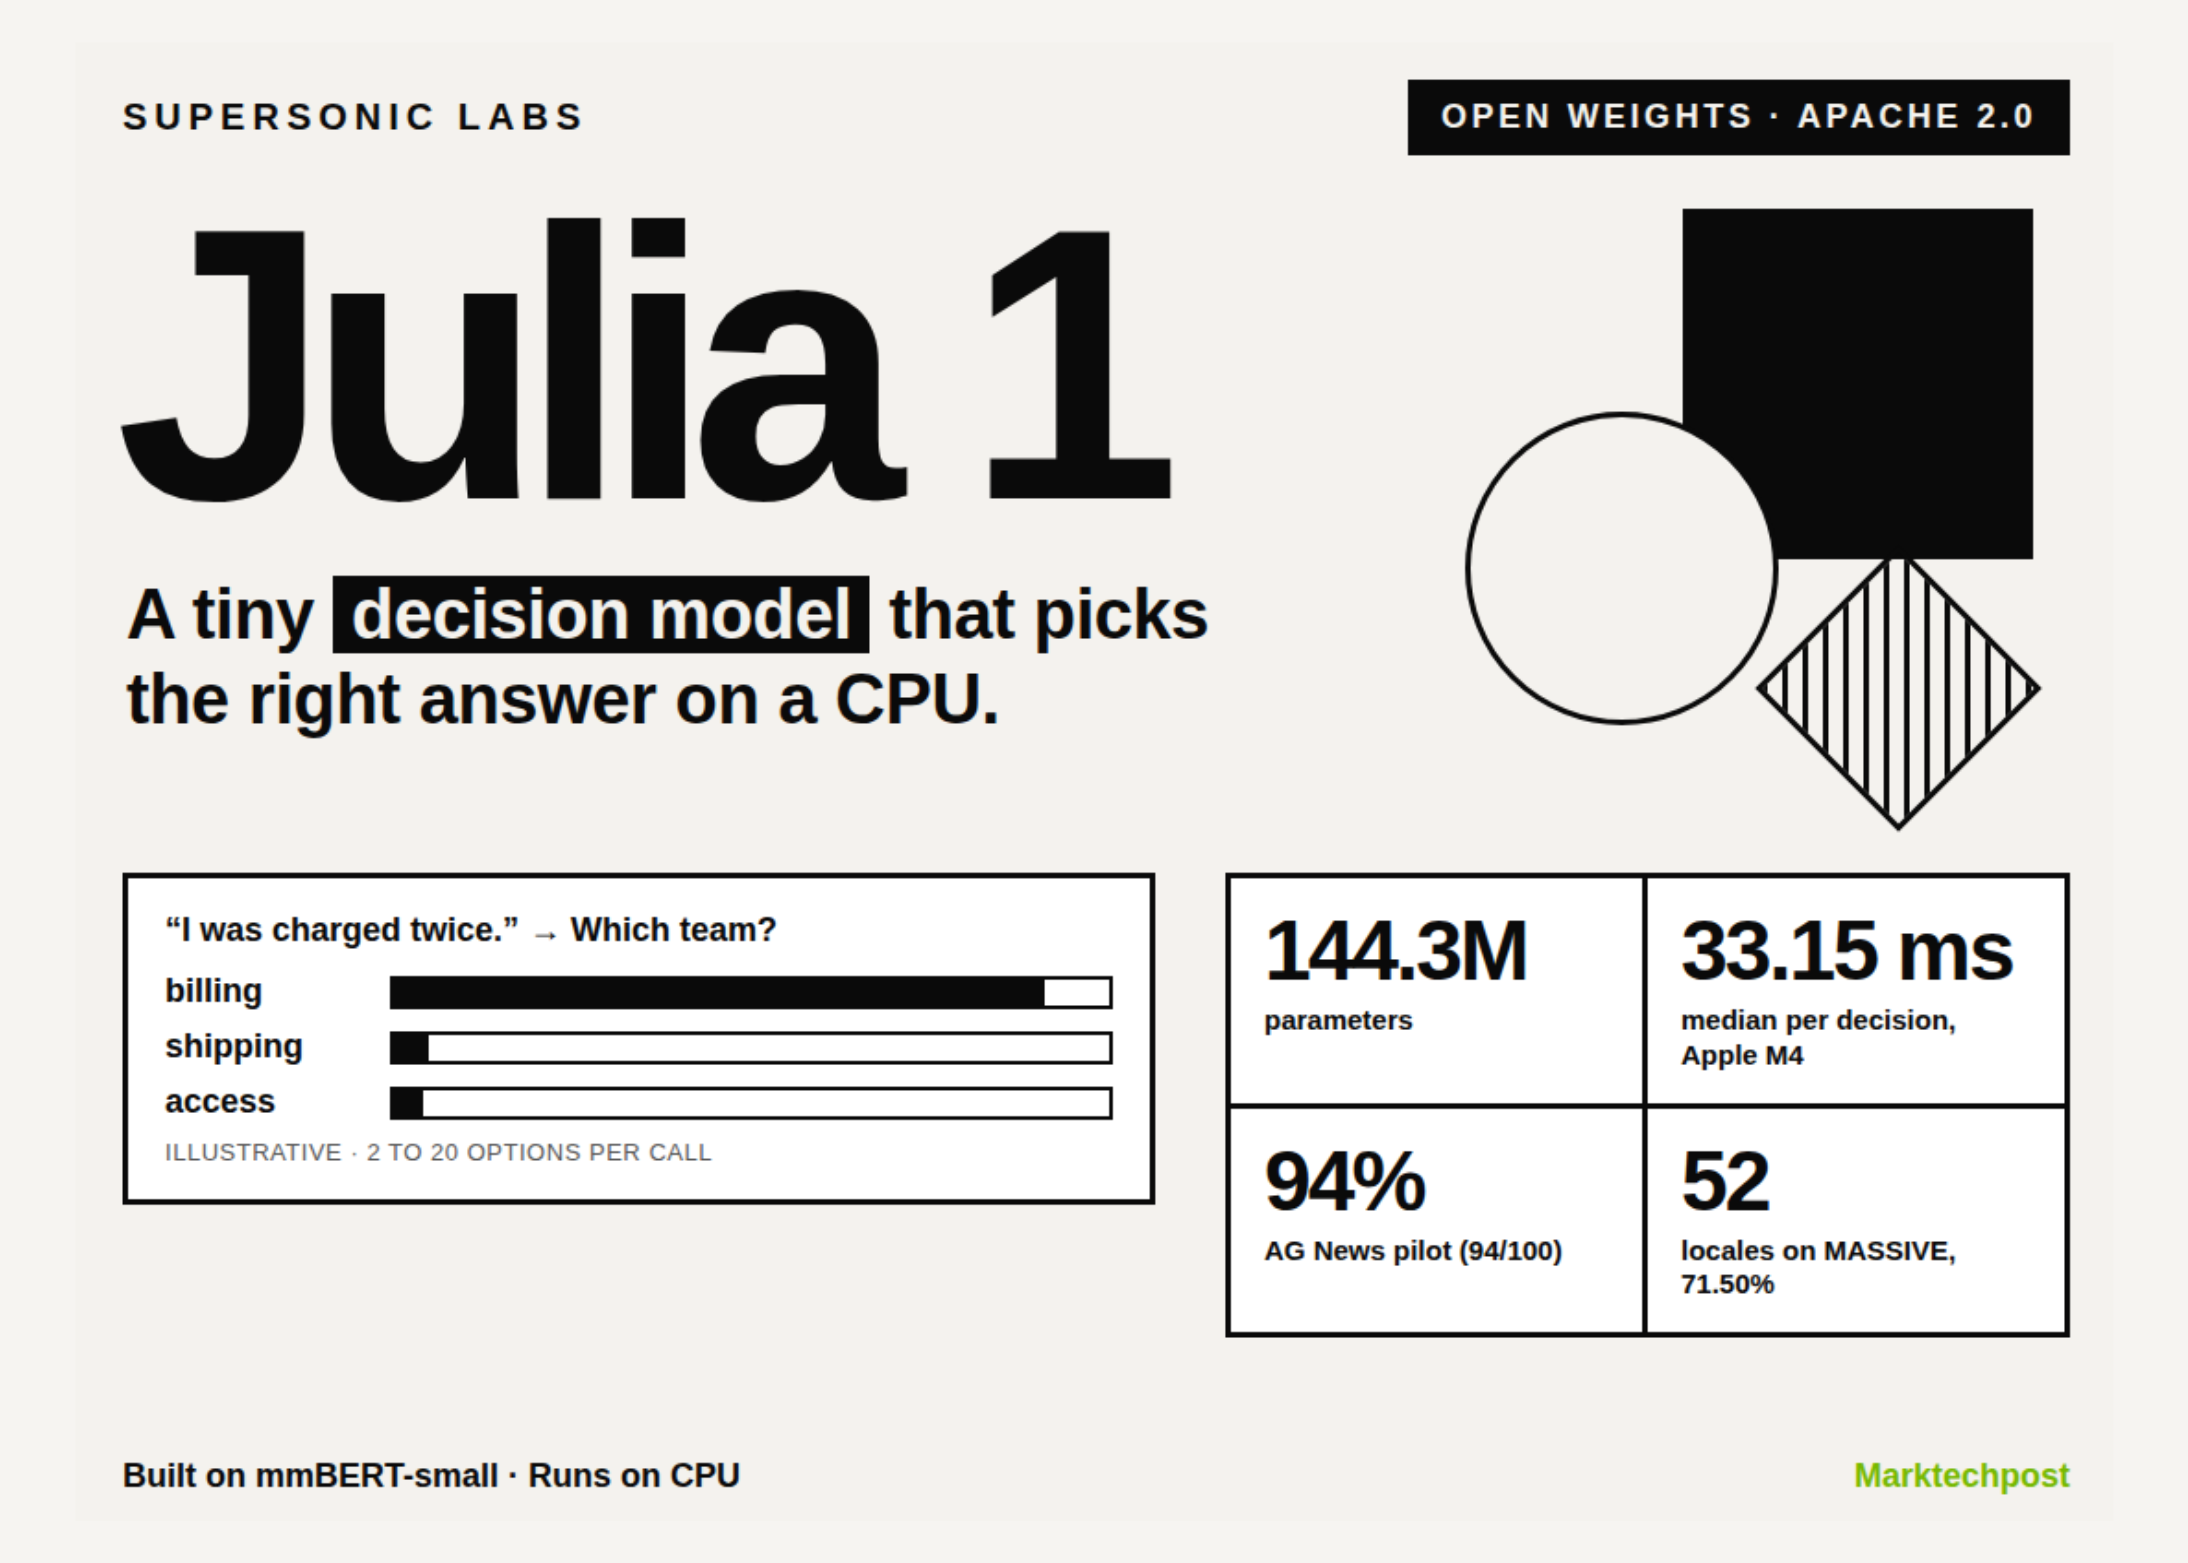
Supersonic Labs Releases Julia 1: A 144.3M-Parameter Open Decision Model That Runs on a CPU
AI & Technology

Supersonic Labs Releases Julia 1: A 144.3M-Parameter Open Decision Model That Runs on a CPU

September 26, 2026
Next Post
Adams admin hires foreign firms to run NYC’s Downtown Heliport, raising security concerns: Not ‘a wise choice’

Adams admin hires foreign firms to run NYC's Downtown Heliport, raising security concerns: Not 'a wise choice'

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
London pays musical tribute to Dolly Parton

London pays musical tribute to Dolly Parton

September 22, 2026
Retroid Pocket Unexpectedly Expands Its Duo Lineup With A Lite Plus Version

Retroid Pocket Unexpectedly Expands Its Duo Lineup With A Lite Plus Version

September 20, 2026
Forensic psychiatrist Dr. Resnick testifies on Clancy’s mental state

Forensic psychiatrist Dr. Resnick testifies on Clancy’s mental state

September 26, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!