• bitcoinBitcoin(BTC)$77,552.000.46%
  • ethereumEthereum(ETH)$2,511.79-0.38%
  • tetherTether(USDT)$1.00-0.02%
  • binancecoinBNB(BNB)$722.96-0.48%
  • rippleXRP(XRP)$1.370.62%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$100.92-0.74%
  • tronTRON(TRX)$0.338635-0.28%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.000.00%
  • zcashZcash(ZEC)$1,124.40-1.43%
  • HyperliquidHyperliquid(HYPE)$80.071.22%
  • dogecoinDogecoin(DOGE)$0.083952-0.97%
  • RainRain(RAIN)$0.015212-3.53%
  • moneroMonero(XMR)$524.59-2.46%
  • USDSUSDS(USDS)$1.00-0.01%
  • whitebitWhiteBIT Coin(WBT)$80.420.25%
  • chainlinkChainlink(LINK)$11.37-0.97%
  • leo-tokenLEO Token(LEO)$9.03-0.41%
  • cardanoCardano(ADA)$0.2069820.14%
  • stellarStellar(XLM)$0.1817131.05%
  • Ethena USDeEthena USDe(USDE)$1.00-0.02%
  • daiDai(DAI)$1.00-0.01%
  • bitcoin-cashBitcoin Cash(BCH)$223.71-0.60%
  • USD1USD1(USD1)$1.00-0.01%
  • litecoinLitecoin(LTC)$54.140.88%
  • uniswapUniswap(UNI)$6.420.63%
  • CantonCanton(CC)$0.096155-1.68%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.35-1.48%
  • hedera-hashgraphHedera(HBAR)$0.0762961.55%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • avalanche-2Avalanche(AVAX)$7.39-0.05%
  • nearNEAR Protocol(NEAR)$2.391.51%
  • shiba-inuShiba Inu(SHIB)$0.000005-0.86%
  • suiSui(SUI)$0.72-0.78%
  • crypto-com-chainCronos(CRO)$0.058190-2.95%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,329.46-0.49%
  • MemeCoreMemeCore(M)$1.16-2.50%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • okbOKB(OKB)$114.270.08%
  • BittensorBittensor(TAO)$236.250.43%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.140.05%
  • BitwayBitway(BTW)$0.7230.87%
  • aaveAave(AAVE)$126.26-0.84%
  • AsterAster(ASTER)$0.700.40%
  • pax-goldPAX Gold(PAXG)$4,333.51-0.51%
  • mantleMantle(MNT)$0.560.77%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0573210.03%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

This AI Paper from Harvard Introduces Q-Probing: A New Frontier in Machine Learning for Adapting Pre-Trained Language Models

March 2, 2024
in AI & Technology
Reading Time: 5 mins read
A A
This AI Paper from Harvard Introduces Q-Probing: A New Frontier in Machine Learning for Adapting Pre-Trained Language Models
ShareShareShareShareShare

The challenge of tailoring general-purpose LLMs to specific tasks without extensive retraining or additional data persists even after significant advancements in the field. Adapting LMs for specialized tasks often requires substantial computational resources and domain-specific data. Traditional methods involve finetuning the entire model on task-specific datasets, which can be computationally expensive and data-intensive, creating a barrier for applications with limited resources or those requiring rapid deployment across various tasks.

Current approaches to model adaptation involve rejection sampling, one of the methods used for reward maximization, but it involves high training and inference costs. Another approach is to use rejection sampling with finetuning or distillation to reduce inference costs. Iterative finetuning is an interesting direction for future work. Prompting is a training-free adaptation method, but finetuning still outperforms prompting methods.

Researchers from Harvard University introduced Q-Probe, which presents a novel method for adapting pre-trained LMs to maximize task-specific rewards efficiently. It employs a simple linear function within the model’s embedding space to reweight candidate completions, aiming for a balance between the depth of finetuning and the simplicity of prompting. This method significantly reduces computational overhead while retaining the model’s adaptability to various tasks.

Q-Probe operates by applying a form of rejection sampling to the LM’s outputs, utilizing a linear probe to assess and prioritize completions based on their projected utility. Reward modeling or direct policy learning objectives based on importance-weighted policy gradients can be used to train the Q-Probes. Q-Probe can be trained on top of an API, as it only requires access to sampling and embeddings. At inference, it is used to generate samples through rejection sampling. It predicts a value for each embedding, determining the logits for a softmax distribution used to sample the chosen completion. The sampling procedure is equivalent to a KL-constrained maximization of the Q-Probe as the number of samples increases. This method has shown gains in domains with ground-truth rewards and implicit rewards defined by preference data, even outperforming finetuning in data-limited regimes.
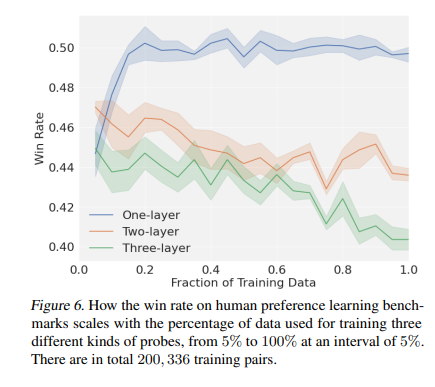
The application of Q-Probe has demonstrated promising results, especially in domains such as code generation, where it has shown potential to surpass traditional finetuning methods in accuracy and efficiency. It outperforms methods like PPO (offline) and DPO while performing on par with KTO when evaluated on human preference data. The process achieves a high “win rate” compared to the winning completion in the data for each prompt, as judged by GPT-4. The win rate increases with the number of samples generated during inference. When the base model is swapped with the KTO-finetuned model, Q-Probe on the KTO-finetuned model outperforms either KTO alone or Q-Probing on the base model. These results show the applicability of the proposed inference-time algorithm with existing finetuning methods.

In summary, Q-Probe represents a significant advancement in the field of LM adaptation, providing an efficient and effective means of tailoring general-purpose models to specific tasks. Bridging the gap between extensive finetuning and simple prompting opens new avenues for applying LMs across a wider range of domains, enhancing their utility and accessibility.


Check out the Paper and Github. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and Google News. Join our 38k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our Telegram Channel

You may also like our FREE AI Courses….

YOU MAY ALSO LIKE

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?

Which Is Better For Charging Your MacBook?

Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in Materials at the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast who is always researching applications in fields like biomaterials and biomedical science. With a strong background in Material Science, he is exploring new advancements and creating opportunities to contribute.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?
AI & Technology

Anthropic’s 3-Step ‘Pace the Frontier’ Plan Wins OpenAI, xAI and Microsoft Support: Is It Too Late to Slow AI Down?

September 14, 2026
Which Is Better For Charging Your MacBook?
AI & Technology

Which Is Better For Charging Your MacBook?

September 14, 2026
At What Length Do Ethernet Cables Drop To Lower Speeds?
AI & Technology

At What Length Do Ethernet Cables Drop To Lower Speeds?

September 14, 2026
Nadella Announces Public Consultation on Microsoft’s MAI Model Rules – Unite.AI
AI & Technology

Nadella Announces Public Consultation on Microsoft’s MAI Model Rules – Unite.AI

September 13, 2026
Next Post
‘Unabomber’ Ted Kaczynski found dead in prison cell at age 81

‘Unabomber’ Ted Kaczynski found dead in prison cell at age 81

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Will We See The Foldable iPhone Ultra At The ‘Surprise And Shine’ Keynote Today?

Will We See The Foldable iPhone Ultra At The ‘Surprise And Shine’ Keynote Today?

September 9, 2026
How To Adjust The Liquid Glass Effect On Your iPhone With iOS 27

How To Adjust The Liquid Glass Effect On Your iPhone With iOS 27

September 13, 2026
KSLV Vs. SLVP: A 26% Yield Hasn't Been Enough

KSLV Vs. SLVP: A 26% Yield Hasn't Been Enough

September 11, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!