• bitcoinBitcoin(BTC)$83,391.00-3.01%
  • ethereumEthereum(ETH)$2,656.68-3.08%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$766.71-2.68%
  • rippleXRP(XRP)$1.47-8.50%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$113.37-3.63%
  • tronTRON(TRX)$0.339807-0.91%
  • zcashZcash(ZEC)$1,487.08-7.58%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.040.37%
  • HyperliquidHyperliquid(HYPE)$91.16-5.17%
  • dogecoinDogecoin(DOGE)$0.092459-7.70%
  • moneroMonero(XMR)$553.03-2.80%
  • whitebitWhiteBIT Coin(WBT)$83.55-3.35%
  • USDSUSDS(USDS)$1.00-0.01%
  • chainlinkChainlink(LINK)$12.21-5.84%
  • cardanoCardano(ADA)$0.235441-7.65%
  • RainRain(RAIN)$0.012079-6.56%
  • leo-tokenLEO Token(LEO)$8.92-0.59%
  • stellarStellar(XLM)$0.198480-8.72%
  • bitcoin-cashBitcoin Cash(BCH)$327.91-7.68%
  • uniswapUniswap(UNI)$8.86-13.39%
  • nearNEAR Protocol(NEAR)$4.15-9.29%
  • litecoinLitecoin(LTC)$67.406.97%
  • Ethena USDeEthena USDe(USDE)$1.00-0.02%
  • daiDai(DAI)$1.000.01%
  • avalanche-2Avalanche(AVAX)$10.09-9.14%
  • USD1USD1(USD1)$1.00-0.01%
  • CantonCanton(CC)$0.107304-5.15%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.41-3.25%
  • hedera-hashgraphHedera(HBAR)$0.089111-8.98%
  • suiSui(SUI)$0.95-7.63%
  • shiba-inuShiba Inu(SHIB)$0.000006-8.39%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • BittensorBittensor(TAO)$284.01-8.57%
  • crypto-com-chainCronos(CRO)$0.060739-9.48%
  • MemeCoreMemeCore(M)$1.22-4.62%
  • BitwayBitway(BTW)$1.015.31%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • tether-goldTether Gold(XAUT)$4,263.62-1.31%
  • okbOKB(OKB)$118.33-4.62%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.02%
  • mantleMantle(MNT)$0.68-0.13%
  • aaveAave(AAVE)$136.25-9.12%
  • OndoOndo(ONDO)$0.425409-2.78%
  • EthenaEthena(ENA)$0.200590-6.29%
  • MorphoMorpho(MORPHO)$2.703.66%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

This AI Paper from China Introduces KV-Cache Optimization Techniques for Efficient Large Language Model Inference

July 28, 2024
in AI & Technology
Reading Time: 4 mins read
A A
This AI Paper from China Introduces KV-Cache Optimization Techniques for Efficient Large Language Model Inference
ShareShareShareShareShare

Large Language Models (LLMs) are a subset of artificial intelligence focusing on understanding and generating human language. These models leverage complex architectures to comprehend and produce human-like text, facilitating applications in customer service, content creation, and beyond.

A major challenge with LLMs is their efficiency when processing long texts. The Transformer architecture they use has a quadratic time complexity, which increases computational load significantly, especially when dealing with extended sequences. This complexity poses a substantial barrier to achieving efficient performance, particularly as the length of text inputs grows. Addressing this challenge is crucial for the continued advancement and application of LLMs in real-world scenarios.

YOU MAY ALSO LIKE

Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model

Researchers have introduced the KV-Cache mechanism to address this issue, which stores keys and values generated by past tokens. This reduces the time complexity from quadratic to linear. However, KV-Cache increases GPU memory usage, which scales with the conversation length, creating a new bottleneck. Current methods aim to balance this trade-off between computational efficiency and memory overhead, making it essential to optimize KV-Cache usage effectively.

The research team from Wuhan University and Shanghai Jiao Tong University introduced several KV-Cache compression methods. These methods optimize KV-Cache space usage across LLMs’ pre-training, deployment, and inference phases, aiming to enhance efficiency without compromising performance. Their approach includes modifying the model architecture during pre-training to reduce the size of the Keys and Values vectors by up to 75%. This adjustment maintains the advantages of the attention mechanism while significantly lowering memory requirements.

The proposed methods include architectural adjustments during pre-training, which reduce the size of generated Keys and Value vectors. During deployment, frameworks like Paged Attention and DistKV-LLM distribute KV-Cache across multiple servers to improve memory management. Post-training methods include dynamic eviction strategies and quantization techniques that compress KV-Cache without significantly losing model capabilities. Specifically, Paged Attention uses a mapping table to store KV-Cache discontinuously in GPU memory, minimizing fragmentation and improving inference speed. DistKV-LLM extends this by enabling distributed deployment across servers and enhancing large-scale cloud service efficiency.
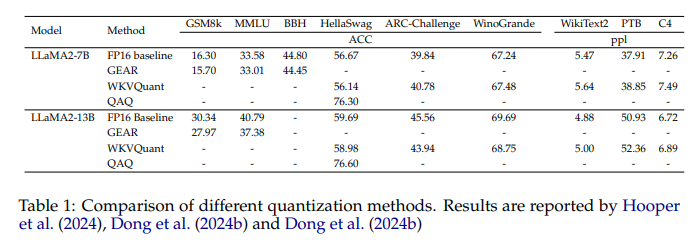
The methods introduced have shown significant improvements in memory efficiency and inference speed. For instance, the GQA method used in popular models like LLaMA2-70B achieves better memory utilization by reducing the KV-Cache size while maintaining performance levels. These optimizations demonstrate the potential to handle longer contexts more effectively. Specifically, GQA reduces memory usage to a fraction of that required by traditional methods, achieving a 75% reduction in KV-Cache size. Furthermore, models using Multi-Query Attention (MQA) and GQA demonstrate improved throughput and reduced latency, crucial metrics for real-time applications. The research indicates that the LLaMA2-70B model’s per-token memory usage drops from 0.5MB to 0.125MB, showcasing a significant enhancement in efficiency.

The research provides comprehensive strategies for optimizing KV-Cache in LLMs, addressing the memory overhead issue. By implementing these methods, LLMs can achieve higher efficiency and better performance, paving the way for more sustainable and scalable AI solutions. The findings from Wuhan University and Shanghai Jiao Tong University offer a roadmap for future advancements, emphasizing the importance of efficient memory management in the evolution of LLM technology. These strategies not only mitigate current limitations but also open avenues for exploring more sophisticated applications of LLMs in various industries.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter..

Don’t Forget to join our 47k+ ML SubReddit

Find Upcoming AI Webinars here

Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in Materials at the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast who is always researching applications in fields like biomaterials and biomedical science. With a strong background in Material Science, he is exploring new advancements and creating opportunities to contribute.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev
AI & Technology

Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev

September 24, 2026
A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model
AI & Technology

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model

September 24, 2026
Everything Announced At Meta Connect 2026
AI & Technology

Everything Announced At Meta Connect 2026

September 24, 2026
Meta Put Muse In A Tamagotchi Like ‘Charm’ Device
AI & Technology

Meta Put Muse In A Tamagotchi Like ‘Charm’ Device

September 24, 2026
Next Post
Is kelp the sustainable food craze of the future?

Is kelp the sustainable food craze of the future?

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Fox News parts ways with longtime host Maria Bartiromo

Fox News parts ways with longtime host Maria Bartiromo

September 18, 2026
Current with Christine Romans – Sept. 3 | NBC News NOW

Current with Christine Romans – Sept. 3 | NBC News NOW

September 18, 2026
WATCH: Day 21 of Lindsay Clancy murder trial | NBC News

WATCH: Day 21 of Lindsay Clancy murder trial | NBC News

September 23, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!