
Tencent AI Lab has released Covo-Audio, a 7B-parameter end-to-end Large Audio Language Model (LALM). The model is designed to unify speech processing and language intelligence by directly processing continuous audio inputs and generating audio outputs within a single architecture.
System Architecture
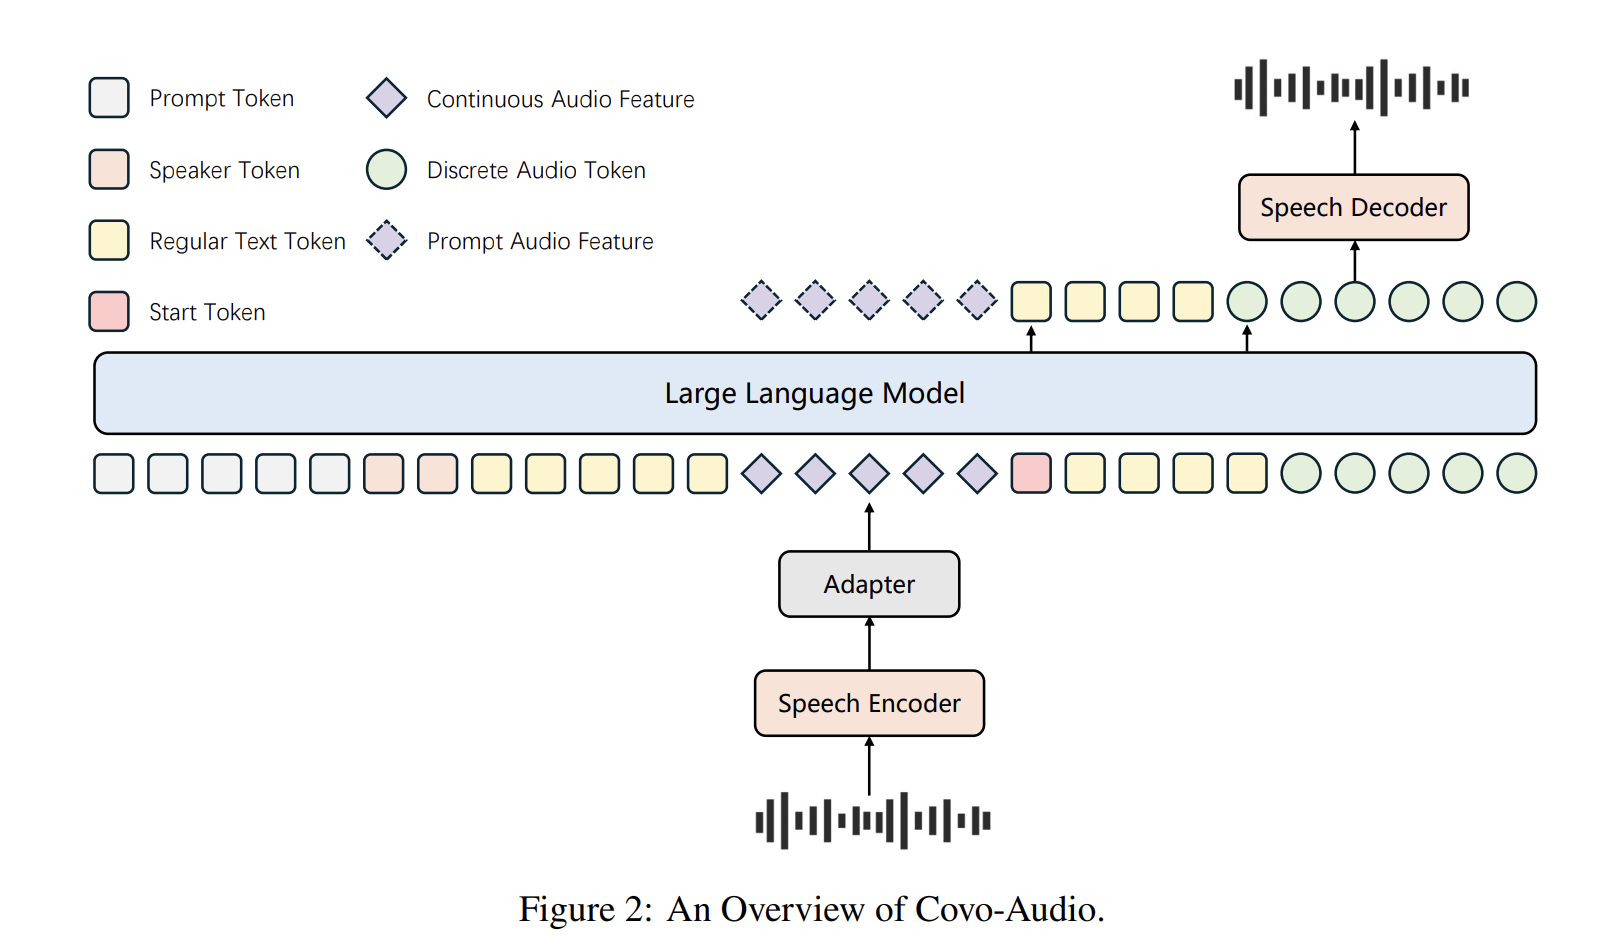
The Covo-Audio framework consists of four primary components designed for seamless cross-modal interaction:
- Audio Encoder: The model utilizes Whisper-large-v3 as its primary encoder due to its robustness against background noise and varied accents. This component operates at a frame rate of 50 Hz.
- Audio Adapter: To bridge the encoder and the LLM, a specialized adapter employs three downsampling modules, integrating linear and convolution layers to reduce the frame rate from 50 Hz to 6.25 Hz.
- LLM Backbone: The system is built upon Qwen2.5-7B-Base, which has been adapted to process interleaved sequences of continuous acoustic features and textual tokens.
- Speech Tokenizer and Decoder: The tokenizer, based on WavLM-large, uses a codebook size of 16,384 to produce discrete audio tokens at 25 Hz. The decoder employs a Flow-Matching (FM) based framework and a BigVGAN vocoder to reconstruct high-fidelity 24K waveforms.
Hierarchical Tri-modal Interleaving
A core contribution of this work is the Hierarchical Tri-modal Speech-Text Interleaving strategy. Unlike traditional methods that operate solely at the word or character level, this framework aligns continuous acoustic features , discrete speech tokens , and natural language text .
The model utilizes two primary patterns:
- Sequential Interleaving : Continuous features, text, and discrete tokens are arranged in a progressive chain.
- Parallel Integration : Continuous features are aligned with a coupled text-discrete unit.
The hierarchical aspect ensures structural coherence by using phrase-level interleaving for fine-grained alignment and sentence-level interleaving to preserve global semantic integrity in long-form utterances. The training process involved a two-stage pre-training pipeline processing a total of 2T tokens.
Intelligence-Speaker Decoupling
To mitigate the high cost of constructing large-scale dialogue data for specific speakers, the research team proposed an Intelligence Speaker Decoupling strategy. This technique separates dialogue intelligence from voice rendering, allowing for flexible voice customization using minimal text-to-speech (TTS) data.
The method reformats high-quality TTS recordings into pseudo-conversations with masked text loss. By excluding the text response portion from the loss calculation, the model preserves its reasoning abilities while inheriting the naturalness of the TTS speaker. This enables personalized interaction without the need for extensive, speaker-specific dialogue datasets.
Full-Duplex Voice Interaction
Covo-Audio evolved into Covo-Audio-Chat-FD, a variant capable of simultaneous dual-stream communication. The audio encoder is reformatted into a chunk-streaming manner, and the user and model streams are chunk-interleaved in a 1:4 ratio. Each chunk represents 0.16s of audio.
The system manages conversational states through specific architectural tokens:
- THINK Token: Indicates a listening-only state while the model waits to respond.
- SHIFT Token: Signifies the transition to the model’s speaking turn.
- BREAK Token: Detects interruption signals (barge-ins), triggering the model to terminate speaking immediately and switch back to listening.
For multi-turn scenarios, the model implements a recursive context-filling strategy, where continuous audio features from user input and generated tokens from previous turns are prefixed as historical context.
Audio Reasoning and Reinforcement Learning
To enhance complex reasoning, the model incorporates Chain-of-Thought (CoT) reasoning and Group Relative Policy Optimization (GRPO). The model is optimized using a verifiable composite reward function:
/* <![CDATA[ */
wp.i18n.setLocaleData( { 'text direction\u0004ltr': [ 'ltr' ] } );
//# sourceURL=wp-i18n-js-after
/* ]]> */
This structure allows the model to optimize for correctness , structured output adherence , logical coherence , and reasoning depth .
Evaluation and Performance
Covo-Audio (7B) shows competitive or superior results on several evaluated benchmarks, with strongest claims made for models of comparable scale and selected speech/audio tasks. On the MMAU benchmark, it achieved an average score of 75.30%, the highest among evaluated 7B-scale models. It notably excelled in music understanding with a score of 76.05%. On the MMSU benchmark, Covo-Audio achieved a leading 66.64% average accuracy.
Regarding its conversational variants, Covo-Audio-Chat demonstrated strong performance on URO-Bench, particularly in speech reasoning and spoken dialogue tasks, outperforming models like Qwen3-Omni on the Chinese track. For empathetic interaction on the VStyle benchmark, it achieved state-of-the-art results in Mandarin for anger (4.89), sadness (4.93), and anxiety (5.00).
The research team notes an ‘early-response’ issue on the GaokaoEval full-duplex setting, where unusually long silent pauses between vocal fragments can cause premature responses. This ‘early-response’ behavior correlates with the model’s pause-handling success metric and is identified as a critical direction for future optimization.
Key Takeaways
- Unified End-to-End Architecture: Covo-Audio is a 7B-parameter model that natively processes continuous audio inputs and generates high-fidelity audio outputs within a single, unified architecture. It eliminates the need for cascaded ASR-LLM-TTS pipelines, reducing error propagation and information loss.
- Hierarchical Tri-modal Interleaving: The model employs a specialized strategy to align continuous acoustic features, discrete speech tokens, and natural language text. By interleaving these modalities at both phrase and sentence levels, it preserves global semantic integrity while capturing fine-grained prosodic nuances.
- Intelligence-Speaker Decoupling: Tencent research team introduces a technique to decouple dialogue intelligence from specific voice rendering. This allows for flexible voice customization using lightweight Text-to-Speech (TTS) data, significantly lowering the cost of developing personalized conversational agents.
- Native Full-Duplex Interaction: The Covo-Audio-Chat-FD variant supports simultaneous listening and speaking. It utilizes specific architectural tokens—THINK, SHIFT, and BREAK—to manage complex real-time dynamics such as smooth turn-taking, backchanneling, and user barge-ins.
- Superior Parameter Efficiency: Despite its compact 7B scale, Covo-Audio achieves state-of-the-art or highly competitive performance across core benchmarks, including MMAU, MMSU, and URO-Bench. It frequently matches or exceeds the performance of much larger systems, such as 32B-parameter models, in audio and speech understanding tasks.
Check out the Paper, Model on HF and Repo. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
The post Tencent AI Open Sources Covo-Audio: A 7B Speech Language Model and Inference Pipeline for Real-Time Audio Conversations and Reasoning appeared first on MarkTechPost.
Credit: Source link