



















• bitcoinBitcoin(BTC)$78,616.00-2.02%
  • ethereumEthereum(ETH)$2,246.44-3.38%
  • tetherTether(USDT)$1.00-0.03%
  • binancecoinBNB(BNB)$716.89-5.13%
  • rippleXRP(XRP)$1.26-3.19%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$98.19-2.26%
  • tronTRON(TRX)$0.3398202.67%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.03%
  • HyperliquidHyperliquid(HYPE)$93.2017.47%
  • zcashZcash(ZEC)$1,270.801.49%
  • dogecoinDogecoin(DOGE)$0.076296-3.07%
  • moneroMonero(XMR)$591.020.16%
  • USDSUSDS(USDS)$1.00-0.14%
  • whitebitWhiteBIT Coin(WBT)$75.18-2.38%
  • leo-tokenLEO Token(LEO)$9.43-0.30%
  • chainlinkChainlink(LINK)$11.13-3.63%
  • cardanoCardano(ADA)$0.194418-2.87%
  • stellarStellar(XLM)$0.167571-1.24%
  • bitcoin-cashBitcoin Cash(BCH)$284.601.06%
  • nearNEAR Protocol(NEAR)$4.25-5.40%
  • RainRain(RAIN)$0.0066014.20%
  • daiDai(DAI)$1.000.02%
  • Ethena USDeEthena USDe(USDE)$1.00-0.19%
  • litecoinLitecoin(LTC)$56.25-2.83%
  • uniswapUniswap(UNI)$6.82-4.19%
  • USD1USD1(USD1)$1.00-0.08%
  • avalanche-2Avalanche(AVAX)$8.61-1.89%
  • CantonCanton(CC)$0.095339-1.50%
  • suiSui(SUI)$0.90-2.26%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.18-3.82%
  • tether-goldTether Gold(XAUT)$3,999.27-0.68%
  • hedera-hashgraphHedera(HBAR)$0.071381-3.94%
  • Global DollarGlobal Dollar(USDG)$1.000.04%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.10%
  • quant-networkQuant(QNT)$192.74-1.48%
  • BittensorBittensor(TAO)$238.48-4.79%
  • shiba-inuShiba Inu(SHIB)$0.000005-3.88%
  • Ripple USDRipple USD(RLUSD)$1.00-0.03%
  • crypto-com-chainCronos(CRO)$0.051304-3.43%
  • EthenaEthena(ENA)$0.188177-5.63%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.12%
  • okbOKB(OKB)$112.931.78%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • MemeCoreMemeCore(M)$1.02-1.12%
  • BitwayBitway(BTW)$1.48-17.63%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • pepePepe(PEPE)$0.000005-1.43%
  • aaveAave(AAVE)$126.55-3.83%
  • OndoOndo(ONDO)$0.394092-4.37%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Seeing and Hearing: Bridging Visual and Audio Worlds with AI

March 13, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Seeing and Hearing: Bridging Visual and Audio Worlds with AI
ShareShareShareShareShare

The pursuit of generating lifelike images, videos, and sounds through artificial intelligence (AI) has recently taken a significant leap forward. However, these advancements have predominantly focused on single modalities, ignoring our world’s inherently multimodal nature. Addressing this shortfall, researchers have introduced a pioneering optimization-based framework designed to integrate visual and audio content creation seamlessly. This innovative approach utilizes existing pre-trained models, notably the ImageBind model, to establish a shared representational space that facilitates the generation of content that is both visually and aurally cohesive.

The challenge of synchronizing video and audio generation presents a unique set of complexities. Traditional methods, which often involve generating video and audio in separate stages, fall short in delivering the desired quality and control. Recognizing the limitations of such two-stage processes, researchers have explored the potential of leveraging powerful, pre-existing models that excel in individual modalities. A key discovery was the ImageBind model’s ability to link different data types within a unified semantic space, thus serving as an effective “aligner” in the content generation process.

At the core of this method is the use of diffusion models, which generate content by progressively reducing noise. The proposed system employs ImageBind as a kind of referee, providing feedback on the alignment between the partially generated image and its corresponding audio. This feedback is then used to fine-tune the generation process, ensuring a harmonious audio-visual match. The approach is akin to classifier guidance in diffusion models but applied across modalities to maintain semantic coherence.

The researchers further refined their system to tackle challenges such as the semantic sparsity of audio content (e.g., background music) by incorporating textual descriptions for richer guidance. Additionally, a novel “guided prompt tuning” technique was developed to enhance content generation, particularly for audio-driven video creation. This method allows for dynamic adjustment of the generation process based on textual prompts, ensuring a higher degree of content alignment and fidelity.
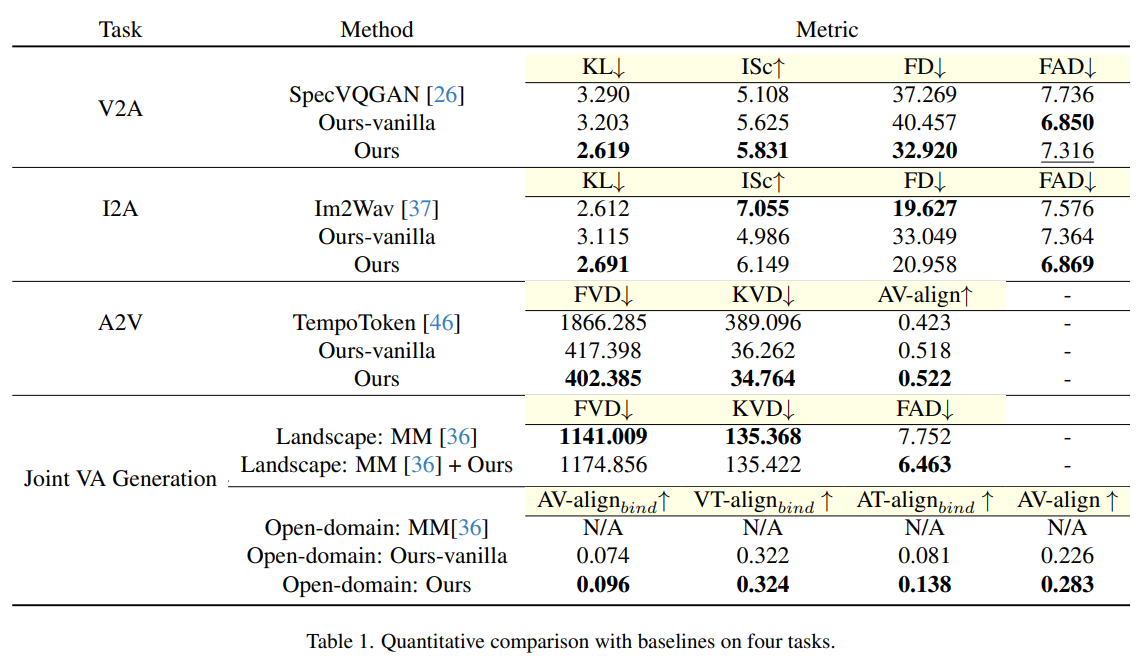
To validate their approach, the researchers conducted a comprehensive comparison against several baselines across different generation tasks. For video-to-audio generation, they selected SpecVQGAN as a baseline, while for image-to-audio tasks, Im2Wav served as the comparison point. TempoTokens was chosen for the audio-to-video generation task. Additionally, MM-Diffusion, a state-of-the-art model for joint video and audio generation in a limited domain, was used as a baseline for evaluating the proposed method in open-domain tasks. These rigorous comparisons revealed that the proposed method consistently outperformed existing models, demonstrating its effectiveness and flexibility in bridging visual and auditory content generation.

This research offers a versatile, resource-efficient pathway for integrating visual and auditory content generation, setting a new benchmark for AI-driven multimedia creation. The ability to harness pre-existing models for this purpose hints at the potential for future advancements, where improvements in foundational models could lead to even more compelling and cohesive multimedia experiences.

Despite its impressive capabilities, the researchers acknowledge limitations primarily stemming from the generation capacity of the foundational models, such as AudioLDM and AnimateDiff. The current performance in aspects like visual quality, complex concept composition, and motion dynamics in audio-to-video and joint video-audio tasks suggests room for future enhancements. However, the adaptability of their approach indicates that integrating more advanced generative models could further refine and improve the quality of multimodal content creation, offering a promising outlook for the future.


Check out the Paper and Project. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and Google News. Join our 38k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our Telegram Channel

You may also like our FREE AI Courses….

YOU MAY ALSO LIKE

Microsoft Offers Buyouts to 60,000 Employees

Meta Looks to Raise $95 Billion From Stock Sale to Fund AI Investments

Vineet Kumar is a consulting intern at MarktechPost. He is currently pursuing his BS from the Indian Institute of Technology(IIT), Kanpur. He is a Machine Learning enthusiast. He is passionate about research and the latest advancements in Deep Learning, Computer Vision, and related fields.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Microsoft Offers Buyouts to 60,000 Employees
AI & Technology

Microsoft Offers Buyouts to 60,000 Employees

October 30, 2026
Meta Looks to Raise  Billion From Stock Sale to Fund AI Investments
AI & Technology

Meta Looks to Raise $95 Billion From Stock Sale to Fund AI Investments

October 30, 2026
Anthropic to Deliver Menlo’s Biggest-Ever Return
AI & Technology

Anthropic to Deliver Menlo’s Biggest-Ever Return

October 30, 2026
Anthropic’s S-1 Reveals Financial War Chest
AI & Technology

Anthropic’s S-1 Reveals Financial War Chest

October 29, 2026
Next Post
Minneapolis community marks third anniversary of George Floyd’s death

Minneapolis community marks third anniversary of George Floyd's death

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
USS Abraham Lincoln sailors reunite with loved ones after nearly a year away

USS Abraham Lincoln sailors reunite with loved ones after nearly a year away

October 29, 2026
Live updates: Police and protesters clash in France as water cannon deployed in Paris – CNN

Live updates: Police and protesters clash in France as water cannon deployed in Paris – CNN

October 24, 2026
‘Shameful’: Alex Pretti’s parents accuse Trump officials of shielding son’s killers – The Guardian

‘Shameful’: Alex Pretti’s parents accuse Trump officials of shielding son’s killers – The Guardian

October 27, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!




