
• bitcoinBitcoin(BTC)$71,623.00-3.74%
  • ethereumEthereum(ETH)$2,015.86-3.03%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$655.28-4.50%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • rippleXRP(XRP)$1.03-2.58%
  • solanaSolana(SOL)$81.57-3.88%
  • tronTRON(TRX)$0.315532-0.39%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.01-3.12%
  • HyperliquidHyperliquid(HYPE)$71.59-2.34%
  • zcashZcash(ZEC)$955.54-4.69%
  • dogecoinDogecoin(DOGE)$0.066011-3.70%
  • moneroMonero(XMR)$541.67-8.23%
  • USDSUSDS(USDS)$1.00-0.01%
  • leo-tokenLEO Token(LEO)$9.17-0.35%
  • whitebitWhiteBIT Coin(WBT)$69.23-3.52%
  • chainlinkChainlink(LINK)$10.05-4.07%
  • cardanoCardano(ADA)$0.172115-3.01%
  • stellarStellar(XLM)$0.147620-1.18%
  • Ethena USDeEthena USDe(USDE)$1.00-0.03%
  • bitcoin-cashBitcoin Cash(BCH)$225.81-2.72%
  • nearNEAR Protocol(NEAR)$3.43-7.96%
  • daiDai(DAI)$1.000.01%
  • litecoinLitecoin(LTC)$49.98-2.05%
  • avalanche-2Avalanche(AVAX)$8.32-3.24%
  • uniswapUniswap(UNI)$6.04-8.13%
  • CantonCanton(CC)$0.089182-3.80%
  • suiSui(SUI)$0.80-3.92%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.14-5.48%
  • USD1USD1(USD1)$1.000.01%
  • tether-goldTether Gold(XAUT)$3,877.76-2.51%
  • hedera-hashgraphHedera(HBAR)$0.063739-4.11%
  • RainRain(RAIN)$0.003800-0.01%
  • Ripple USDRipple USD(RLUSD)$1.00-0.02%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • paypal-usdPayPal USD(PYUSD)$1.000.01%
  • shiba-inuShiba Inu(SHIB)$0.000004-2.76%
  • BittensorBittensor(TAO)$209.58-5.28%
  • crypto-com-chainCronos(CRO)$0.047562-1.06%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.01%
  • quant-networkQuant(QNT)$162.08-9.52%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • okbOKB(OKB)$96.92-1.57%
  • Spiko Amundi Overnight Swap Fund (EUR)Spiko Amundi Overnight Swap Fund (EUR)(EURSAFO)$1.12-0.33%
  • EthenaEthena(ENA)$0.139956-7.40%
  • pepePepe(PEPE)$0.000004-6.85%
  • MemeCoreMemeCore(M)$0.823.34%
  • Falcon USDFalcon USD(USDF)$0.990.05%
  • aaveAave(AAVE)$113.41-8.19%
  • pax-goldPAX Gold(PAXG)$3,880.95-2.47%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Scale AI Launches Singapore Legal Reasoning Benchmark with IMDA – Unite.AI

November 12, 2026
in AI & Technology
Reading Time: 3 mins read
A A
Scale AI Launches Singapore Legal Reasoning Benchmark with IMDA – Unite.AI
ShareShareShareShareShare

Scale AI and Singapore’s Infocomm Media Development Authority (IMDA) introduced SG-LegalClarify on November 12, 2026, testing 19 language models on 1,860 scenarios across 10 domains of Singapore law. The benchmark examines both legal accuracy and whether models ask for missing facts before answering.

YOU MAY ALSO LIKE

Ex-NVIDIA CEO Jensen Huang Is Set To Testify Before Congress This Month

Jensen Huang Expected to Testify to House Committees Within a Week – Unite.AI

Scale describes SG-LegalClarify as the first research initiative under a collaboration formalized in April 2026 and publicly described on July 7, 2026. The project is intended to help governments assess AI systems against their own laws and institutions, rather than assume that results on international benchmarks transfer to every national setting.

The research paper presents Singapore as a demanding test because inherited English common law operates alongside local modifications and Singapore-specific statutes. A model relying on generic common-law reasoning can therefore miss the governing local rule. SG-LegalClarify also tests a separate skill: deciding whether a query contains enough legally material information to answer at all.

That distinction matters in ordinary queries. A driver asking about a speeding penalty may need to supply the vehicle type, actual speed and existing demerit points. An assistant that gives a penalty without those details can produce an authoritative-sounding but legally incorrect answer.

Paired Questions Test When Models Ask

The dataset begins with 1,100 English-language source questions: 340 fully specified and 760 underspecified. Each underspecified question has a fully specified counterpart containing its hidden facts. Twenty-three verified lawyers authored the questions, with seven also serving as reviewers. Their legal experience ranged from two to 37 years, with a median of six.

Each question has a lawyer-written rubric covering issue identification, rule recall, application and conclusion, with 12,546 criteria across the dataset. Of those criteria, 89.0% are mandatory for a substantively correct answer; the headline results count only mandatory items.

A sufficiency gate first makes each model choose between answering directly and gathering facts. On the fact-gathering path, a simulated user reveals hidden facts only when the model explicitly requests them. A three-model AI judge panel, selected through comparisons with human lawyer assessments, grades each criterion by majority vote.

Search Improved Scores but Clarification Remained Weak

The paper reports that Claude Fable 5 led closed-book testing by satisfying 69.8% of mandatory criteria, against an average of 53.8%. With web search, Kimi K3 led at 77.8% and the average rose to 63.0%; every model improved, although the gains varied. Rule recall was the weakest grading component, with pass rates of 43.2% without search and 56.5% with it.

Scale’s summary reports that approximately 39% of closed-book scenarios with missing facts received no clarifying question, while models asked unnecessary questions in approximately 28% of scenarios that already contained enough information. When facts were missing, models asked about an average of only 39% of the relevant facts identified by legal experts.

In a descriptive comparison of web-enabled trials where models requested every relevant missing fact, the paper reports that 55.6% reached the correct legal conclusion, 32.1% reached an incorrect conclusion and 12.3% provided no conclusion. Complete information gathering therefore did not ensure correct application of the law.

Evaluation Limits and Release Plans

The authors identify several limits to the results: human validation of the AI helpers was limited, provider differences prevented identical search-tool access, and upfront routing may have altered clarification behavior. Not every annotated missing variable is necessary to resolve an instance, so incomplete fact-request coverage does not automatically indicate inadequate clarification.

The researchers plan to release 50% of the source questions in each category while retaining the rest for private evaluation, keeping every underspecified–fully specified pair in the same split. Model outputs on the public split and the evaluation pipeline are also planned releases.

The paper’s ethics statement says the scores should not be interpreted as evidence that a model is safe for unsupervised legal advice. For governments evaluating legal AI, the findings make clarification part of the accuracy question: a system must recognize which facts local law makes material, then apply that law correctly after obtaining them.

Credit: Source link

ShareTweetSendSharePin

Related Posts

Ex-NVIDIA CEO Jensen Huang Is Set To Testify Before Congress This Month
AI & Technology

Ex-NVIDIA CEO Jensen Huang Is Set To Testify Before Congress This Month

November 12, 2026
Jensen Huang Expected to Testify to House Committees Within a Week – Unite.AI
AI & Technology

Jensen Huang Expected to Testify to House Committees Within a Week – Unite.AI

November 12, 2026
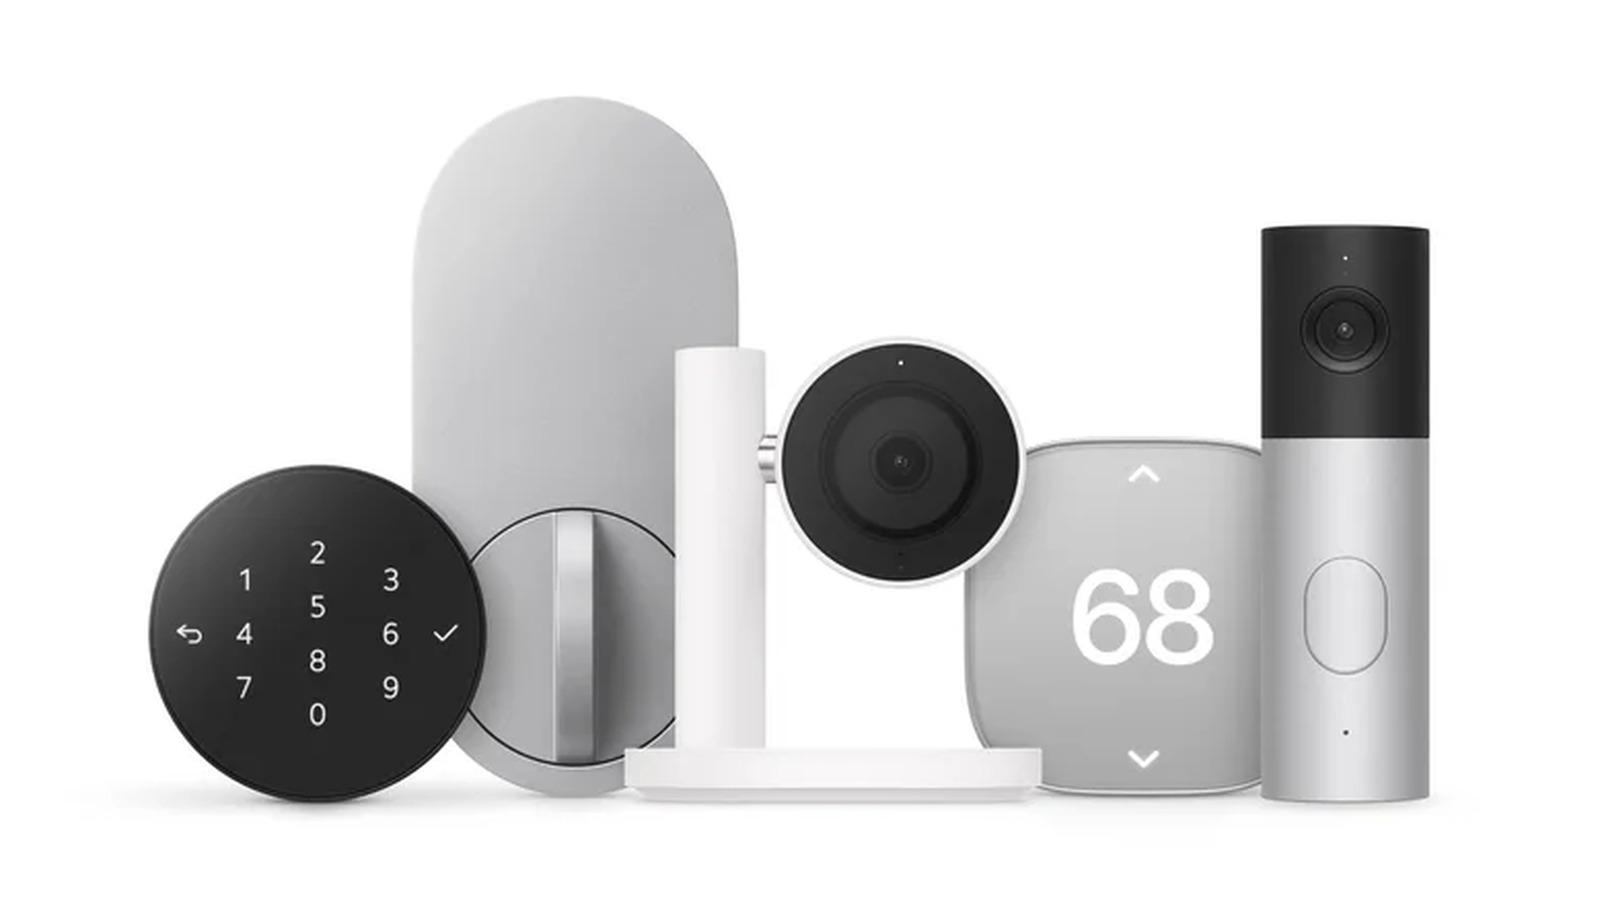
Pre-Orders For Some Apple Home Collection Devices Will Open November 13
AI & Technology

Pre-Orders For Some Apple Home Collection Devices Will Open November 13

November 12, 2026
Definity Plans In-Workflow AI Help for Vyne Brokers With ProNavigator – Unite.AI
AI & Technology

Definity Plans In-Workflow AI Help for Vyne Brokers With ProNavigator – Unite.AI

November 12, 2026
Next Post
Trump says more military action “still possible” as the Iran War continues

Trump says more military action “still possible” as the Iran War continues

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Trump names Stephen Miller as new Chief of Staff

Trump names Stephen Miller as new Chief of Staff

November 8, 2026
Nebuly Raises M Series A to Expand Enterprise AI Measurement – Unite.AI

Nebuly Raises $21M Series A to Expand Enterprise AI Measurement – Unite.AI

November 12, 2026
El-Sayed calls out GOP leadership during victory speech

El-Sayed calls out GOP leadership during victory speech

November 10, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!