• bitcoinBitcoin(BTC)$75,675.00-6.14%
  • ethereumEthereum(ETH)$2,243.96-7.71%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$689.52-3.99%
  • rippleXRP(XRP)$1.23-6.33%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$88.84-7.38%
  • tronTRON(TRX)$0.316787-0.98%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.051.61%
  • zcashZcash(ZEC)$1,239.37-5.12%
  • HyperliquidHyperliquid(HYPE)$77.62-8.54%
  • moneroMonero(XMR)$611.89-2.76%
  • dogecoinDogecoin(DOGE)$0.071159-7.54%
  • USDSUSDS(USDS)$1.000.00%
  • whitebitWhiteBIT Coin(WBT)$72.93-6.61%
  • leo-tokenLEO Token(LEO)$9.330.06%
  • chainlinkChainlink(LINK)$10.63-8.21%
  • cardanoCardano(ADA)$0.180633-8.36%
  • bitcoin-cashBitcoin Cash(BCH)$272.09-3.94%
  • stellarStellar(XLM)$0.151764-9.60%
  • nearNEAR Protocol(NEAR)$3.67-11.17%
  • daiDai(DAI)$1.000.02%
  • Ethena USDeEthena USDe(USDE)$1.00-0.03%
  • RainRain(RAIN)$0.006068-2.43%
  • uniswapUniswap(UNI)$6.83-11.10%
  • litecoinLitecoin(LTC)$51.34-8.73%
  • CantonCanton(CC)$0.095290-2.76%
  • USD1USD1(USD1)$1.00-0.06%
  • avalanche-2Avalanche(AVAX)$8.18-7.64%
  • suiSui(SUI)$0.84-10.48%
  • tether-goldTether Gold(XAUT)$4,080.460.71%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.11-6.66%
  • hedera-hashgraphHedera(HBAR)$0.066932-7.66%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • quant-networkQuant(QNT)$188.38-8.72%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.000004-5.56%
  • Ripple USDRipple USD(RLUSD)$1.000.03%
  • BittensorBittensor(TAO)$215.98-8.89%
  • crypto-com-chainCronos(CRO)$0.048377-6.94%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.03%
  • okbOKB(OKB)$105.55-5.16%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • EthenaEthena(ENA)$0.160362-12.94%
  • pepePepe(PEPE)$0.000005-6.04%
  • aaveAave(AAVE)$126.31-4.90%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Spiko Amundi Overnight Swap Fund (EUR)Spiko Amundi Overnight Swap Fund (EUR)(EURSAFO)$1.140.05%
  • MemeCoreMemeCore(M)$0.82-2.95%
  • pax-goldPAX Gold(PAXG)$4,089.370.64%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Researchers from ETH Zurich and UC Berkeley Introduce MaxInfoRL: A New Reinforcement Learning Framework for Balancing Intrinsic and Extrinsic Exploration

December 22, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Researchers from ETH Zurich and UC Berkeley Introduce MaxInfoRL: A New Reinforcement Learning Framework for Balancing Intrinsic and Extrinsic Exploration
ShareShareShareShareShare

Reinforcement Learning, despite its popularity in a variety of fields, faces some fundamental difficulties that refrain users from exploiting its full potential. To begin with, algorithms like PPO, which are widely used, suffer from the curse of sample inefficiency (the need for multiple episodes to learn basic actions). Moving on, Off-Policy methods like SAC and DrQ offer some immunity against the above problem. They are applicable in the real world while being compute-efficient, but they have drawbacks. Off-policy methods often require dense reward signals, which means their performance is undermined in rewards’ sparsity or local optima. This suboptimality can be attributed to naive exploration schemes such as ε-greedy and Boltzmann exploration. The scalability and simplicity of these algorithms are appealing enough for users to accept the trade-off with optimality.

Intrinsic exploration has recently shown great potential in this regard, where reward signals such as information gain and curiosity improve the exploration of RL agents. Approaches to maximizing information gain show great theoretical potential and have even achieved empirical state-of-the-art (SOTA). While this approach appears promising in theory, a gap exists in balancing intrinsic and naive extrinsic exploration objectives. This article discusses the latest research that claims to find a balance between intrinsic and extrinsic exploration in practice.

YOU MAY ALSO LIKE

Google Plans Its First Wyoming Data Center with Carbon-Capture Power – Unite.AI

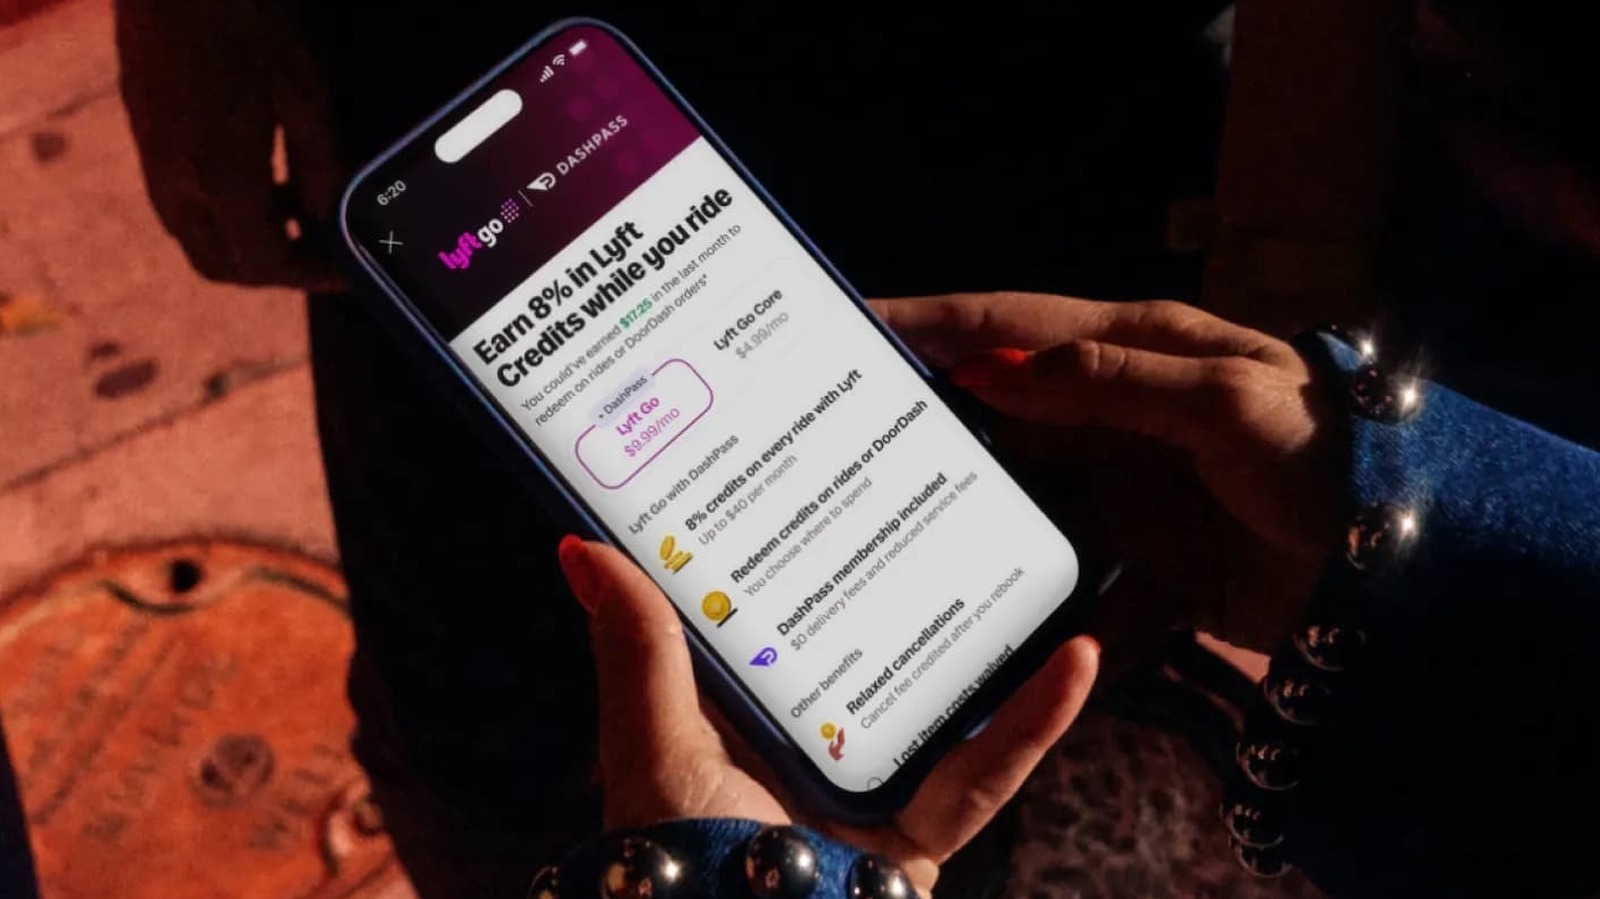
Lyft’s New Subscription Bundles In DoorDash’s DashPass For $10 Per Month

Researchers from ETH Zurich and UC Berkeley have put forth MAXINFORL, which improves the naive old exploration techniques and aligns them theoretically and practically with intrinsic rewards. MAXINFORL is a novel class of Off-policy model-free algorithms for continuous state-action spaces that augment existing RL methods with directed exploration. It takes the standard Boltzmann exploration technique and enhances it through an intrinsic reward. The authors propose a practical auto-tuning procedure simplifying the trade-off between exploration and rewards. Thus, the algorithms modified by MAXINFORL explore by visiting trajectories that achieve the maximum information gain while efficiently solving the task. The authors also show that the proposed algorithms benefit from all theoretical properties of contraction and convergence that hold for other max-entropy RL algorithms, such as SAC.

Let us jog down memory lane and review intrinsic rewards, precisely information gains, to get the fundamentals right. They enable RL agents to acquire information in a more principled manner by directing agents toward underexplored regions. In MAXINFORL, the authors use intrinsic rewards to guide exploration such that, instead of random sampling, the exploration is informed to cover the state-action spaces efficiently. For this, the authors modify ε-greedy selection to learn Optimal Q for extrinsic and intrinsic rewards, determining the action to be taken. Thus, ε–MAXINFORL augments the Boltzmann Exploration strategy. However, the augmented policy presents a trade-off between value function maximization and the entropy of states, rewards, and actions. MAXINFORL introduces two exploration bonuses in this augmentation: policy entropy and information gain. Additionally, in this strategy, the Q-function and policy update rules converge to an optimal policy.

The research team evaluated MAXINFORL with Boltzmann exploration across several deep RL benchmarks on state-based and visual control tasks. The SAC method was used for state-based tasks, and for visual control tasks, the authors combined the algorithm with DrQ. The authors compared MAXINFORL against various baselines across tasks of different dimensionality. It was observed that MAXINFORLSAC performed consistently across all tasks, while other baselines struggled to maintain comparable performance. Even in environments requiring complex exploration, MAXINFORL achieved the best performance. The paper also compared the performance of SAC with and without MAXINFORL and found a stark improvement in speed. For visual tasks, MAXINFORL also achieved substantial gains in performance and sample efficiency.

Conclusion: Researchers presented MAXINFORL algorithms that augmented naive extrinsic exploration techniques to achieve intrinsic rewards by targeting high entropy in state rewards and actions.. In a variety of benchmark tasks involving state-based and visual control, it outperformed off-policy baselines. However, since it required training several models, it was burdened by computational overhead.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. Don’t Forget to join our 60k+ ML SubReddit.

🚨 Trending: LG AI Research Releases EXAONE 3.5: Three Open-Source Bilingual Frontier AI-level Models Delivering Unmatched Instruction Following and Long Context Understanding for Global Leadership in Generative AI Excellence….


Adeeba Alam Ansari is currently pursuing her Dual Degree at the Indian Institute of Technology (IIT) Kharagpur, earning a B.Tech in Industrial Engineering and an M.Tech in Financial Engineering. With a keen interest in machine learning and artificial intelligence, she is an avid reader and an inquisitive individual. Adeeba firmly believes in the power of technology to empower society and promote welfare through innovative solutions driven by empathy and a deep understanding of real-world challenges.

🧵🧵 [Download] Evaluation of Large Language Model Vulnerabilities Report (Promoted)


Credit: Source link

ShareTweetSendSharePin

Related Posts

Google Plans Its First Wyoming Data Center with Carbon-Capture Power – Unite.AI
AI & Technology

Google Plans Its First Wyoming Data Center with Carbon-Capture Power – Unite.AI

November 5, 2026
Lyft’s New Subscription Bundles In DoorDash’s DashPass For  Per Month
AI & Technology

Lyft’s New Subscription Bundles In DoorDash’s DashPass For $10 Per Month

November 5, 2026
Guardian Applies Sierra AI to High-Volume Insurance Service – Unite.AI
AI & Technology

Guardian Applies Sierra AI to High-Volume Insurance Service – Unite.AI

November 5, 2026
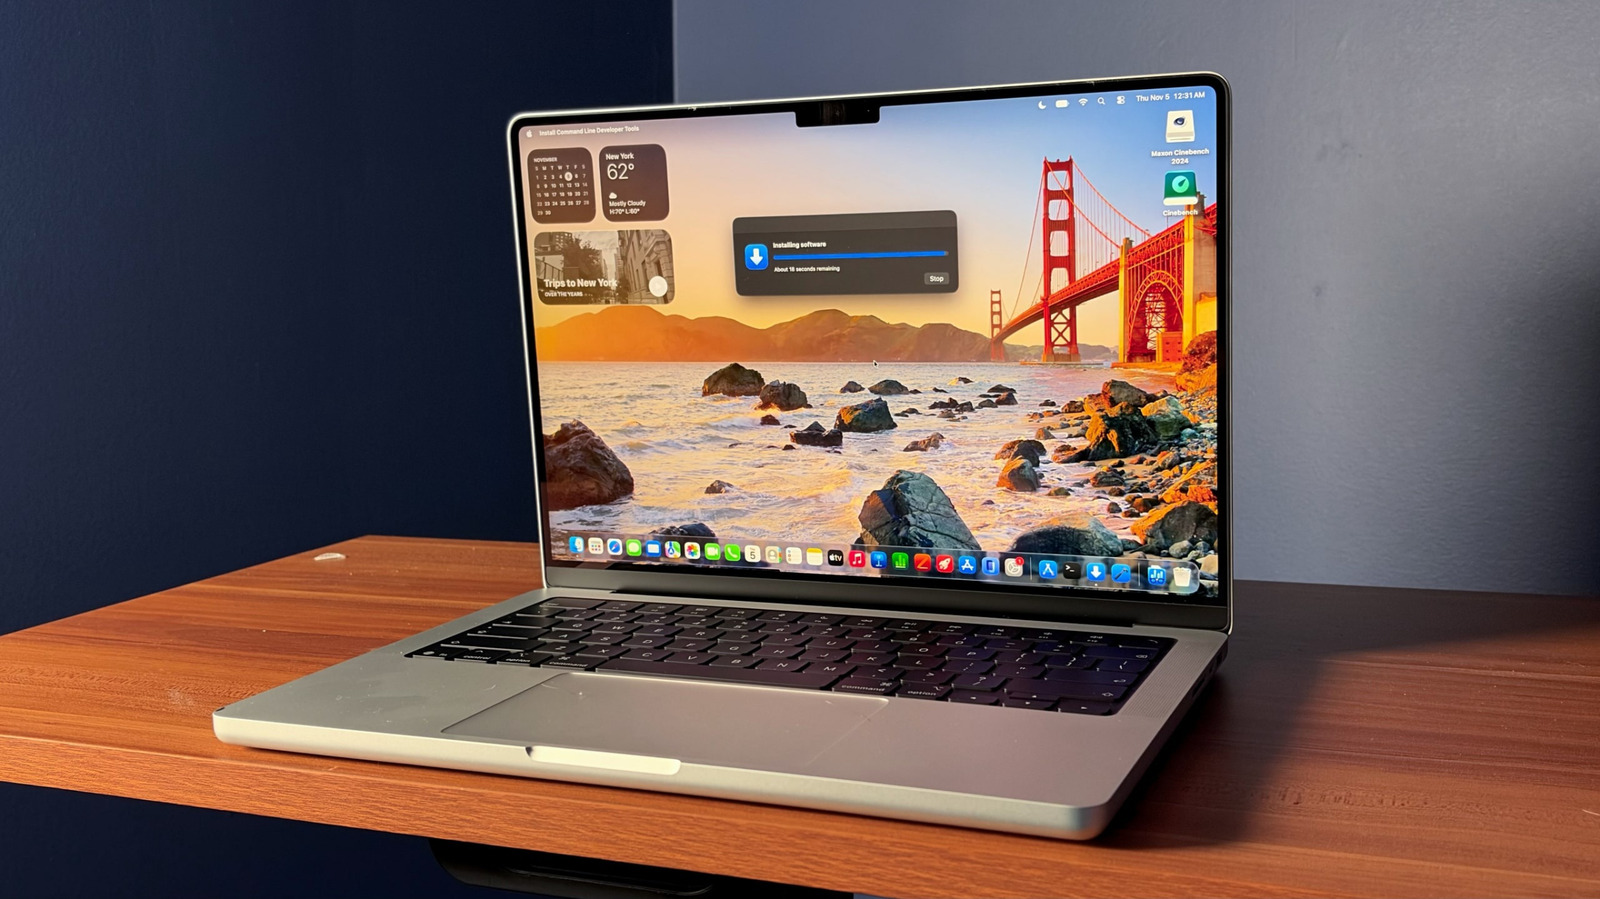
A Slight Upgrade, But Still The Most Accessible MacBook Pro
AI & Technology

A Slight Upgrade, But Still The Most Accessible MacBook Pro

November 5, 2026
Next Post
Mix-LN: A Hybrid Normalization Technique that Combines the Strengths of both Pre-Layer Normalization and Post-Layer Normalization

Mix-LN: A Hybrid Normalization Technique that Combines the Strengths of both Pre-Layer Normalization and Post-Layer Normalization

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Man catches child after he falls off balcony

Man catches child after he falls off balcony

October 31, 2026
The Death Stranding Anime’s First Teaser Trailer Arrives Ahead Of Its Disney+ Debut

The Death Stranding Anime’s First Teaser Trailer Arrives Ahead Of Its Disney+ Debut

October 30, 2026
Election Edition: Will Democrats (Finally) Turn Texas Blue?

Election Edition: Will Democrats (Finally) Turn Texas Blue?

November 2, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!