• bitcoinBitcoin(BTC)$75,531.00-3.95%
  • ethereumEthereum(ETH)$2,394.46-5.67%
  • tetherTether(USDT)$1.00-0.05%
  • binancecoinBNB(BNB)$712.20-1.62%
  • rippleXRP(XRP)$1.28-11.01%
  • usd-coinUSDC(USDC)$1.00-0.02%
  • solanaSolana(SOL)$96.83-6.06%
  • tronTRON(TRX)$0.332612-1.76%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.01-3.46%
  • zcashZcash(ZEC)$1,115.40-4.69%
  • HyperliquidHyperliquid(HYPE)$76.78-4.38%
  • dogecoinDogecoin(DOGE)$0.079937-5.01%
  • RainRain(RAIN)$0.014035-2.21%
  • USDSUSDS(USDS)$1.00-0.03%
  • moneroMonero(XMR)$503.85-1.99%
  • whitebitWhiteBIT Coin(WBT)$77.64-4.63%
  • chainlinkChainlink(LINK)$10.88-6.19%
  • leo-tokenLEO Token(LEO)$8.83-1.83%
  • cardanoCardano(ADA)$0.194690-7.17%
  • stellarStellar(XLM)$0.176501-8.90%
  • Ethena USDeEthena USDe(USDE)$1.00-0.07%
  • daiDai(DAI)$1.000.00%
  • USD1USD1(USD1)$1.00-0.03%
  • bitcoin-cashBitcoin Cash(BCH)$215.64-4.11%
  • litecoinLitecoin(LTC)$51.13-4.23%
  • uniswapUniswap(UNI)$6.32-3.27%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.32-2.57%
  • CantonCanton(CC)$0.090880-7.05%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • hedera-hashgraphHedera(HBAR)$0.074360-4.26%
  • avalanche-2Avalanche(AVAX)$7.26-4.84%
  • nearNEAR Protocol(NEAR)$2.33-7.13%
  • shiba-inuShiba Inu(SHIB)$0.000005-6.32%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.04%
  • suiSui(SUI)$0.68-5.94%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • crypto-com-chainCronos(CRO)$0.055143-7.44%
  • tether-goldTether Gold(XAUT)$4,292.68-0.11%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • MemeCoreMemeCore(M)$1.132.94%
  • BittensorBittensor(TAO)$217.51-6.87%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • okbOKB(OKB)$109.88-3.39%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.01%
  • aaveAave(AAVE)$121.96-5.44%
  • pax-goldPAX Gold(PAXG)$4,295.79-0.13%
  • BitwayBitway(BTW)$0.6912.07%
  • AsterAster(ASTER)$0.68-3.53%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.056922-1.50%
  • mantleMantle(MNT)$0.54-6.21%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

REBEL: A Reinforcement Learning RL Algorithm that Reduces the Problem of RL to Solving a Sequence of Relative Reward Regression Problems on Iteratively Collected Datasets

April 30, 2024
in AI & Technology
Reading Time: 5 mins read
A A
REBEL: A Reinforcement Learning RL Algorithm that Reduces the Problem of RL to Solving a Sequence of Relative Reward Regression Problems on Iteratively Collected Datasets
ShareShareShareShareShare

Initially designed for continuous control tasks, Proximal Policy Optimization (PPO) has become widely used in reinforcement learning (RL) applications, including fine-tuning generative models. However, PPO’s effectiveness relies on multiple heuristics for stable convergence, such as value networks and clipping, making its implementation sensitive and complex. Despite this, RL demonstrates remarkable versatility, transitioning from tasks like continuous control to fine-tuning generative models. Yet, adapting PPO, originally meant to optimize two-layer networks, to fine-tune modern generative models with billions of parameters raises concerns. This necessitates storing multiple models in memory simultaneously and raises questions about the suitability of PPO for such tasks. Also, PPO’s performance varies widely due to seemingly trivial implementation details. This raises the question: Are there simpler algorithms that scale to modern RL applications?

Policy Gradient (PG) methods, renowned for their direct, gradient-based policy optimization, are pivotal in RL. Divided into two families, PG methods based on REINFORCE often incorporate variance reduction techniques, while adaptive PG techniques precondition policy gradients to ensure stability and faster convergence. However, computing and inverting the Fisher Information Matrix in adaptive PG methods like TRPO pose computational challenges, leading to coarse approximations like PPO. 

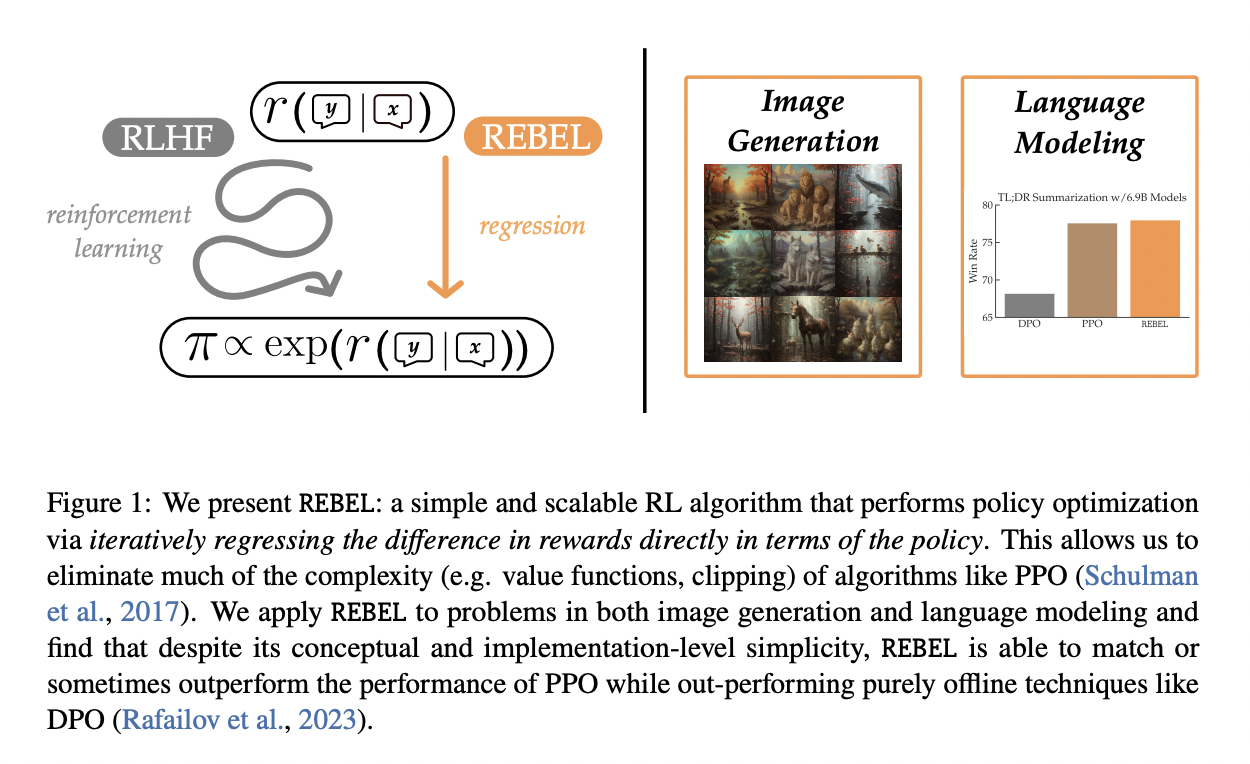
Researchers from  Cornell, Princeton, and  Carnegie Mellon University introduce REBEL: REgression to RElative REward Based RL. This algorithm reduces the problem of policy optimization by regressing the relative rewards via direct policy parameterization between two completions to a prompt, enabling strikingly lightweight implementation. Theoretical analysis reveals REBEL as a foundation for RL algorithms like Natural Policy Gradient, matching top theoretical guarantees for convergence and sample efficiency. REBEL accommodates offline data and addresses intransitive preferences that are common in practice. 

The researchers adopt the Contextual Bandit formulation for RL, which is particularly relevant for models like LLMs and Diffusion Models due to deterministic transitions. Prompt-response pairs are considered with a reward function to measure response quality. The KL-constrained RL problem is formulated to fine-tune the policy according to rewards while adhering to a baseline policy. A closed-form solution to the relative entropy problem is derived from prior research work, allowing the reward to be expressed as a function of the policy. REBEL iteratively updates the policy based on a square loss objective, utilizing paired samples to approximate the partition function. This core REBEL objective aims to fit the relative rewards between response pairs, ultimately seeking to solve the KL-constrained RL problem.
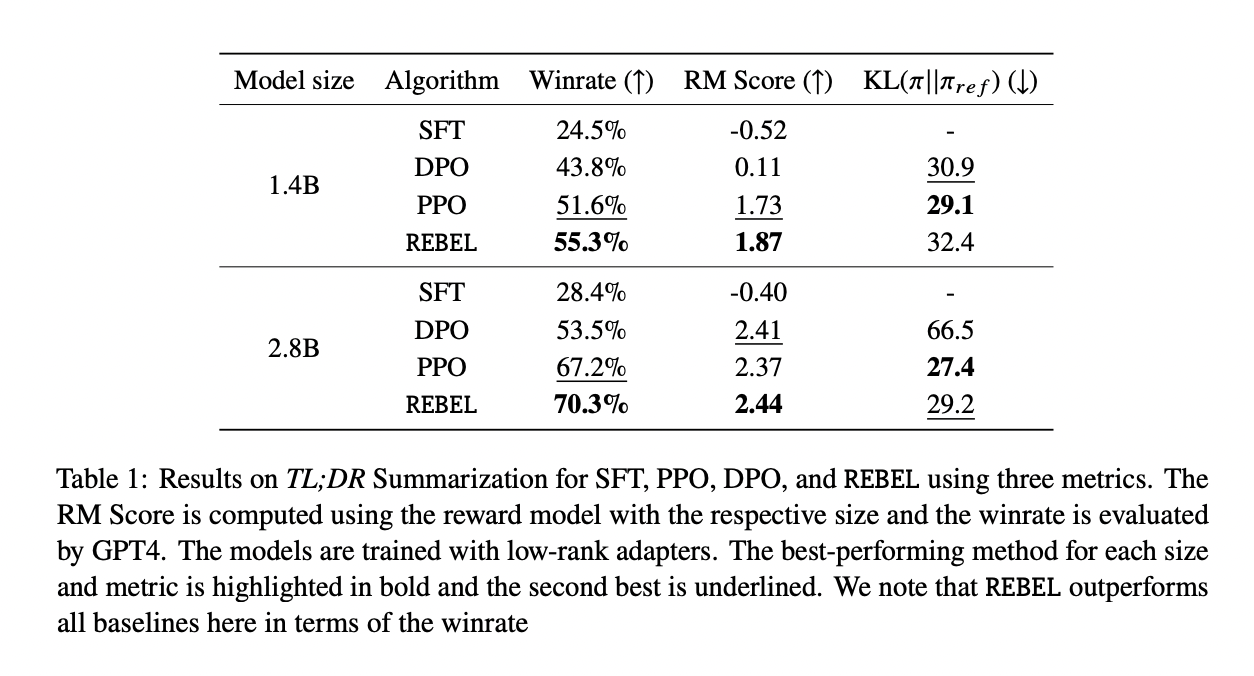
The comparison between REBEL, SFT, PPO, and DPO for models trained with LoRA reveals REBEL’s superior performance regarding RM score across all model sizes, albeit with a slightly larger KL divergence than PPO. Particularly, REBEL achieves the highest win rate under GPT4 when evaluated against human references, indicating the advantage of regressing relative rewards. The trade-off between reward model score and KL divergence, where REBEL exhibits higher divergence but achieves larger RM scores than PPO, especially towards the end of training. 
In conclusion, this research presents REBEL, a simplified RL algorithm that tackles the RL problem by solving a series of relative reward regression tasks on sequentially gathered datasets. Unlike policy gradient approaches, which often rely on additional networks and heuristics like clipping for optimization stability, REBEL focuses on driving down training error on a least squares problem, making it remarkably straightforward to implement and scale. Theoretically, REBEL aligns with the strongest guarantees available for RL algorithms in agnostic settings. In practice, REBEL demonstrates competitive or superior performance compared to more complex and resource-intensive methods across language modeling and guided image generation tasks.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 40k+ ML SubReddit

YOU MAY ALSO LIKE

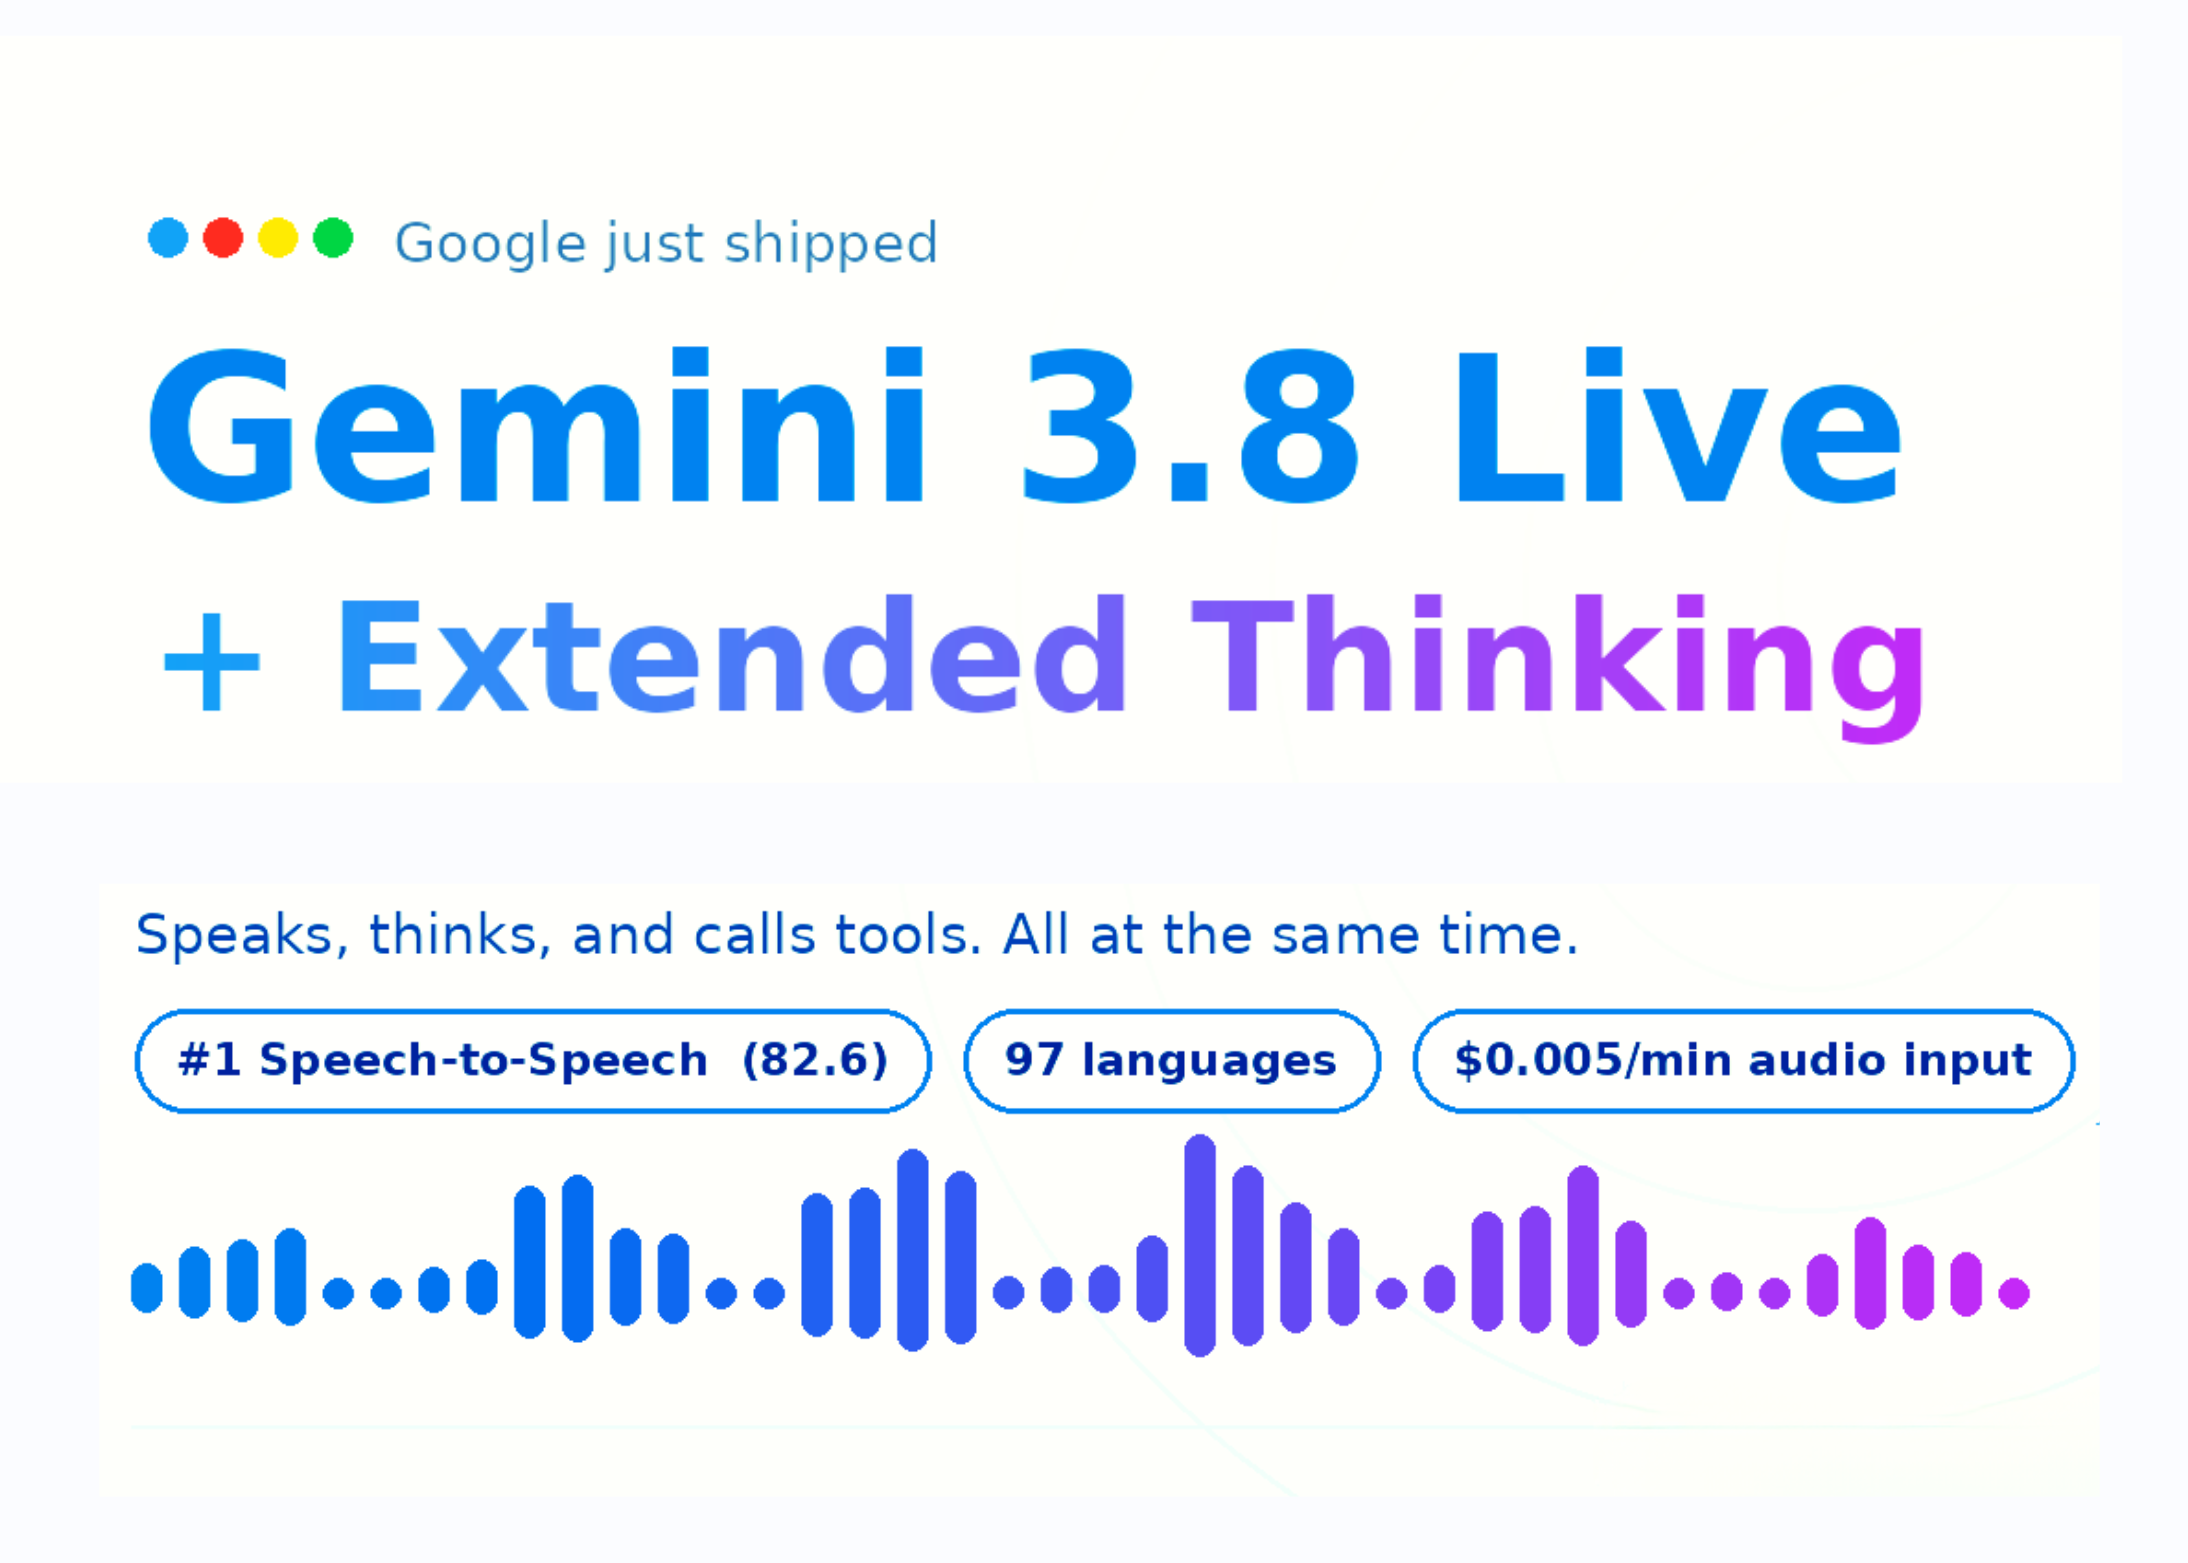
Google Releases Gemini 3.8 Live and 3.8 Live Extended Thinking for Production Grade Voice Agents

How To Improve The Audio Quality On Your iPhone

Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Google Releases Gemini 3.8 Live and 3.8 Live Extended Thinking for Production Grade Voice Agents
AI & Technology

Google Releases Gemini 3.8 Live and 3.8 Live Extended Thinking for Production Grade Voice Agents

September 15, 2026
How To Improve The Audio Quality On Your iPhone
AI & Technology

How To Improve The Audio Quality On Your iPhone

September 15, 2026
Ferrovalle Taps INFORM for AI Smart Yard at Mexico City Rail Hub – Unite.AI
AI & Technology

Ferrovalle Taps INFORM for AI Smart Yard at Mexico City Rail Hub – Unite.AI

September 15, 2026
Google’s Latest Pixel Drop Will Keep You More Connected To Your VIPs
AI & Technology

Google’s Latest Pixel Drop Will Keep You More Connected To Your VIPs

September 15, 2026
Next Post
Charlotte shooting suspect named after 4 officers killed in NC

Charlotte shooting suspect named after 4 officers killed in NC

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Columbia Strategic Income Fund Q2 2026 Commentary

Columbia Strategic Income Fund Q2 2026 Commentary

September 14, 2026
Supreme Court rejects Missouri’s attempt to use newly drawn Republican congressional map

Supreme Court rejects Missouri’s attempt to use newly drawn Republican congressional map

September 14, 2026
DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and Cross-Layer Attention Reuse

DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and Cross-Layer Attention Reuse

September 10, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!