• bitcoinBitcoin(BTC)$83,214.00-2.97%
  • ethereumEthereum(ETH)$2,636.39-3.45%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$765.51-2.21%
  • rippleXRP(XRP)$1.46-8.12%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$112.82-3.71%
  • tronTRON(TRX)$0.338787-1.21%
  • zcashZcash(ZEC)$1,466.13-9.12%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.040.37%
  • HyperliquidHyperliquid(HYPE)$90.03-5.67%
  • dogecoinDogecoin(DOGE)$0.091927-7.66%
  • moneroMonero(XMR)$545.66-4.01%
  • whitebitWhiteBIT Coin(WBT)$83.25-3.34%
  • USDSUSDS(USDS)$1.00-0.02%
  • chainlinkChainlink(LINK)$12.14-5.27%
  • cardanoCardano(ADA)$0.233920-7.29%
  • RainRain(RAIN)$0.011989-7.24%
  • leo-tokenLEO Token(LEO)$8.92-0.63%
  • stellarStellar(XLM)$0.197437-8.34%
  • bitcoin-cashBitcoin Cash(BCH)$328.83-4.97%
  • uniswapUniswap(UNI)$8.87-8.71%
  • nearNEAR Protocol(NEAR)$4.17-9.55%
  • litecoinLitecoin(LTC)$66.826.76%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • daiDai(DAI)$1.000.01%
  • avalanche-2Avalanche(AVAX)$10.07-9.20%
  • USD1USD1(USD1)$1.00-0.01%
  • CantonCanton(CC)$0.106840-4.73%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.40-3.27%
  • hedera-hashgraphHedera(HBAR)$0.089328-7.62%
  • suiSui(SUI)$0.94-6.97%
  • shiba-inuShiba Inu(SHIB)$0.000006-7.96%
  • Global DollarGlobal Dollar(USDG)$1.00-0.02%
  • BittensorBittensor(TAO)$279.24-9.56%
  • crypto-com-chainCronos(CRO)$0.060528-8.66%
  • MemeCoreMemeCore(M)$1.23-3.84%
  • BitwayBitway(BTW)$1.017.63%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • tether-goldTether Gold(XAUT)$4,254.34-1.49%
  • okbOKB(OKB)$117.82-4.10%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.19%
  • mantleMantle(MNT)$0.66-2.86%
  • aaveAave(AAVE)$135.78-8.26%
  • OndoOndo(ONDO)$0.418547-3.79%
  • EthenaEthena(ENA)$0.200465-5.32%
  • polkadotPolkadot(DOT)$1.11-4.65%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

RAGEval: An AI Framework for Automatically Generating Evaluation Datasets to Evaluate the Knowledge Usage Ability of Different LLMs in Different Scenarios

August 9, 2024
in AI & Technology
Reading Time: 5 mins read
A A
RAGEval: An AI Framework for Automatically Generating Evaluation Datasets to Evaluate the Knowledge Usage Ability of Different LLMs in Different Scenarios
ShareShareShareShareShare

Natural Language Processing (NLP), despite its progress, faces the persistent challenge of hallucination, where models generate incorrect or nonsensical information. Researchers have introduced Retrieval-Augmented Generation (RAG) systems to mitigate this issue by incorporating external information retrieval to enhance the accuracy of generated responses.

The problem, however, is the reliability and effectiveness of RAG systems in providing accurate responses across different domains. Existing benchmarks primarily focus on general knowledge but need to improve in evaluating the performance of RAG models in specialized fields like finance, healthcare, and legal sectors. This limitation arises from the difficulty in curating high-quality datasets that can comprehensively test the models’ ability to handle domain-specific information.

YOU MAY ALSO LIKE

Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model

Current methods for evaluating RAG systems include established NLP metrics such as F1, BLEU, ROUGE-L, and EM for answer generation and Hit Rate, MRR, and NDCG for retrieval assessment. More recent approaches use LLM-generated data to evaluate contextual relevance, faithfulness, and informativeness. However, these metrics often lack the nuance required for assessing the generative capabilities of RAG systems in vertical domains. Consequently, a more robust evaluation framework is necessary to address these shortcomings and provide a detailed assessment of RAG performance in specialized areas.

Researchers from Tsinghua University, Beijing Normal University, University of Chinese Academy of Sciences, and Northeastern University introduced the RAGEval framework to address these challenges. This framework automatically generates evaluation datasets tailored to specific scenarios in various vertical domains. The process begins by summarizing a schema from seed documents, generating diverse documents and constructing question-answering pairs based on these configurations. The framework then evaluates the model responses using novel metrics focusing on factual accuracy.

The proposed method, RAGEval, employs a “schema-configuration-document-QAR-keypoint” pipeline to ensure the robustness and reliability of the evaluation process. This involves generating a schema that encapsulates essential domain-specific knowledge, creating configurations from this schema, and producing diverse documents. These documents are then used to generate questions and reference answers, forming QAR triples evaluated for completeness, hallucination, and irrelevance. This comprehensive approach ensures that the evaluation datasets are rich in factual information and logical coherence.
A hybrid approach is used to generate these configurations, combining rule-based and LLM-based methods to assign values to the schema elements. Rule-based methods ensure high accuracy and consistency, particularly for structured data, while LLMs are used to generate more complex or diverse content. This method produces a wide range of high-quality, diverse configurations, ensuring the generated documents are accurate and contextually relevant.

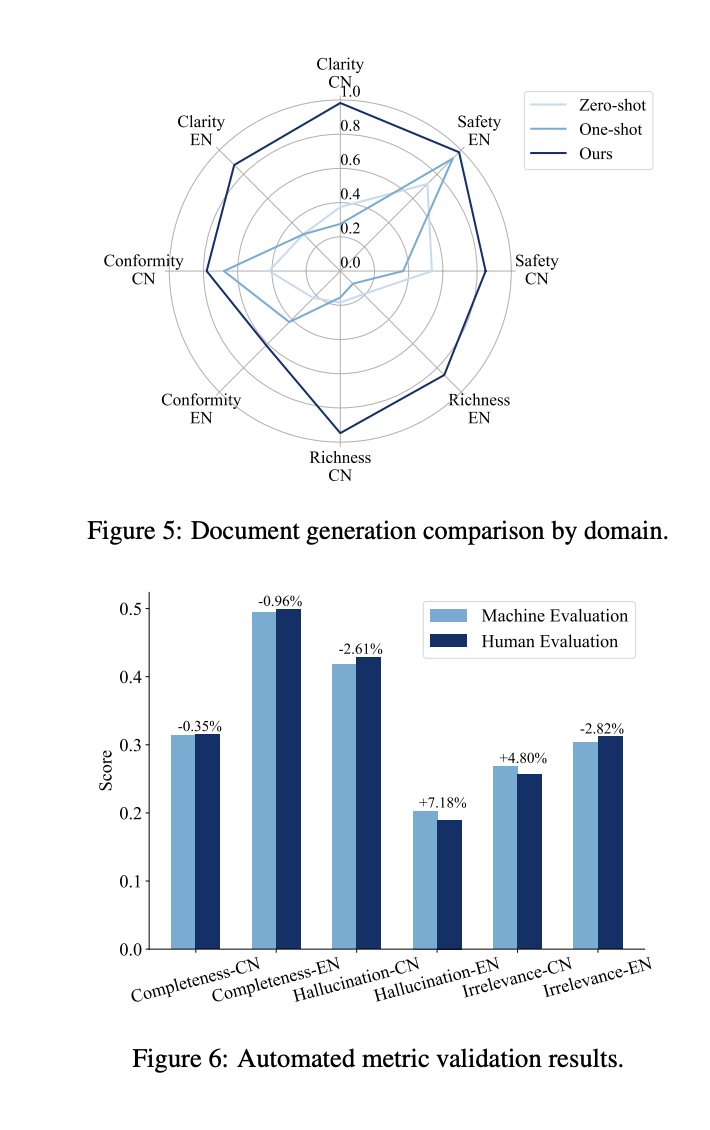
Experimental results demonstrated that the RAGEval framework is highly effective in generating accurate, safe, and rich content across various domains. The human evaluation results highlighted the robustness of this method, showing that the generated documents were clear, specific, and closely resembled real-world documents. Moreover, the validation of automated evaluation metrics showed a high degree of alignment with human judgment, confirming the reliability of these metrics in reflecting model performance.
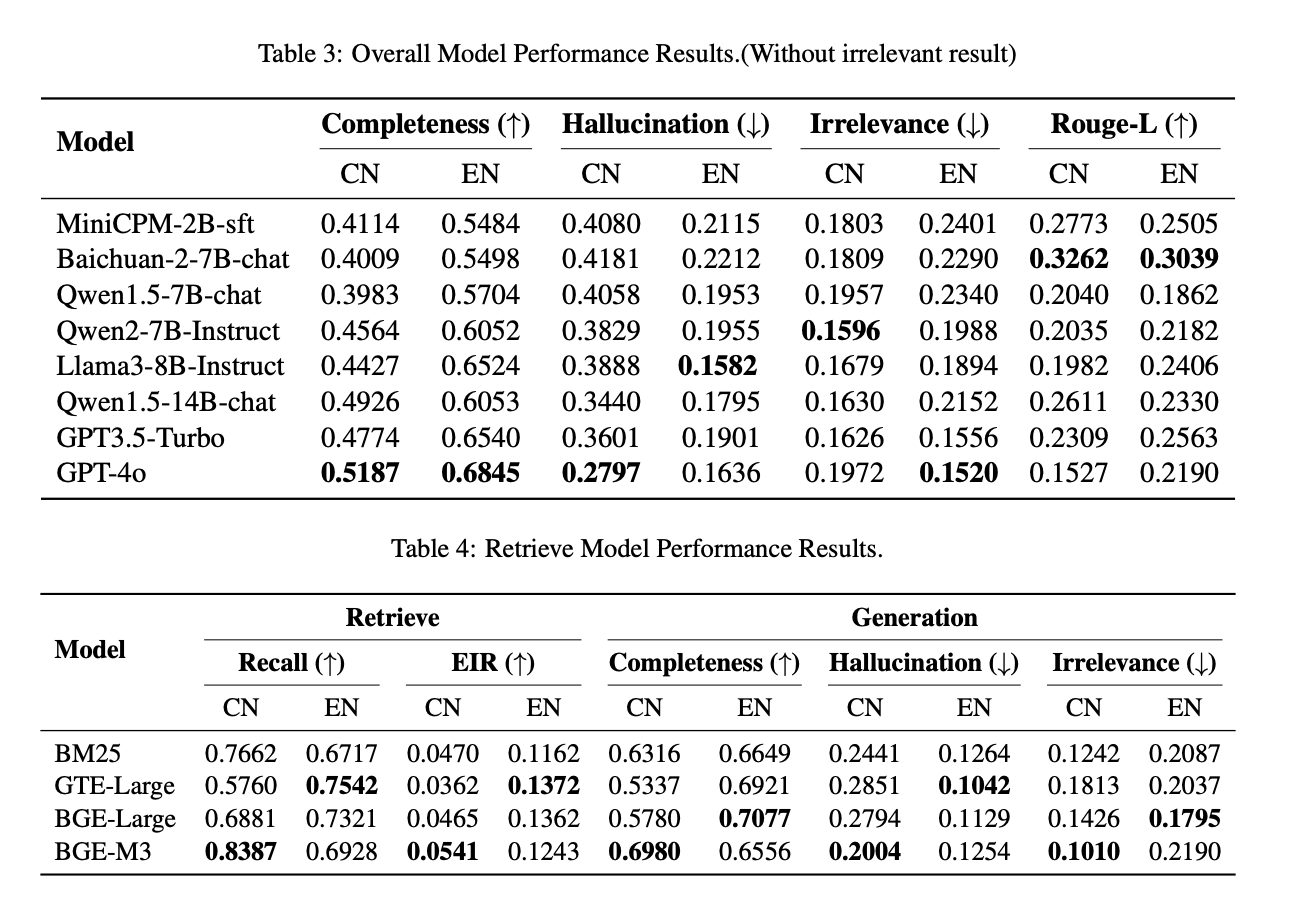
GPT-4o performed better overall, achieving the highest Completeness scores of 0.5187 for Chinese and 0.6845 for English. However, the gap with top-performing open-source models, such as Qwen1.5-14B-chat and Llama3-8B-Instruct, was relatively small. Qwen1.5-14B-chat achieved a Completeness score of 0.4926 in Chinese, while Llama3-8B-Instruct scored 0.6524 in English. These results suggest that with further advancements, open-source models have significant potential to close the performance gap with proprietary models.

In conclusion, the RAGEval framework offers a robust solution for evaluating RAG systems, addressing the limitations of existing benchmarks by focusing on domain-specific factual accuracy. This approach enhances the reliability of RAG models in various industries and paves the way for future improvements in proprietary and open-source models. For best results, researchers and developers are encouraged to leverage frameworks like RAGEval to ensure their models meet the specific needs of their application domains.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter..

Don’t Forget to join our 48k+ ML SubReddit

Find Upcoming AI Webinars here


Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in Materials at the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast who is always researching applications in fields like biomaterials and biomedical science. With a strong background in Material Science, he is exploring new advancements and creating opportunities to contribute.


Credit: Source link

ShareTweetSendSharePin

Related Posts

Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev
AI & Technology

Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev

September 24, 2026
A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model
AI & Technology

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model

September 24, 2026
Everything Announced At Meta Connect 2026
AI & Technology

Everything Announced At Meta Connect 2026

September 24, 2026
Meta Put Muse In A Tamagotchi Like ‘Charm’ Device
AI & Technology

Meta Put Muse In A Tamagotchi Like ‘Charm’ Device

September 24, 2026
Next Post
Top Story with Tom Llamas – April 16 | NBC News NOW

Top Story with Tom Llamas - April 16 | NBC News NOW

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
She’s Paying Her Boyfriend’s Debt For Free Rent

She’s Paying Her Boyfriend’s Debt For Free Rent

September 23, 2026
Odfjell Drilling Stock: Buy On Strong Industry Prospects, Juicy Dividend Yield (ODFJF)

Odfjell Drilling Stock: Buy On Strong Industry Prospects, Juicy Dividend Yield (ODFJF)

September 23, 2026
GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

September 19, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!