• bitcoinBitcoin(BTC)$78,521.00-1.93%
  • ethereumEthereum(ETH)$2,243.49-3.14%
  • tetherTether(USDT)$1.00-0.03%
  • binancecoinBNB(BNB)$716.32-4.85%
  • rippleXRP(XRP)$1.26-2.87%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$97.93-2.11%
  • tronTRON(TRX)$0.3369471.97%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.03%
  • HyperliquidHyperliquid(HYPE)$93.1317.74%
  • zcashZcash(ZEC)$1,271.512.06%
  • dogecoinDogecoin(DOGE)$0.076295-2.62%
  • moneroMonero(XMR)$590.600.15%
  • USDSUSDS(USDS)$1.00-0.22%
  • whitebitWhiteBIT Coin(WBT)$75.06-2.23%
  • leo-tokenLEO Token(LEO)$9.43-0.31%
  • chainlinkChainlink(LINK)$11.11-3.23%
  • cardanoCardano(ADA)$0.193940-2.50%
  • stellarStellar(XLM)$0.166885-0.88%
  • bitcoin-cashBitcoin Cash(BCH)$283.260.96%
  • nearNEAR Protocol(NEAR)$4.25-4.83%
  • RainRain(RAIN)$0.0065935.38%
  • daiDai(DAI)$1.000.03%
  • Ethena USDeEthena USDe(USDE)$1.00-0.19%
  • litecoinLitecoin(LTC)$56.13-2.28%
  • uniswapUniswap(UNI)$6.79-3.59%
  • USD1USD1(USD1)$1.00-0.06%
  • avalanche-2Avalanche(AVAX)$8.60-1.50%
  • CantonCanton(CC)$0.094833-1.54%
  • suiSui(SUI)$0.89-2.30%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.17-3.68%
  • tether-goldTether Gold(XAUT)$3,986.11-0.82%
  • hedera-hashgraphHedera(HBAR)$0.071620-3.03%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.17%
  • quant-networkQuant(QNT)$195.010.19%
  • shiba-inuShiba Inu(SHIB)$0.000005-3.60%
  • BittensorBittensor(TAO)$237.39-4.63%
  • crypto-com-chainCronos(CRO)$0.051464-2.54%
  • Ripple USDRipple USD(RLUSD)$1.00-0.04%
  • EthenaEthena(ENA)$0.187704-4.89%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.01%
  • okbOKB(OKB)$112.530.95%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • MemeCoreMemeCore(M)$1.03-0.74%
  • BitwayBitway(BTW)$1.47-17.98%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • pepePepe(PEPE)$0.000005-0.67%
  • aaveAave(AAVE)$126.67-3.31%
  • OndoOndo(ONDO)$0.392329-4.06%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM Inference

May 24, 2024
in AI & Technology
Reading Time: 5 mins read
A A
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM Inference
ShareShareShareShareShare

LLMs like GPT-4 excel in language comprehension but struggle with high GPU memory usage during inference, limiting their scalability for real-time applications like chatbots. Existing methods reduce memory by compressing the KV cache but overlook inter-layer dependencies and pre-computation memory demands. Inference memory usage primarily comes from model parameters and the KV cache, with the latter consuming significantly more memory. For instance, a 7 billion parameter model uses 14 GB for parameters but 72 GB for the KV cache. This substantial memory requirement restricts the throughput of LLM inference on GPUs.

Researchers from Shanghai Jiao Tong University, Xiaohongshu Inc., and South China University of Technology developed PyramidInfer, which enhances LLM inference by compressing the KV cache. Unlike existing methods that overlook inter-layer dependencies and the memory demands of pre-computation, PyramidInfer retains only crucial context keys and values layer-by-layer. Inspired by recent tokens’ consistency in attention weights, this approach significantly reduces GPU memory usage. Experiments show PyramidInfer improves throughput by 2.2x and reduces KV cache memory by over 54% compared to existing methods, demonstrating its effectiveness across various tasks and models.

Efficient strategies are essential to handle the growing demand for chatbot queries, aiming to maximize throughput by leveraging GPU parallelism. One approach is increasing GPU memory through pipeline parallelism and KV cache offload, utilizing multiple GPUs or RAM. For limited GPU memory, reducing the KV cache is another option. Techniques like FlashAttention 2 and PagedAttention minimize memory waste by optimizing CUDA operations. Methods such as StreamingLLM, H2O, and Scissorhands compress the KV cache by focusing on recent context or attention mechanisms but overlook layer differences and prefill phase compression. PyramidInfer addresses these gaps by considering layer-specific compression in both phases.
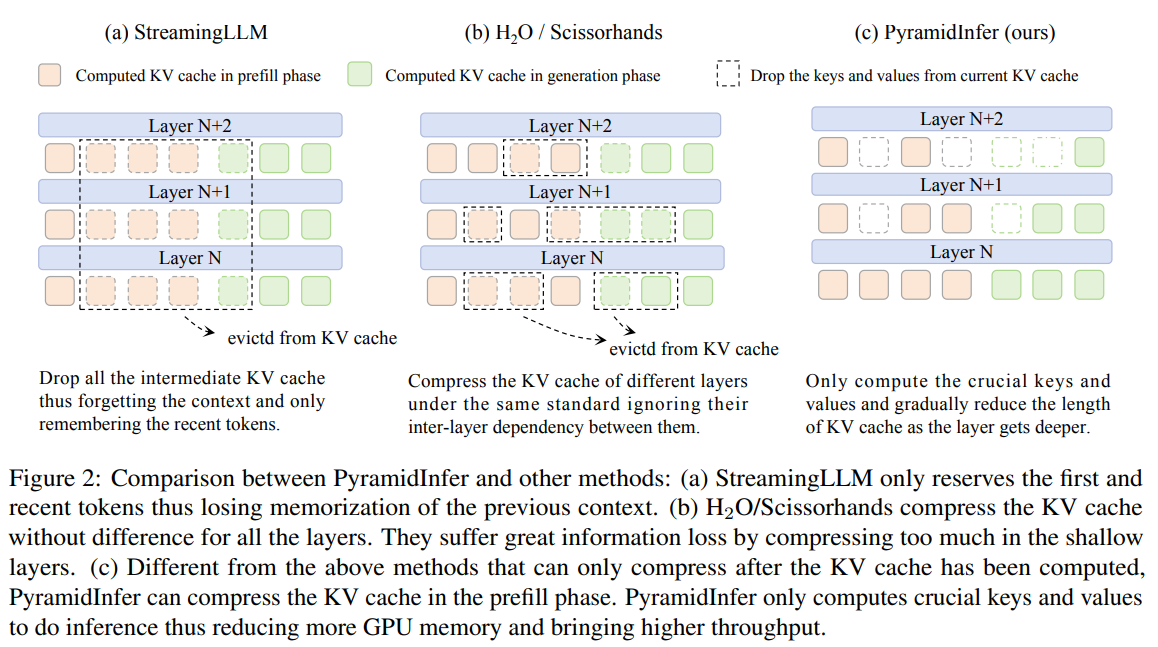
Verification of the Inference Context Redundancy (ICR) and Recent Attention Consistency (RAC) hypotheses inspired the design of PyramidInfer. ICR posits that many context keys and values are redundant during inference and are only necessary in training to predict the next token. Experiments with a 40-layer LLaMA 2-13B model revealed that deeper layers have higher redundancy, allowing for significant KV cache reduction without affecting output quality. RAC confirms that certain keys and values are consistently attended by recent tokens, enabling the selection of pivotal contexts (PVCs) for efficient inference. PyramidInfer leverages these insights to compress the KV cache effectively in both prefill and generation phases.

PyramidInfer’s performance was evaluated across various tasks and models, demonstrating significant reductions in GPU memory usage and increased throughput while maintaining generation quality. The evaluation included language modeling on wikitext-v2, LLM benchmarks like MMLU and BBH, mathematical reasoning with GSM8K, coding via HumanEval, conversation handling with MT-Bench, and long text summarization using LEval. PyramidInfer was tested on models such as LLaMA 2, LLaMA 2-Chat, Vicuna 1.5-16k, and CodeLLaMA across different sizes. Results showed that PyramidInfer effectively maintained generation quality with less GPU memory than full cache methods and significantly outperformed local strategies.

In conclusion, PyramidInfer introduces an efficient method to compress the KV cache during both prefill and generation phases, inspired by ICR and RAC. This approach significantly reduces GPU memory usage without compromising model performance, making it ideal for deploying large language models in resource-constrained environments. Despite its effectiveness, PyramidInfer requires additional computation, limiting speedup with small batch sizes. As the first to compress the KV cache in the prefill phase, PyramidInfer is yet to be a lossless method, indicating potential for future improvements in this area.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 42k+ ML SubReddit

YOU MAY ALSO LIKE

Microsoft Offers Buyouts to 60,000 Employees

Meta Looks to Raise $95 Billion From Stock Sale to Fund AI Investments

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.


✅ [Featured Tool] Check out Taipy Enterprise Edition


Credit: Source link

ShareTweetSendSharePin

Related Posts

Microsoft Offers Buyouts to 60,000 Employees
AI & Technology

Microsoft Offers Buyouts to 60,000 Employees

October 30, 2026
Meta Looks to Raise  Billion From Stock Sale to Fund AI Investments
AI & Technology

Meta Looks to Raise $95 Billion From Stock Sale to Fund AI Investments

October 30, 2026
Anthropic to Deliver Menlo’s Biggest-Ever Return
AI & Technology

Anthropic to Deliver Menlo’s Biggest-Ever Return

October 30, 2026
Anthropic’s S-1 Reveals Financial War Chest
AI & Technology

Anthropic’s S-1 Reveals Financial War Chest

October 29, 2026
Next Post
The ONE Thing Keeping You From Building Wealth – Dave Ramsey Rant

The ONE Thing Keeping You From Building Wealth – Dave Ramsey Rant

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Tupac’s sister gives emotional impact statement

Tupac’s sister gives emotional impact statement

October 26, 2026
Who is Nobel Peace Prize winner Navi Pillay?

Who is Nobel Peace Prize winner Navi Pillay?

October 28, 2026
Security kills man who brought gun to Nashville courthouse

Security kills man who brought gun to Nashville courthouse

October 29, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!