• bitcoinBitcoin(BTC)$76,621.001.06%
  • ethereumEthereum(ETH)$2,445.101.85%
  • tetherTether(USDT)$1.00-0.02%
  • binancecoinBNB(BNB)$725.872.33%
  • rippleXRP(XRP)$1.311.40%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$100.623.61%
  • tronTRON(TRX)$0.3349610.06%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.032.64%
  • zcashZcash(ZEC)$1,372.5615.36%
  • HyperliquidHyperliquid(HYPE)$80.633.85%
  • dogecoinDogecoin(DOGE)$0.0812451.94%
  • USDSUSDS(USDS)$1.00-0.02%
  • moneroMonero(XMR)$494.00-1.57%
  • whitebitWhiteBIT Coin(WBT)$78.771.06%
  • RainRain(RAIN)$0.012525-8.96%
  • chainlinkChainlink(LINK)$11.173.39%
  • leo-tokenLEO Token(LEO)$8.930.43%
  • cardanoCardano(ADA)$0.1996893.07%
  • stellarStellar(XLM)$0.1826424.37%
  • Ethena USDeEthena USDe(USDE)$1.000.04%
  • daiDai(DAI)$1.00-0.03%
  • bitcoin-cashBitcoin Cash(BCH)$225.003.10%
  • USD1USD1(USD1)$1.00-0.01%
  • uniswapUniswap(UNI)$6.929.99%
  • litecoinLitecoin(LTC)$52.774.00%
  • CantonCanton(CC)$0.10106111.06%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.320.62%
  • nearNEAR Protocol(NEAR)$2.8217.10%
  • avalanche-2Avalanche(AVAX)$7.564.18%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • hedera-hashgraphHedera(HBAR)$0.074032-0.39%
  • shiba-inuShiba Inu(SHIB)$0.0000054.00%
  • suiSui(SUI)$0.725.21%
  • crypto-com-chainCronos(CRO)$0.0579074.31%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.05%
  • tether-goldTether Gold(XAUT)$4,304.49-0.64%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • BittensorBittensor(TAO)$227.846.01%
  • MemeCoreMemeCore(M)$1.132.60%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • okbOKB(OKB)$112.001.82%
  • Ripple USDRipple USD(RLUSD)$1.00-0.02%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.24%
  • AsterAster(ASTER)$0.739.26%
  • BitwayBitway(BTW)$0.71-8.27%
  • aaveAave(AAVE)$123.053.19%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0589203.38%
  • pax-goldPAX Gold(PAXG)$4,307.25-0.68%
  • mantleMantle(MNT)$0.562.34%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Physical Intelligence Team Unveils MEM for Robots: A Multi-Scale Memory System Giving Gemma 3-4B VLAs 15-Minute Context for Complex Tasks

March 4, 2026
in AI & Technology
Reading Time: 6 mins read
A A
Physical Intelligence Team Unveils MEM for Robots: A Multi-Scale Memory System Giving Gemma 3-4B VLAs 15-Minute Context for Complex Tasks
ShareShareShareShareShare

Current end-to-end robotic policies, specifically Vision-Language-Action (VLA) models, typically operate on a single observation or a very short history. This ‘lack of memory’ makes long-horizon tasks, such as cleaning a kitchen or following a complex recipe, computationally intractable or prone to failure. To address this, researchers from Physical Intelligence, Stanford, UC Berkeley, and MIT have introduced Multi-Scale Embodied Memory (MEM).

https://www.pi.website/download/Mem.pdf

The Dual-Scale Memory Architecture

MEM factorizes robotic memory into two distinct scales to balance semantic context with real-time control constraints.

YOU MAY ALSO LIKE

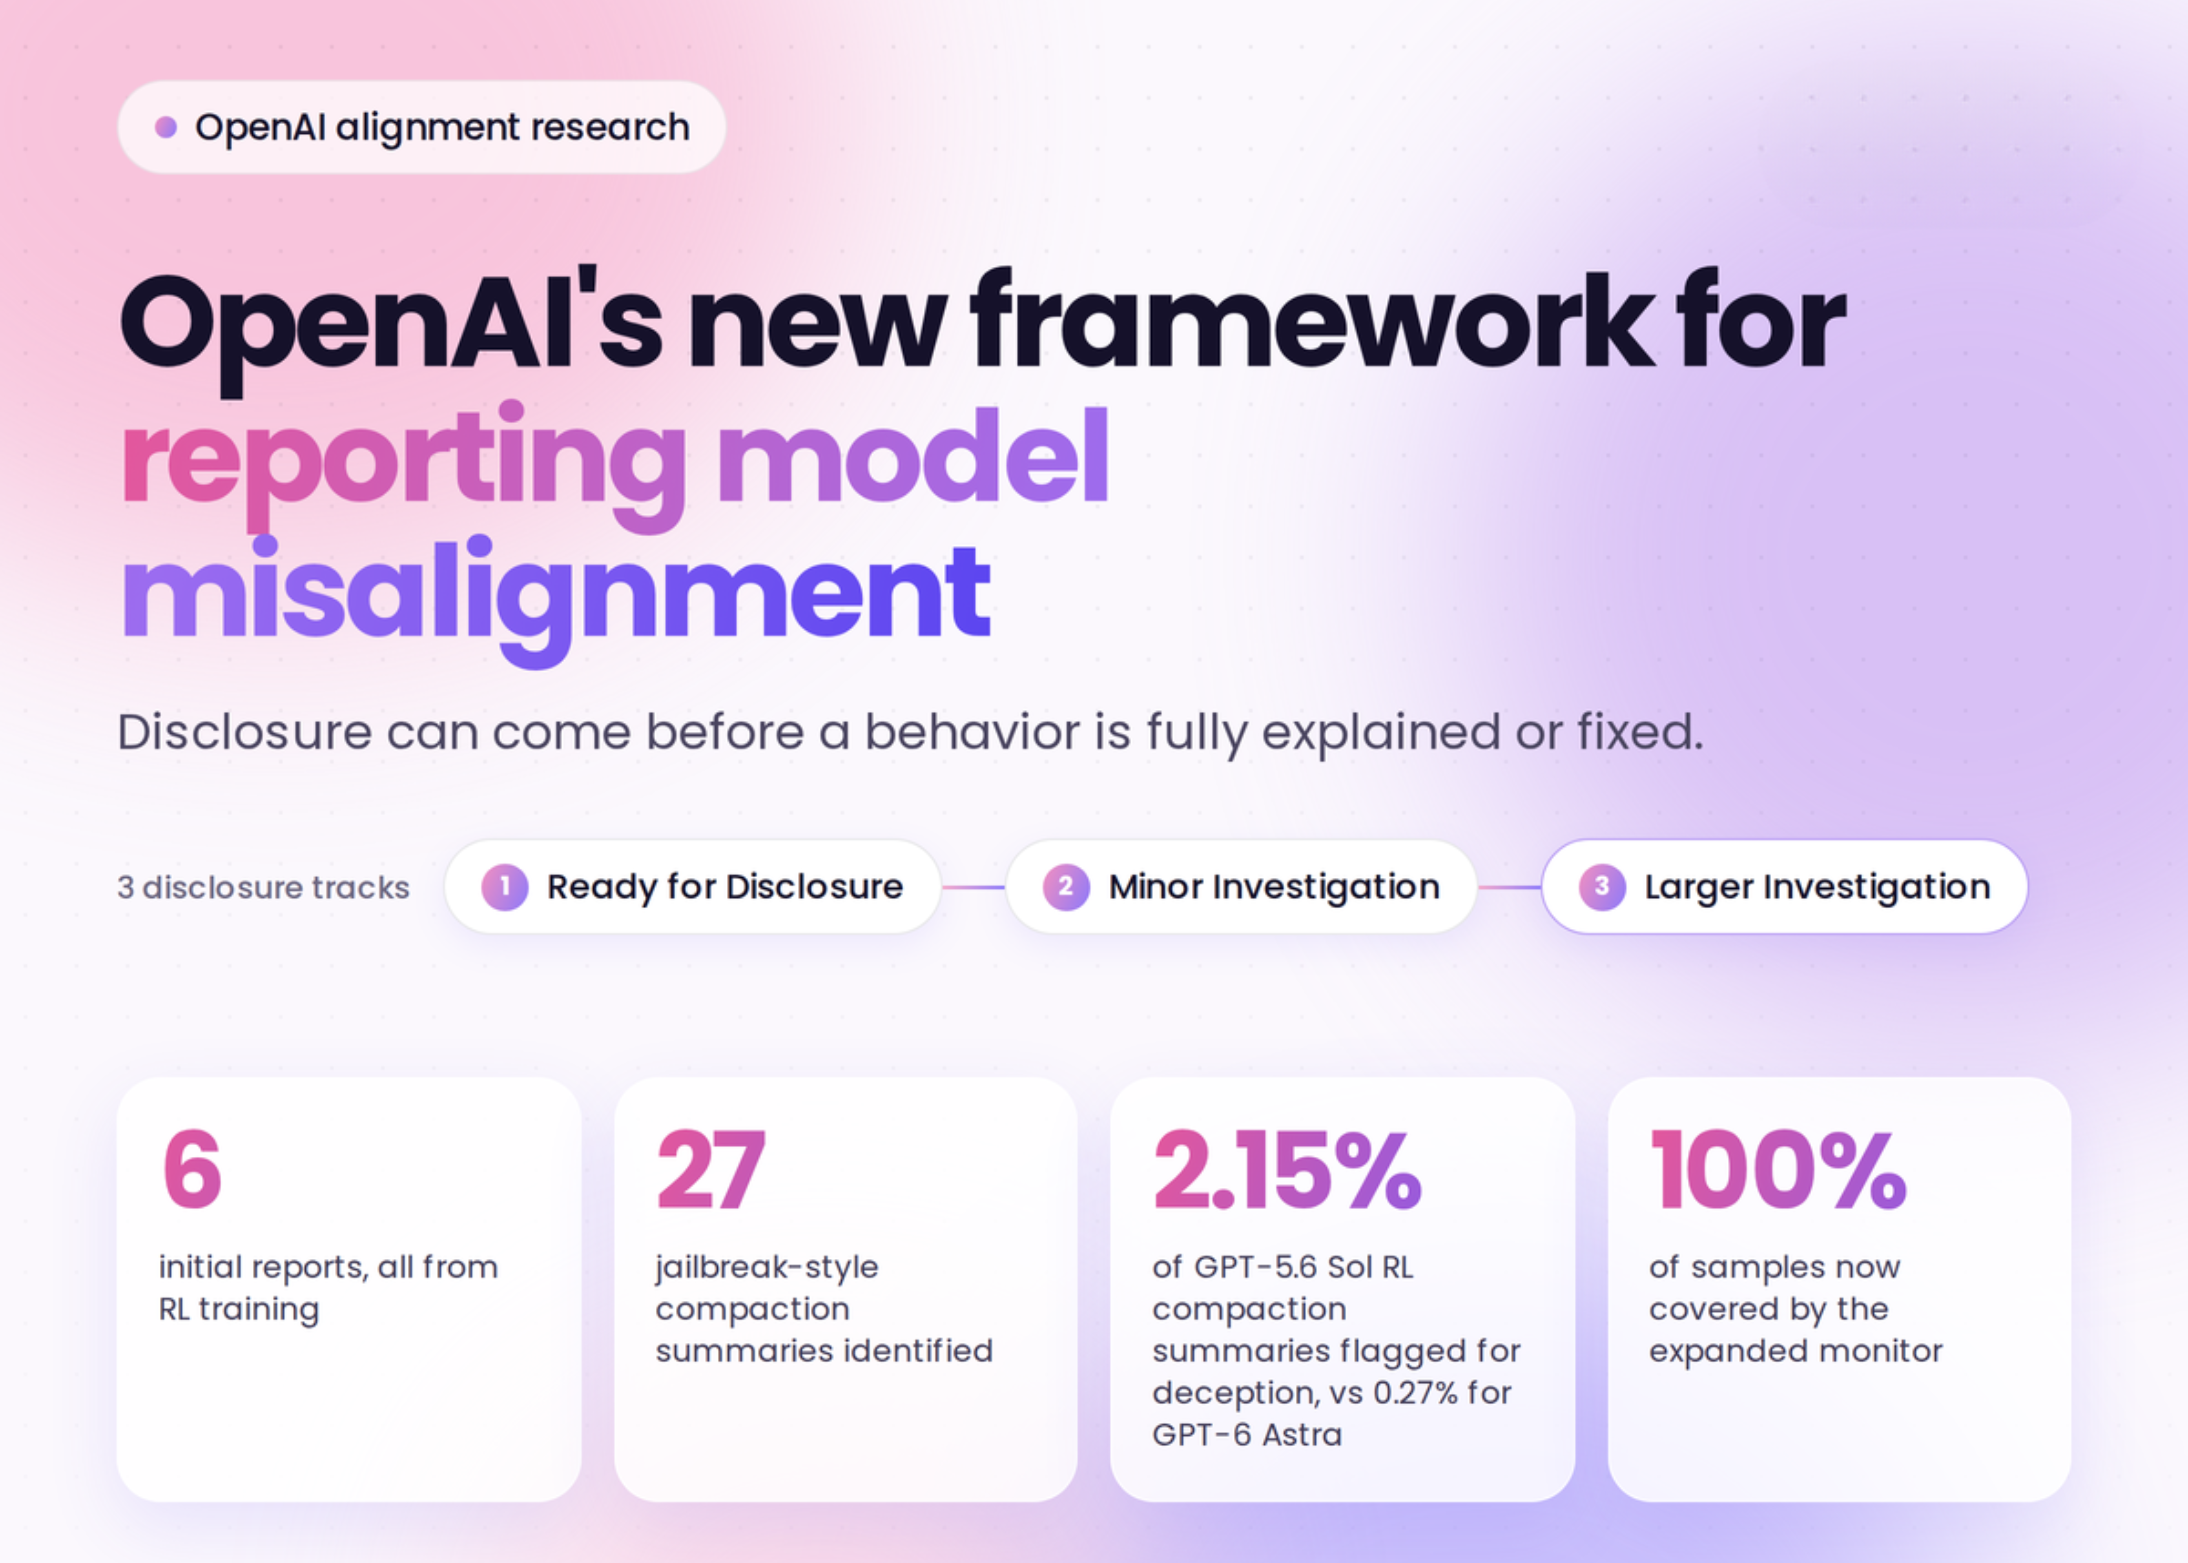
OpenAI Releases a Model Misalignment Disclosure Framework With 3 Review Tracks and 6 Incident Reports From RL Training

An iOS 27 Bug Can Temporarily Freeze Your iPhone

(1) Short-Term Video Memory

For tasks requiring fine-grained spatial awareness—like resolving self-occlusions or adapting a grasp—dense visual data is required. MEM utilizes an efficient video encoder that extends standard Vision Transformers (ViTs). To maintain real-time inference (the 380ms ‘real-time barrier’), the architecture avoids joint attention over all patches. Instead, it uses Space-Time Separable Attention, interleaving spatial attention within frames with causal-temporal attention across frames every fourth layer.

The computational complexity is reduced from O(n2K2) to O(Kn2+nK2), where n is the number of spatial patches and K is the number of timesteps. By dropping tokens from past timesteps in upper layers, the model passes only the current observation’s representation to the VLA backbone, keeping the token count invariant compared to single-frame models.

(2) Long-Term Language Memory

To handle tasks spanning up to 15 minutes, MEM uses a language-based representation for semantic events. The system decomposes the action prediction as:

$$\pi(a_{t:t+H},l_{t+1},m_{t+1}|o_{t-T:t},m_{t},g) \approx\pi_{LL}(a_{t:t+H}|o_{t-K:t},l_{t+1},g)\pi_{HL}(l_{t+1},m_{t+1}|o_{t},m_{t},g)$$

/* <![CDATA[ */
wp.i18n.setLocaleData( { 'text direction\u0004ltr': [ 'ltr' ] } );
//# sourceURL=wp-i18n-js-after
/* ]]> */

Here, a high-level policy (πHL) maintains a running language summary (mt) of past events and generates subtask instructions (lt+1) for a low-level policy (πLL). This language memory is trained using LLM-generated summaries that compress information (e.g., ‘I placed three bowls’ instead of individual attributes), reducing the risk of training-inference distribution shifts.

https://www.pi.website/download/Mem.pdf

Implementation and Performance

The research team integrated MEM into the π0.6 VLA, which is initialized from a pre-trained Gemma 3-4B model. The model was pre-trained on a diverse mixture of robot demonstrations, vision-language tasks, and internet video data.

Key Results:

  • In-Context Adaptation: MEM enables robots to adapt manipulation strategies based on recent failures. In evaluation, this led to a +62% success rate increase in opening refrigerators with unknown hinge directions and a +11% increase in picking up chopsticks at variable heights.
  • Long-Horizon Tasks: The model successfully performed 15-minute tasks like ‘Recipe Setup’ (retrieving ingredients from multiple locations) and ‘Kitchen Cleaning’ (washing dishes and wiping counters). Memory-less VLAs failed these tasks significantly more often.
  • Efficiency: The video encoder allows the model to process up to 16 observation frames (spanning ~1 minute) while remaining under critical real-time inference thresholds on a single NVIDIA H100 GPU.

MEM demonstrates that combining dense, short-term visual tokens with compressed, long-term language summaries allows VLAs to scale their ‘working memory’ without incurring prohibitive computational costs.


Check out the Paper and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

The post Physical Intelligence Team Unveils MEM for Robots: A Multi-Scale Memory System Giving Gemma 3-4B VLAs 15-Minute Context for Complex Tasks appeared first on MarkTechPost.

Credit: Source link

ShareTweetSendSharePin

Related Posts

OpenAI Releases a Model Misalignment Disclosure Framework With 3 Review Tracks and 6 Incident Reports From RL Training
AI & Technology

OpenAI Releases a Model Misalignment Disclosure Framework With 3 Review Tracks and 6 Incident Reports From RL Training

September 17, 2026
An iOS 27 Bug Can Temporarily Freeze Your iPhone
AI & Technology

An iOS 27 Bug Can Temporarily Freeze Your iPhone

September 17, 2026
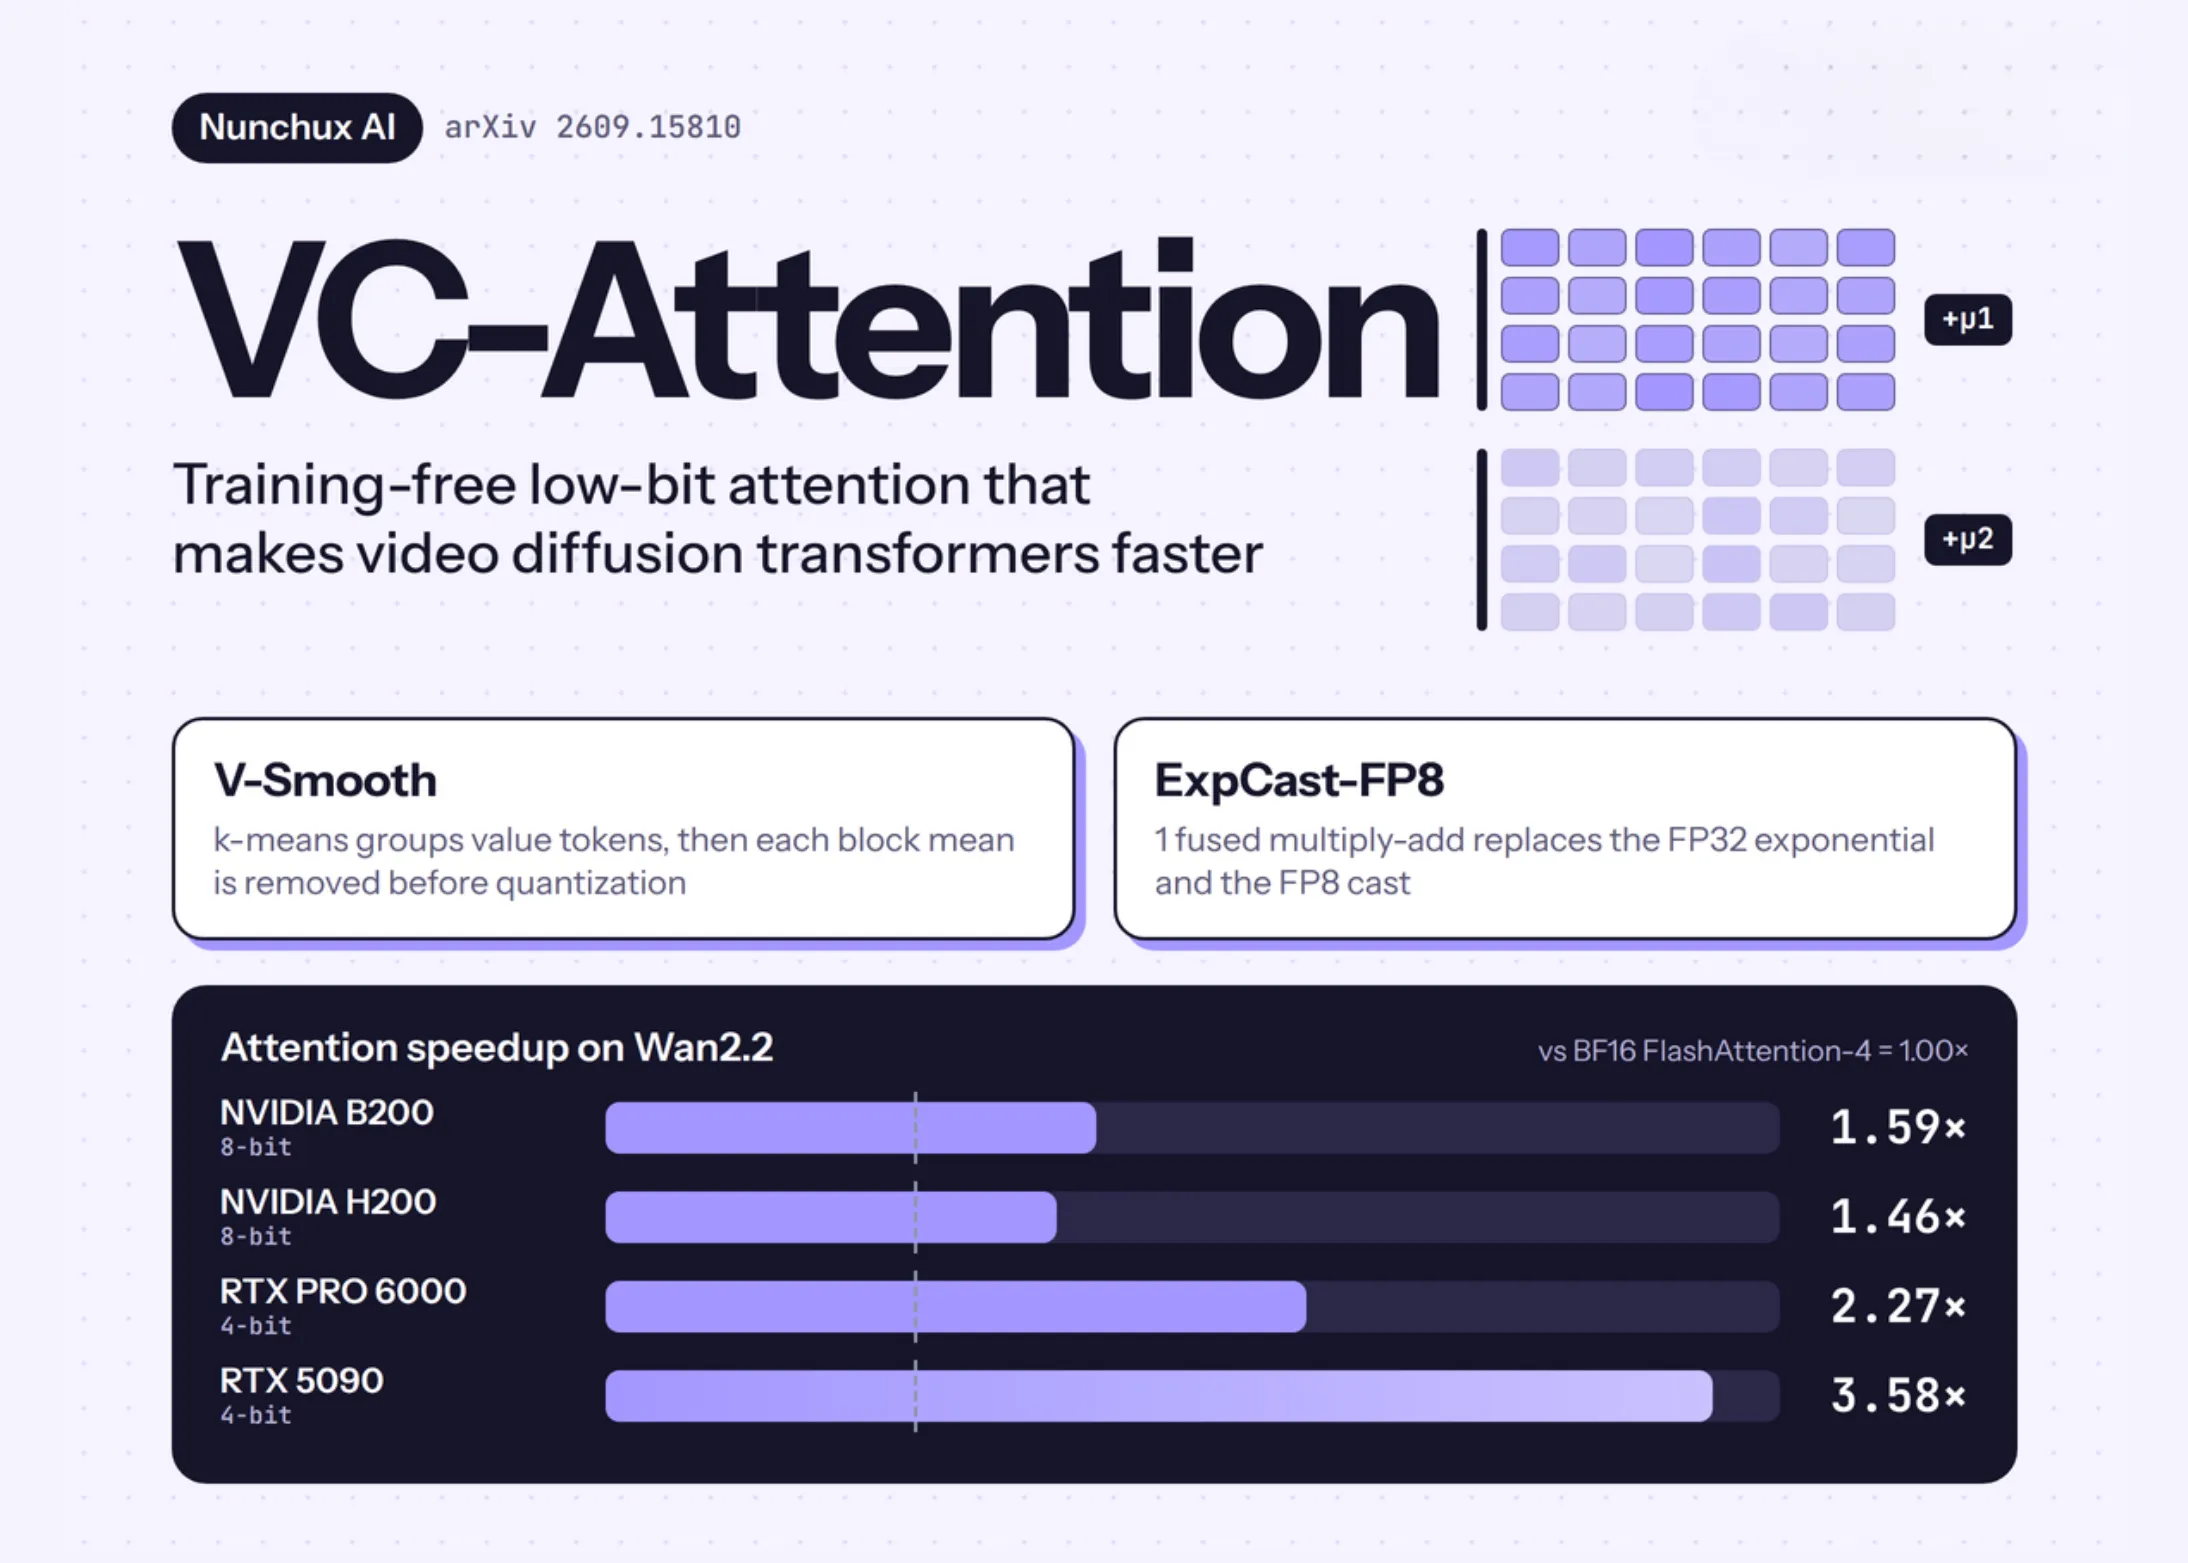
Nunchux AI Introduces VC-Attention: A Training-Free Low-Bit Attention Kernel That Speeds Up Video Diffusion Transformers
AI & Technology

Nunchux AI Introduces VC-Attention: A Training-Free Low-Bit Attention Kernel That Speeds Up Video Diffusion Transformers

September 17, 2026
House Passes Ratepayer Protection Act on Data Center Power Costs – Unite.AI
AI & Technology

House Passes Ratepayer Protection Act on Data Center Power Costs – Unite.AI

September 16, 2026
Next Post
WARNING: TRUMP NEW THREAT TO BIG BANKS…

WARNING: TRUMP NEW THREAT TO BIG BANKS...

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Morning News NOW Full Episode – Sept. 8

Morning News NOW Full Episode – Sept. 8

September 16, 2026
Teen celebrates finishing cancer treatment with surprise from friends

Teen celebrates finishing cancer treatment with surprise from friends

September 17, 2026
Kushner and Witkoff meet with Zelenskyy in Kyiv

Kushner and Witkoff meet with Zelenskyy in Kyiv

September 16, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!