
• bitcoinBitcoin(BTC)$81,850.000.88%
  • ethereumEthereum(ETH)$2,649.451.72%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$766.880.87%
  • rippleXRP(XRP)$1.433.24%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$111.70-0.30%
  • tronTRON(TRX)$0.338921-0.25%
  • zcashZcash(ZEC)$1,512.222.83%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.14%
  • HyperliquidHyperliquid(HYPE)$93.001.65%
  • dogecoinDogecoin(DOGE)$0.0893821.50%
  • moneroMonero(XMR)$570.41-0.93%
  • whitebitWhiteBIT Coin(WBT)$83.570.52%
  • RainRain(RAIN)$0.0139565.51%
  • USDSUSDS(USDS)$1.00-0.03%
  • chainlinkChainlink(LINK)$12.623.46%
  • cardanoCardano(ADA)$0.2286383.88%
  • leo-tokenLEO Token(LEO)$8.930.65%
  • stellarStellar(XLM)$0.1986163.20%
  • uniswapUniswap(UNI)$8.890.28%
  • bitcoin-cashBitcoin Cash(BCH)$255.621.79%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • nearNEAR Protocol(NEAR)$3.60-2.14%
  • daiDai(DAI)$1.000.00%
  • litecoinLitecoin(LTC)$58.023.14%
  • CantonCanton(CC)$0.1118432.34%
  • USD1USD1(USD1)$1.000.01%
  • avalanche-2Avalanche(AVAX)$9.6519.04%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.391.26%
  • hedera-hashgraphHedera(HBAR)$0.0815453.19%
  • suiSui(SUI)$0.855.41%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.0000060.70%
  • BittensorBittensor(TAO)$271.688.36%
  • MemeCoreMemeCore(M)$1.33-3.45%
  • crypto-com-chainCronos(CRO)$0.0600961.42%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.03%
  • tether-goldTether Gold(XAUT)$4,373.80-0.11%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • okbOKB(OKB)$119.382.63%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.09%
  • aaveAave(AAVE)$142.672.78%
  • OndoOndo(ONDO)$0.4317718.11%
  • mantleMantle(MNT)$0.644.26%
  • EthenaEthena(ENA)$0.20440223.61%
  • AsterAster(ASTER)$0.761.31%
  • Pump.funPump.fun(PUMP)$0.004123-4.29%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

OpenAI Releases a Research Preview of GPT‑5.3-Codex-Spark: A 15x Faster AI Coding Model Delivering Over 1000 Tokens Per Second on Cerebras Hardware

February 12, 2026
in AI & Technology
Reading Time: 6 mins read
A A
OpenAI Releases a Research Preview of GPT‑5.3-Codex-Spark: A 15x Faster AI Coding Model Delivering Over 1000 Tokens Per Second on Cerebras Hardware
ShareShareShareShareShare

OpenAI just launched a new research preview called GPT-5.3 Codex-Spark. This model is built for 1 thing: extreme speed. While the standard GPT-5.3 Codex focuses on deep reasoning, Spark is designed for near-instant response times. It is the result of a deep hardware-software integration between OpenAI and Cerebras.

The results are game-changing. Spark is 15x faster than the flagship GPT-5.3 Codex. It consistently delivers over 1000 tokens per second. This speed effectively removes the delay between a developer’s thought and the model’s code output.

YOU MAY ALSO LIKE

How To Block And Unblock A Number On Your Android Phone

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

The Hardware: Wafer-Scale Engineering

The massive performance jump is powered by the Cerebras Wafer-Scale Engine 3 (WSE-3). Traditional AI models run on clusters of small GPUs. These GPUs must communicate to each other over cables, which creates a ‘bottleneck.’ This bottleneck slows down the speed of the model.

The WSE-3 is different. It is a single, giant chip the size of a whole silicon wafer. Because the entire model lives on 1 piece of silicon, there are no cables to slow it down. This architecture provides:

  • Massive on-chip memory.
  • Ultra-high bandwidth.
  • Low-latency compute.

By using the Cerebras CS-3 system, OpenAI can run inference at speeds that traditional GPU clusters cannot reach.

Software Optimizations and Low Latency

Speed is not just about the chip. OpenAI re-engineered the way the model communicates with your computer. They moved away from traditional request methods and introduced a persistent WebSocket connection.

This change leads to several technical improvements:

  1. Round-Trip Time (RTT): Client-server overhead is reduced by 80%.
  2. Time-to-First-Token (TTFT): This is improved by 50%, meaning the code starts appearing almost the moment you hit enter.
  3. Per-Token Overhead: Internal processing time per token is cut by 30%.

These optimizations allow for ‘Real-Time Steering.’ You can interrupt the model while it is typing and redirect its logic without waiting for the full block to finish.

The Trade-offs: Speed vs. Reasoning

GPT-5.3 Codex-Spark is optimized for throughput, not deep complexity. It is a ‘smaller’ model than the flagship GPT-5.3 Codex. Because of this, it has lower reasoning depth.

https://openai.com/index/introducing-gpt-5-3-codex-spark/

Devs should be aware of these performance differences:

  • Benchmarks: Spark scores lower on SWE-Bench Pro and Terminal-Bench 2.0 compared to the flagship model. It may struggle with very complex, multi-file architecture changes.
  • Security: Under OpenAI’s Preparedness Framework, the flagship GPT-5.3 Codex is rated as ‘High’ capability for cybersecurity. Spark does not meet this high threshold. It should not be used for sensitive security logic or autonomous authentication tasks.

Quick Specs and Access

Spark is available now for ChatGPT Pro users and developers. You can access it through the following tools:

  • Codex App: Use the model picker to select ‘Spark.’
  • VS Code Extension: Integrated directly into the composer.
  • CLI: Access it via the command codex --model gpt-5.3-codex-spark.
Feature GPT-5.3 Codex-Spark GPT-5.3 Codex (Flagship)
Tokens per Second 1000+ ~70
Context Window 128k 128k
Hardware Cerebras WSE-3 NVIDIA GPU Clusters
Best For Fast Iteration Deep Reasoning / Security

Key Takeaways

  • Great Speed: Spark is 15x faster than the flagship GPT-5.3 Codex, delivering an unprecedented throughput of over 1,000 tokens per second to enable near-instant code generation.
  • Custom Silicon Infrastructure: This is OpenAI’s first model to run on Cerebras Wafer-Scale Engine 3 (WSE-3) hardware rather than traditional NVIDIA GPUs, using ‘wafer-scale’ memory to eliminate data bottlenecks.
  • Drastic Latency Reduction: The integration of a persistent WebSocket connection reduces client-server round-trip overhead by 80% and improves the time-to-first-token by 50%.
  • Real-Time Steering: Designed for ‘micro-iterations,’ the model’s speed allows developers to interrupt and redirect logic in real-time, shifting the workflow from batch-processing to live pair-programming.
  • Targeted Capability Trade-offs: While faster, Spark has lower reasoning depth than the flagship model and does not meet the ‘High capability’ threshold for cybersecurity in OpenAI’s Preparedness Framework, making it unsuitable for sensitive auth or security tasks.

Check out the Technical details here. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

Credit: Source link

ShareTweetSendSharePin

Related Posts

How To Block And Unblock A Number On Your Android Phone
AI & Technology

How To Block And Unblock A Number On Your Android Phone

September 19, 2026
Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies
AI & Technology

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

September 19, 2026
What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI
AI & Technology

What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI

September 19, 2026
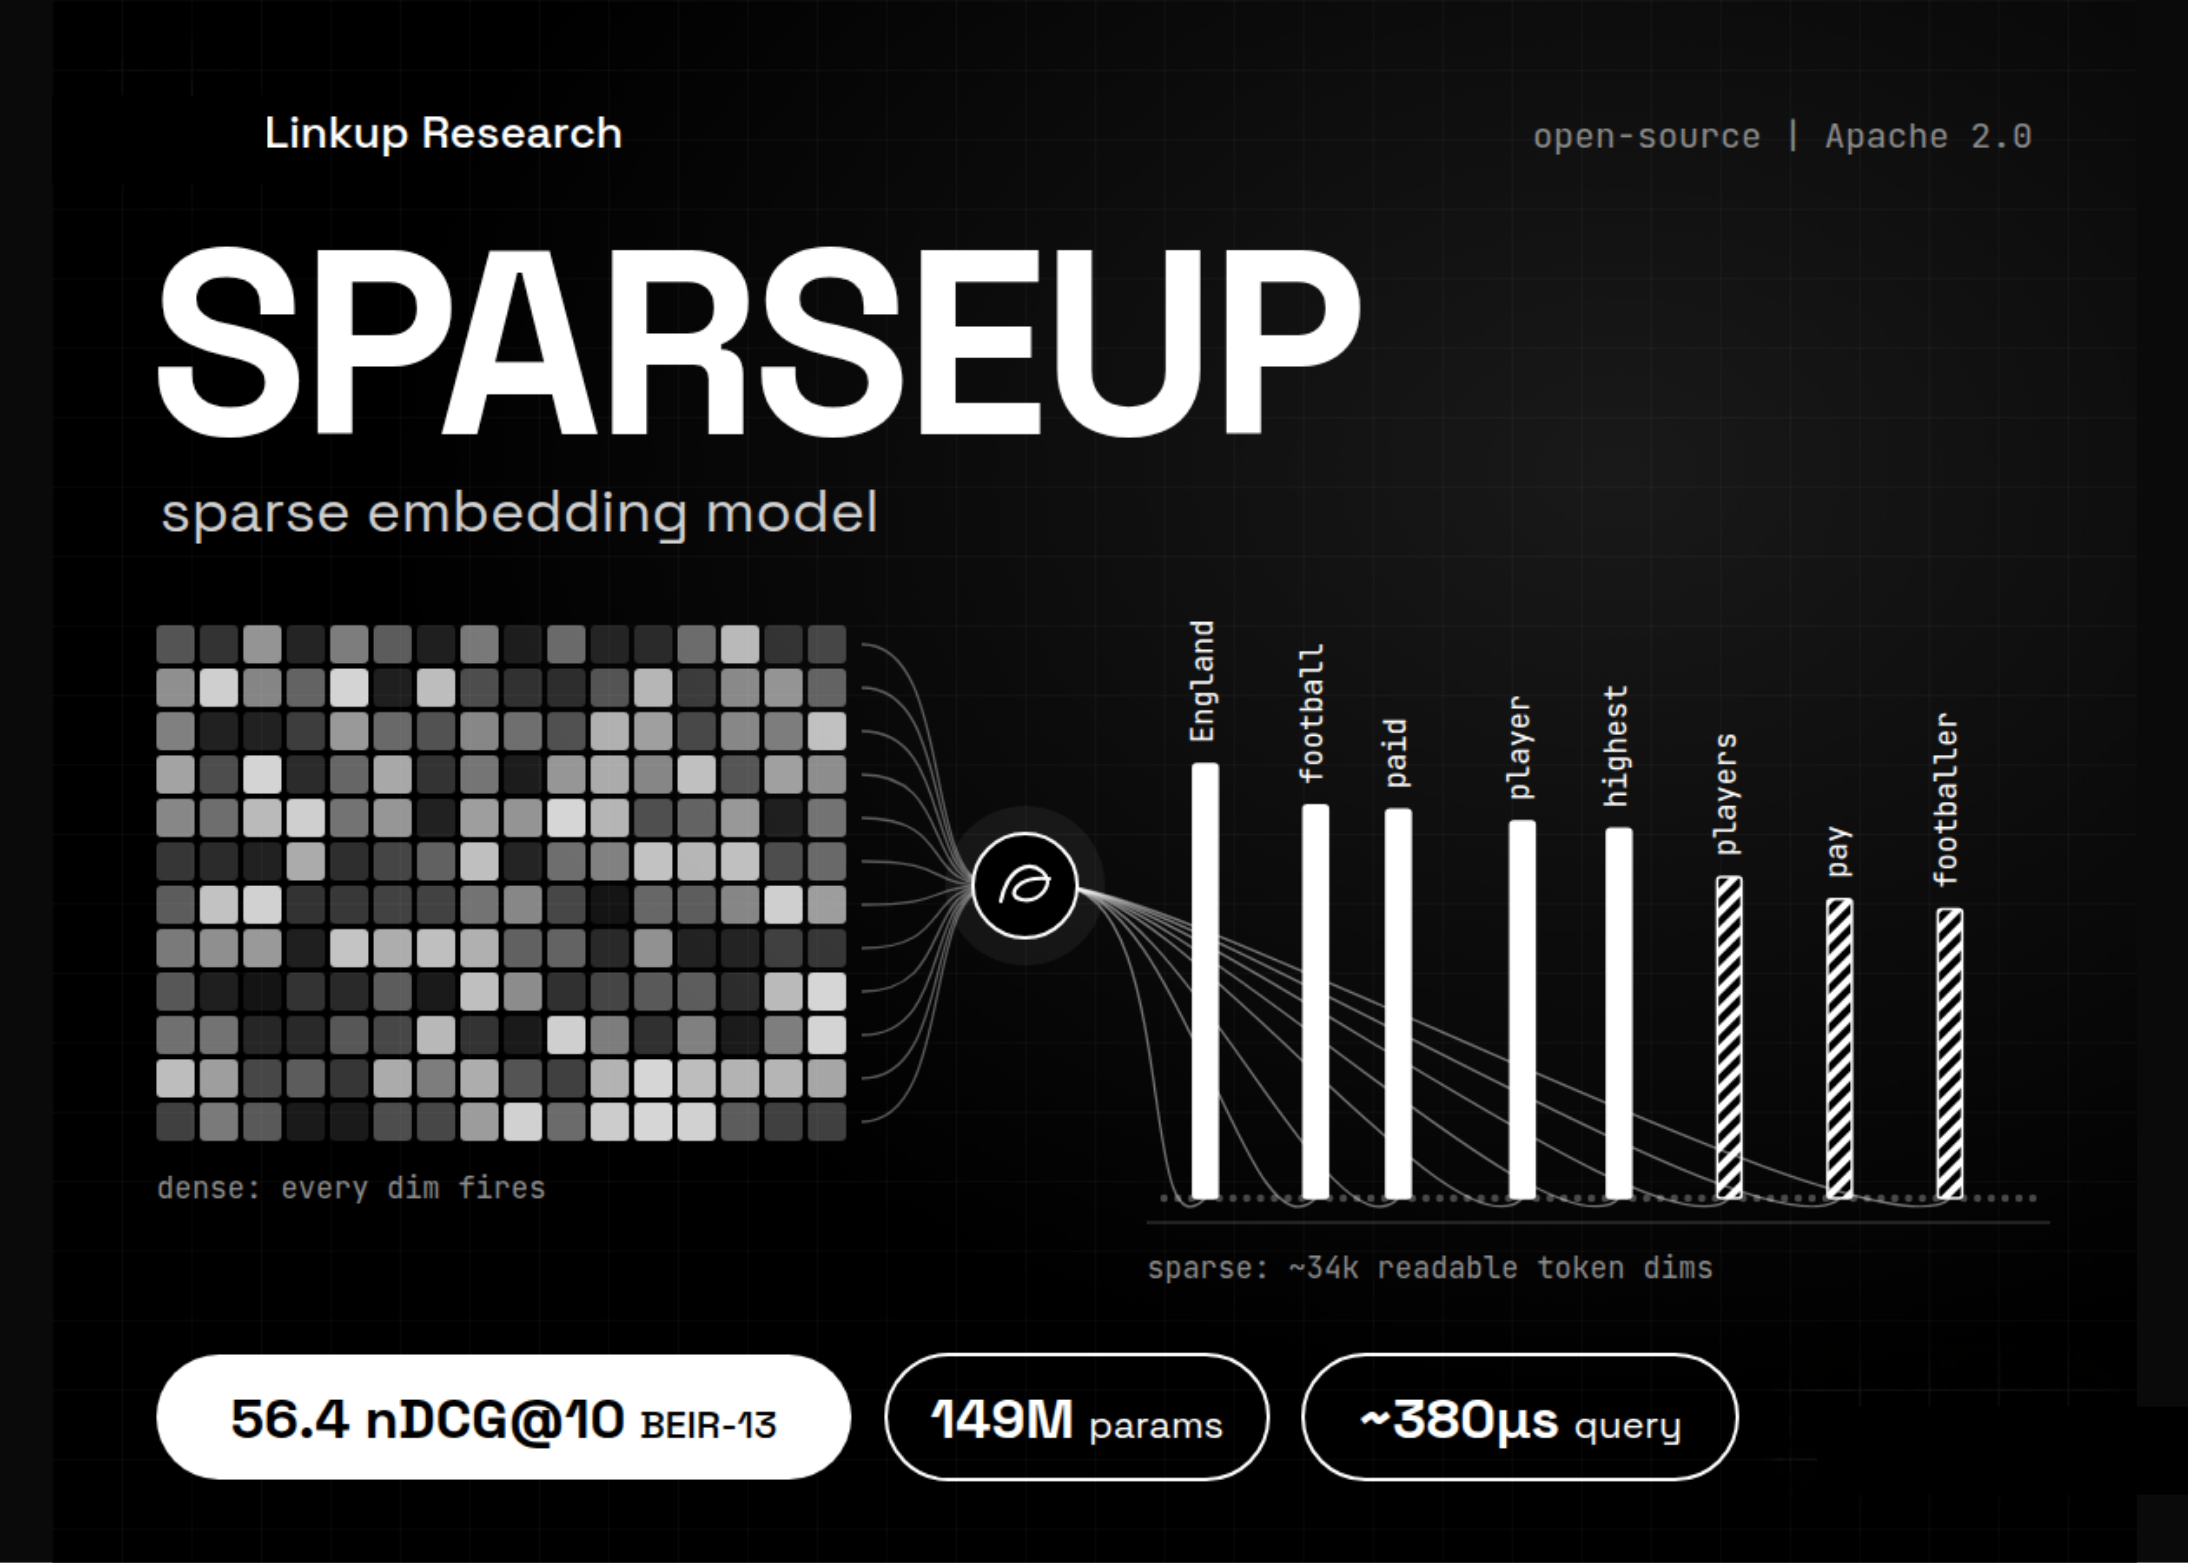
Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model
AI & Technology

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

September 19, 2026
Next Post
Why the shakeup at the DOJ’s antitrust division is a victory for free-market Republicans

Why the shakeup at the DOJ’s antitrust division is a victory for free-market Republicans

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Billy Joel reveals he underwent brain surgery

Billy Joel reveals he underwent brain surgery

September 14, 2026
Should You Buy the Dip in 2026? Kevin Mahn Plays This or That

Should You Buy the Dip in 2026? Kevin Mahn Plays This or That

September 16, 2026
Critics say ‘fashion slop’ is coming for the industry’s design creativity

Critics say ‘fashion slop’ is coming for the industry’s design creativity

September 14, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!