• bitcoinBitcoin(BTC)$83,006.00-2.13%
  • ethereumEthereum(ETH)$2,645.68-2.66%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$761.68-2.14%
  • rippleXRP(XRP)$1.48-4.22%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$118.23-4.94%
  • tronTRON(TRX)$0.333580-0.02%
  • zcashZcash(ZEC)$1,547.32-6.99%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.060.00%
  • HyperliquidHyperliquid(HYPE)$88.92-4.77%
  • dogecoinDogecoin(DOGE)$0.092738-5.34%
  • chainlinkChainlink(LINK)$13.71-4.77%
  • moneroMonero(XMR)$528.64-5.40%
  • whitebitWhiteBIT Coin(WBT)$82.74-2.19%
  • USDSUSDS(USDS)$1.00-0.01%
  • cardanoCardano(ADA)$0.243215-5.49%
  • RainRain(RAIN)$0.012507-1.60%
  • leo-tokenLEO Token(LEO)$9.010.02%
  • stellarStellar(XLM)$0.207718-5.42%
  • nearNEAR Protocol(NEAR)$5.13-4.66%
  • bitcoin-cashBitcoin Cash(BCH)$308.10-10.89%
  • uniswapUniswap(UNI)$9.11-9.28%
  • CantonCanton(CC)$0.1379031.47%
  • litecoinLitecoin(LTC)$70.42-2.21%
  • Ethena USDeEthena USDe(USDE)$1.000.00%
  • avalanche-2Avalanche(AVAX)$10.42-6.80%
  • suiSui(SUI)$1.19-6.36%
  • daiDai(DAI)$1.000.02%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.632.07%
  • USD1USD1(USD1)$1.00-0.01%
  • hedera-hashgraphHedera(HBAR)$0.0974161.68%
  • quant-networkQuant(QNT)$265.3854.65%
  • BitwayBitway(BTW)$1.2921.74%
  • BittensorBittensor(TAO)$302.89-9.25%
  • shiba-inuShiba Inu(SHIB)$0.000006-6.03%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • crypto-com-chainCronos(CRO)$0.064060-5.52%
  • tether-goldTether Gold(XAUT)$4,160.90-2.77%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • EthenaEthena(ENA)$0.265469-2.23%
  • MemeCoreMemeCore(M)$1.15-6.29%
  • OndoOndo(ONDO)$0.52-3.40%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • okbOKB(OKB)$116.74-4.33%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.11%
  • aaveAave(AAVE)$147.59-5.83%
  • Pump.funPump.fun(PUMP)$0.0048809.45%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

OpenAI launches web crawling GPTBot, sparking blocking effort by website owners and creators

August 8, 2023
in AI & Technology
Reading Time: 5 mins read
A A
OpenAI launches web crawling GPTBot, sparking blocking effort by website owners and creators
ShareShareShareShareShare

Head over to our on-demand library to view sessions from VB Transform 2023. Register Here


Without fanfare or an official announcement, ChatGPT maker OpenAI launched a new website crawling bot this week for scanning website content to train its large language models (LLMs). But after news of the bot broke, a revolt ensued, as website owners and creators quickly traded tips on how to block GPTBot from scraping their site’s data.

YOU MAY ALSO LIKE

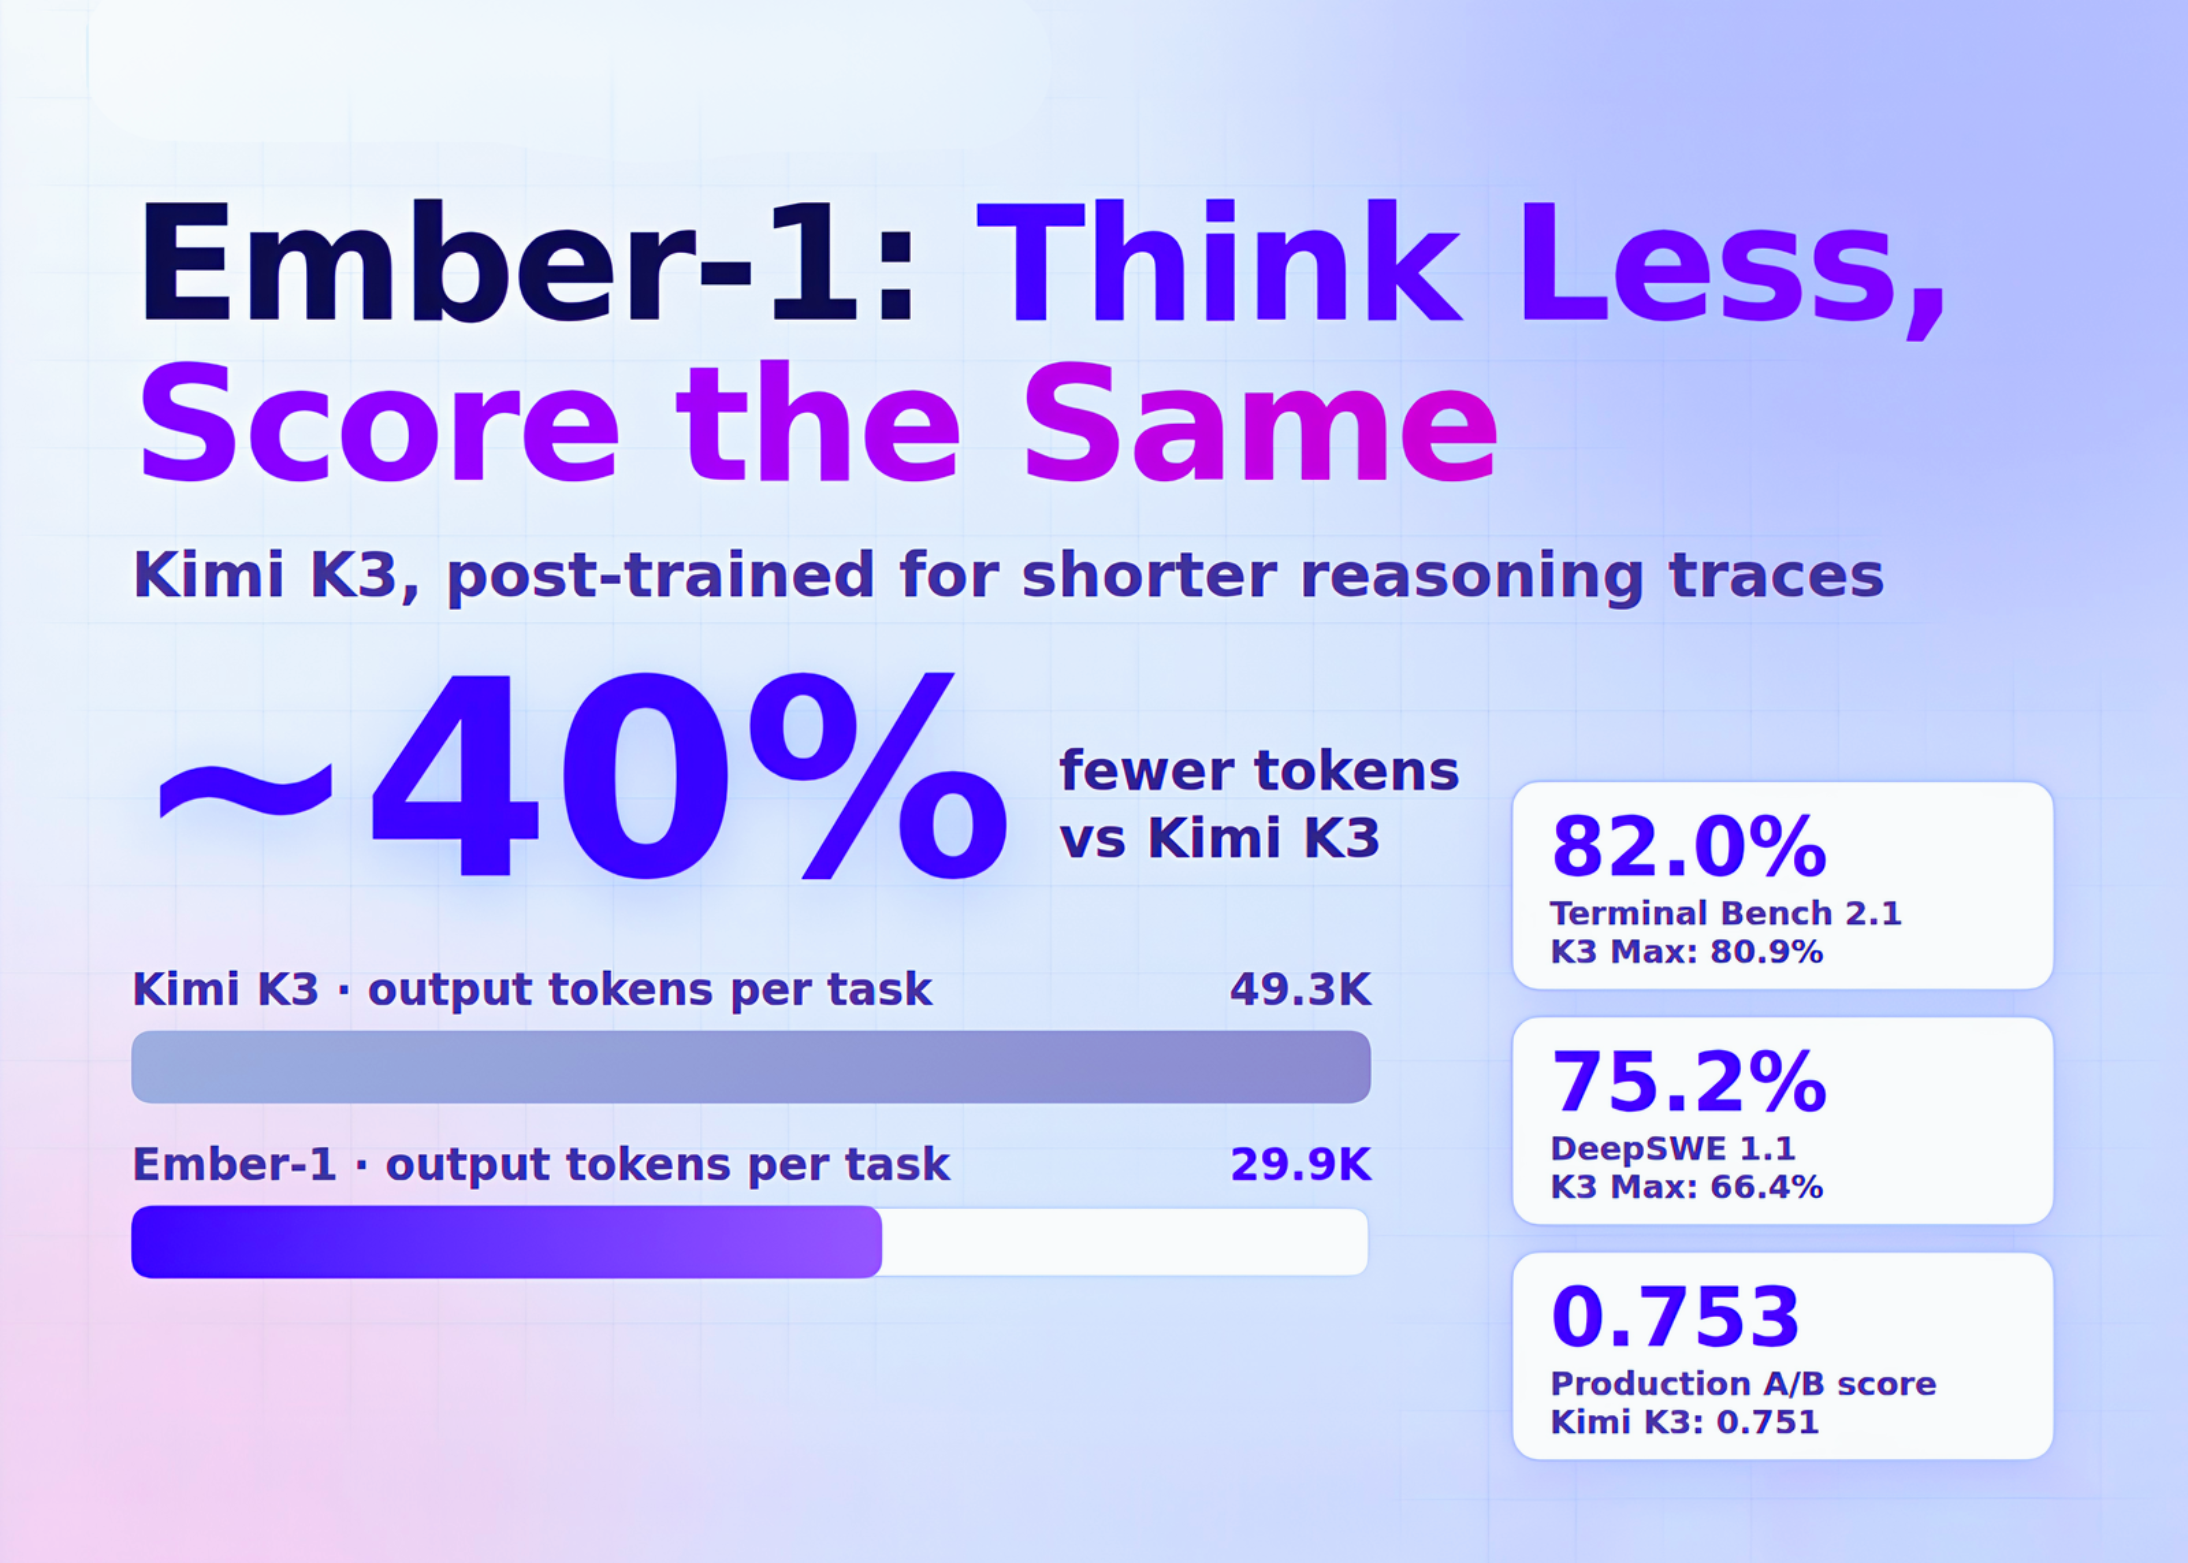
Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens

You Can Now Preorder The Tiny Boox Picco Ereader

When OpenAI added the GPTBot support page, it also introduced a way to block the service from scraping your website. A small modification to a website’s robots.txt file would stop the content from being shared with OpenAI. However, due to how extensively the web is scraped otherwise, it’s unclear if simply blocking GPTBot will completely stop content from being included in LLM training data.

“We periodically collect public data from the internet which may be used to improve the capabilities, accuracy, and safety of future models,” an OpenAI spokesperson said in an email. “On our website, we provide instructions on how to disallow our collection bot from accessing a site. Web pages are filtered to remove sources that have paywalls, are known to gather personally identifiable information (PII), or have text that violates our policies.”

Websites raise their defenses

Web outlets like The Verge have already added the robots.txt flag to stop the OpenAI model from grabbing content to add to its LLMs. Casey Newton has asked readers of his substack newsletter, Platformer, if he should stop OpenAI from collecting his content. Neil Clarke, editor of sci-fi magazine Clarkesworld, announced on X (formerly known as Twitter) that it would block GPTBot.

Event

VB Transform 2023 On-Demand

Did you miss a session from VB Transform 2023? Register to access the on-demand library for all of our featured sessions.


Register Now

Shortly after GPTBot’s launch became public, OpenAI announced a $395,000 grant and partnership with New York University’s Arthur L. Carter Journalism Institute. Led by former Reuters editor-in-chief Stephen Adler, NYU’s Ethics and Journalism Initiative aims to aid students in developing responsible ways to leverage AI in the news business.

“We are excited about the potential of the new Ethics and Journalism Initiative and very pleased to support its goal of addressing a broad array of challenges journalists face when striving to practice their profession ethically and responsibly, especially those related to the implementation of AI,” said Tom Rubin, OpenAI’s chief of intellectual property and content, in a release on Tuesday.

Rubin did not mention public web scraping—nor the controversy surrounding it—in the release. 

What’s ‘known’ can’t really be forgotten

While a little more control over who gets to use the content on the open net is handy, it’s still unclear how effective simply blocking the GPTBot would be in stopping LLMs from gobbling up content that isn’t locked behind a paywall. LLMs and other generative AI platforms have already used massive collections of public data to train the datasets they currently deploy. 

Awesome!
Most of the big LLMs and Image Generators source a lot of their scraped material from CommonCrawl. ChatGPT, the Meta LLMs and Stable Diffusion used Common Crawl.

They scrape every month, and save it “forever”, but you can block them:https://t.co/NIByP2Jiju

— Benjamin BLM (@stealcase) August 7, 2023

Google’s Colossal Clean Crawled Corpus (C4) data set and nonprofit Common Crawl are well-known collections of training data. If your data or content was captured in those scraping efforts, experts say it’s likely a permanent part of the training information used to enable OpenAI’s ChatGPT, Google’s Bard or Meta’s LLaMA platforms. Services like CommonCrawl do allow for similar robots.txt blocks, but website owners would have needed to implement those changes before any data was collected.

VentureBeat was no exception, with its information found in the C4 training data and available through the Common Crawl datasets as well. 

Questions of web scraping fairness remain before courts

Last year, the U.S. Ninth Circuit of Appeals reasserted the notion that web scraping publicly accessible data is a legal activity that did not contravene the Computer Fraud and Abuse Act (CFAA). 

Despite this, data scraping practices in the name of training AI have come under attack this past year on several fronts. In July, OpenAI was hit with two lawsuits. One, filed in federal court in San Francisco, alleges that OpenAI unlawfully copied book text by not getting consent from copyright holders or offering them credit and compensation. The other claims ChatGPT and DALL-E collect people’s personal data from across the internet in violation of privacy laws.

Further lawsuits have been filed by Sarah Silverman and novelists Christopher Golden and Richard Kadrey alleging that the companies trained their LLMs on the authors’ published works without consent. X and Reddit have also made news around data scraping, and both sought to protect their respective datasets by limiting access to them. In an effort to curb the effects of AI data scraping, X temporarily prevented individuals who were not logged in from viewing tweets on the social media platform and also set rate limits for how many tweets can be viewed. Reddit waged a PR campaign against its moderators and third-party app developers who got caught in the crossfire when it started to charge higher prices for API access in a bid to fend off web scraping of its content.

VentureBeat’s mission is to be a digital town square for technical decision-makers to gain knowledge about transformative enterprise technology and transact. Discover our Briefings.


Credit: Source link

ShareTweetSendSharePin

Related Posts

Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens
AI & Technology

Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens

September 28, 2026
You Can Now Preorder The Tiny Boox Picco Ereader
AI & Technology

You Can Now Preorder The Tiny Boox Picco Ereader

September 28, 2026
20 Agentic Use Cases of TypeSafe AI’s Jev
AI & Technology

20 Agentic Use Cases of TypeSafe AI’s Jev

September 28, 2026
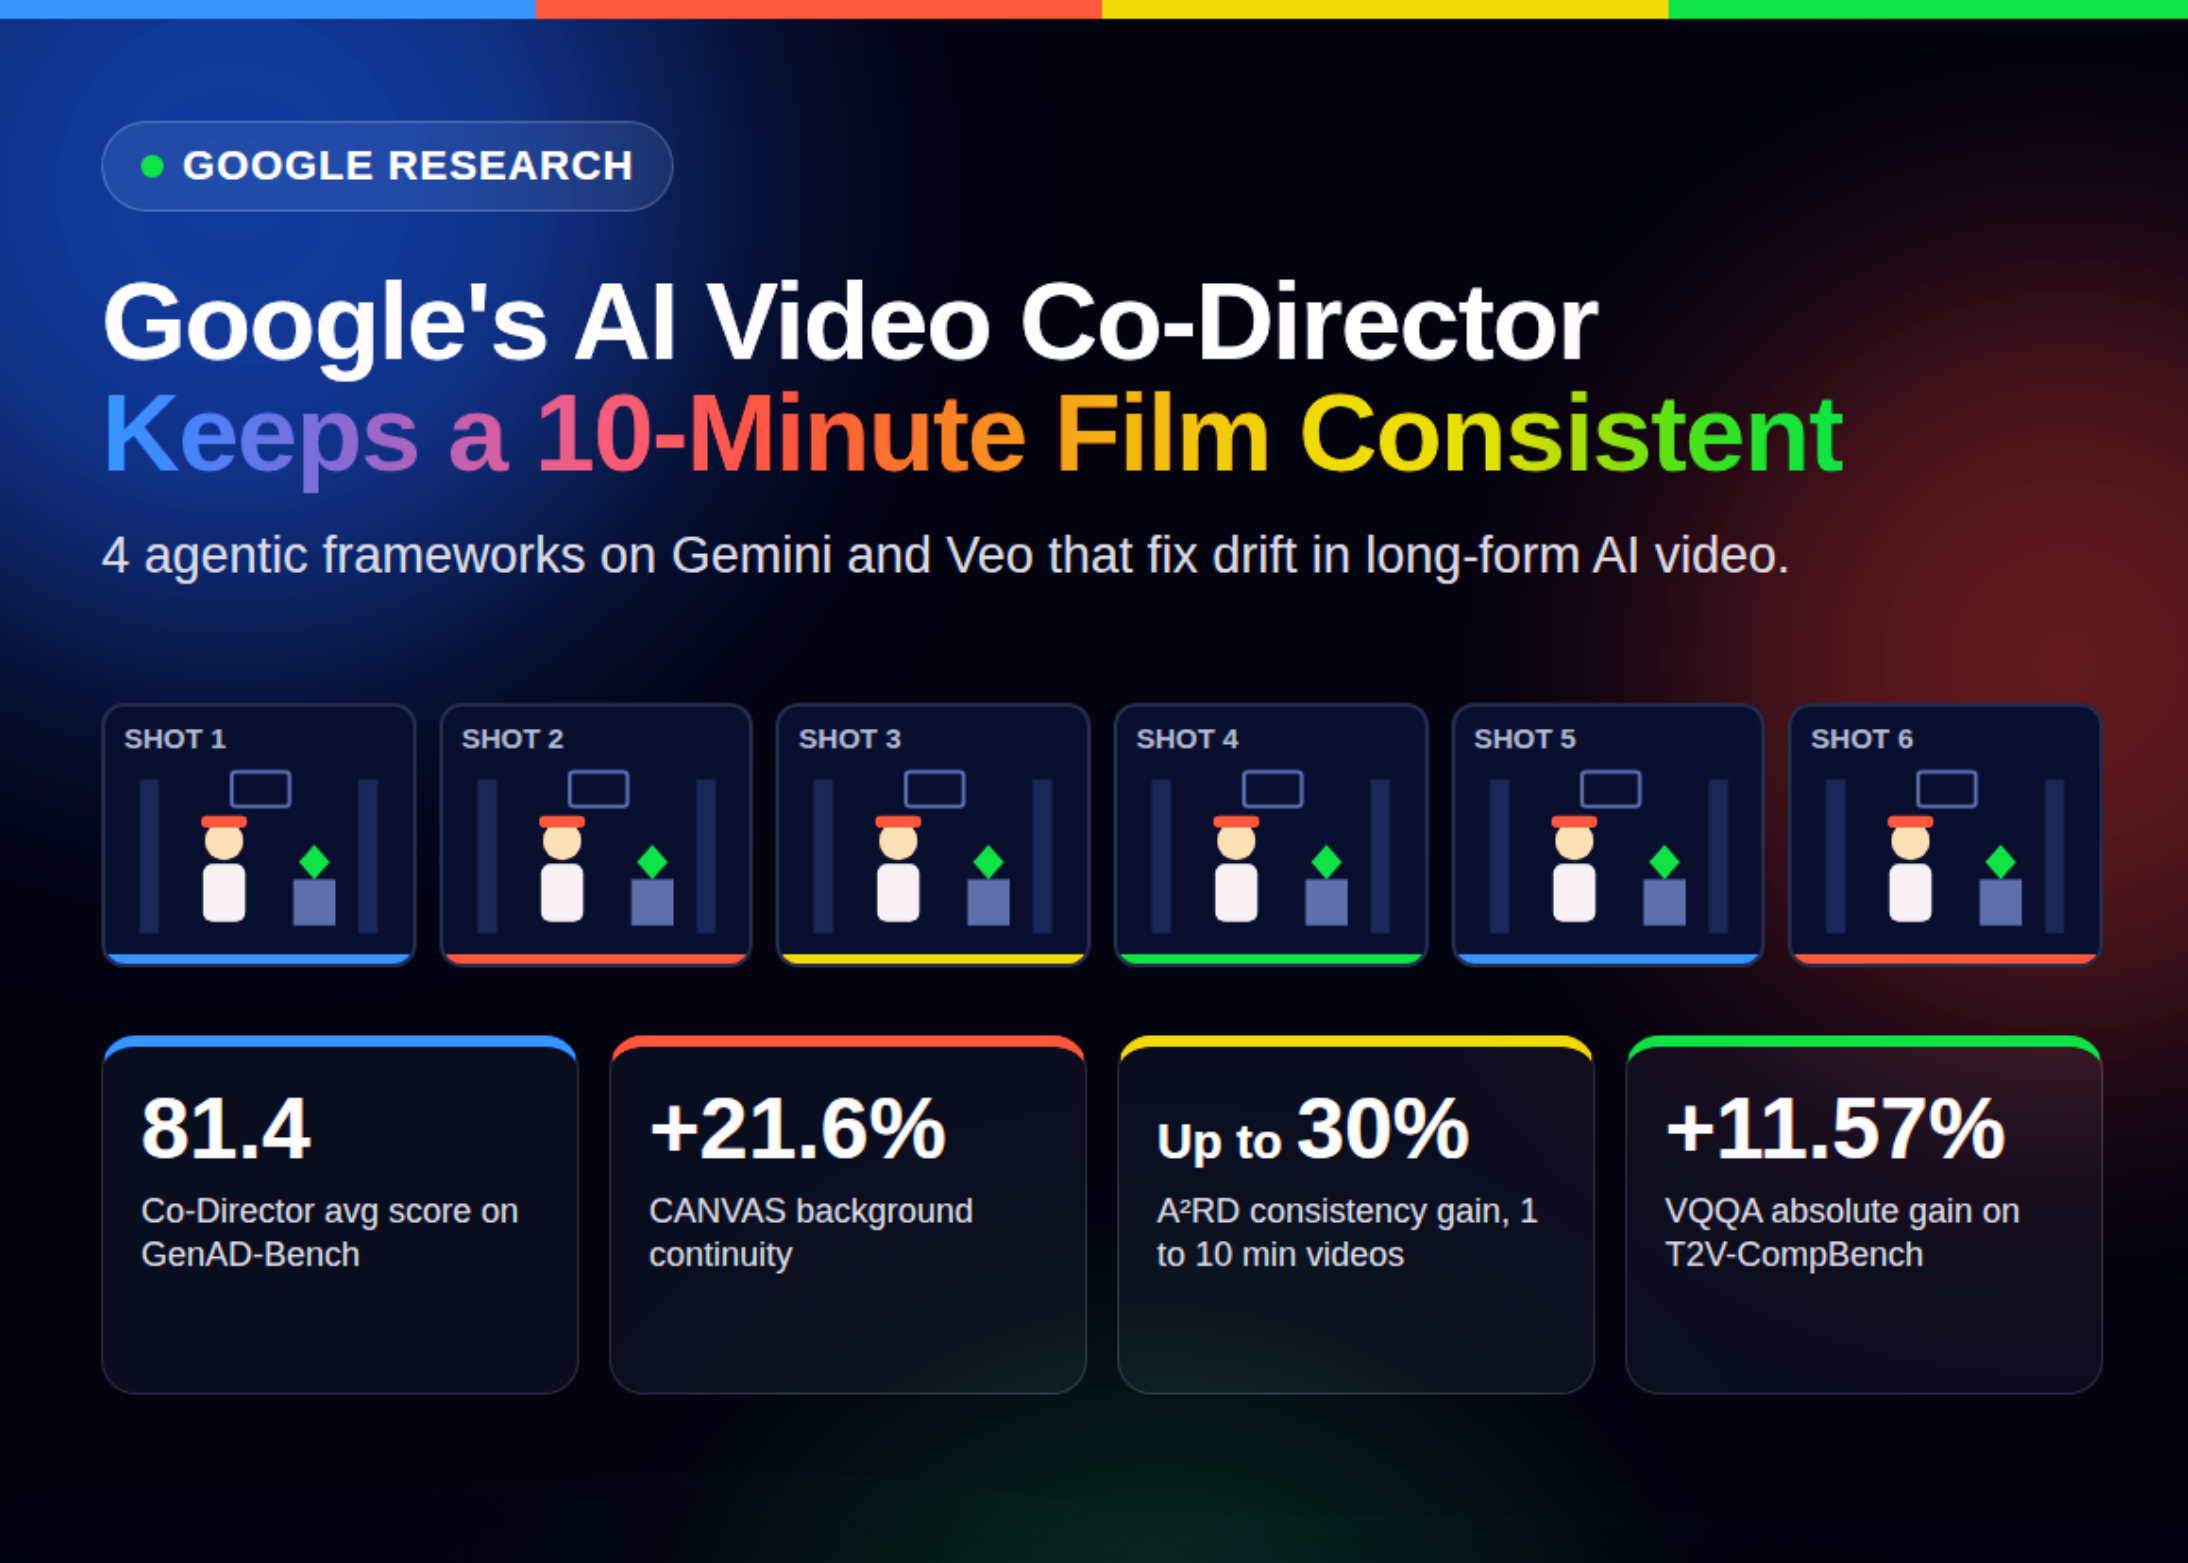
Google Research Introduces an AI Video Co-Director: 4 Agentic Frameworks for Coherent, Minutes-Long Video Generation
AI & Technology

Google Research Introduces an AI Video Co-Director: 4 Agentic Frameworks for Coherent, Minutes-Long Video Generation

September 28, 2026
Next Post
Coverage Initiation for American Express and Coach, Upgrade for Corning

Coverage Initiation for American Express and Coach, Upgrade for Corning

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Cracker Barrel upgrades three popular menu items

Cracker Barrel upgrades three popular menu items

September 24, 2026
What the jury could decide in Clancy murder trial

What the jury could decide in Clancy murder trial

September 22, 2026
Paramount wins Warner Bros takeover after settling states, union lawsuits – Reuters

Paramount wins Warner Bros takeover after settling states, union lawsuits – Reuters

September 21, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!