
• bitcoinBitcoin(BTC)$78,325.001.10%
  • ethereumEthereum(ETH)$2,317.401.19%
  • tetherTether(USDT)$1.000.04%
  • binancecoinBNB(BNB)$699.870.18%
  • rippleXRP(XRP)$1.28-0.41%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$92.81-0.32%
  • tronTRON(TRX)$0.318958-1.06%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.24%
  • zcashZcash(ZEC)$1,288.897.52%
  • HyperliquidHyperliquid(HYPE)$84.24-1.12%
  • moneroMonero(XMR)$642.732.95%
  • dogecoinDogecoin(DOGE)$0.074761-0.47%
  • USDSUSDS(USDS)$1.000.02%
  • whitebitWhiteBIT Coin(WBT)$75.250.88%
  • leo-tokenLEO Token(LEO)$9.330.42%
  • chainlinkChainlink(LINK)$11.15-0.89%
  • cardanoCardano(ADA)$0.189881-0.58%
  • stellarStellar(XLM)$0.162850-1.89%
  • bitcoin-cashBitcoin Cash(BCH)$273.68-0.84%
  • nearNEAR Protocol(NEAR)$4.023.33%
  • Ethena USDeEthena USDe(USDE)$1.000.02%
  • daiDai(DAI)$1.000.01%
  • uniswapUniswap(UNI)$7.32-0.69%
  • RainRain(RAIN)$0.006022-5.92%
  • litecoinLitecoin(LTC)$54.68-0.21%
  • CantonCanton(CC)$0.0975830.99%
  • avalanche-2Avalanche(AVAX)$8.680.95%
  • suiSui(SUI)$0.901.26%
  • USD1USD1(USD1)$1.000.11%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.171.52%
  • tether-goldTether Gold(XAUT)$4,027.991.94%
  • hedera-hashgraphHedera(HBAR)$0.0704870.38%
  • quant-networkQuant(QNT)$198.700.54%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • shiba-inuShiba Inu(SHIB)$0.0000050.58%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • BittensorBittensor(TAO)$229.100.84%
  • Ripple USDRipple USD(RLUSD)$1.00-0.02%
  • crypto-com-chainCronos(CRO)$0.050763-0.09%
  • EthenaEthena(ENA)$0.1791224.41%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.16%
  • okbOKB(OKB)$107.92-1.62%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.0000050.66%
  • aaveAave(AAVE)$130.901.47%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Pump.funPump.fun(PUMP)$0.0043232.34%
  • OndoOndo(ONDO)$0.3989632.17%
  • MemeCoreMemeCore(M)$0.84-1.99%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

NVIDIA Researchers Propose Reinforcement Learning Pretraining (RLP): Reinforcement as a Pretraining Objective for Building Reasoning During Pretraining

October 14, 2025
in AI & Technology
Reading Time: 7 mins read
A A
NVIDIA Researchers Propose Reinforcement Learning Pretraining (RLP): Reinforcement as a Pretraining Objective for Building Reasoning During Pretraining
ShareShareShareShareShare

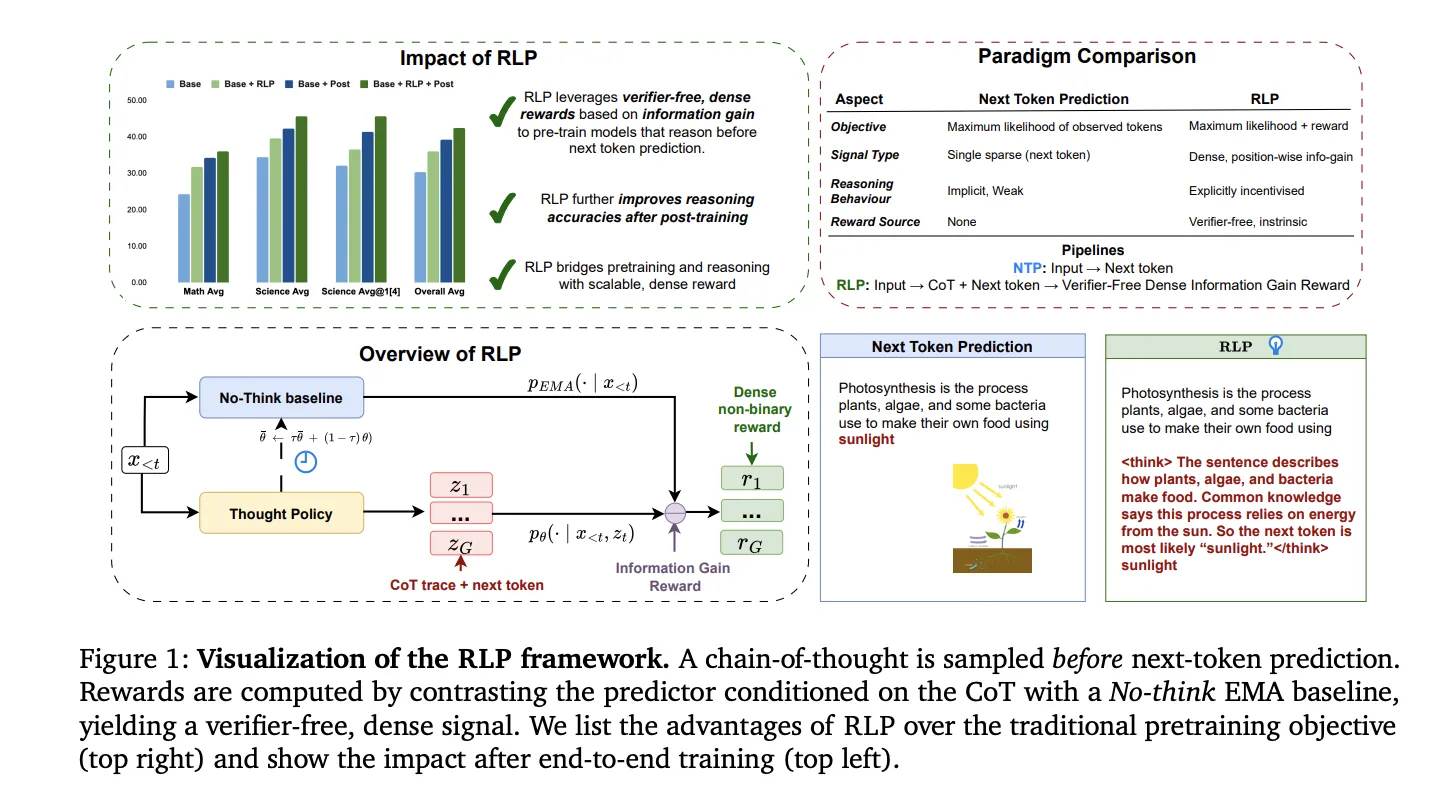
NVIDIA AI has introduced Reinforcement Learning Pretraining (RLP), a training objective that injects reinforcement learning into the pretraining stage rather than deferring it to post-training. The core idea is simple and testable: treat a short chain-of-thought (CoT) as an action sampled before next-token prediction and reward it by the information gain it provides on the observed next token, measured against a no-think EMA baseline. This produces a verifier-free, dense, position-wise reward that can be applied to ordinary text streams at pretraining scale.

https://github.com/NVlabs/RLP/blob/main/pdf/RLP_Reinforcement_as_a_Pretraining_Objective.pdf

Mechanism: Information-Gain Rewards with an EMA Counterfactual

RLP uses a single network (shared parameters) to (1) sample a CoT policy
𝜋
𝜃
(
𝑐
𝑡
∣
𝑥
<
𝑡
)
π
θ
​

(c
t
​

YOU MAY ALSO LIKE

AI Can Surface More Vulnerabilities Than Ever. Humans Still Have to Decide What Comes Next. – Unite.AI

Apple Music’s Upcoming Feature Will Let You Record Yourself Doing Karaoke

∣x
<t
​

) and then (2) score the next token
𝑝
𝜃
(
𝑥
𝑡
∣
𝑥
<
𝑡
,
𝑐
𝑡
)
p
θ
​

(x
t
​

∣x
<t
​

,c
t
​

). A slowly updated EMA teacher
𝑝
𝜙
(
𝑥
𝑡
∣
𝑥
<
𝑡
)
p
ϕ
​

(x
t
​

∣x
<t
​

) provides a no-think counterfactual. The per-token reward is the log-likelihood ratio-

/* <![CDATA[ */
wp.i18n.setLocaleData( { 'text direction\u0004ltr': [ 'ltr' ] } );
/* ]]> */

r(ct​)=logpθ​(xt​∣x<t​,ct​)−logpϕ​(xt​∣x<t​), computed under teacher forcing. Training updates only the thought tokens using a clipped surrogate with per-token importance ratios and group-relative advantages (multiple sampled thoughts per context reduce variance). The objective maximizes expected information gain; theoretical results connect the expected reward to reductions in cross-entropy and bound it via marginalization over thoughts.

Why this matters technically: unlike prior “reinforcement pretraining” variants that rely on sparse, binary correctness signals or proxy filters, RLP’s dense, verifier-free reward attaches position-wise credit wherever thinking improves prediction, enabling updates at every token position in general web-scale corpora without external verifiers or curated answer keys.

Understanding the Results

Qwen3-1.7B-Base: Pretraining with RLP improved the overall math+science average by ~19% vs the base model and ~17% vs compute-matched continuous pretraining (CPT). After identical post-training (SFT + RLVR) across all variants, the RLP-initialized model retained a ~7–8% relative advantage, with the largest gains on reasoning-heavy benchmarks (AIME25, MMLU-Pro).

Nemotron-Nano-12B v2: Applying RLP to a 12B hybrid Mamba-Transformer checkpoint yielded an overall average increase from 42.81% to 61.32% and an absolute +23% gain on scientific reasoning, even though the RLP run used ~200B fewer tokens (training for 19.8T vs 20T tokens; RLP applied for 250M tokens). This highlights data efficiency and architecture-agnostic behavior.
https://github.com/NVlabs/RLP/blob/main/pdf/RLP_Reinforcement_as_a_Pretraining_Objective.pdf

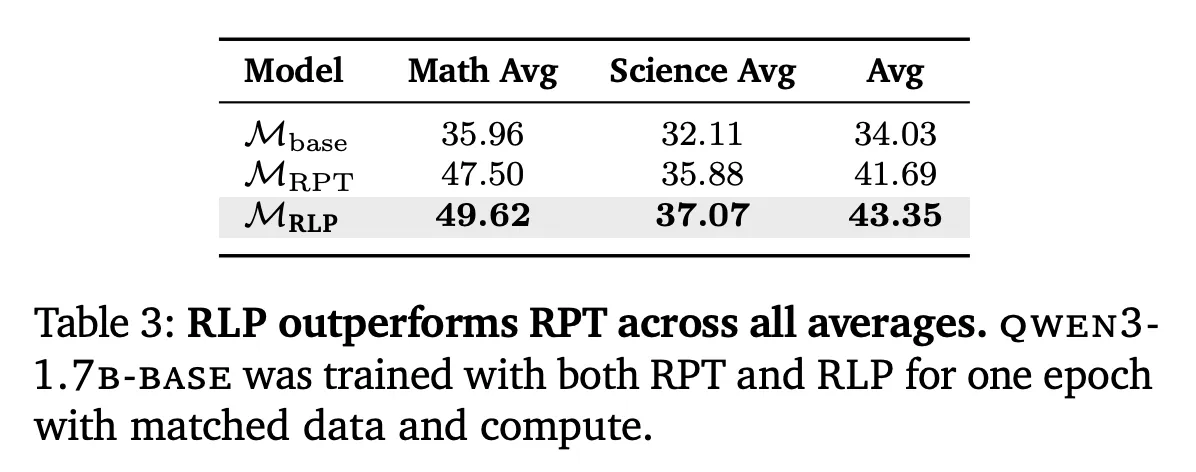
RPT comparison: Under matched data and compute with Omni-MATH-style settings, RLP outperformed RPT on math, science, and overall averages—attributed to RLP’s continuous information-gain reward versus RPT’s sparse binary signal and entropy-filtered tokens.
https://github.com/NVlabs/RLP/blob/main/pdf/RLP_Reinforcement_as_a_Pretraining_Objective.pdf

Positioning vs. Post-Training RL and Data Curation

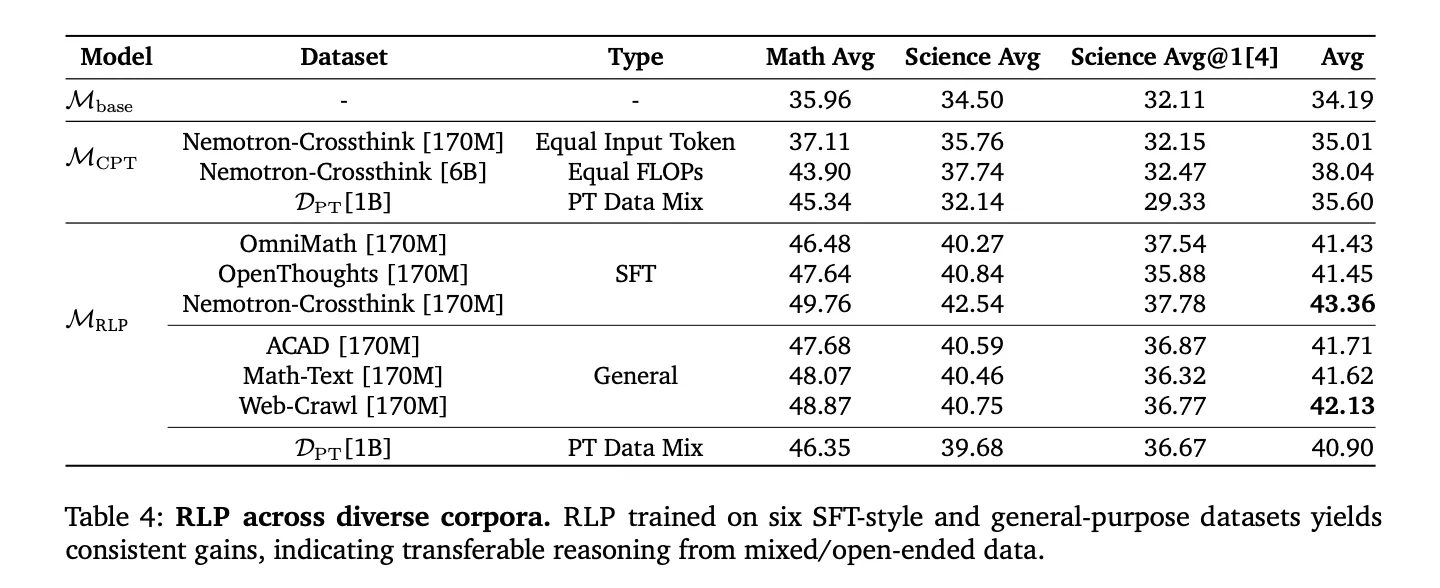
Reinforcement Learning Pretraining (RLP) is orthogonal to post-training pipelines (SFT, RLVR) and shows compounding improvements after standard alignment. Because the reward is computed from model log-evidence rather than external verifiers, it scales to domain-agnostic corpora (web crawl, academic text, textbooks) and SFT-style reasoning corpora, avoiding the brittleness of narrow curated datasets. In compute-matched comparisons (including CPT with 35× more tokens to match FLOPs), RLP still led on overall averages, suggesting the improvements derive from objective design, not budget.

Key Takeaways

  • RLP makes reasoning a pretraining objective: sample a chain-of-thought before next-token prediction and reward it by information gain over a no-think EMA baseline.
  • Verifier-free, dense, position-wise signal: works on ordinary text streams without external graders, enabling scalable pretraining updates on every token.
  • Qwen3-1.7B results: +19% vs Base and +17% vs compute-matched CPT during pretraining; with identical SFT+RLVR, RLP retains ~7–8% gains (largest on AIME25, MMLU-Pro).
  • Nemotron-Nano-12B v2: overall average rises 42.81% → 61.32% (+18.51 pp; ~35–43% rel.) and +23 points on scientific reasoning, using ~200B fewer NTP tokens.
  • Training details that matter: update gradients only on thought tokens with a clipped surrogate and group-relative advantages; more rollouts (≈16) and longer thought lengths (≈2048) help; token-level KL anchoring offers no benefit.

Conclusion

RLP reframes pretraining to directly reward “think-before-predict” behavior using a verifier-free, information-gain signal, yielding durable reasoning gains that persist through identical SFT+RLVR and extend across architectures (Qwen3-1.7B, Nemotron-Nano-12B v2). The method’s objective—contrasting CoT-conditioned likelihood against a no-think EMA baseline—integrates cleanly into large-scale pipelines without curated verifiers, making it a practical upgrade to next-token pretraining rather than a post-training add-on.


Check out the Paper, Code and Project Page. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

The post NVIDIA Researchers Propose Reinforcement Learning Pretraining (RLP): Reinforcement as a Pretraining Objective for Building Reasoning During Pretraining appeared first on MarkTechPost.

Credit: Source link

ShareTweetSendSharePin

Related Posts

AI Can Surface More Vulnerabilities Than Ever. Humans Still Have to Decide What Comes Next. – Unite.AI
AI & Technology

AI Can Surface More Vulnerabilities Than Ever. Humans Still Have to Decide What Comes Next. – Unite.AI

November 4, 2026
Apple Music’s Upcoming Feature Will Let You Record Yourself Doing Karaoke
AI & Technology

Apple Music’s Upcoming Feature Will Let You Record Yourself Doing Karaoke

November 4, 2026
CrowdStrike Targets Rogue AI Agents With Insider Threat Detection – Unite.AI
AI & Technology

CrowdStrike Targets Rogue AI Agents With Insider Threat Detection – Unite.AI

November 4, 2026
Binance Attackers Used Fake Job Interviews To Pull Off .3 Billion Crypto Heist
AI & Technology

Binance Attackers Used Fake Job Interviews To Pull Off $6.3 Billion Crypto Heist

November 4, 2026
Next Post
It’s the end for Windows 10

It’s the end for Windows 10

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
TJX Companies Q3 Preview: Positive Outlook As Discount Retail Retains Appeal (NYSE:TJX)

TJX Companies Q3 Preview: Positive Outlook As Discount Retail Retains Appeal (NYSE:TJX)

November 3, 2026
Tennessee correction chief to resign following failed execution

Tennessee correction chief to resign following failed execution

November 1, 2026
New video of deadly school bus crash

New video of deadly school bus crash

October 30, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!