
• bitcoinBitcoin(BTC)$80,263.00-0.17%
  • ethereumEthereum(ETH)$2,328.14-0.19%
  • tetherTether(USDT)$1.000.02%
  • binancecoinBNB(BNB)$741.200.02%
  • rippleXRP(XRP)$1.29-0.19%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$101.590.73%
  • tronTRON(TRX)$0.3302860.38%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.000.00%
  • zcashZcash(ZEC)$1,230.091.92%
  • HyperliquidHyperliquid(HYPE)$77.361.24%
  • dogecoinDogecoin(DOGE)$0.0771600.79%
  • moneroMonero(XMR)$590.85-2.07%
  • USDSUSDS(USDS)$1.00-0.01%
  • whitebitWhiteBIT Coin(WBT)$77.31-0.19%
  • chainlinkChainlink(LINK)$11.450.69%
  • leo-tokenLEO Token(LEO)$8.97-0.46%
  • cardanoCardano(ADA)$0.2045880.17%
  • stellarStellar(XLM)$0.1697390.39%
  • nearNEAR Protocol(NEAR)$4.562.19%
  • RainRain(RAIN)$0.008083-0.17%
  • bitcoin-cashBitcoin Cash(BCH)$279.462.44%
  • Ethena USDeEthena USDe(USDE)$1.00-0.04%
  • daiDai(DAI)$1.000.02%
  • litecoinLitecoin(LTC)$56.620.52%
  • uniswapUniswap(UNI)$7.044.64%
  • CantonCanton(CC)$0.1006760.08%
  • avalanche-2Avalanche(AVAX)$8.951.49%
  • USD1USD1(USD1)$1.00-0.02%
  • suiSui(SUI)$0.92-0.05%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.22-2.41%
  • hedera-hashgraphHedera(HBAR)$0.0773770.92%
  • tether-goldTether Gold(XAUT)$4,015.640.70%
  • quant-networkQuant(QNT)$218.5520.53%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.05%
  • shiba-inuShiba Inu(SHIB)$0.000005-0.14%
  • BittensorBittensor(TAO)$252.111.47%
  • EthenaEthena(ENA)$0.2055915.21%
  • crypto-com-chainCronos(CRO)$0.054122-0.78%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.05%
  • okbOKB(OKB)$108.871.98%
  • MemeCoreMemeCore(M)$1.009.15%
  • BitwayBitway(BTW)$1.49-12.66%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • aaveAave(AAVE)$135.83-0.22%
  • OndoOndo(ONDO)$0.4126272.52%
  • Pump.funPump.fun(PUMP)$0.0042591.35%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

NVIDIA AI Releases ProRLv2: Advancing Reasoning in Language Models with Extended Reinforcement Learning RL

August 12, 2025
in AI & Technology
Reading Time: 6 mins read
A A
NVIDIA AI Releases ProRLv2: Advancing Reasoning in Language Models with Extended Reinforcement Learning RL
ShareShareShareShareShare

What Is ProRLv2?

ProRLv2 is the latest version of NVIDIA’s Prolonged Reinforcement Learning (ProRL), designed specifically to push the boundaries of reasoning in large language models (LLMs). By scaling reinforcement learning (RL) steps from 2,000 up to 3,000, ProRLv2 systematically tests how extended RL can unlock new solution spaces, creativity, and high-level reasoning that were previously inaccessible—even with smaller models like the 1.5B-parameter Nemotron-Research-Reasoning-Qwen-1.5B-v2.

Key Innovations in ProRLv2

ProRLv2 incorporates several innovations to overcome common RL limitations in LLM training:

  • REINFORCE++- Baseline: A robust RL algorithm that enables long-horizon optimization over thousands of steps, handling the instability typical in RL for LLMs.
  • KL Divergence Regularization & Reference Policy Reset: Periodically refreshes the reference model with the current best checkpoint, allowing stable progress and continued exploration by preventing the RL objective from dominating too early.
  • Decoupled Clipping & Dynamic Sampling (DAPO): Encourages diverse solution discovery by boosting unlikely tokens and focusing learning signals on prompts of intermediate difficulty.
  • Scheduled Length Penalty: Cyclically applied, helping maintain diversity and prevent entropy collapse as training lengthens.
  • Scaling Training Steps: ProRLv2 moves the RL training horizon from 2,000 to 3,000 steps, directly testing how much longer RL can expand reasoning abilities.

How ProRLv2 Expands LLM Reasoning

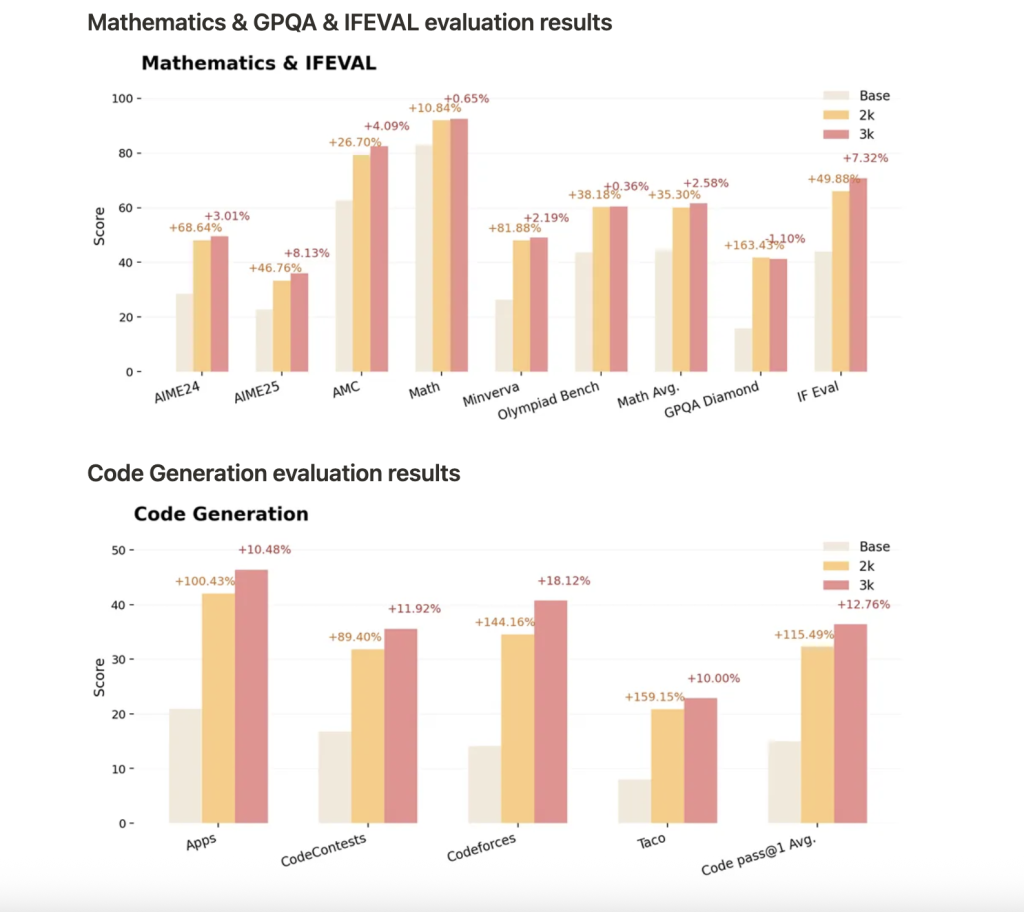
Nemotron-Research-Reasoning-Qwen-1.5B-v2, trained with ProRLv2 for 3,000 RL steps, sets a new standard for open-weight 1.5B models on reasoning tasks, including math, code, science, and logic puzzles:

  • Performance surpasses previous versions and competitors like DeepSeek-R1-1.5B.
  • Sustained gains with more RL steps: Longer training leads to continual improvements, especially on tasks where base models perform poorly, demonstrating genuine expansion in reasoning boundaries.
  • Generalization: Not only does ProRLv2 boost pass@1 accuracy, but it also enables novel reasoning and solution strategies on tasks not seen during training.
  • Benchmarks: Gains include average pass@1 improvements of 14.7% in math, 13.9% in coding, 54.8% in logic puzzles, 25.1% in STEM reasoning, and 18.1% in instruction-following tasks, with further improvements in v2 on unseen and harder benchmarks.
Why It Matters

The major finding of ProRLv2 is that continued RL training, with careful exploration and regularization, reliably expands what LLMs can learn and generalize. Rather than hitting an early plateau or overfitting, prolonged RL allows smaller models to rival much larger ones in reasoning—demonstrating that scaling RL itself is as important as model or dataset size.

YOU MAY ALSO LIKE

GXO, Agility Robotics Expand Digit Humanoid Deployments to More U.S. Sites – Unite.AI

iFixit’s Teardown Of The iPhone Duo Shows Potential Causes For Cracked Screens

Using Nemotron-Research-Reasoning-Qwen-1.5B-v2

The latest checkpoint is available for testing on Hugging Face. Loading the model:

from transformers import AutoTokenizer, AutoModelForCausalLM

tokenizer = AutoTokenizer.from_pretrained("nvidia/Nemotron-Research-Reasoning-Qwen-1.5B")
model = AutoModelForCausalLM.from_pretrained("nvidia/Nemotron-Research-Reasoning-Qwen-1.5B")

Conclusion

ProRLv2 redefines the limits of reasoning in language models by showing that RL scaling laws matter as much as size or data. Through advanced regularization and smart training schedules, it enables deep, creative, and generalizable reasoning even in compact architectures. The future lies in how far RL can push—not just how big models can get.


Check out the Unofficial Blog and Model on Hugging Face here. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.

Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in Materials at the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast who is always researching applications in fields like biomaterials and biomedical science. With a strong background in Material Science, he is exploring new advancements and creating opportunities to contribute.

Credit: Source link

ShareTweetSendSharePin

Related Posts

GXO, Agility Robotics Expand Digit Humanoid Deployments to More U.S. Sites – Unite.AI
AI & Technology

GXO, Agility Robotics Expand Digit Humanoid Deployments to More U.S. Sites – Unite.AI

October 26, 2026
iFixit’s Teardown Of The iPhone Duo Shows Potential Causes For Cracked Screens
AI & Technology

iFixit’s Teardown Of The iPhone Duo Shows Potential Causes For Cracked Screens

October 26, 2026
Tsinghua AI Open-Sources AKV, a Cache Engineering Server for LLM Agents on SGLang
AI & Technology

Tsinghua AI Open-Sources AKV, a Cache Engineering Server for LLM Agents on SGLang

October 26, 2026
Which Screenless Fitness Tracker Is Better For You?
AI & Technology

Which Screenless Fitness Tracker Is Better For You?

October 26, 2026
Next Post
Fritz the hippo celebrated his 3rd birthday with a watermelon cake at the Cincinnati Zoo

Fritz the hippo celebrated his 3rd birthday with a watermelon cake at the Cincinnati Zoo

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
U.K. police say they received letter with claims against Meghan's father, wasn't shared with other law enforcement – CBS News

U.K. police say they received letter with claims against Meghan's father, wasn't shared with other law enforcement – CBS News

October 24, 2026
Voyager: Maintaining A Strong Buy For Q4 PET Imaging Data AD And More (NASDAQ:VYGR)

Voyager: Maintaining A Strong Buy For Q4 PET Imaging Data AD And More (NASDAQ:VYGR)

October 23, 2026
NVIDIA Expands Isaac Platform with Agile ONE SN Reference Humanoid – Unite.AI

NVIDIA Expands Isaac Platform with Agile ONE SN Reference Humanoid – Unite.AI

October 21, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!