Language models (LMs) face significant challenges related to privacy and copyright concerns due to their training on vast amounts of text data. The inadvertent inclusion of private and copyrighted content in training datasets has led to legal and ethical issues, including copyright lawsuits and compliance requirements with regulations like GDPR. Data owners increasingly demand the removal of their data from trained models, highlighting the need for effective machine unlearning techniques. These developments have spurred research into methods that can transform existing trained models to behave as if they had never been exposed to certain data, while maintaining overall performance and efficiency.
Researchers have made various attempts to address the challenges of machine unlearning in language models. Exact unlearning methods, which aim to make the unlearned model identical to a model retrained without the forgotten data, have been developed for simple models like SVMs and naive Bayes classifiers. However, these approaches are computationally infeasible for modern large language models.
Approximate unlearning methods have emerged as more practical alternatives. These include parameter optimization techniques like Gradient Ascent, localization-informed unlearning that targets specific model units, and in-context unlearning that modifies model outputs using external knowledge. Researchers have also explored applying unlearning to specific downstream tasks and for eliminating harmful behaviors in language models.
Evaluation methods for machine unlearning in language models have primarily focused on specific tasks like question answering or sentence completion. Metrics such as familiarity scores and comparisons with retrained models have been used to assess unlearning effectiveness. However, existing evaluations often lack comprehensiveness and fail to adequately address real-world deployment considerations like scalability and sequential unlearning requests.
Researchers from the University of Washington, Princeton University, the University of Southern California, the University of Chicago, and Google Research introduce MUSE (Machine Unlearning Six-Way Evaluation), a comprehensive framework designed to assess the effectiveness of machine unlearning algorithms for language models. This systematic approach evaluates six critical properties that address both data owners’ and model deployers’ requirements for practical unlearning. MUSE examines the ability of unlearning algorithms to remove verbatim memorization, knowledge memorization, and privacy leakage while also assessing their capacity to preserve utility, scale effectively, and sustain performance across multiple unlearning requests. By applying this framework to evaluate eight representative machine unlearning algorithms on datasets focused on unlearning Harry Potter books and news articles, MUSE provides a holistic view of the current state and limitations of unlearning techniques in real-world scenarios.
MUSE proposes a comprehensive set of evaluation metrics that address both data owner and model deployer expectations for machine unlearning in language models. The framework consists of six key criteria:
Data Owner Expectations:
1. No verbatim memorization: Measured by prompting the model with the beginning of a sequence from the forget set and comparing the model’s continuation with the true continuation using ROUGE-L F1 score.
2. No knowledge memorization: Assessed by testing the model’s ability to answer questions derived from the forget set, using ROUGE scores to compare model-generated answers with true answers.
3. No privacy leakage: Evaluated using a membership inference attack (MIA) method to detect if the model retains information indicating that the forget set was part of the training data.
Model Deployer Expectations:
4. Utility preservation: Measured by evaluating the model’s performance on the retain set using the knowledge memorization metric.
5. Scalability: Assessed by examining the model’s performance on forget sets of varying sizes.
6. Sustainability: Analyzed by tracking the model’s performance over sequential unlearning requests.
MUSE evaluates these metrics on two representative datasets: NEWS (BBC news articles) and BOOKS (Harry Potter series), providing a realistic testbed for assessing unlearning algorithms in practical scenarios.
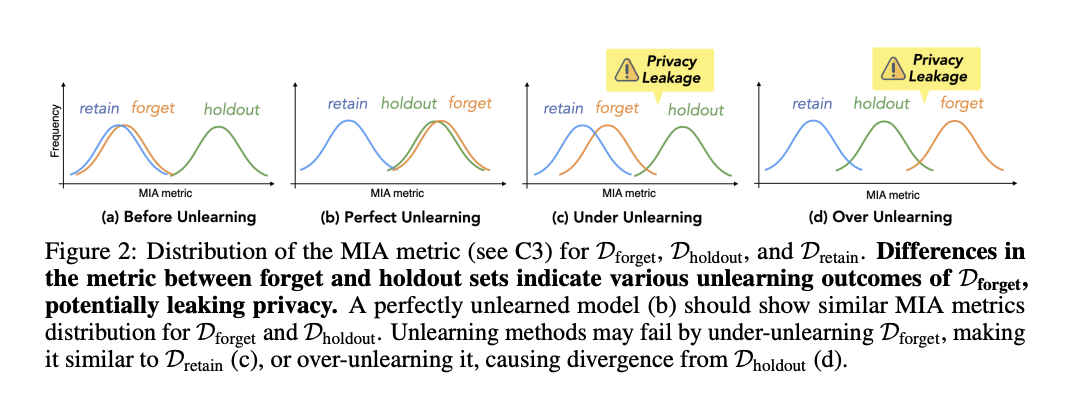
The MUSE framework’s evaluation of eight unlearning methods revealed significant challenges in machine unlearning for language models. While most methods effectively removed verbatim and knowledge memorization, they struggled with privacy leakage, often under- or over-unlearning. All methods significantly degraded model utility, with some rendering models unusable. Scalability issues emerged as forget set sizes increased, and sustainability proved problematic with sequential unlearning requests, leading to progressive performance degradation. These findings underscore the substantial trade-offs and limitations in current unlearning techniques, highlighting the pressing need for more effective and balanced approaches to meet both data owner and deployer expectations.
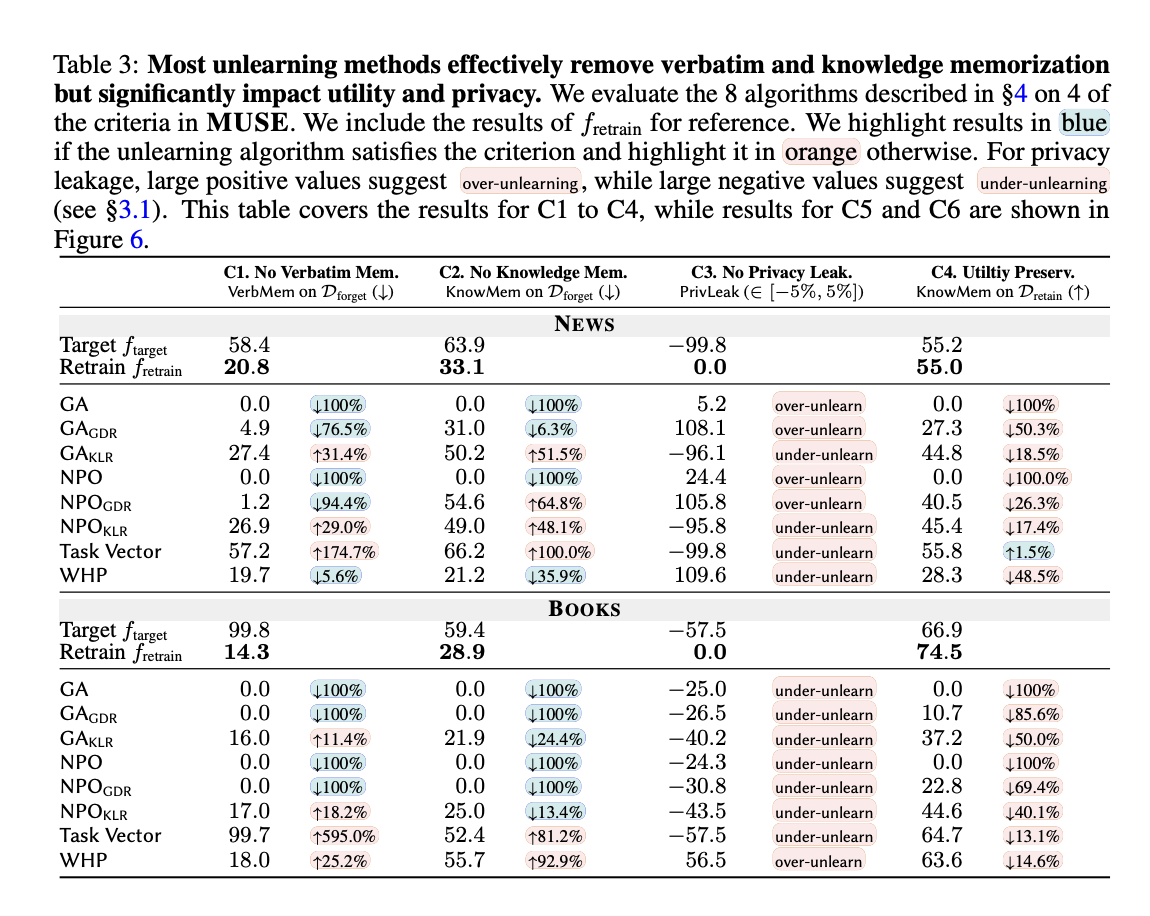
This research introduces MUSE, a comprehensive machine unlearning evaluation benchmark, assesses six key properties crucial for both data owners and model deployers. The evaluation reveals that while current unlearning methods effectively prevent content memorization, they do so at a substantial cost to model utility on retained data. Also, these methods often result in significant privacy leakage and struggle with scalability and sustainability when handling large-scale content removal or successive unlearning requests. These findings underscore the limitations of existing approaches and emphasize the urgent need for developing more robust and balanced machine unlearning techniques that can better address the complex requirements of real-world applications.
Check out the Paper and Project. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter.
Join our Telegram Channel and LinkedIn Group.
If you like our work, you will love our newsletter..
Don’t Forget to join our 46k+ ML SubReddit
Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.
Credit: Source link