• bitcoinBitcoin(BTC)$86,403.000.80%
  • ethereumEthereum(ETH)$2,744.10-0.03%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$787.98-1.42%
  • rippleXRP(XRP)$1.575.13%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$117.32-0.26%
  • tronTRON(TRX)$0.341416-1.09%
  • zcashZcash(ZEC)$1,542.723.02%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.01-2.89%
  • HyperliquidHyperliquid(HYPE)$94.842.00%
  • dogecoinDogecoin(DOGE)$0.0999873.04%
  • moneroMonero(XMR)$573.840.68%
  • whitebitWhiteBIT Coin(WBT)$86.690.43%
  • chainlinkChainlink(LINK)$13.020.40%
  • USDSUSDS(USDS)$1.00-0.01%
  • RainRain(RAIN)$0.013430-5.18%
  • cardanoCardano(ADA)$0.2507472.48%
  • leo-tokenLEO Token(LEO)$8.960.81%
  • stellarStellar(XLM)$0.2137701.89%
  • bitcoin-cashBitcoin Cash(BCH)$328.4424.95%
  • nearNEAR Protocol(NEAR)$4.429.49%
  • uniswapUniswap(UNI)$9.163.08%
  • avalanche-2Avalanche(AVAX)$11.191.51%
  • Ethena USDeEthena USDe(USDE)$1.00-0.04%
  • litecoinLitecoin(LTC)$61.26-3.38%
  • daiDai(DAI)$1.000.01%
  • CantonCanton(CC)$0.115651-1.48%
  • USD1USD1(USD1)$1.000.00%
  • hedera-hashgraphHedera(HBAR)$0.0981995.71%
  • suiSui(SUI)$1.00-1.49%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.440.31%
  • shiba-inuShiba Inu(SHIB)$0.0000060.49%
  • BittensorBittensor(TAO)$309.137.38%
  • crypto-com-chainCronos(CRO)$0.0664314.60%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • MemeCoreMemeCore(M)$1.31-12.42%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • tether-goldTether Gold(XAUT)$4,328.04-0.57%
  • okbOKB(OKB)$121.69-0.84%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • BitwayBitway(BTW)$0.86-6.28%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.12%
  • aaveAave(AAVE)$142.96-0.04%
  • mantleMantle(MNT)$0.662.79%
  • OndoOndo(ONDO)$0.428916-4.34%
  • Pump.funPump.fun(PUMP)$0.0044441.54%
  • EthenaEthena(ENA)$0.205771-3.15%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

MMLongBench-Doc: A Comprehensive Benchmark for Evaluating Long-Context Document Understanding in Large Vision-Language Models

July 19, 2024
in AI & Technology
Reading Time: 4 mins read
A A
MMLongBench-Doc: A Comprehensive Benchmark for Evaluating Long-Context Document Understanding in Large Vision-Language Models
ShareShareShareShareShare

Document understanding (DU) focuses on the automatic interpretation and processing of documents, encompassing complex layout structures and multi-modal elements such as text, tables, charts, and images. This task is essential for extracting and utilizing the vast amounts of information contained in documents generated annually.

One of the critical challenges lies in understanding long-context documents that span many pages and require comprehension across various modalities and pages. Traditional single-page DU models struggle with this, making it crucial to develop benchmarks to evaluate models’ performance on lengthy documents. Researchers have identified that these long-context documents necessitate specific capabilities such as localization and cross-page comprehension, which are not adequately addressed by current single-page DU datasets.

YOU MAY ALSO LIKE

Do USB Extenders Really Work And Are They Safe To Use?

How To Enter VR Mode On Steam

Current methods for DU involve Large Vision-Language Models (LVLMs) such as GPT-4o, Gemini-1.5, and Claude-3, developed by companies like OpenAI and Anthropic. These models have shown promise on single-page tasks but need help with long-context document understanding due to the need for multi-page comprehension and integrating multimodal elements. This gap in capability underscores the importance of creating comprehensive benchmarks to push the development of more advanced models.

Researchers from institutions including Nanyang Technological University, Shanghai AI Laboratory, and Peking University have introduced MMLongBench-Doc, a comprehensive benchmark designed to evaluate the long-context DU capabilities of LVLMs. This benchmark includes 135 PDF-formatted documents from diverse domains, averaging 47.5 pages and 21,214.1 textual tokens. It features 1,091 questions requiring evidence from text, images, charts, tables, and layout structures, with a significant portion necessitating cross-page comprehension. This rigorous benchmark aims to push the boundaries of current DU models.

In-depth, the methodology involves using screenshots of document pages as inputs to LVLMs, comparing their performance with traditional OCR-parsed text models. The benchmark’s construction was meticulous, with ten expert annotators editing questions from existing datasets and creating new ones for comprehensiveness. The annotation process ensured high quality through a three-round, semi-automatic reviewing process. This approach highlighted the need for models to handle lengthy documents comprehensively, making MMLongBench-Doc a critical tool for evaluating and improving DU models.
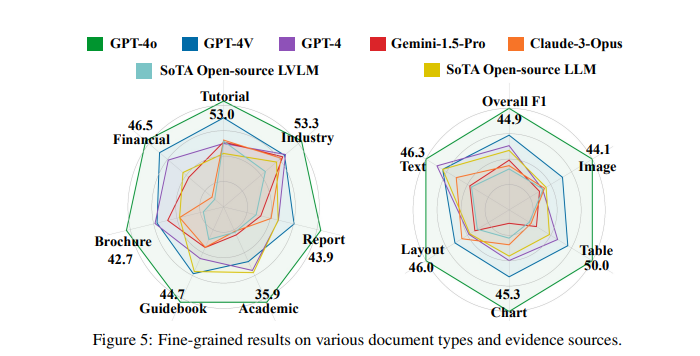
The performance evaluations revealed that LVLMs generally struggle with long-context DU. For instance, the best-performing model, GPT-4o, achieved an F1 score of 44.9%, while the second-best, GPT-4V, scored 30.5%. Other models, such as Gemini-1.5 and Claude-3, showed even lower performance. These results indicate the substantial challenges in long-context DU and the necessity for further advancements. The study compared these results with OCR-based models, noting that some LVLMs performed worse than single-modal LLMs when fed with lossy OCR-parsed text.

The detailed results highlighted that while LVLMs can handle multi-modal inputs to some extent, their capabilities still need to be improved. For example, 33.0% of the questions in the benchmark were cross-page questions requiring multi-page comprehension, and 22.5% were designed to be unanswerable to detect potential hallucinations. This rigorous testing underscored the need for more capable LVLMs. Proprietary models outperformed open-source ones, attributed to their higher acceptable image numbers and maximum image resolutions.
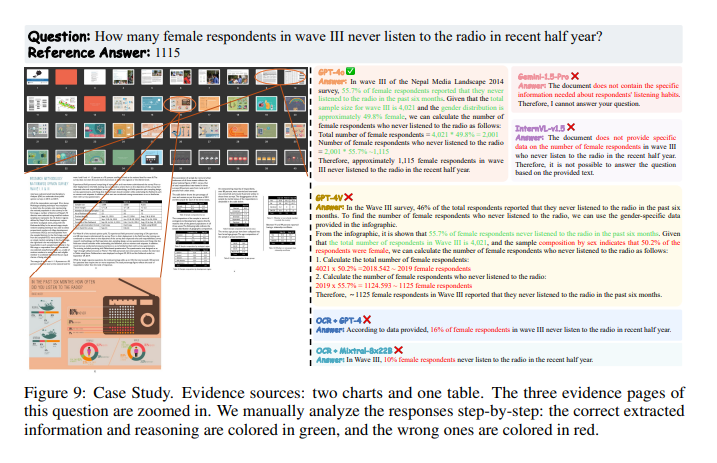
In conclusion, this study underscores the complexity of long-context document understanding and the necessity for advanced models capable of effectively processing and comprehending lengthy, multi-modal documents. The MMLongBench-Doc benchmark, developed by collaborating with leading research institutions, is a valuable tool for evaluating and improving these models’ performance. The study’s findings highlight current models’ significant challenges and the need for continued research and development in this area to achieve more effective and comprehensive DU solutions.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 46k+ ML SubReddit

Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in Materials at the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast who is always researching applications in fields like biomaterials and biomedical science. With a strong background in Material Science, he is exploring new advancements and creating opportunities to contribute.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Do USB Extenders Really Work And Are They Safe To Use?
AI & Technology

Do USB Extenders Really Work And Are They Safe To Use?

September 22, 2026
How To Enter VR Mode On Steam
AI & Technology

How To Enter VR Mode On Steam

September 22, 2026
Peloton Has Made A Foldable (Treadmill)
AI & Technology

Peloton Has Made A Foldable (Treadmill)

September 22, 2026
OpenAI Faces Lawsuit From British Columbia Over Tumbler Ridge Shooting
AI & Technology

OpenAI Faces Lawsuit From British Columbia Over Tumbler Ridge Shooting

September 22, 2026
Next Post
Hallie Jackson NOW – May 29 | NBC News NOW

Hallie Jackson NOW - May 29 | NBC News NOW

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Stay Tuned NOW Streaming Behind The Scenes! – Aug 31

Stay Tuned NOW Streaming Behind The Scenes! – Aug 31

September 20, 2026
Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

September 19, 2026
The Street Fighter Movie Popcorn Bucket Is Gloriously Goofy

The Street Fighter Movie Popcorn Bucket Is Gloriously Goofy

September 18, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!