
Mistral AI has released Voxtral TTS, an open-weight text-to-speech model that marks the company’s first major move into audio generation. Following the release of its transcription and language models, Mistral is now providing the final ‘output layer’ of the audio stack, positioning itself as a direct competitor to proprietary voice APIs in the developer ecosystem.
Voxtral TTS is more than just a synthetic voice generator. It is a high-performance, modular component designed to be integrated into real-time voice workflows. By releasing the model under a CC BY-NC license, Mistral team continues its strategy of enabling developers to build and deploy frontier-grade capabilities without the constraints of closed-source API pricing or data privacy limitations.
Architecture: The 4B Parameter Hybrid Model
While many recent developments in text-to-speech have focused on massive, resource-intensive architectures, Voxtral TTS is built with a focus on efficiency. The model features 4B parameters, categorized as a lightweight model by modern frontier standards.
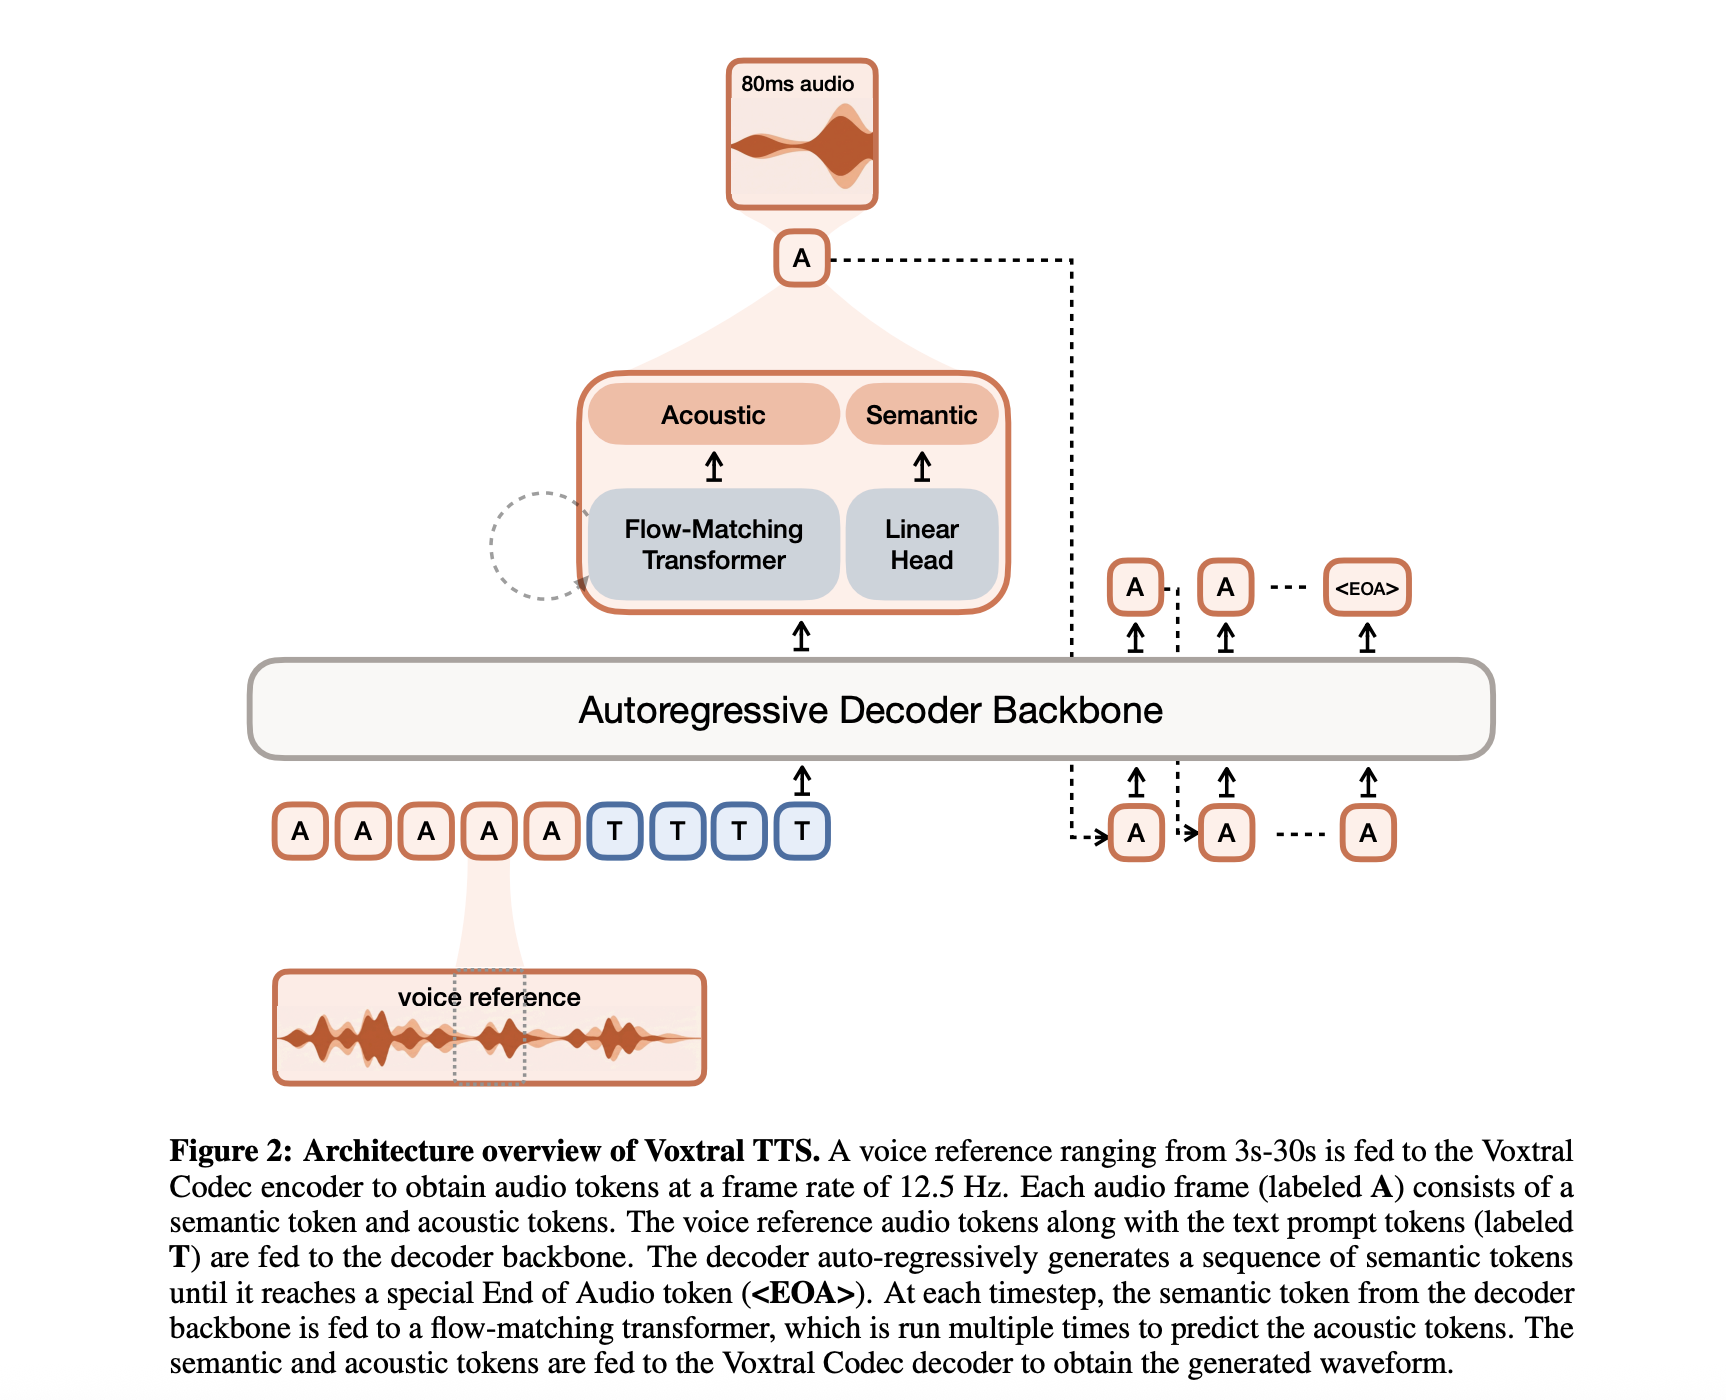
This parameter count is distributed across a hybrid architecture designed to solve the common trade-offs between generation speed and audio naturalness. The system comprises three primary components:
- Transformer Decoder Backbone: A 3.4B parameter module based on the Ministral architecture that handles the text understanding and predicts semantic representations of speech.
- Flow-Matching Acoustic Transformer: A 390M parameter module that converts those semantic representations into detailed acoustic features.
- Neural Audio Codec: A 300M parameter decoder that maps the acoustic features back into a high-fidelity audio waveform.
By separating the ‘meaning’ of the speech (semantic) from the ‘texture’ of the voice (acoustic), Voxtral TTS maintains long-range consistency while delivering the fine-grained nuances required for lifelike interaction.
Performance: 70ms Latency and High Throughput
In the context of production-grade AI, latency is the defining constraint. Mistral has optimized Voxtral TTS for low-latency streaming inference, making it suitable for conversational agents and real-time translation.
The model achieves a 70ms model latency for a typical 10-second voice sample and 500-character input. This speed is critical for reducing the perceived delay in voice-first applications, where even small pauses can disrupt the flow of human-machine interaction.
Furthermore, the model boasts a high Real-Time Factor (RTF) of approximately 9.7x. This means the system can synthesize audio nearly ten times faster than it is spoken. For developers, this throughput translates to lower compute costs and the ability to handle high-concurrency workloads on standard inference hardware.
Global Reach: 9 Languages and Dialect Accuracy
Voxtral TTS is natively multilingual, supporting 9 languages out of the gate: English, French, German, Spanish, Dutch, Portuguese, Italian, Hindi, and Arabic.
The training objective for the model goes beyond simple phonetic translation. Mistral has emphasized the model’s ability to capture diverse dialects, recognizing the subtle shifts in cadence and prosody that distinguish regional speakers. This technical precision makes the model an effective tool for global applications—from international customer support to localized content creation—where a generic, ‘flattened’ accent often fails to pass the human test.
Adaptive Voice Adaptation
One of the standout features for AI devs is the model’s ease of voice adaptation. Voxtral TTS supports zero-shot and few-shot voice cloning, allowing it to adapt to a new voice using as little as 3 seconds of reference audio.
This capability allows for the creation of consistent brand voices or personalized user experiences without the need for extensive fine-tuning. Because the model uses a factorized representation, it can apply the characteristics of a reference voice (timbre, tone, and pitch) to any generated text while maintaining the correct linguistic prosody of the target language.
Benchmarks: A Challenge to the Proprietary Giants
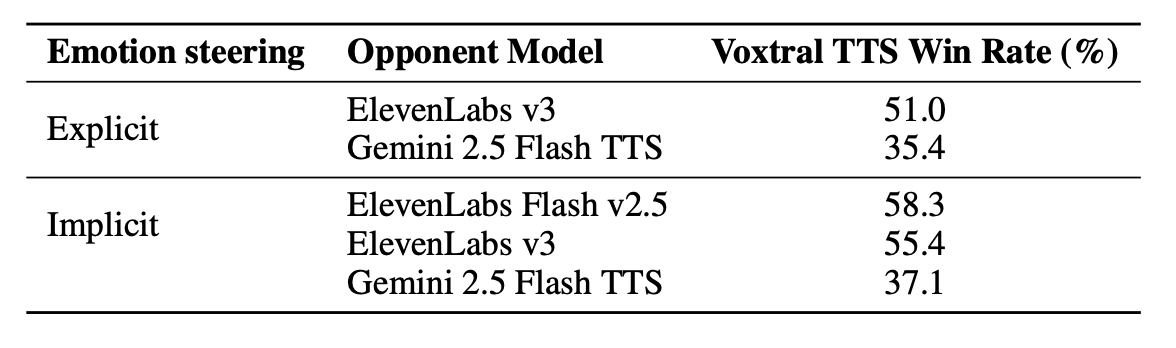
Mistral’s evaluations focus on how Voxtral TTS stacks up against the current industry leaders in synthetic speech, specifically ElevenLabs. In human preference tests conducted by native speakers, Voxtral TTS demonstrated significant gains in naturalness and expressivity.
- Vs. ElevenLabs Flash v2.5: Voxtral TTS achieved a 68.4% win rate in multilingual voice cloning evaluations.
- Vs. ElevenLabs v3: The model achieved parity or higher scores in speaker similarity, proving that an open-weight model can effectively match the fidelity of the most advanced proprietary flagship voices.
These benchmarks suggest that for many enterprise use cases, the performance gap between open-source tools and high-cost APIs has effectively closed.
Deployment and Integration
Voxtral TTS is designed to function as part of a comprehensive Audio Intelligence stack. It integrates natively with Voxtral Transcribe, creating an end-to-end speech-to-speech (S2S) pipeline.
For AI developers building on local or private cloud infrastructure, the model’s small footprint is a significant advantage. Mistral’s team has confirmed that the model is efficient enough to run on standard smartphone and laptop hardware once quantized. This ‘edge-readiness’ allows for a new class of private, offline applications, from secure corporate assistants to on-device accessibility tools.
| Specification | Metric |
| Model Size | 4B Parameters |
| Latency (10s voice / 500 chars) | 70ms |
| Real-Time Factor (RTF) | ~9.7x |
| Supported Languages | 9 |
| Reference Audio Needed | 3 – 30 seconds |
| License | CC BY-NC |
Key Takeaways
- High-Efficiency 4B Parameter Model: Voxtral TTS is a frontier open-weight model with a 4B parameter footprint, utilizing a hybrid architecture that combines auto-regressive semantic generation with flow-matching for acoustic details.
- Ultra-Low 70ms Latency: Optimized for real-time applications, the model achieves a 70ms model latency for a typical 10-second voice sample (500-character input) and an impressive Real-Time Factor (RTF) of approximately 9.7x.
- Superior Multilingual Performance: The model supports 9 languages (English, French, German, Spanish, Dutch, Portuguese, Italian, Hindi, and Arabic) and outperformed ElevenLabs Flash v2.5 with a 68.4% win rate in human preference tests for multilingual voice cloning.
- Instant Voice Adaptation: Developers can achieve high-fidelity voice cloning with as little as 3 seconds of reference audio, enabling zero-shot cross-lingual adaptation where a speaker’s unique identity is preserved across different languages.
- Full Audio Stack Integration: Designed as the ‘output layer’ of a unified audio intelligence pipeline, it plugs natively into Voxtral Transcribe to create low-latency, end-to-end speech-to-speech workflows.
Check out the Paper, Model Weight and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
The post Mistral AI Releases Voxtral TTS: A 4B Open-Weight Streaming Speech Model for Low-Latency Multilingual Voice Generation appeared first on MarkTechPost.
Credit: Source link