• bitcoinBitcoin(BTC)$77,086.00-5.14%
  • ethereumEthereum(ETH)$2,212.42-6.12%
  • tetherTether(USDT)$1.00-0.07%
  • binancecoinBNB(BNB)$686.93-9.71%
  • rippleXRP(XRP)$1.22-8.05%
  • usd-coinUSDC(USDC)$1.00-0.05%
  • solanaSolana(SOL)$93.20-8.98%
  • tronTRON(TRX)$0.3561398.15%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.04%
  • HyperliquidHyperliquid(HYPE)$89.2310.58%
  • zcashZcash(ZEC)$1,202.34-8.67%
  • dogecoinDogecoin(DOGE)$0.073169-8.60%
  • moneroMonero(XMR)$602.081.00%
  • USDSUSDS(USDS)$1.00-0.05%
  • whitebitWhiteBIT Coin(WBT)$73.92-5.41%
  • leo-tokenLEO Token(LEO)$9.450.34%
  • chainlinkChainlink(LINK)$10.39-12.16%
  • cardanoCardano(ADA)$0.184645-10.70%
  • stellarStellar(XLM)$0.159906-7.50%
  • bitcoin-cashBitcoin Cash(BCH)$267.68-7.68%
  • nearNEAR Protocol(NEAR)$4.01-15.26%
  • RainRain(RAIN)$0.006619-2.49%
  • daiDai(DAI)$1.00-0.01%
  • Ethena USDeEthena USDe(USDE)$1.00-0.16%
  • litecoinLitecoin(LTC)$53.61-10.13%
  • uniswapUniswap(UNI)$6.36-12.78%
  • USD1USD1(USD1)$1.00-0.18%
  • CantonCanton(CC)$0.091967-8.43%
  • avalanche-2Avalanche(AVAX)$8.10-10.17%
  • suiSui(SUI)$0.84-11.29%
  • tether-goldTether Gold(XAUT)$4,002.02-0.75%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.12-10.13%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • hedera-hashgraphHedera(HBAR)$0.067453-10.54%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.06%
  • shiba-inuShiba Inu(SHIB)$0.000005-9.28%
  • Ripple USDRipple USD(RLUSD)$1.00-0.06%
  • BittensorBittensor(TAO)$223.61-13.19%
  • quant-networkQuant(QNT)$177.63-11.72%
  • crypto-com-chainCronos(CRO)$0.050383-5.77%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.24%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • MemeCoreMemeCore(M)$1.01-2.80%
  • BitwayBitway(BTW)$1.52-12.10%
  • EthenaEthena(ENA)$0.168884-19.29%
  • okbOKB(OKB)$106.83-4.17%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • pepePepe(PEPE)$0.000004-12.35%
  • Falcon USDFalcon USD(USDF)$0.99-0.28%
  • Spiko Amundi Overnight Swap Fund (EUR)Spiko Amundi Overnight Swap Fund (EUR)(EURSAFO)$1.140.36%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Meta-Rewarding LLMs: A Self-Improving Alignment Technique Where the LLM Judges Its Own Judgements and Uses the Feedback to Improve Its Judgment Skills

August 8, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Meta-Rewarding LLMs: A Self-Improving Alignment Technique Where the LLM Judges Its Own Judgements and Uses the Feedback to Improve Its Judgment Skills
ShareShareShareShareShare

Large Language Models (LLMs) have made significant progress in following instructions and responding to user queries. However, the current instruction tuning process faces major challenges. Acquiring human-generated data for training these models is expensive and time-consuming. Moreover, the quality of such data is limited by human capabilities. This limitation is especially evident while addressing the ‘Super Alignment’ challenge, which aims to control potentially super-intelligent AIs whose actions may exceed human comprehension. There is a need to focus on finding effective methods in the AI field to guide LLMs’ development beyond human-level performance as they continue to advance.

Researchers have explored various methods to align LLMs with human values. One popular method is Reinforcement Learning from Human Feedback (RLHF), which uses the Proximal Policy Optimization (PPO) technique to train a reward model based on human preference data. The second method, the LLM-as-a-Judge has gained popularity for evaluation and reward model training. However, these methods often rely on human data or input from stronger models, potentially limiting their effectiveness for super alignment challenges. The last approach, Super Alignment includes Constitutional AI and CriticGPT which attempt to use AI to generate feedback but still struggle with training both the actor and judge components during self-improvement.

YOU MAY ALSO LIKE

Anthropic to Deliver Menlo’s Biggest-Ever Return

Anthropic’s S-1 Reveals Financial War Chest

Researchers from Meta FAIR, the University of California, Berkeley, and New York University have introduced a new method called Meta-Rewarding to improve the instruction-following abilities of LLMs. This method adds a third role, the meta-judge, to the existing actor and judge roles. The meta-judge evaluates the model’s judgments using a mechanism similar to LLM-as-a-Judge, called LLM-as-a-Meta-Judge. This process helps to generate training data with preference pairs of judgments, in addition to the standard preferences between actor responses. The Meta-Rewarding enhances the overall instruction-following capability of the model by improving both acting and judging skills. 

​​The Meta-Rewarding method is developed on the instruction-finetuned Llama-3-8B-Instruct model, which serves as the seed model. Researchers performed supervised finetuning (SFT) on the Evaluation Fine-Tuning (EFT) dataset, which includes ranked human responses from Open Assistant. This step enhances the ability of the model to act as a judge. The Meta-Rewarding iterations use 20K prompts generated by Llama-2-70B-Chat. Each iteration samples 5K prompts from this set, performing four iterations. This iterative approach enhances the model’s performance in acting and judging roles. The experimental setup of previous work is closely followed, adapting it to include the meta-judge component for self-improvement.

The results obtained on evaluating Meta-Rewarding show that the length-controlled win rate increased from 22.9% to 39.4% on AlpacaEval, outperforming even GPT-4-0314. This method also outperforms the enhanced standard Self-Rewarding training, which had a win rate of 35.5%, highlighting the importance of the meta-judge. The same performance is seen on the Arena-Hard benchmark, which tests models’ ability to handle complex questions. After four iterations, Meta-Rewarding consistently improved scores, achieving an 8.5% increase over the seed model’s 20.6% score. These results prove that Meta-Rewarding enhances LLMs’ capabilities in following instructions and answering complex questions.
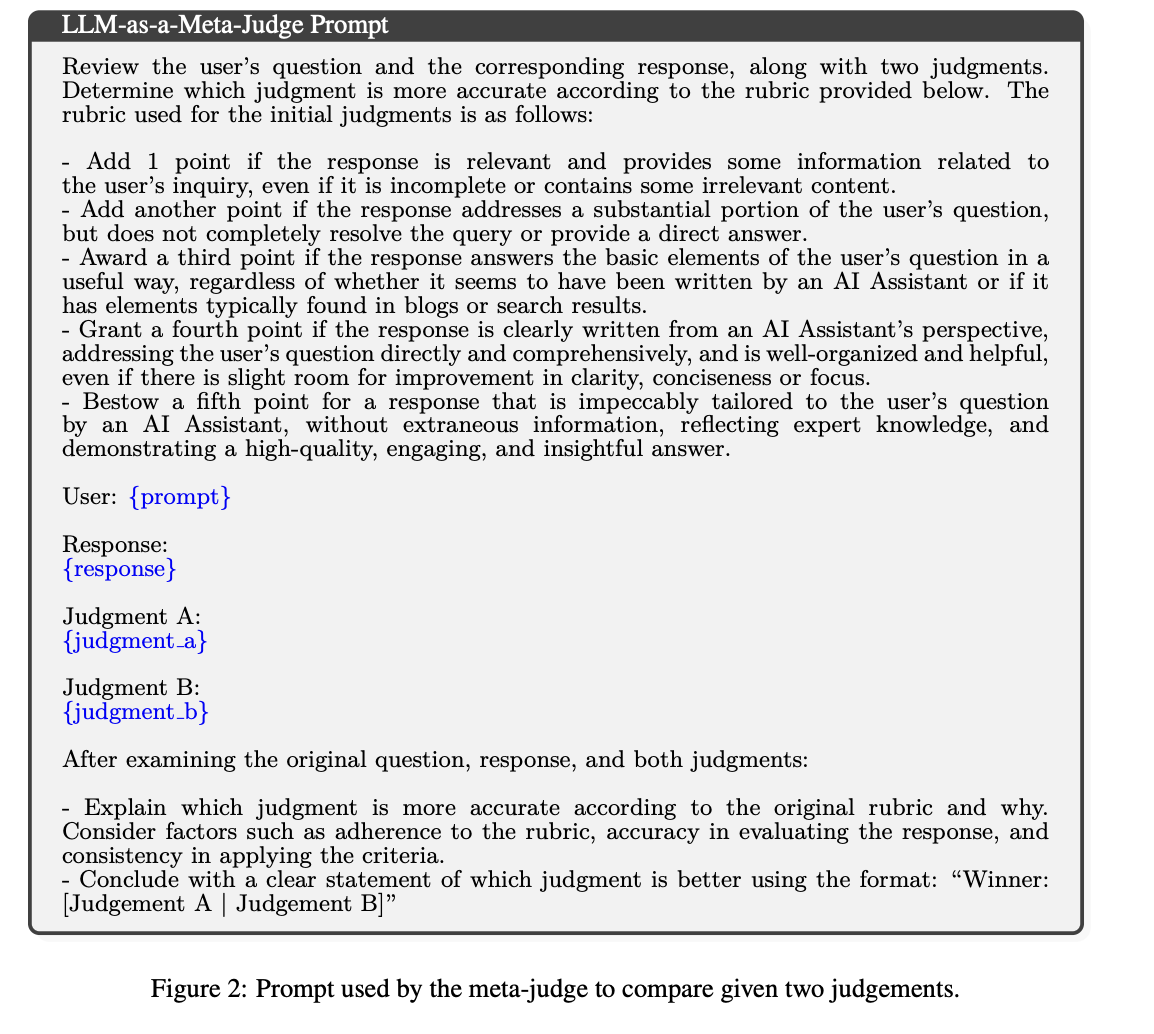
In conclusion, researchers proposed Meta-Rewarding, a new method to enhance the instruction-following abilities of LLMs. This method utilizes a meta-judge to evaluate and choose judgments for optimizing preferences, which addresses the limitations of previous Self-Rewarding frameworks by directly training the judge. Moreover, it includes a novel length-control technique to address issues of length explosion during AI feedback training. The model’s judgment abilities align more closely with human judges and advanced AI judges like GPT-4. However, the researchers address a limitation in their 5-point judging system, which occasionally leads to ties due to minimal differences in response quality.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter..

Don’t Forget to join our 48k+ ML SubReddit

Find Upcoming AI Webinars here


Sajjad Ansari is a final year undergraduate from IIT Kharagpur. As a Tech enthusiast, he delves into the practical applications of AI with a focus on understanding the impact of AI technologies and their real-world implications. He aims to articulate complex AI concepts in a clear and accessible manner.


Credit: Source link

ShareTweetSendSharePin

Related Posts

Anthropic to Deliver Menlo’s Biggest-Ever Return
AI & Technology

Anthropic to Deliver Menlo’s Biggest-Ever Return

October 30, 2026
Anthropic’s S-1 Reveals Financial War Chest
AI & Technology

Anthropic’s S-1 Reveals Financial War Chest

October 29, 2026
Anthropic IPO Is the “One We’ve Been Waiting For”: Bessemer’s Deeter
AI & Technology

Anthropic IPO Is the “One We’ve Been Waiting For”: Bessemer’s Deeter

October 29, 2026
Anthropic Drops Its S-1, Giving Market Glimpse Into Finances
AI & Technology

Anthropic Drops Its S-1, Giving Market Glimpse Into Finances

October 29, 2026
Next Post
Taylor Swift cancels Vienna shows after two arrested on suspicion of plotting attack – The Washington Post

Taylor Swift cancels Vienna shows after two arrested on suspicion of plotting attack - The Washington Post

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Clavicular accuser drops sex assault claim from civil case

Clavicular accuser drops sex assault claim from civil case

October 25, 2026
College football picks: Predictions against the spread, odds, betting lines for top 25 games in Week 8 – CBS Sports

College football picks: Predictions against the spread, odds, betting lines for top 25 games in Week 8 – CBS Sports

October 24, 2026
Oregon police say four victims dead, including three children, in school shooting

Oregon police say four victims dead, including three children, in school shooting

October 24, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!