• bitcoinBitcoin(BTC)$83,554.00-1.49%
  • ethereumEthereum(ETH)$2,689.17-0.72%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$769.65-1.40%
  • rippleXRP(XRP)$1.52-0.81%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$120.07-2.79%
  • tronTRON(TRX)$0.3349780.29%
  • zcashZcash(ZEC)$1,593.83-3.92%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.00-5.78%
  • HyperliquidHyperliquid(HYPE)$90.31-2.77%
  • dogecoinDogecoin(DOGE)$0.094571-3.92%
  • chainlinkChainlink(LINK)$14.723.57%
  • moneroMonero(XMR)$533.58-3.38%
  • whitebitWhiteBIT Coin(WBT)$83.56-1.30%
  • USDSUSDS(USDS)$1.00-0.03%
  • cardanoCardano(ADA)$0.252630-1.65%
  • RainRain(RAIN)$0.012568-0.92%
  • leo-tokenLEO Token(LEO)$9.05-0.15%
  • stellarStellar(XLM)$0.2277905.12%
  • nearNEAR Protocol(NEAR)$5.200.35%
  • bitcoin-cashBitcoin Cash(BCH)$314.65-6.90%
  • uniswapUniswap(UNI)$9.06-7.79%
  • litecoinLitecoin(LTC)$70.92-0.87%
  • hedera-hashgraphHedera(HBAR)$0.12073827.30%
  • CantonCanton(CC)$0.133170-2.34%
  • avalanche-2Avalanche(AVAX)$10.57-3.33%
  • Ethena USDeEthena USDe(USDE)$1.000.00%
  • suiSui(SUI)$1.19-5.30%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.662.94%
  • daiDai(DAI)$1.000.03%
  • USD1USD1(USD1)$1.00-0.02%
  • BitwayBitway(BTW)$1.3013.22%
  • BittensorBittensor(TAO)$308.03-7.41%
  • quant-networkQuant(QNT)$237.2647.93%
  • crypto-com-chainCronos(CRO)$0.0691001.11%
  • shiba-inuShiba Inu(SHIB)$0.000006-3.60%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,158.28-2.86%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • EthenaEthena(ENA)$0.269724-1.30%
  • MemeCoreMemeCore(M)$1.17-2.93%
  • OndoOndo(ONDO)$0.53-2.26%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • okbOKB(OKB)$118.35-2.92%
  • Pump.funPump.fun(PUMP)$0.00531317.61%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • aaveAave(AAVE)$150.57-3.03%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.02%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Meta AI Researchers Propose MEGABYTE: A Multiscale Decoder Architecture that Enables End-to-End Differentiable Modeling of Sequences of Over One Million Bytes

May 19, 2023
in AI & Technology
Reading Time: 4 mins read
A A
Meta AI Researchers Propose MEGABYTE: A Multiscale Decoder Architecture that Enables End-to-End Differentiable Modeling of Sequences of Over One Million Bytes
ShareShareShareShareShare

Million-byte sequences are common as music, picture, and video files frequently have several megabyte sizes. However, because of the quadratic cost of self-attention and, more significantly, the expense of large feedforward networks per position, large transformer decoders (LLMs) normally only require a few thousand tokens of context. This significantly reduces the range of tasks for which LLMs may be used. Researchers from META present MEGABYTE, a novel method for simulating lengthy byte sequences. Byte sequences are divided into fixed-sized patches roughly equivalent to tokens. 

Then, their model has three components: 

(1) A local module, a tiny autoregressive model that forecasts bytes within a patch. 

🚀 JOIN the fastest ML Subreddit Community

(2) A patch embedder merely encodes a patch by losslessly concatenating embeddings of each byte. 

(3) A global module, a big autoregressive transformer that inputs and outputs patch representations.

Importantly, most byte predictions are straightforward for many tasks (such as completing a word given the initial few letters), negating the need for massive networks per byte and allowing for considerably smaller models for intra-patch modeling. For extended sequence modeling, the MEGABYTE architecture offers three key advantages over Transformers: Self-attention that is sub-quadratic The vast majority of research on long sequence models has been devoted to reducing the quadratic cost of self-attention. Lengthy sequences are divided into two shorter sequences using MEGABYTE, and the self-attention cost is decreased to O(N(4/3)) by using optimum patch sizes, which are still tractable for lengthy sequences. Layers with per-patch feedforward. MEGABYTE allows for far bigger and more expressive models at the same cost by using huge feedforward layers per patch rather than per position. More than 98% of FLOPS are used in GPT3-size models to compute position-wise feedforward layers. 

Decoding Parallelism three Transformers must serially process all calculations during generation since each timestep’s input results from the initial output. MEGABYTE makes Greater parallelism during generation possible thanks to the parallel production of representations for patches. With patch size P, MEGABYTE may utilize a layer with mP parameters once for the same price as a baseline transformer, using the same feedforward layer with m parameters P times. For instance, when trained on the same compute, a MEGABYTE model with 1.5B parameters may create sequences 40% quicker than a conventional 350M Transformer while increasing perplexity. 

Together, these enhancements enable us to expand to lengthy sequences, increase generation speed during deployment, and train much bigger and better-performing models for the same computational budget. Sequences of bytes are translated into bigger discrete tokens in existing autoregressive models, which generally involve some tokenization. This is where MEGABYTE stands in stark contrast. Tokenization makes pre-processing, multi-modal modeling, and transfer to different domains more difficult while obscuring the model’s beneficial structure. Additionally, it implies that most cutting-edge models are still in progress. The most popular methods of tokenization lose information without language-specific heuristics. 

Therefore, switching from tokenization to performant and effective byte models would have several benefits. They carry out in-depth tests for both strong baselines and MEGABYTE. To concentrate their comparisons entirely on the model architecture rather than training resources, which are known to be advantageous to all models, they employ a single compute and data budget across all models. They discover that MEGABYTE enables byte-level models to reach state-of-the-art perplexities for density estimation on ImageNet, perform competitively with subword models on extended context language modeling, and allow audio modeling from raw audio data. These findings show that tokenization-free autoregressive sequence modeling is scaleable.


Check out the Paper. Don’t forget to join our 21k+ ML SubReddit, Discord Channel, and Email Newsletter, where we share the latest AI research news, cool AI projects, and more. If you have any questions regarding the above article or if we missed anything, feel free to email us at [email protected]

🚀 Check Out 100’s AI Tools in AI Tools Club


YOU MAY ALSO LIKE

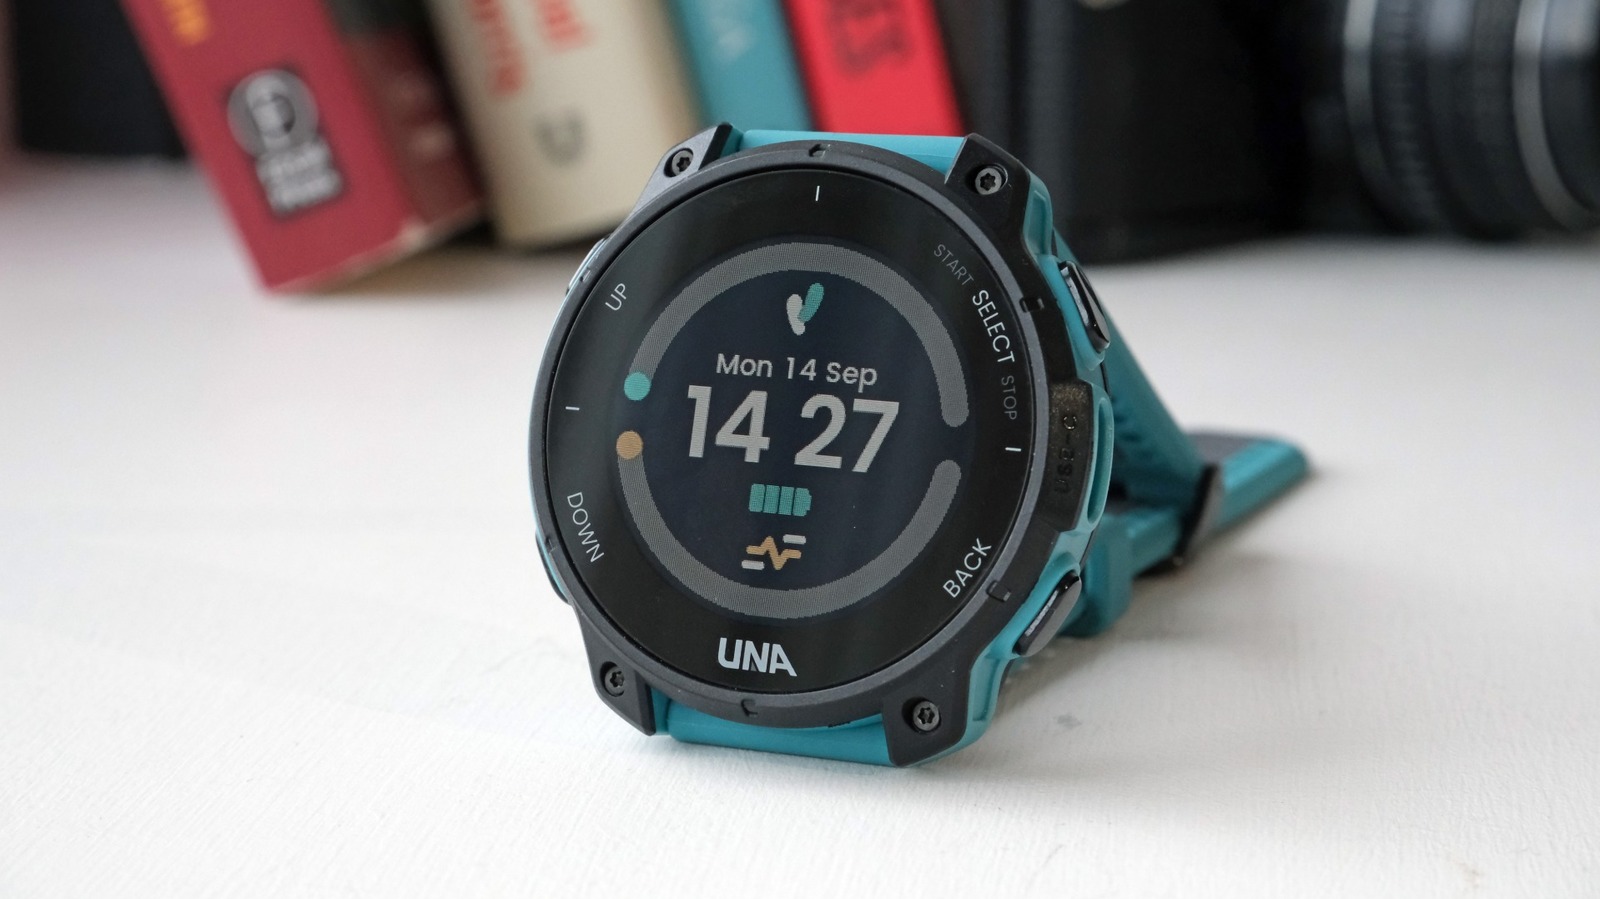
A Modular, Repairable GPS Watch Is A Good First Step

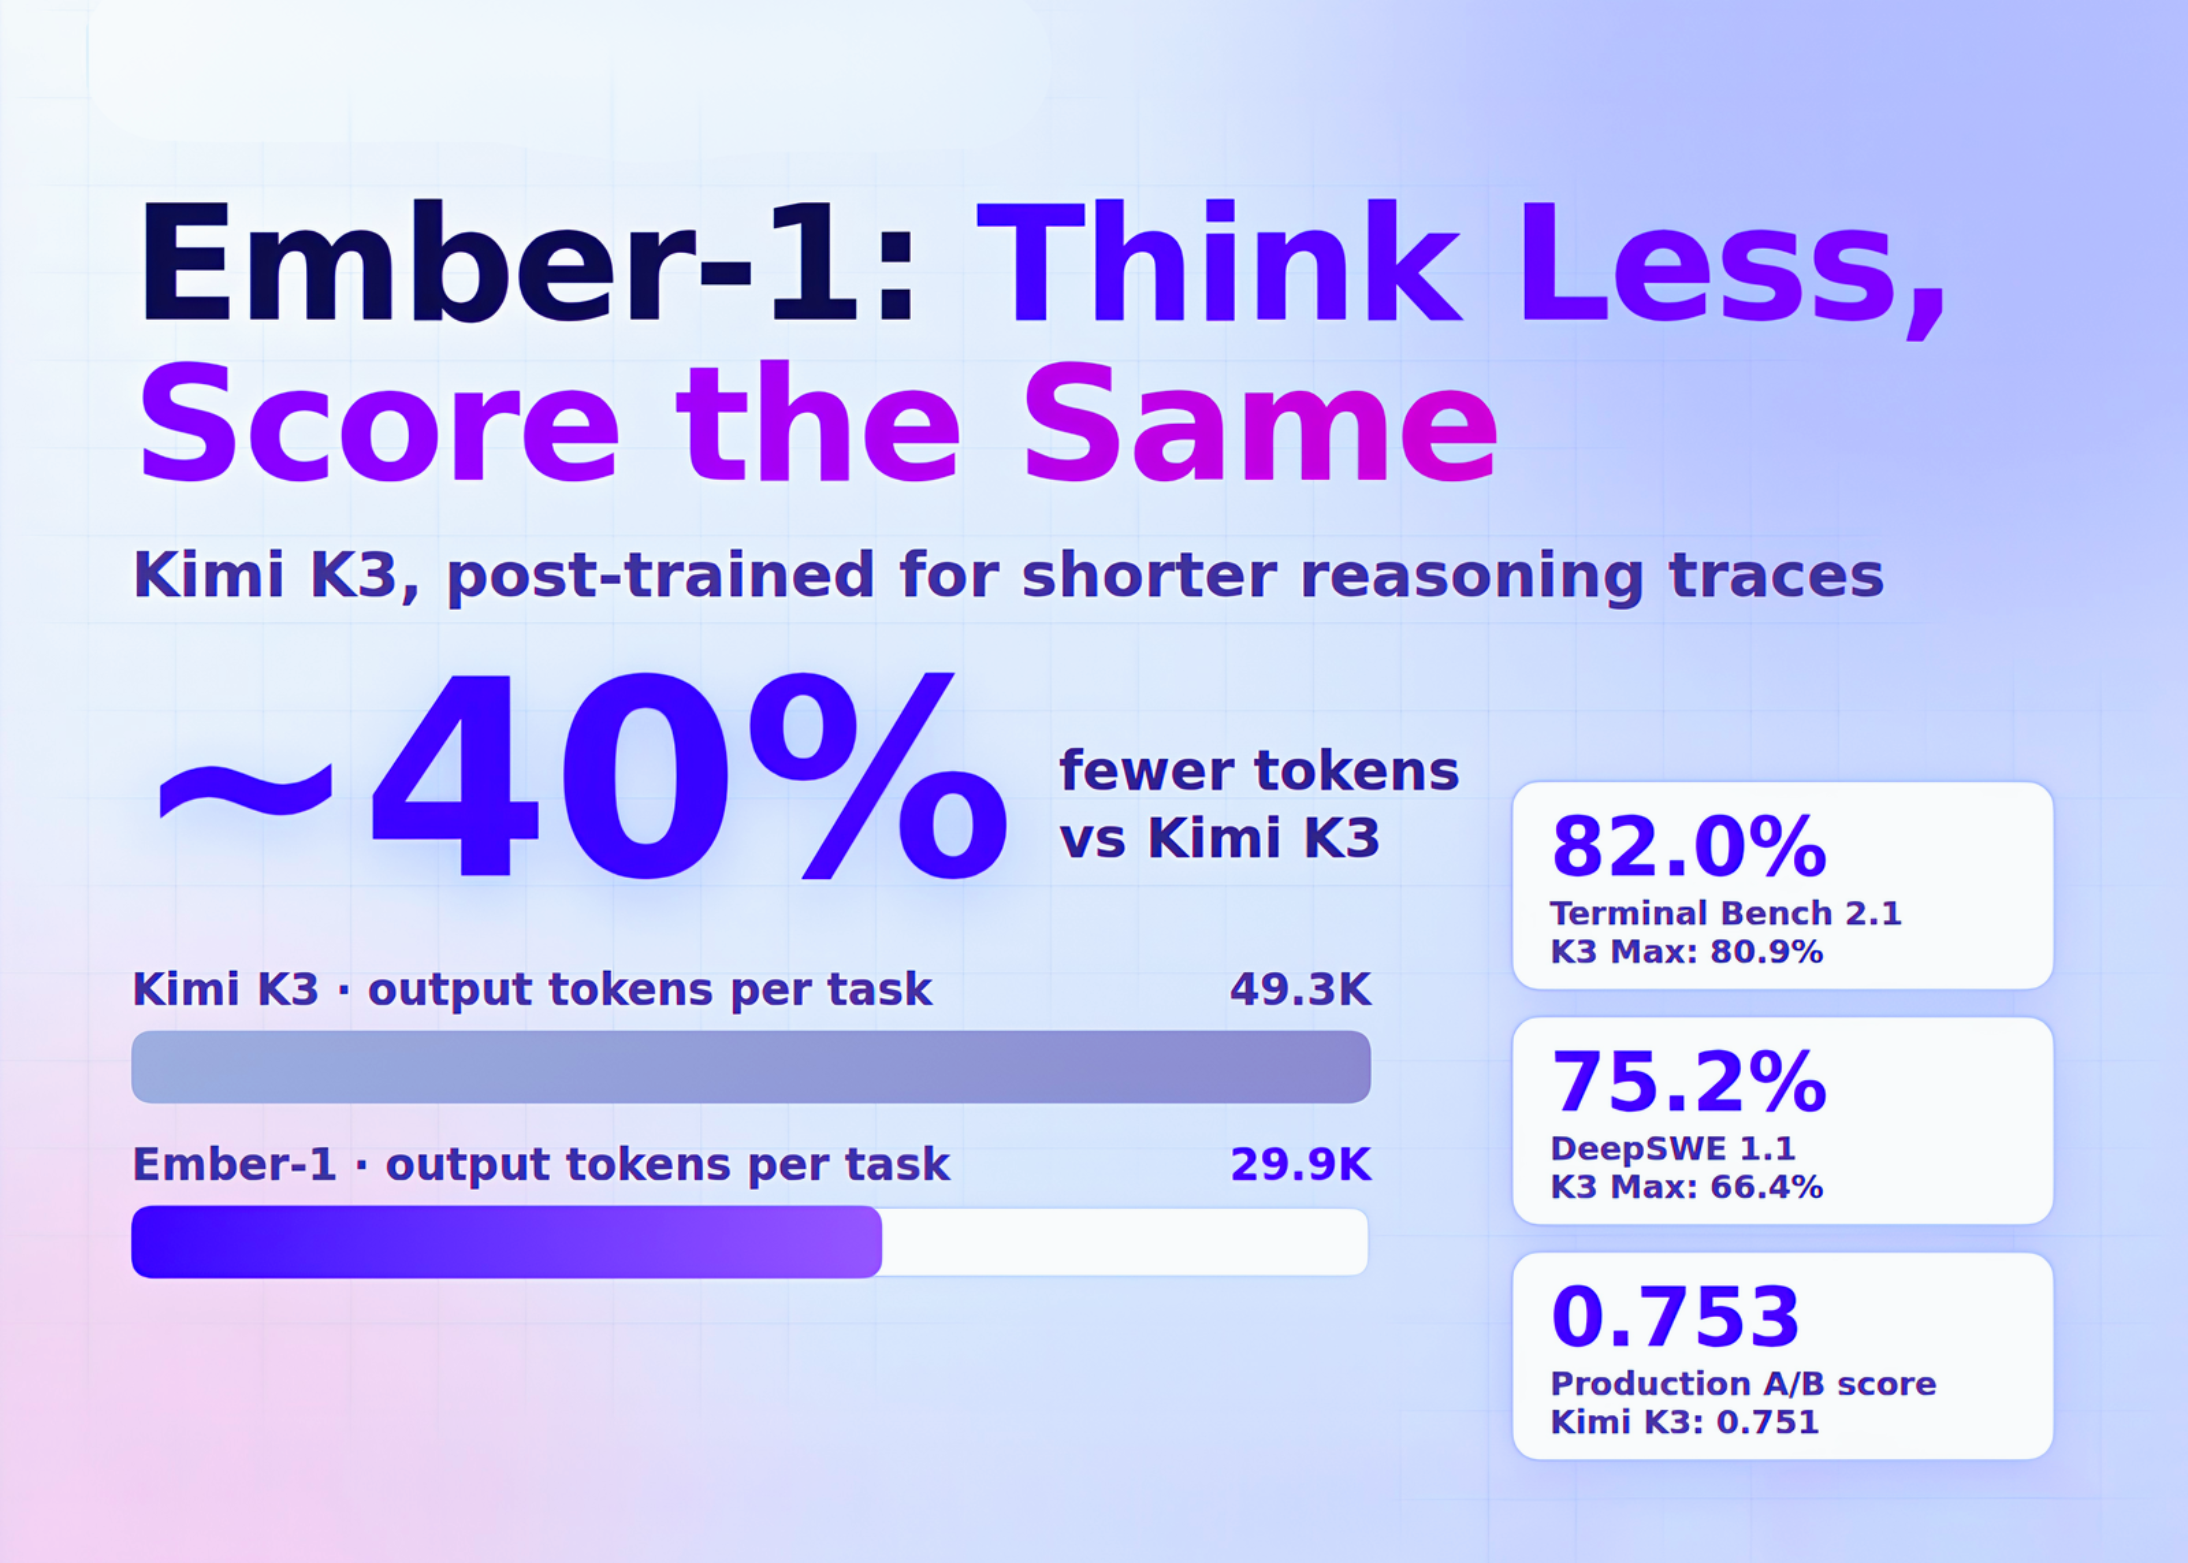
Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens

Aneesh Tickoo is a consulting intern at MarktechPost. He is currently pursuing his undergraduate degree in Data Science and Artificial Intelligence from the Indian Institute of Technology(IIT), Bhilai. He spends most of his time working on projects aimed at harnessing the power of machine learning. His research interest is image processing and is passionate about building solutions around it. He loves to connect with people and collaborate on interesting projects.


➡️ Meet Bright Data: The World’s #1 Web Data Platform

Credit: Source link

ShareTweetSendSharePin

Related Posts

A Modular, Repairable GPS Watch Is A Good First Step
AI & Technology

A Modular, Repairable GPS Watch Is A Good First Step

September 28, 2026
Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens
AI & Technology

Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens

September 28, 2026
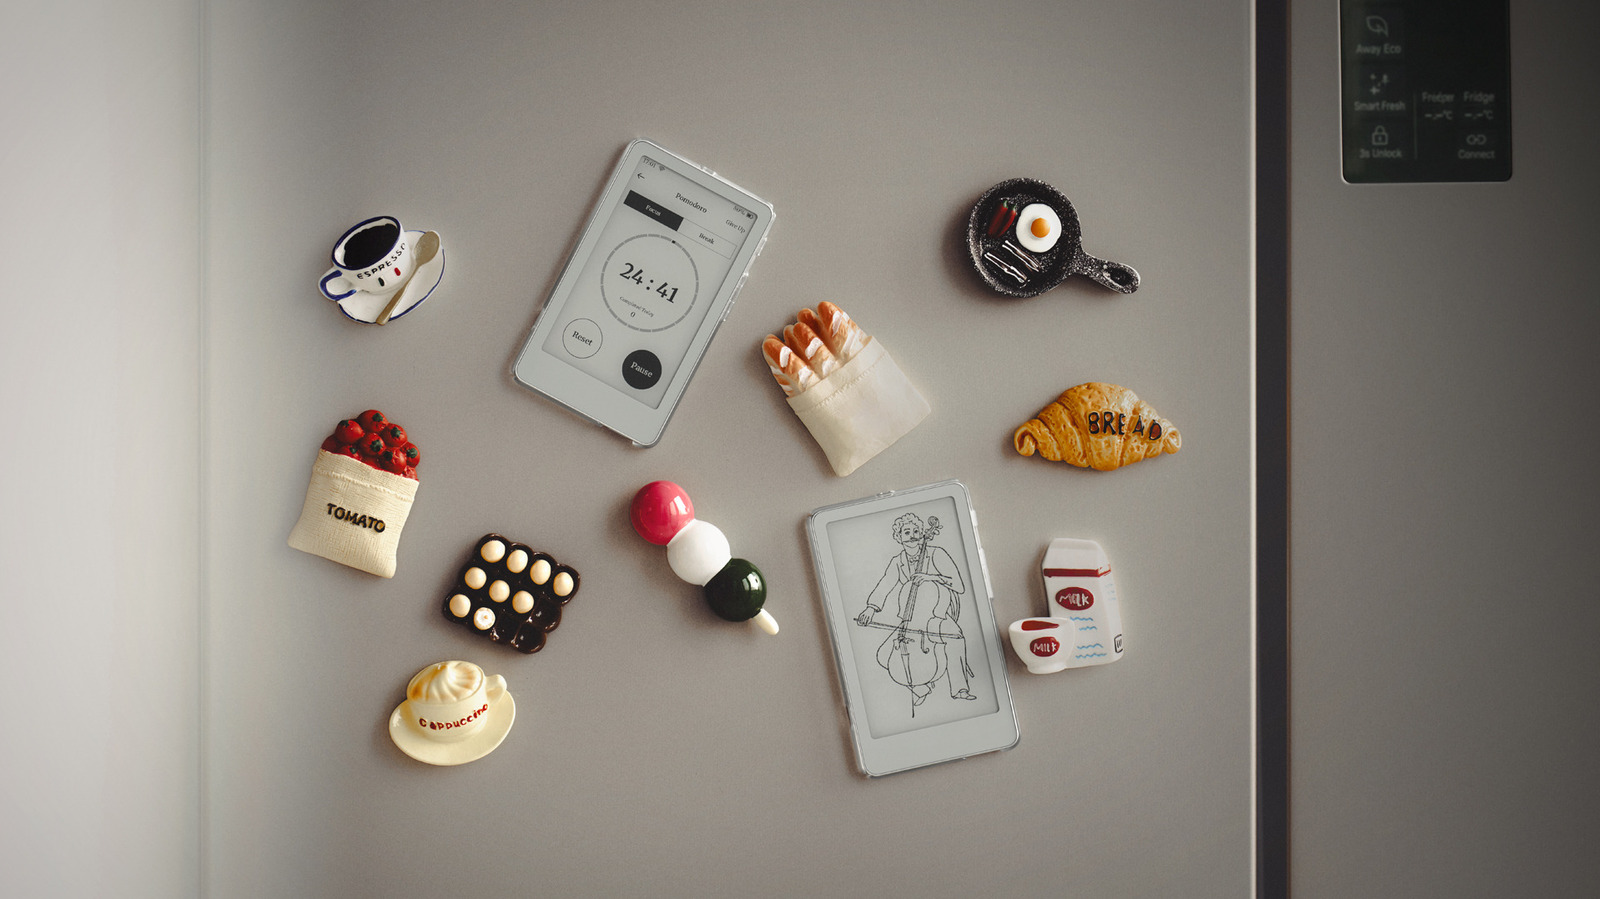
You Can Now Preorder The Tiny Boox Picco Ereader
AI & Technology

You Can Now Preorder The Tiny Boox Picco Ereader

September 28, 2026
20 Agentic Use Cases of TypeSafe AI’s Jev
AI & Technology

20 Agentic Use Cases of TypeSafe AI’s Jev

September 28, 2026
Next Post
Bloomberg Technology 07/08/2022 Elon Musk Ends Twitter Deal

Bloomberg Technology 07/08/2022 Elon Musk Ends Twitter Deal

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
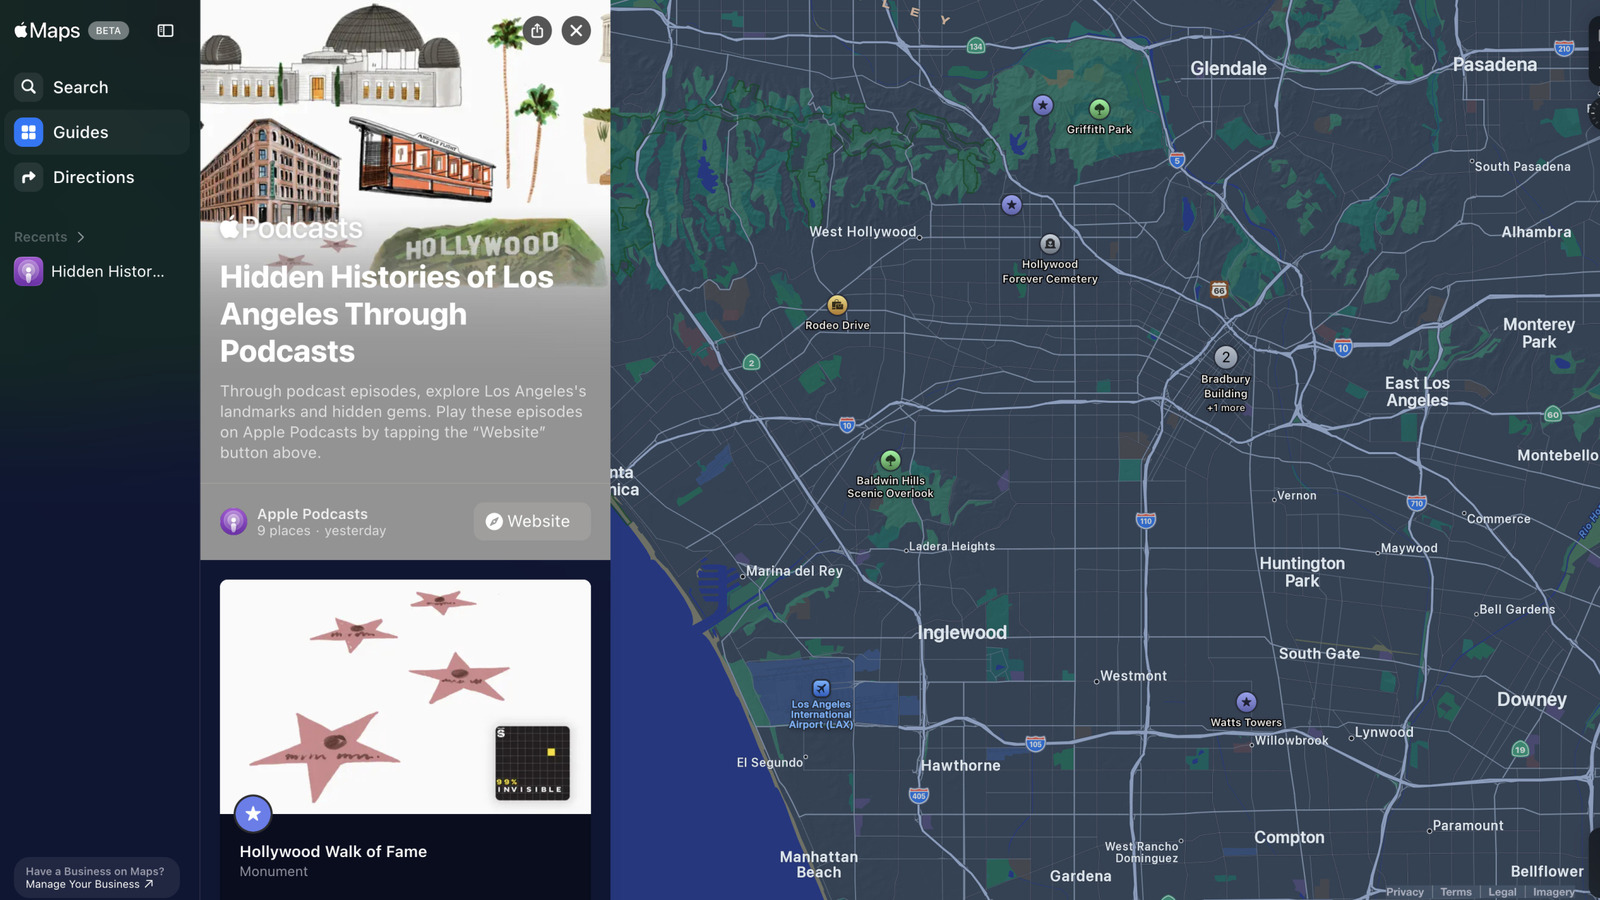
Apple Links Landmarks On Its Maps App To Hidden Histories Podcast Episodes

Apple Links Landmarks On Its Maps App To Hidden Histories Podcast Episodes

September 23, 2026
Trump administration looks to revoke visas of up to 200,000 people

Trump administration looks to revoke visas of up to 200,000 people

September 24, 2026
New report: Utah Valley University tried to warn Charlie Kirk’s staff of risks, but team ignored concerns – The Salt Lake Tribune

New report: Utah Valley University tried to warn Charlie Kirk’s staff of risks, but team ignored concerns – The Salt Lake Tribune

September 26, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!