• bitcoinBitcoin(BTC)$83,554.00-1.49%
  • ethereumEthereum(ETH)$2,689.17-0.72%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$769.65-1.40%
  • rippleXRP(XRP)$1.52-0.81%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$120.07-2.79%
  • tronTRON(TRX)$0.3349780.29%
  • zcashZcash(ZEC)$1,593.83-3.92%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.00-5.78%
  • HyperliquidHyperliquid(HYPE)$90.31-2.77%
  • dogecoinDogecoin(DOGE)$0.094571-3.92%
  • chainlinkChainlink(LINK)$14.723.57%
  • moneroMonero(XMR)$533.58-3.38%
  • whitebitWhiteBIT Coin(WBT)$83.56-1.30%
  • USDSUSDS(USDS)$1.00-0.03%
  • cardanoCardano(ADA)$0.252630-1.65%
  • RainRain(RAIN)$0.012568-0.92%
  • leo-tokenLEO Token(LEO)$9.05-0.15%
  • stellarStellar(XLM)$0.2277905.12%
  • nearNEAR Protocol(NEAR)$5.200.35%
  • bitcoin-cashBitcoin Cash(BCH)$314.65-6.90%
  • uniswapUniswap(UNI)$9.06-7.79%
  • litecoinLitecoin(LTC)$70.92-0.87%
  • hedera-hashgraphHedera(HBAR)$0.12073827.30%
  • CantonCanton(CC)$0.133170-2.34%
  • avalanche-2Avalanche(AVAX)$10.57-3.33%
  • Ethena USDeEthena USDe(USDE)$1.000.00%
  • suiSui(SUI)$1.19-5.30%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.662.94%
  • daiDai(DAI)$1.000.03%
  • USD1USD1(USD1)$1.00-0.02%
  • BitwayBitway(BTW)$1.3013.22%
  • BittensorBittensor(TAO)$308.03-7.41%
  • quant-networkQuant(QNT)$237.2647.93%
  • crypto-com-chainCronos(CRO)$0.0691001.11%
  • shiba-inuShiba Inu(SHIB)$0.000006-3.60%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,158.28-2.86%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • EthenaEthena(ENA)$0.269724-1.30%
  • MemeCoreMemeCore(M)$1.17-2.93%
  • OndoOndo(ONDO)$0.53-2.26%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • okbOKB(OKB)$118.35-2.92%
  • Pump.funPump.fun(PUMP)$0.00531317.61%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • aaveAave(AAVE)$150.57-3.03%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.02%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Meta AI Released MobileLLM-R1: A Edge Reasoning Model with less than 1B Parameters and Achieves 2x–5x Performance Boost Over Other Fully Open-Source AI Models

September 15, 2025
in AI & Technology
Reading Time: 6 mins read
A A
Meta AI Released MobileLLM-R1: A Edge Reasoning Model with less than 1B Parameters and Achieves 2x–5x Performance Boost Over Other Fully Open-Source AI Models
ShareShareShareShareShare

Meta has released MobileLLM-R1, a family of lightweight edge reasoning models now available on Hugging Face. The release includes models ranging from 140M to 950M parameters, with a focus on efficient mathematical, coding, and scientific reasoning at sub-billion scale.

Unlike general-purpose chat models, MobileLLM-R1 is designed for edge deployment, aiming to deliver state-of-the-art reasoning accuracy while remaining computationally efficient.
YOU MAY ALSO LIKE

A Modular, Repairable GPS Watch Is A Good First Step

Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens

What architecture powers MobileLLM-R1?

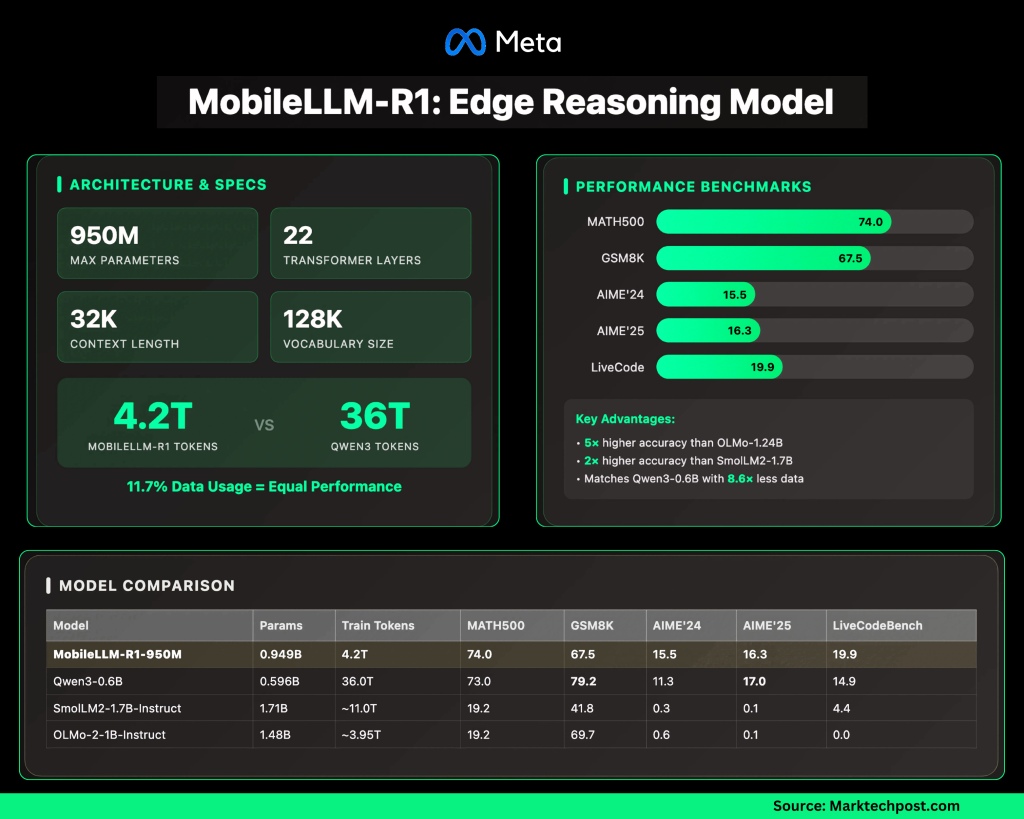
The largest model, MobileLLM-R1-950M, integrates several architectural optimizations:

  • 22 Transformer layers with 24 attention heads and 6 grouped KV heads.
  • Embedding dimension: 1536; hidden dimension: 6144.
  • Grouped-Query Attention (GQA) reduces compute and memory.
  • Block-wise weight sharing cuts parameter count without heavy latency penalties.
  • SwiGLU activations improve small-model representation.
  • Context length: 4K for base, 32K for post-trained models.
  • 128K vocabulary with shared input/output embeddings.

The emphasis is on reducing compute and memory requirements, making it suitable for deployment on constrained devices.

How efficient is the training?

MobileLLM-R1 is notable for data efficiency:

  • Trained on ~4.2T tokens in total.
  • By comparison, Qwen3’s 0.6B model was trained on 36T tokens.
  • This means MobileLLM-R1 uses only ≈11.7% of the data to reach or surpass Qwen3’s accuracy.
  • Post-training applies supervised fine-tuning on math, coding, and reasoning datasets.

This efficiency translates directly into lower training costs and resource demands.

How does it perform against other open models?

On benchmarks, MobileLLM-R1-950M shows significant gains:

  • MATH (MATH500 dataset): ~5× higher accuracy than Olmo-1.24B and ~2× higher accuracy than SmolLM2-1.7B.
  • Reasoning and coding (GSM8K, AIME, LiveCodeBench): Matches or surpasses Qwen3-0.6B, despite using far fewer tokens.

The model delivers results typically associated with larger architectures while maintaining a smaller footprint.

Where does MobileLLM-R1 fall short?

The model’s focus creates limitations:

  • Strong in math, code, and structured reasoning.
  • Weaker in general conversation, commonsense, and creative tasks compared to larger LLMs.
  • Distributed under FAIR NC (non-commercial) license, which restricts usage in production settings.
  • Longer contexts (32K) raise KV-cache and memory demands at inference.

How does MobileLLM-R1 compare to Qwen3, SmolLM2, and OLMo?

Performance snapshot (post-trained models):

Model Params Train tokens (T) MATH500 GSM8K AIME’24 AIME’25 LiveCodeBench
MobileLLM-R1-950M 0.949B 4.2 74.0 67.5 15.5 16.3 19.9
Qwen3-0.6B 0.596B 36.0 73.0 79.2 11.3 17.0 14.9
SmolLM2-1.7B-Instruct 1.71B ~11.0 19.2 41.8 0.3 0.1 4.4
OLMo-2-1B-Instruct 1.48B ~3.95 19.2 69.7 0.6 0.1 0.0

Key observations:

  • R1-950M matches Qwen3-0.6B in math (74.0 vs 73.0) while requiring ~8.6× fewer tokens.
  • Performance gaps vs SmolLM2 and OLMo are substantial across reasoning tasks.
  • Qwen3 maintains an edge in GSM8K, but the difference is small compared to the training efficiency advantage.

Summary

Meta’s MobileLLM-R1 underscores a trend toward smaller, domain-optimized models that deliver competitive reasoning without massive training budgets. By achieving 2×–5× performance gains over larger open models while training on a fraction of the data, it demonstrates that efficiency—not just scale—will define the next phase of LLM deployment, especially for math, coding, and scientific use cases on edge devices.


Check out the Model on Hugging Face. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.

Credit: Source link

ShareTweetSendSharePin

Related Posts

A Modular, Repairable GPS Watch Is A Good First Step
AI & Technology

A Modular, Repairable GPS Watch Is A Good First Step

September 28, 2026
Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens
AI & Technology

Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens

September 28, 2026
You Can Now Preorder The Tiny Boox Picco Ereader
AI & Technology

You Can Now Preorder The Tiny Boox Picco Ereader

September 28, 2026
20 Agentic Use Cases of TypeSafe AI’s Jev
AI & Technology

20 Agentic Use Cases of TypeSafe AI’s Jev

September 28, 2026
Next Post
Video appears to capture moment Charlie Kirk was shot at Utah Valley University

Video appears to capture moment Charlie Kirk was shot at Utah Valley University

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Invesco Senior Floating Rate Fund Q2 2026 Commentary (OOSAX)

Invesco Senior Floating Rate Fund Q2 2026 Commentary (OOSAX)

September 24, 2026
Arista Networks Is Too Risky

Arista Networks Is Too Risky

September 21, 2026
Tesla drivers sleep with driver assistance programs engaged

Tesla drivers sleep with driver assistance programs engaged

September 24, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!