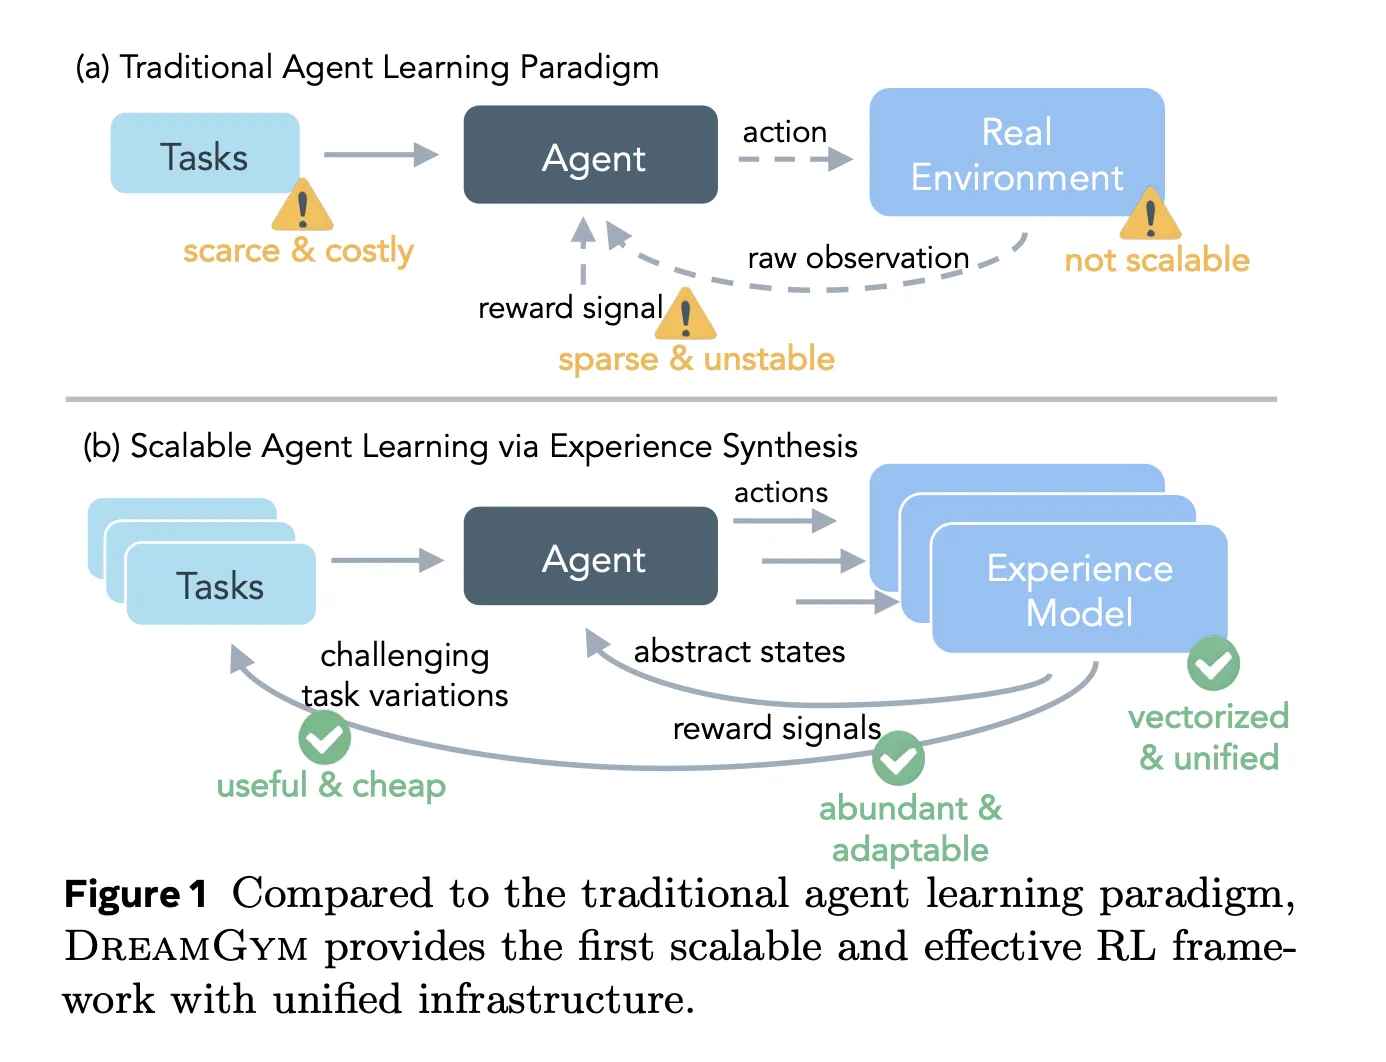

Reinforcement learning RL for large language model LLM agents looks attractive on paper, but in practice it breaks on cost, infrastructure and reward noise. Training an agent that clicks through web pages or completes multi step tool use can easily need tens of thousands of real interactions, each slow, brittle and hard to reset. Meta’s new framework DreamGym reframes that bottleneck as a modeling problem. Instead of running RL directly in environments such as WebShop, ALFWorld and WebArena Lite, it learns a reasoning based experience model that simulates them entirely in text.
Why Real Environment RL for Agents Does Not Scale?
Current RL pipelines for agents face four coupled problems. Real rollouts are costly, task diversity is limited, reward signals are unstable and the infrastructure stack is complex. Web environments change often, rewards depend on fragile scrapers and many actions are irreversible. Reset mechanisms and episode control are also hard to implement, so long horizon tasks become noisy and sample inefficient.
Benchmarks split into two groups. WebShop and ALFWorld are RL ready but expensive, since they still need about 80 thousand real transitions to reach strong baselines with PPO or GRPO. WebArena Lite is not RL ready at all, because resets and automatic reward checks are unreliable, so online RL in the real environment is effectively infeasible.
DreamGym as a Reasoning Based Simulator
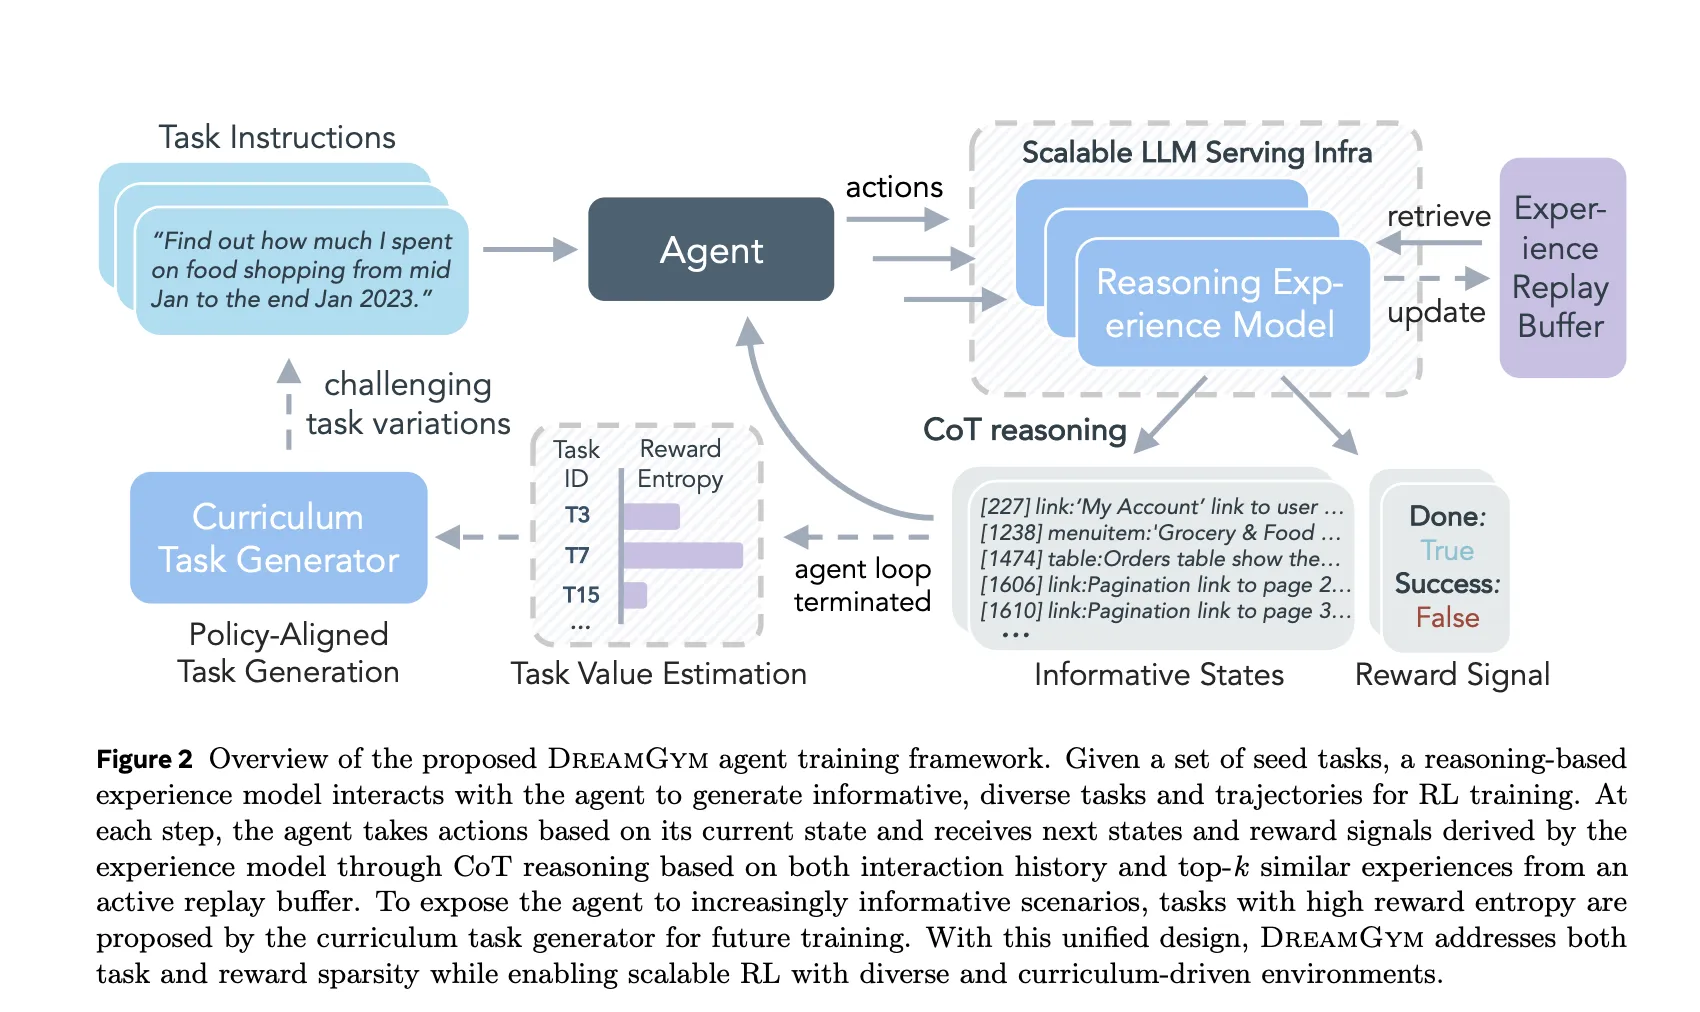
DreamGym is built around three components, a reasoning based experience model, an experience replay buffer and an adaptive curriculum task generator. Together they define a synthetic Markov decision process where the environment lives as text.
The reasoning based experience model Mexp operates in an abstract textual state space. States are compact descriptions of what matters for the task, for example cleaned page elements instead of raw HTML. On each step, the agent provides the current state, the action, the task instruction and the interaction history. The system retrieves the top k similar past transitions from the replay buffer, then uses chain of thought reasoning to produce a reasoning trace, a next state and a reward.
Conceptually, you can view Mexp as an LLM world model for web and tool tasks, but defined purely over text. It is trained with supervised fine tuning on offline trajectories, with a joint objective that learns to generate both the reasoning trace and the next state conditioned on that trace. This forces the model to encode causal structure, not just local text statistics.
Replay Buffer as Grounding Memory
The experience replay buffer is initialized with offline real environment data from WebShop, ALFWorld and WebArena Lite. As DreamGym trains policies in the synthetic environment, it writes new trajectories back into that buffer. Each prediction step in Mexp uses an encoder to retrieve a small set of similar transitions from this memory and conditions on them when generating reasoning and next states.
This retrieval acts as grounding. It keeps synthetic transitions close to the empirical data distribution and reduces hallucinations in long rollouts. The research team showed that removing history or retrieval degrades consistency, informativeness and factuality of the generated states when judged by an external evaluator, and it also lowers downstream success rates on WebShop and WebArena Lite.
Curriculum from Reward Entropy
The curriculum task generator uses the same backbone as the experience model. It selects seed tasks whose outcomes under the current policy have high reward variance, which corresponds to intermediate difficulty tasks that the agent sometimes solves and sometimes fails. For each such task, the model generates variations that preserve action types but change constraints, targets or context.
The selection heuristic is based on reward entropy computed over batches of rollouts for each task. Tasks with non zero variance and balanced success and failure are preferred. Ablations show that turning off this adaptive curriculum causes both WebShop and WebArena Lite performance to drop by around 6 percentage points and leads to early plateaus as the replay buffer saturates with easy, low entropy trajectories.

RL Inside DreamGym and Theoretical Guarantees
Inside DreamGym, the policy uses standard RL algorithms. The research team evaluates Proximal Policy Optimization and Group Relative Policy Optimization. Rollouts alternate between the policy choosing actions and the experience model synthesizing next states and rewards. From the point of view of the RL code, this is just another environment interface.
The research team also derive a trust region style improvement bound that links policy performance in the synthetic MDP and in the real environment. The bound contains error terms that depend on the reward prediction error and the divergence between real and synthetic transition distributions. As those errors shrink, improvement in DreamGym implies improvement in the underlying real task.
Experimental Results on WebShop, ALFWorld and WebArena Lite
DreamGym is tested with Llama-based and Qwen-based agents across WebShop, ALFWorld and WebArena Lite. Results fall into three regimes.
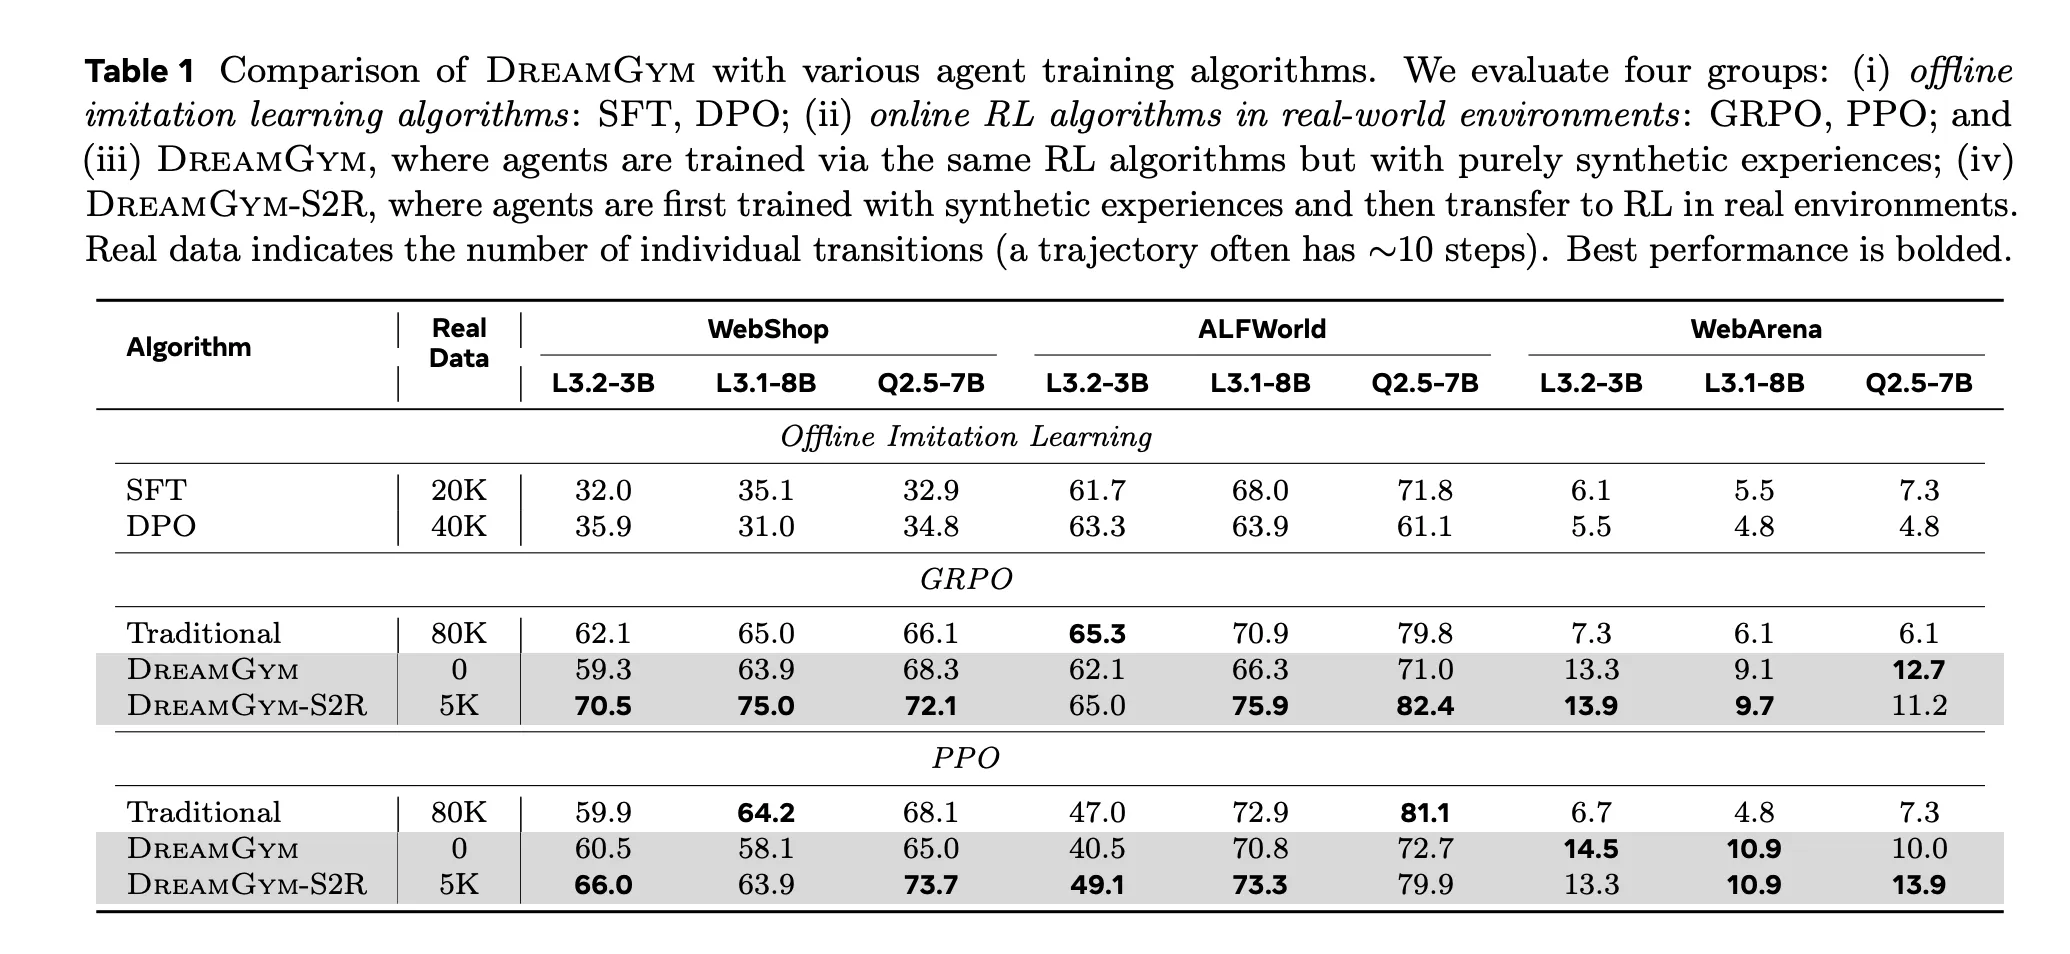
First, in RL ready but costly environments WebShop and ALFWorld, agents trained with PPO or GRPO inside DreamGym, using only synthetic transitions, match the performance of PPO and GRPO baselines that use about 80 thousand real environment interactions. This shows that reasoning based experience synthesis can provide enough signal for stable policy improvement.
Second, in not RL ready environments such as WebArena Lite, DreamGym enables RL training that would otherwise be impractical. The framework achieves more than 30 percent improvement in success rate over all baselines, including supervised fine tuning and direct behavior cloning.
Third, in sim to real transfer, the DreamGym-S2R configuration first trains a policy entirely in the synthetic environment and then fine tunes it with a small number of real rollouts. This setting yields more than 40 percent additional gain compared with training from scratch in the real environment, while using less than 10 percent of the real data and cutting total training cost to roughly between one third and one fifth of the baselines.
Key Takeaways
- DreamGym replaces fragile real environment rollouts with a reasoning based experience model that operates in an abstract textual state space, predicting next state and reward from history, task and retrieved similar transitions.
- The framework combines 3 components, a reasoning experience model, an experience replay buffer seeded with real trajectories, and a curriculum task generator that selects and varies tasks using a reward entropy heuristic, which together stabilize and diversify RL training.
- In WebShop and ALFWorld, which are RL ready but expensive, agents trained with PPO or GRPO entirely inside DreamGym using synthetic interactions match the performance of PPO and GRPO baselines that use about 80,000 real environment transitions.
- In WebArena Lite, which is not RL ready, DreamGym enables online RL and achieves more than 30 percent higher success rate than all non RL baselines including supervised fine tuning and behavior cloning.
- In the sim to real configuration, policies pretrained in DreamGym and then fine tuned with a small number of real rollouts achieve more than 40 percent additional improvement while using less than 10 percent of the real interaction budget and reducing total training cost to around one third to one fifth of standard RL.
Editorial Comments
DreamGym is an important step toward practical reinforcement learning for LLM agents because it reframes the environment as a reasoning based experience model, grounded by an experience replay buffer and a reward entropy driven curriculum, rather than as a fragile browser stack. The reported gains on WebArena Lite, WebShop and ALFWorld with PPO and GRPO suggest that synthetic experience plus Sim to Real adaptation can become a standard pattern for agent training at scale. Overall, DreamGym makes the experience model, not the policy, the main lever for scaling RL agents.
Check out the Full Paper. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
The post Meta AI Introduces DreamGym: A Textual Experience Synthesizer For Reinforcement learning RL Agents appeared first on MarkTechPost.
Credit: Source link