• bitcoinBitcoin(BTC)$77,786.000.21%
  • ethereumEthereum(ETH)$2,505.78-0.26%
  • tetherTether(USDT)$1.000.02%
  • binancecoinBNB(BNB)$720.59-0.46%
  • rippleXRP(XRP)$1.423.65%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$101.760.71%
  • tronTRON(TRX)$0.337776-0.22%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.00%
  • zcashZcash(ZEC)$1,150.633.49%
  • HyperliquidHyperliquid(HYPE)$79.790.45%
  • dogecoinDogecoin(DOGE)$0.083639-0.51%
  • RainRain(RAIN)$0.014243-6.91%
  • USDSUSDS(USDS)$1.000.00%
  • moneroMonero(XMR)$514.69-1.31%
  • whitebitWhiteBIT Coin(WBT)$80.490.08%
  • chainlinkChainlink(LINK)$11.531.04%
  • leo-tokenLEO Token(LEO)$8.96-0.83%
  • cardanoCardano(ADA)$0.206903-0.28%
  • stellarStellar(XLM)$0.1956738.27%
  • Ethena USDeEthena USDe(USDE)$1.000.03%
  • daiDai(DAI)$1.000.01%
  • bitcoin-cashBitcoin Cash(BCH)$222.23-0.72%
  • USD1USD1(USD1)$1.00-0.01%
  • uniswapUniswap(UNI)$6.583.90%
  • litecoinLitecoin(LTC)$52.89-2.91%
  • CantonCanton(CC)$0.095957-0.50%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.34-0.64%
  • hedera-hashgraphHedera(HBAR)$0.0780572.71%
  • avalanche-2Avalanche(AVAX)$7.551.83%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • nearNEAR Protocol(NEAR)$2.432.63%
  • shiba-inuShiba Inu(SHIB)$0.000005-0.22%
  • suiSui(SUI)$0.720.69%
  • paypal-usdPayPal USD(PYUSD)$1.000.03%
  • crypto-com-chainCronos(CRO)$0.0588461.29%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,311.74-0.51%
  • BittensorBittensor(TAO)$232.51-1.56%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • MemeCoreMemeCore(M)$1.10-2.80%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • okbOKB(OKB)$113.23-0.83%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.15%
  • aaveAave(AAVE)$127.501.37%
  • BitwayBitway(BTW)$0.712.87%
  • mantleMantle(MNT)$0.572.69%
  • AsterAster(ASTER)$0.69-0.51%
  • pax-goldPAX Gold(PAXG)$4,314.26-0.50%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0570210.01%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Meet Video-LLaMA: A Multi-Modal Framework that Empowers Large Language Models (LLMs) with the Capability of Understanding both Visual and Auditory Content in the Video

June 11, 2023
in AI & Technology
Reading Time: 4 mins read
A A
Meet Video-LLaMA: A Multi-Modal Framework that Empowers Large Language Models (LLMs) with the Capability of Understanding both Visual and Auditory Content in the Video
ShareShareShareShareShare

Generative Artificial Intelligence has become increasingly popular in the past few months. Being a subset of AI, it enables Large Language Models (LLMs) to generate new data by learning from massive amounts of available textual data. LLMs understand and follow user intentions and instructions by means of text-based conversations. These models imitate humans to produce new and creative content, summarize long paragraphs of text, answer questions precisely, and so on. LLMs are limited to text-based conversations, which comes as a limitation as text-only interaction between a human and a computer is not the most optimal form of communication for a powerful AI assistant or a chatbot.

Researchers have been trying to integrate visual understanding capabilities in LLMs, such as the BLIP-2 framework, which performs vision-language pre-training by using frozen pre-trained image encoders and language decoders. Though efforts have been made to add vision to LLMs, the integration of videos which contributes to a huge part of the content on social media, is still a challenge. This is because it can be difficult to comprehend non-static visual scenes in videos effectively, and it is more difficult to close the modal gap between images and text than it is to close the modal gap between video and text because it requires processing both visual and audio inputs.

To address the challenges, a team of researchers from DAMO Academy, Alibaba Group, has introduced Video-LLaMA, an instruction-tuned audio-visual language model for video understanding. This multi-modal framework enhances language models with the ability to understand both visual and auditory content in videos. Video-LLaMA explicitly addresses the difficulties of integrating audio-visual information and the challenges of temporal changes in visual scenes, in contrast to prior vision-LLMs that focus solely on static image understanding.

🚀 JOIN the fastest ML Subreddit Community

The team has also introduced a Video Q-former that captures the temporal changes in visual scenes. This component assembles the pre-trained image encoder into the video encoder and enables the model to process video frames. Using a video-to-text generation task, the model is trained on the connection between videos and textual descriptions. ImageBind has been used to integrate audio-visual signals as the pre-trained audio encoder. It is a universal embedding model that aligns various modalities and is known for its ability to handle various types of input and generate unified embeddings. Audio Q-former has also been used on the top of ImageBind to learn reasonable auditory query embeddings for the LLM module.

Video-LLaMA has been trained on large-scale video and image-caption pairs to align the output of both the visual and audio encoders with the LLM’s embedding space. This training data allows the model to learn the correspondence between visual and textual information. Video-LLaMA is fine-tuned on visual-instruction-tuning datasets that provide higher-quality data for training the model to generate responses grounded in visual and auditory information.

Upon evaluation, experiments have shown that Video-LLaMA can perceive and understand video content, and it produces insightful replies that are influenced by the audio-visual data offered in the videos. In conclusion, Video-LLaMA has a lot of potential as an audio-visual AI assistant prototype that can react to both visual and audio inputs in videos and can empower LLMs with audio and video understanding capabilities.


Check Out The Paper and Github. Don’t forget to join our 23k+ ML SubReddit, Discord Channel, and Email Newsletter, where we share the latest AI research news, cool AI projects, and more. If you have any questions regarding the above article or if we missed anything, feel free to email us at [email protected]

🚀 Check Out 100’s AI Tools in AI Tools Club


YOU MAY ALSO LIKE

How To Use Meta Display Glasses While Driving With The Audio Only Feature

The EPA Wants To Stop Regulating Power Plant Emissions

Tanya Malhotra is a final year undergrad from the University of Petroleum & Energy Studies, Dehradun, pursuing BTech in Computer Science Engineering with a specialization in Artificial Intelligence and Machine Learning.
She is a Data Science enthusiast with good analytical and critical thinking, along with an ardent interest in acquiring new skills, leading groups, and managing work in an organized manner.


Check out https://aitoolsclub.com to find 100’s of Cool AI Tools

Credit: Source link

ShareTweetSendSharePin

Related Posts

How To Use Meta Display Glasses While Driving With The Audio Only Feature
AI & Technology

How To Use Meta Display Glasses While Driving With The Audio Only Feature

September 15, 2026
The EPA Wants To Stop Regulating Power Plant Emissions
AI & Technology

The EPA Wants To Stop Regulating Power Plant Emissions

September 14, 2026
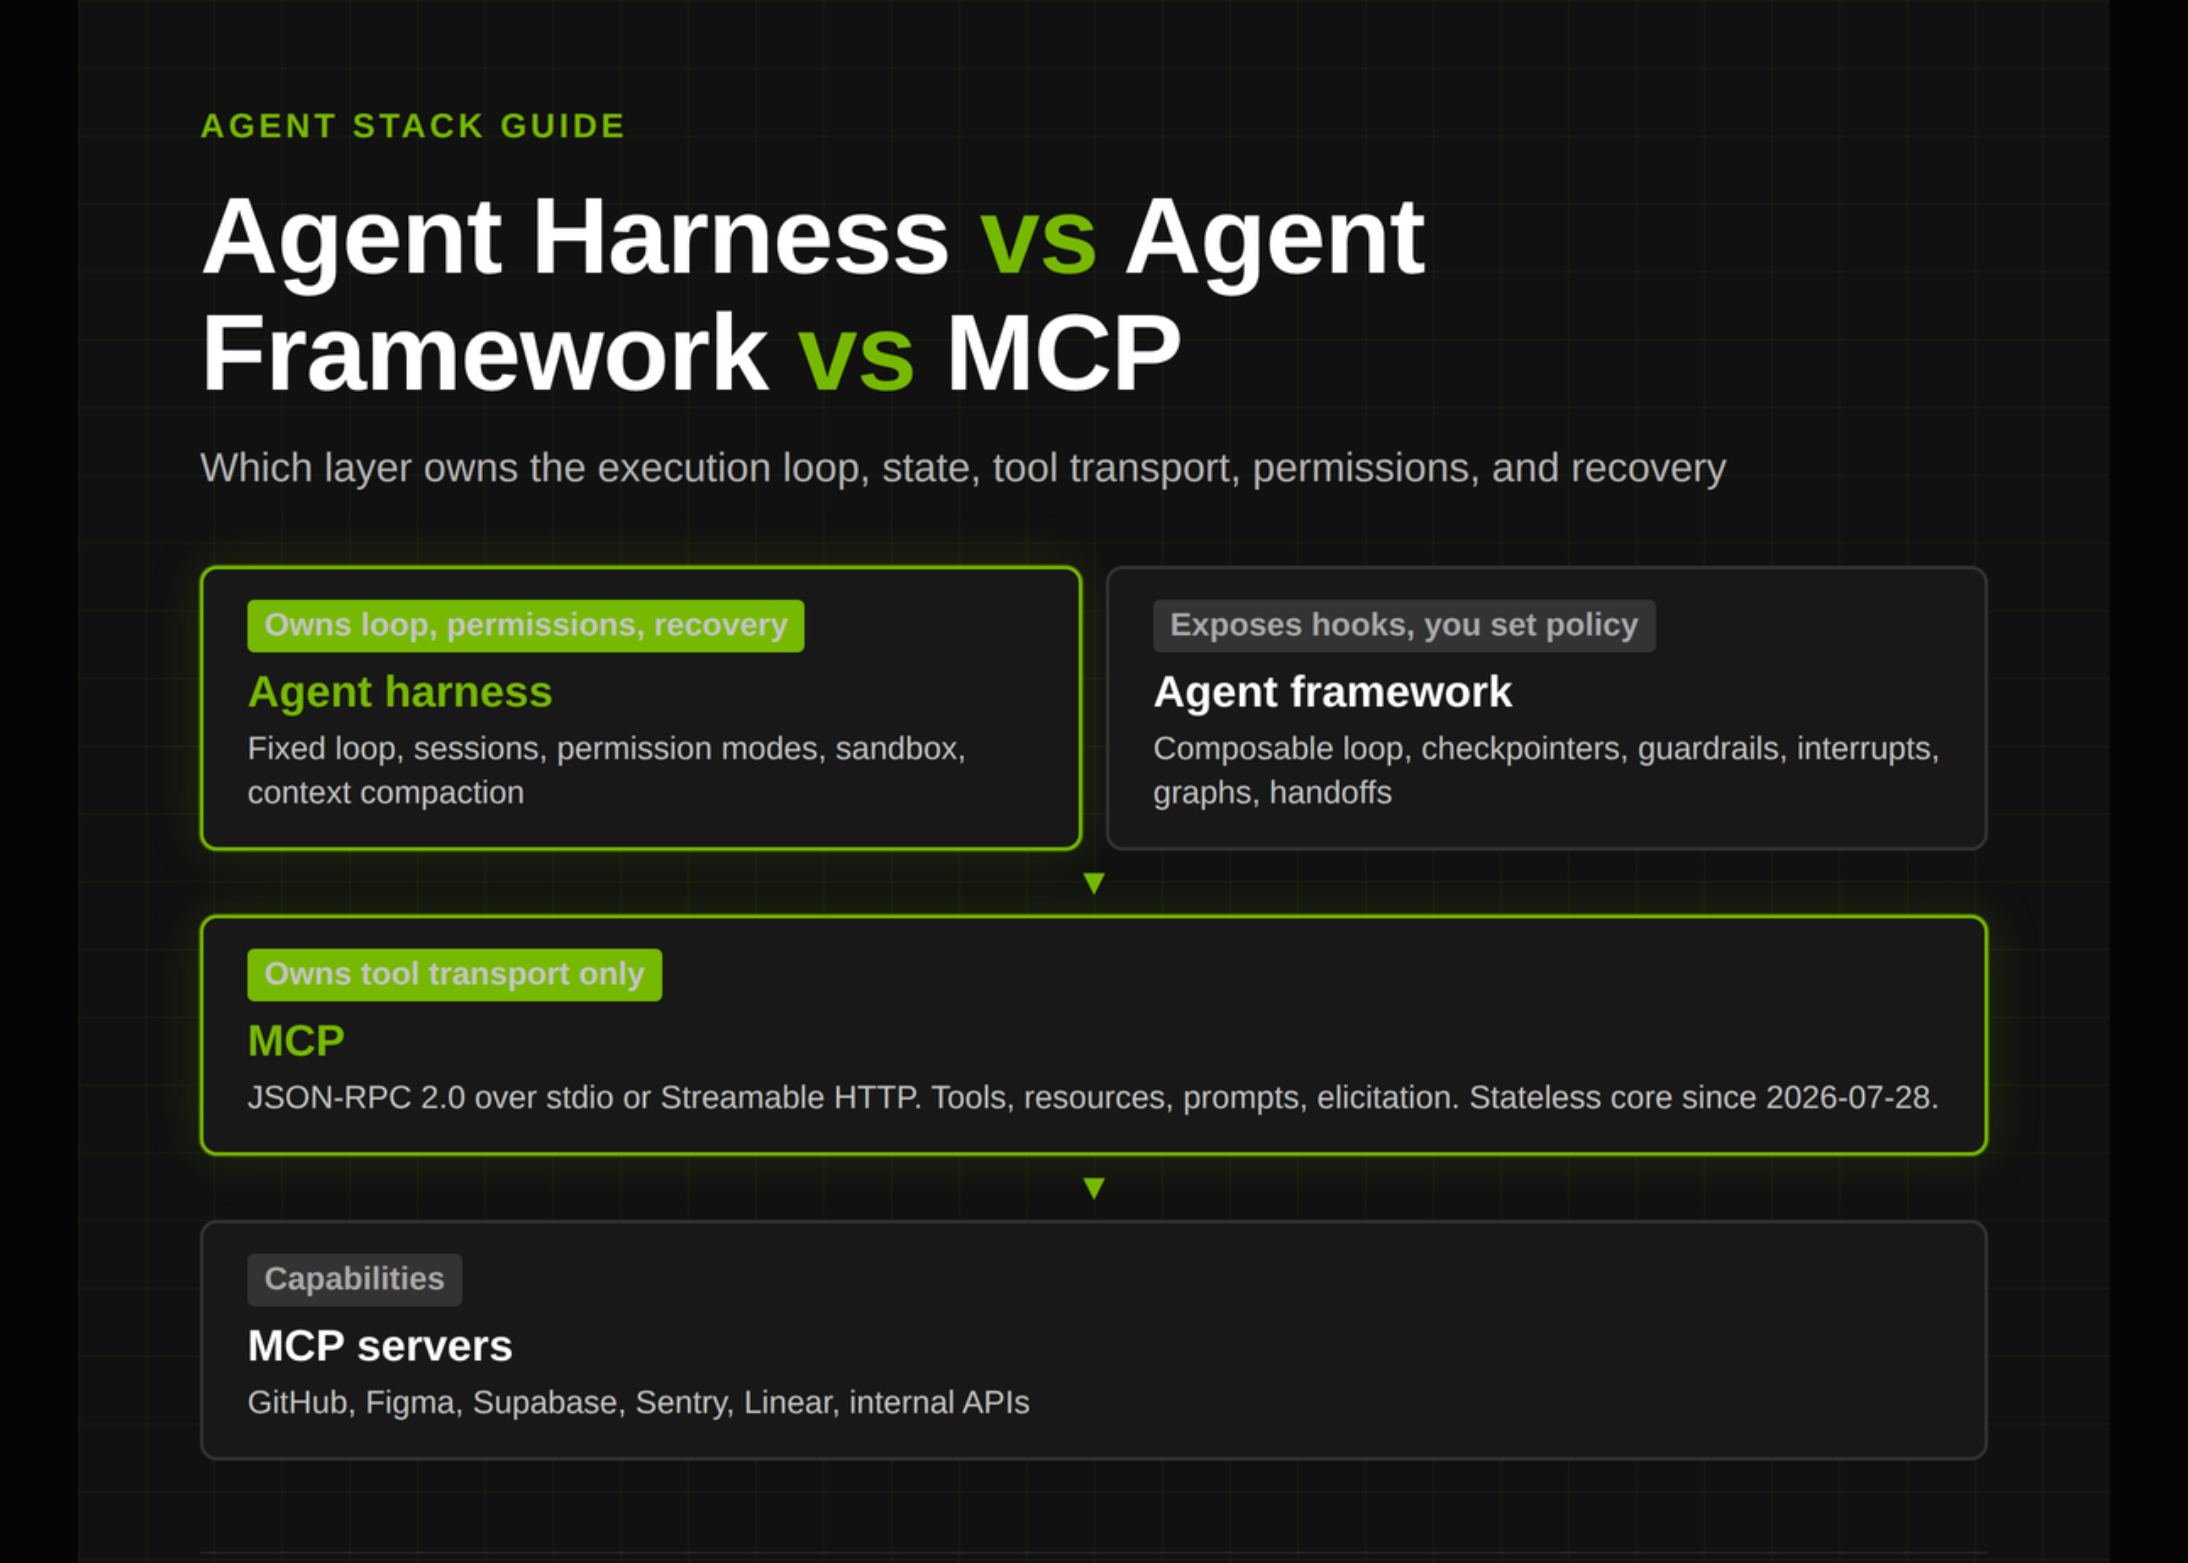
Agent Harness vs Agent Framework vs MCP: Which Layer Owns the Loop, State, Tools, Permissions, and Recovery
AI & Technology

Agent Harness vs Agent Framework vs MCP: Which Layer Owns the Loop, State, Tools, Permissions, and Recovery

September 14, 2026
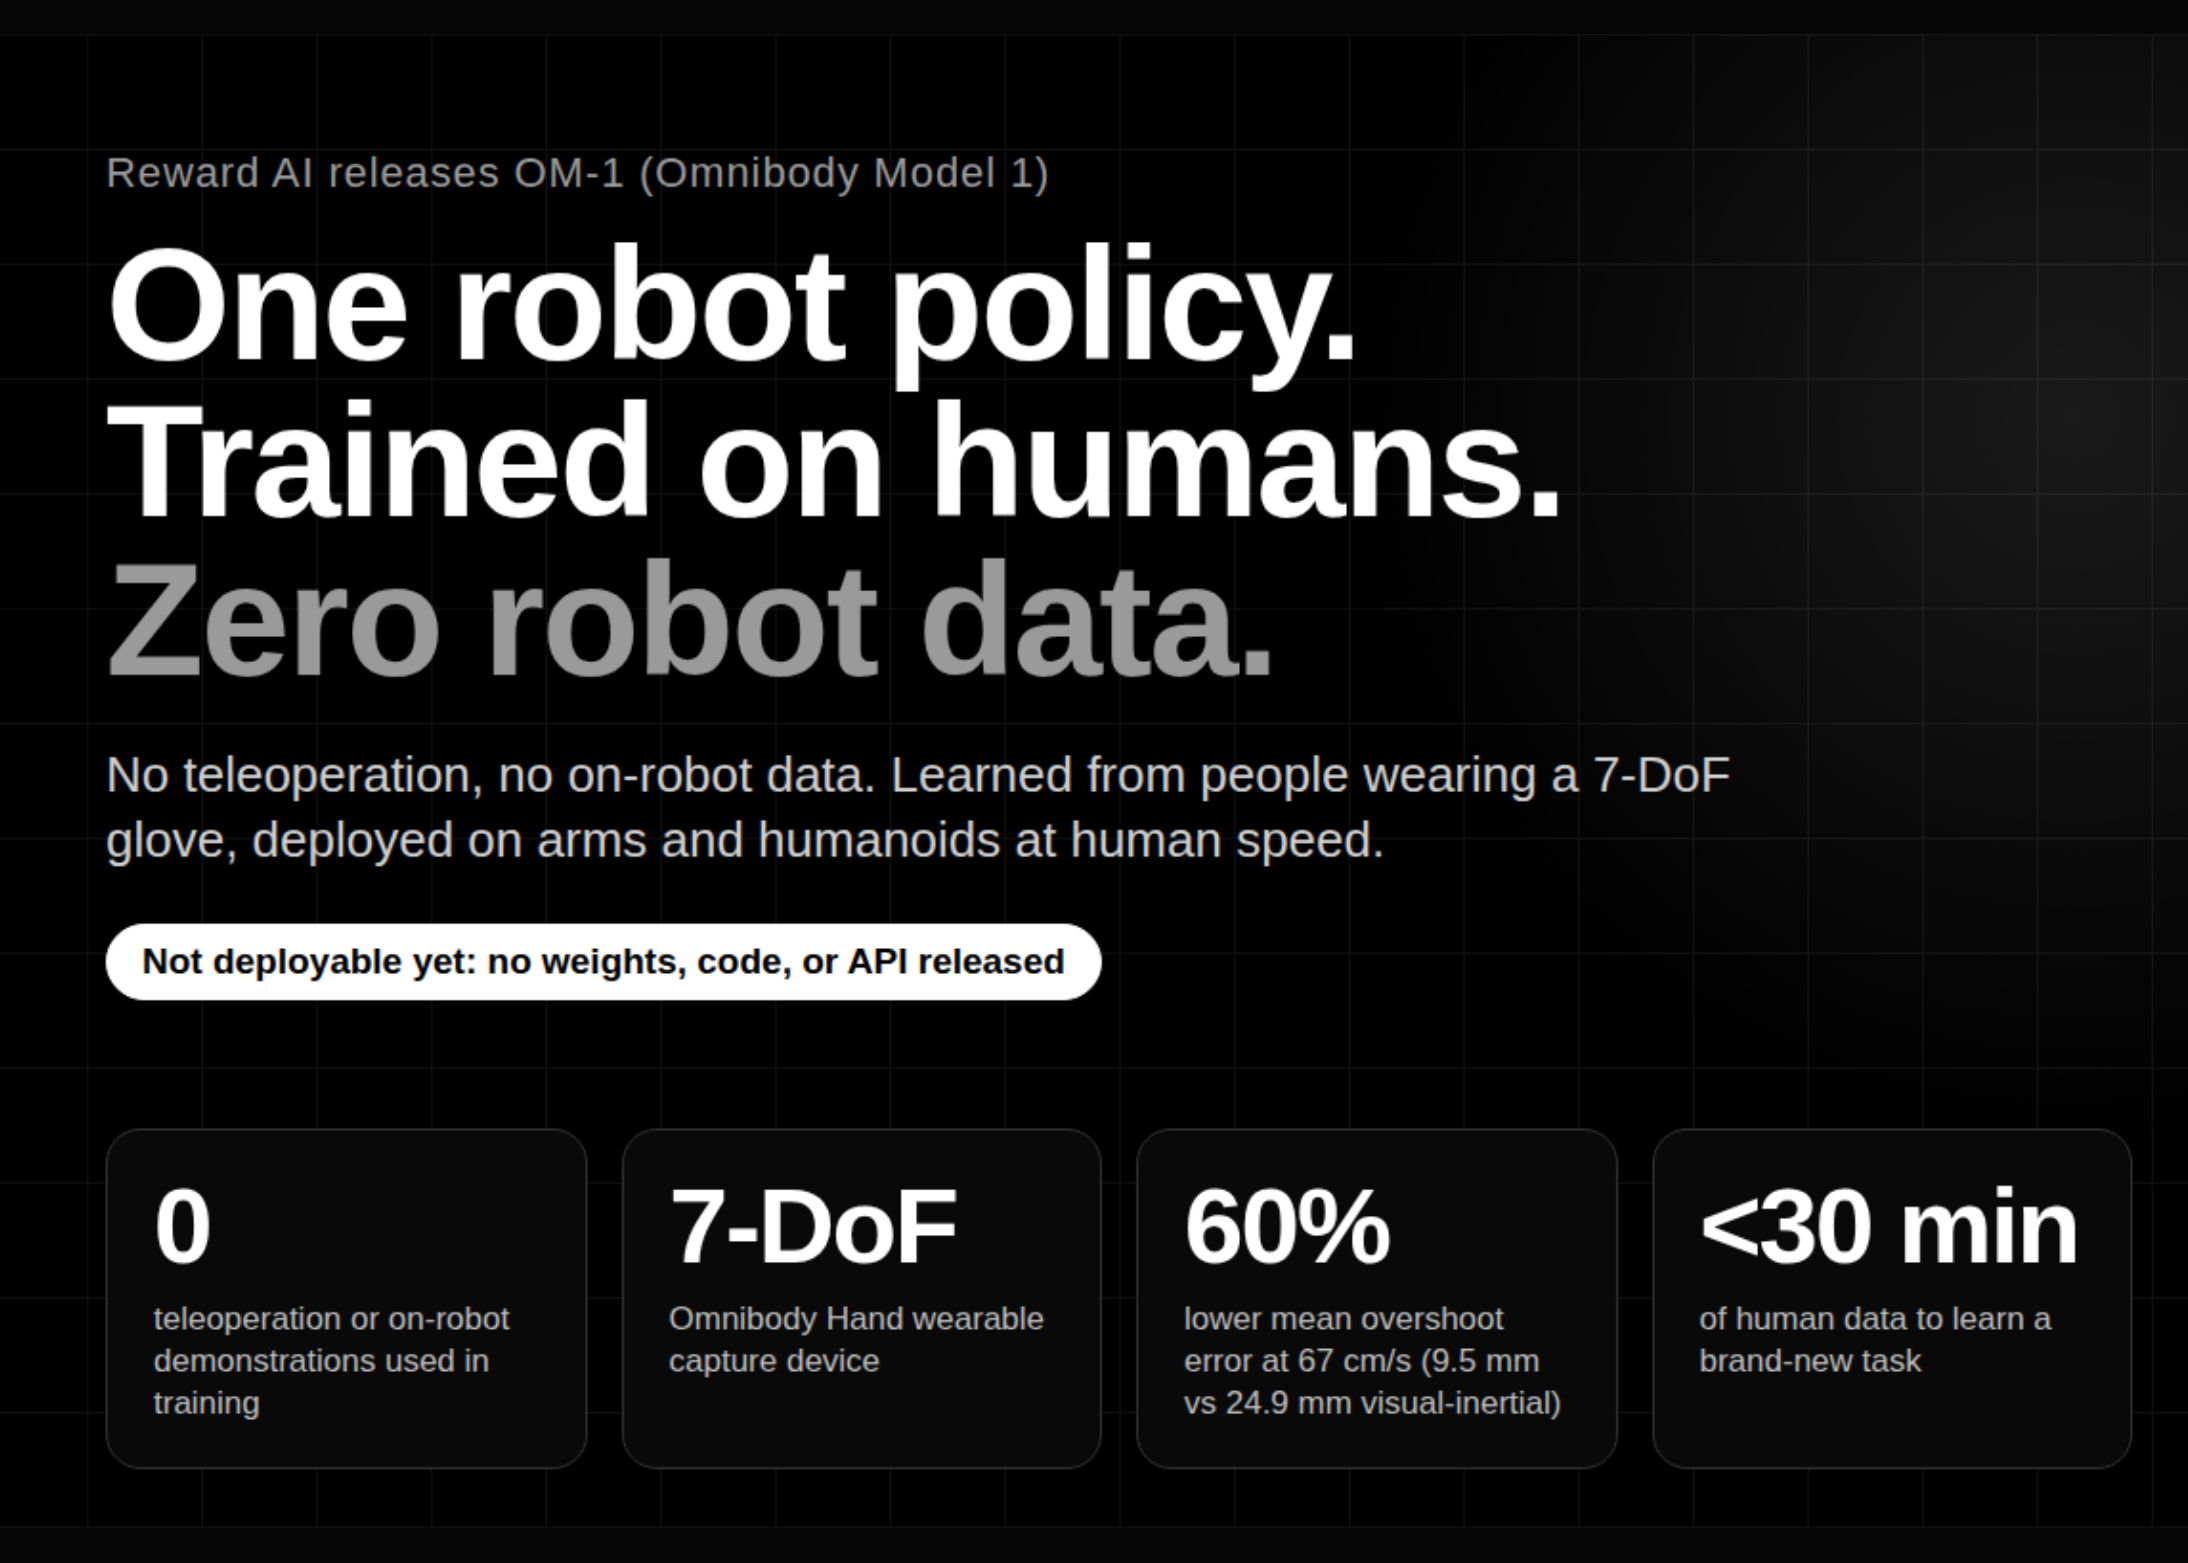
Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data
AI & Technology

Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data

September 14, 2026
Next Post
MY 700HP NISSAN GT-R BROKE DOWN ** NOT CLICKBAIT**

MY 700HP NISSAN GT-R BROKE DOWN ** NOT CLICKBAIT**

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
The Texas ‘Trumpapalooza,’ and Will AI ‘Kill Us All’ Within A Decade? | Sept. 10

The Texas ‘Trumpapalooza,’ and Will AI ‘Kill Us All’ Within A Decade? | Sept. 10

September 14, 2026
How India Is Training The Robots Of The Future

How India Is Training The Robots Of The Future

September 12, 2026
Cancer is killing FBI agents who responded on 9/11

Cancer is killing FBI agents who responded on 9/11

September 12, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!