• bitcoinBitcoin(BTC)$84,151.000.46%
  • ethereumEthereum(ETH)$2,723.801.00%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$764.30-0.43%
  • rippleXRP(XRP)$1.551.46%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$121.040.74%
  • tronTRON(TRX)$0.3349020.01%
  • zcashZcash(ZEC)$1,444.15-9.18%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.00-5.29%
  • HyperliquidHyperliquid(HYPE)$88.14-1.50%
  • dogecoinDogecoin(DOGE)$0.0957071.34%
  • chainlinkChainlink(LINK)$15.142.32%
  • moneroMonero(XMR)$544.091.95%
  • whitebitWhiteBIT Coin(WBT)$84.210.55%
  • USDSUSDS(USDS)$1.00-0.01%
  • cardanoCardano(ADA)$0.2514390.34%
  • RainRain(RAIN)$0.012439-1.32%
  • leo-tokenLEO Token(LEO)$9.03-0.35%
  • stellarStellar(XLM)$0.2318013.57%
  • nearNEAR Protocol(NEAR)$4.89-6.73%
  • bitcoin-cashBitcoin Cash(BCH)$310.96-0.84%
  • uniswapUniswap(UNI)$9.02-0.24%
  • litecoinLitecoin(LTC)$68.02-3.57%
  • CantonCanton(CC)$0.130346-0.49%
  • avalanche-2Avalanche(AVAX)$11.6410.31%
  • hedera-hashgraphHedera(HBAR)$0.112772-6.95%
  • Ethena USDeEthena USDe(USDE)$1.000.01%
  • suiSui(SUI)$1.16-2.69%
  • daiDai(DAI)$1.000.00%
  • USD1USD1(USD1)$1.000.01%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.55-6.41%
  • quant-networkQuant(QNT)$258.015.22%
  • BittensorBittensor(TAO)$311.960.69%
  • BitwayBitway(BTW)$1.31-3.72%
  • crypto-com-chainCronos(CRO)$0.0705892.56%
  • shiba-inuShiba Inu(SHIB)$0.0000061.68%
  • tether-goldTether Gold(XAUT)$4,160.600.04%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • Pump.funPump.fun(PUMP)$0.00584210.85%
  • paypal-usdPayPal USD(PYUSD)$1.000.01%
  • aaveAave(AAVE)$172.7214.76%
  • EthenaEthena(ENA)$0.257289-5.18%
  • okbOKB(OKB)$121.332.54%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • OndoOndo(ONDO)$0.51-3.10%
  • MemeCoreMemeCore(M)$1.06-9.62%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.03%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Meet AudioLDM 2: A Unique AI Framework For Audio Generation That Blends Speech, Music, And Sound Effects

August 23, 2023
in AI & Technology
Reading Time: 4 mins read
A A
Meet AudioLDM 2: A Unique AI Framework For Audio Generation That Blends Speech, Music, And Sound Effects
ShareShareShareShareShare

In a world increasingly reliant on the concepts of Artificial Intelligence and Deep Learning, the realm of audio generation is experiencing a groundbreaking transformation with the introduction of AudioLDM 2. This innovative framework has paved the way for an integrated method of audio synthesis, revolutionizing the way we produce and perceive sound in a variety of contexts, including speech, music, and sound effects. Producing audio information depending on particular variables, such as text, phonemes, or visuals, is known as audio generation. This includes a number of subdomains, including voice, music, sound effects, and even particular sounds like violin or footstep sounds.

Each sub-domain comes with its own challenges, and previous works have often used specialized models tailored to those challenges. Inductive biases, which are predetermined limitations that direct the learning process toward addressing a certain problem, are task-specific biases in these models. These limitations prevent the use of audio generation in complicated situations where many forms of sounds coexist, such as movie sequences, despite great advancements in specialized models. A unified strategy that can provide a variety of audio signals is required.

To address these issues, a team of researchers has introduced AudioLDM 2, a unique framework with adjustable conditions that attempt to generate any type of audio without relying on domain-specific biases. The team has introduced the “language of audio” (LOA), which is a sequence of vectors representing the semantic information of an audio clip. This LOA enables the conversion of information that humans understand into a format suited for producing audio dependent on LOA, thereby capturing both fine-grained auditory features and coarse-grained semantic information.

The team has suggested building on an Audio Mask Autoencoder (AudioMAE) that has been pre-trained on a variety of audio sources to do this. The optimum audio representation for generative tasks is produced by the pre-training framework, which includes reconstructive and generative activities. Then conditioning information like text, audio, and graphics is converted into the AudioMAE feature using a GPT-based language model. Depending on the AudioMAE characteristic, audio is synthesized using a latent diffusion model, and this model is amenable to self-supervised optimization, allowing for pre-training on unlabeled audio data. While addressing difficulties with computing costs and error accumulation present in earlier audio models, the language-modeling technique takes advantage of recent developments in language models.

Upon evaluation, experiments have shown that AudioLDM 2 performs at the cutting edge in tasks requiring text-to-audio and text-to-music production. It outperforms powerful baseline models in tasks requiring text-to-speech, and for activities like producing images to sounds, the framework can additionally include criteria for visual modality. In-context learning for audio, music, and voice are also researched as ancillary features. In comparison, AudioLDM 2 outperforms AudioLDM in terms of quality, adaptability, and the production of understandable speech.

The key contributions have been summarized by the team as follows.

  1. An innovative and adaptable audio generation model has been introduced, which is capable of generating audio, music, and understandable speech with conditions.
  1. The approach has been built upon a universal audio representation, allowing extensive self-supervised pre-training of the core latent diffusion model without needing annotated audio data. This integration combines the strengths of auto-regressive and latent diffusion models.
  1. Through experiments, AudioLDM 2 has been validated as it attains state-of-the-art performance in text-to-audio and text-to-music generation. It has achieved competitive outcomes in text-to-speech generation comparable to the current state-of-the-art methods.

Check out the Paper and Github. All Credit For This Research Goes To the Researchers on This Project. Also, don’t forget to join our 29k+ ML SubReddit, 40k+ Facebook Community, Discord Channel, and Email Newsletter, where we share the latest AI research news, cool AI projects, and more.

If you like our work, please follow us on Twitter


YOU MAY ALSO LIKE

Why Wi-Fi Extenders Simply Aren’t Worth Buying In 2026

Nothing’s Flagship $399 Headphone 1 Pro Actually Have Some Professional Features

Tanya Malhotra is a final year undergrad from the University of Petroleum & Energy Studies, Dehradun, pursuing BTech in Computer Science Engineering with a specialization in Artificial Intelligence and Machine Learning.
She is a Data Science enthusiast with good analytical and critical thinking, along with an ardent interest in acquiring new skills, leading groups, and managing work in an organized manner.


🚀 CodiumAI enables busy developers to generate meaningful tests (Sponsored)


Credit: Source link

ShareTweetSendSharePin

Related Posts

Why Wi-Fi Extenders Simply Aren’t Worth Buying In 2026
AI & Technology

Why Wi-Fi Extenders Simply Aren’t Worth Buying In 2026

September 29, 2026
Nothing’s Flagship 9 Headphone 1 Pro Actually Have Some Professional Features
AI & Technology

Nothing’s Flagship $399 Headphone 1 Pro Actually Have Some Professional Features

September 29, 2026
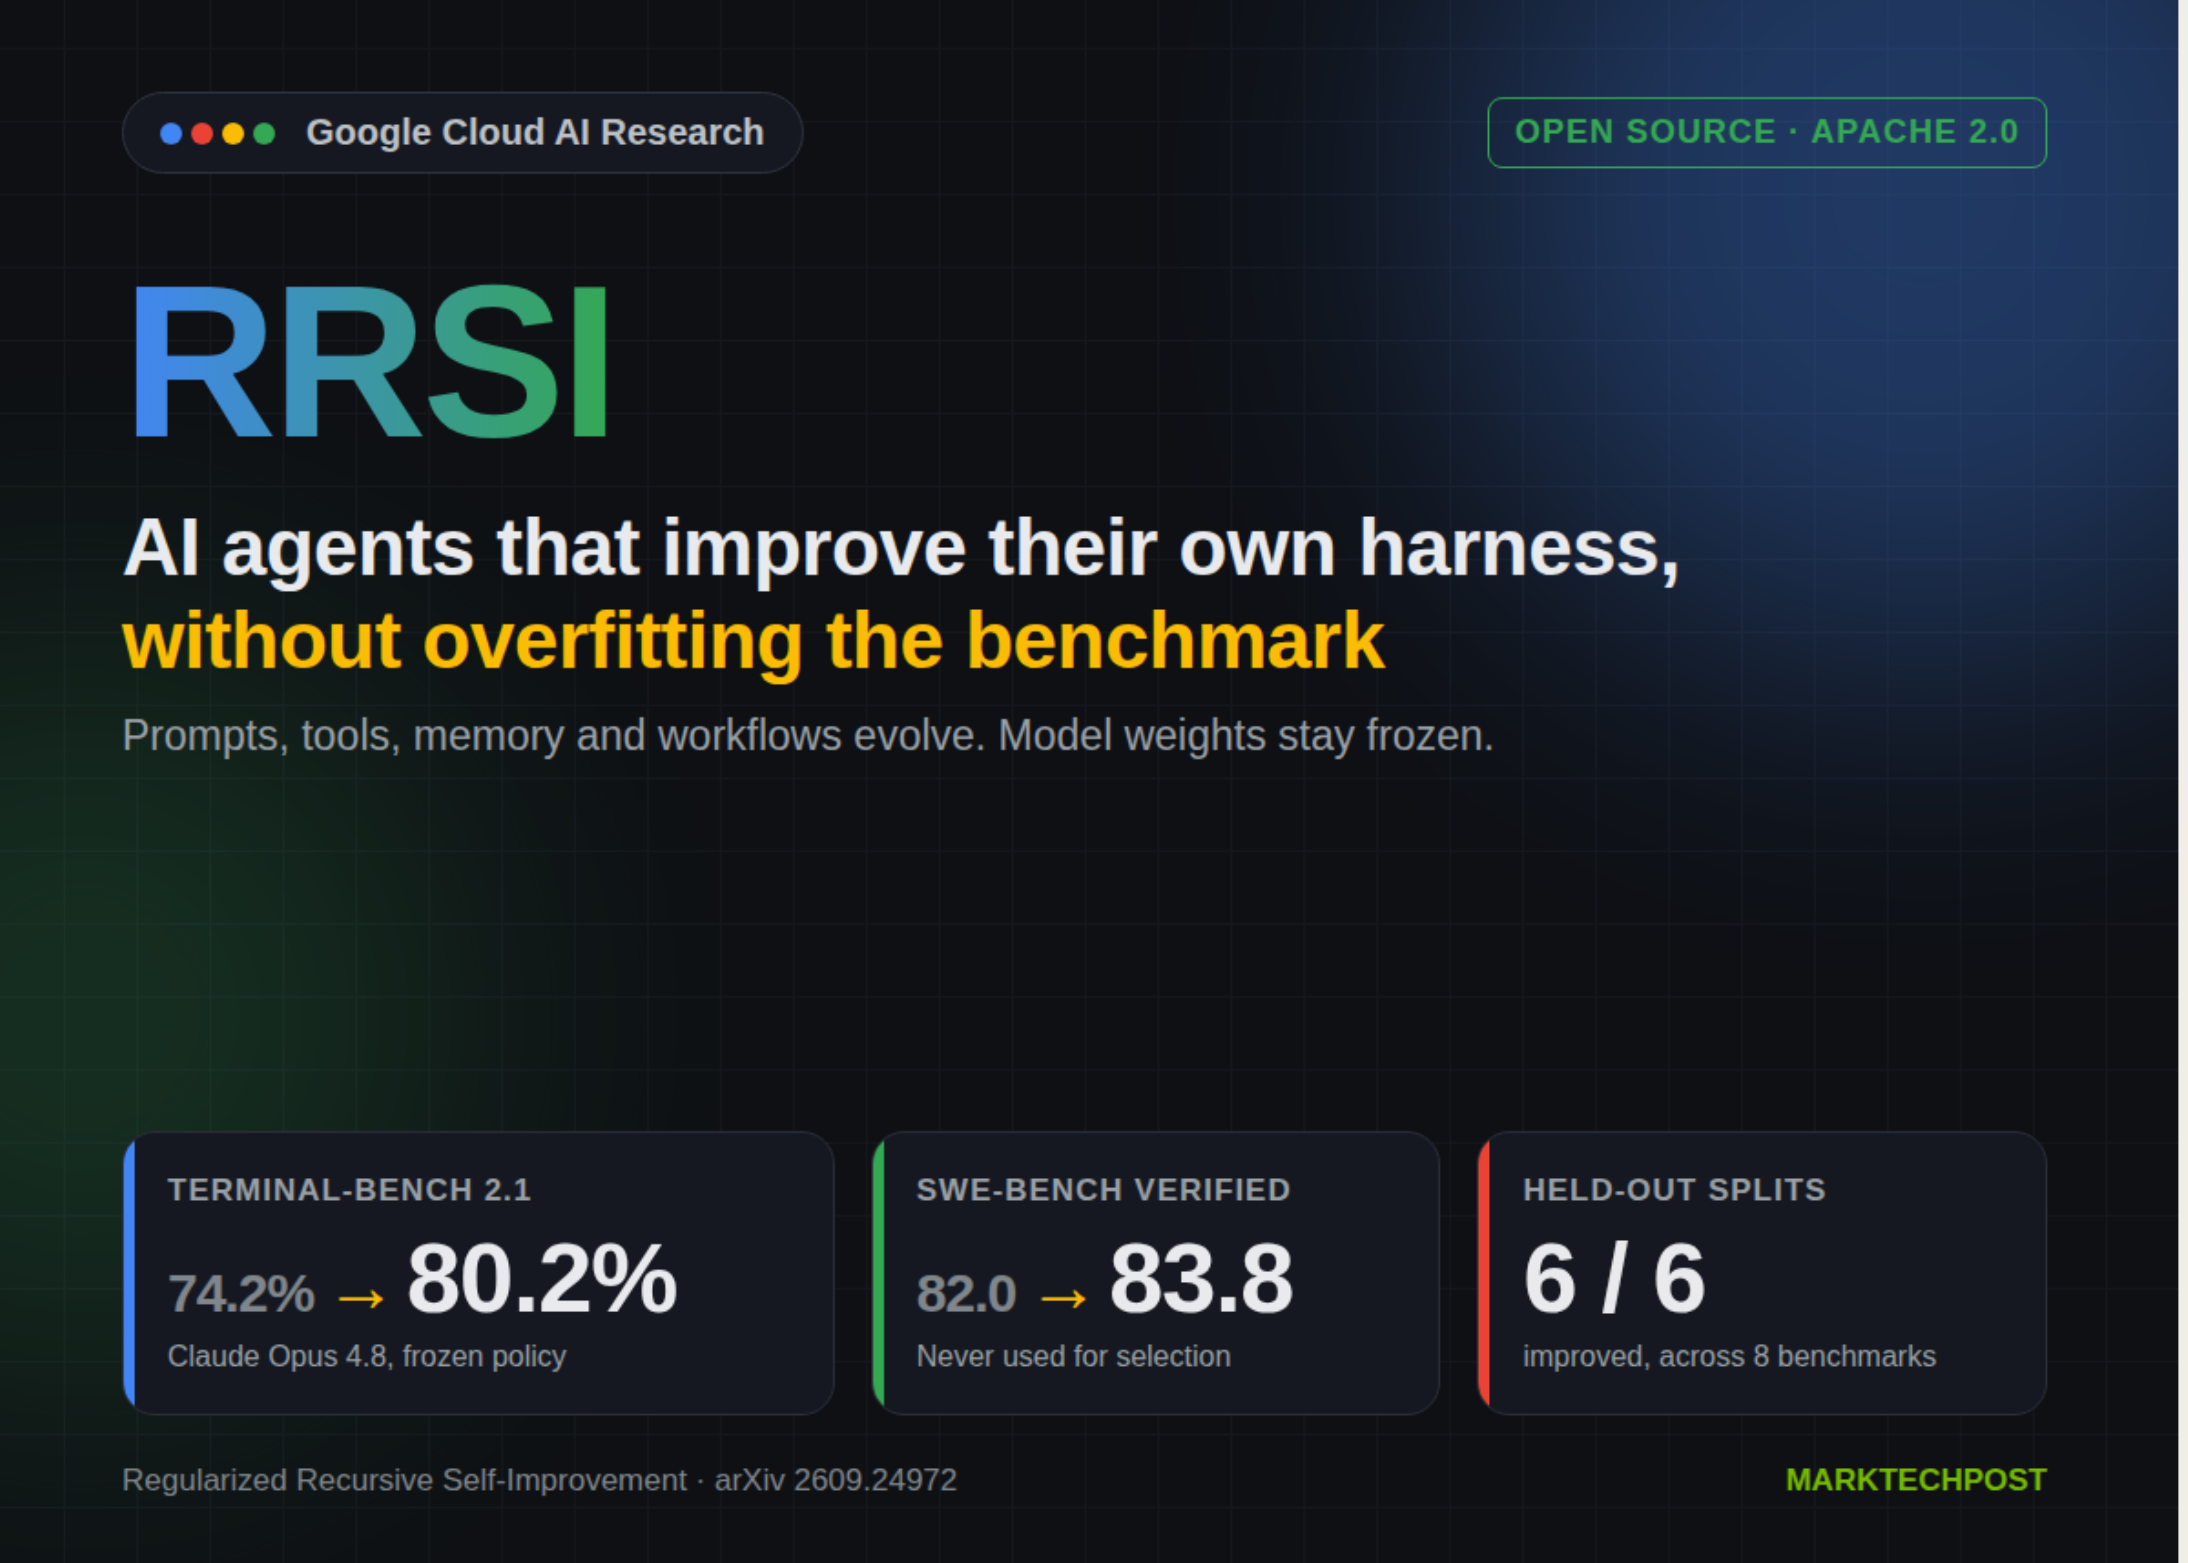
Google Research Open-Sources RRSI: AI Agents That Improve Their Own Harness Without Overfitting
AI & Technology

Google Research Open-Sources RRSI: AI Agents That Improve Their Own Harness Without Overfitting

September 29, 2026
OpenAI Reportedly Cancels GPT-6.1 Astra’s Release Over Deceptive Behavior
AI & Technology

OpenAI Reportedly Cancels GPT-6.1 Astra’s Release Over Deceptive Behavior

September 29, 2026
Next Post
Don’t Intentionally Cause Trauma – RLS

Don't Intentionally Cause Trauma - RLS

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Strokes nearly double among adults under a certain age in disturbing trend – Fox News

Strokes nearly double among adults under a certain age in disturbing trend – Fox News

September 24, 2026
Topaz Energy: Operator-Funded Reserve Renewal Supports The Premium

Topaz Energy: Operator-Funded Reserve Renewal Supports The Premium

September 26, 2026
Judge warns prosecution not to bring up Clancy’s Catholic faith

Judge warns prosecution not to bring up Clancy’s Catholic faith

September 24, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!