• bitcoinBitcoin(BTC)$85,950.006.55%
  • ethereumEthereum(ETH)$2,742.676.11%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$797.845.92%
  • rippleXRP(XRP)$1.508.92%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$118.229.25%
  • tronTRON(TRX)$0.3449640.10%
  • zcashZcash(ZEC)$1,524.376.03%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.020.00%
  • HyperliquidHyperliquid(HYPE)$94.173.49%
  • dogecoinDogecoin(DOGE)$0.09468911.21%
  • moneroMonero(XMR)$576.226.66%
  • whitebitWhiteBIT Coin(WBT)$86.465.52%
  • RainRain(RAIN)$0.01411711.00%
  • chainlinkChainlink(LINK)$13.027.26%
  • USDSUSDS(USDS)$1.000.02%
  • cardanoCardano(ADA)$0.24441010.26%
  • leo-tokenLEO Token(LEO)$8.990.62%
  • stellarStellar(XLM)$0.21147810.33%
  • uniswapUniswap(UNI)$8.913.34%
  • nearNEAR Protocol(NEAR)$4.1312.47%
  • bitcoin-cashBitcoin Cash(BCH)$264.397.60%
  • avalanche-2Avalanche(AVAX)$11.192.85%
  • Ethena USDeEthena USDe(USDE)$1.000.02%
  • litecoinLitecoin(LTC)$62.7610.12%
  • daiDai(DAI)$1.000.01%
  • CantonCanton(CC)$0.1154639.03%
  • USD1USD1(USD1)$1.000.02%
  • suiSui(SUI)$1.0426.39%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.444.82%
  • hedera-hashgraphHedera(HBAR)$0.0914644.44%
  • shiba-inuShiba Inu(SHIB)$0.0000068.80%
  • MemeCoreMemeCore(M)$1.50-2.43%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • BittensorBittensor(TAO)$285.3413.34%
  • crypto-com-chainCronos(CRO)$0.06424510.12%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • tether-goldTether Gold(XAUT)$4,341.46-0.63%
  • okbOKB(OKB)$123.096.04%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • BitwayBitway(BTW)$0.9024.94%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.00%
  • EthenaEthena(ENA)$0.22357011.96%
  • aaveAave(AAVE)$145.518.11%
  • OndoOndo(ONDO)$0.4484309.51%
  • mantleMantle(MNT)$0.647.28%
  • AsterAster(ASTER)$0.764.14%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

LongVA and the Impact of Long Context Transfer in Visual Processing: Enhancing Large Multimodal Models for Long Video Sequences

June 29, 2024
in AI & Technology
Reading Time: 6 mins read
A A
LongVA and the Impact of Long Context Transfer in Visual Processing: Enhancing Large Multimodal Models for Long Video Sequences
ShareShareShareShareShare

The field of research focuses on enhancing large multimodal models (LMMs) to process and understand extremely long video sequences. Video sequences offer valuable temporal information, but current LMMs need help to understand exceptionally long videos. This issue stems from the sheer volume of visual tokens generated by the vision encoders, making it challenging for existing models to handle them efficiently.

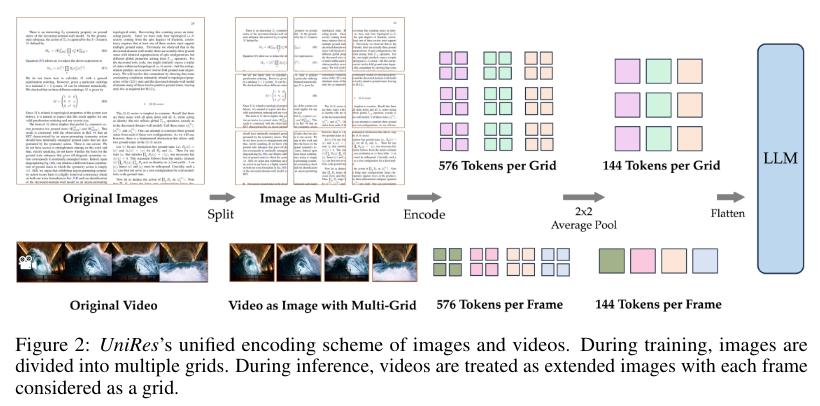
One significant problem this research addresses is the need for current LMMs to effectively process and understand long videos. This challenge arises due to the excessive number of visual tokens produced by vision encoders. For instance, models like LLaVA-1.6 generate between 576 and 2880 visual tokens for a single image, which escalates significantly with more frames. This creates a bottleneck in processing and understanding long video sequences, necessitating innovative solutions.

YOU MAY ALSO LIKE

A Laptop That Works Better With Your Android Phone

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI

Existing methods to tackle this problem include visual resamplers to reduce the number of visual tokens and heuristic techniques to prune or merge visual features. Despite these efforts, most LMMs still need help to process many frames effectively. Current methods like the visual resampler used by models such as MPLUG-Owl-video and MovieChat attempt to compress the visual features but must catch up when dealing with extensive video data.

Researchers from the LMMs-Lab Team, NTU, and SUTD in Singapore have introduced an innovative approach called Long Context Transfer to address this challenge. This approach extends the context length of the language model backbone, enabling it to process a significantly larger number of visual tokens. This method is unique because it does not require additional video training. Instead, it leverages the extended context length of the language model, allowing LMMs to comprehend orders of magnitude more visual tokens. This research was conducted by the LMMs-Lab team.

The proposed model, Long Video Assistant (LongVA), extends the context length of the language model by training it on longer text data. This context-extended language model is then aligned with visual inputs, allowing the model to process long videos effectively without additional complexity. The UniRes encoding scheme, which unifies the representation of images and videos, plays a crucial role in this process. LongVA can treat videos as extended images during inference, significantly enhancing its ability to process long video sequences.

LongVA’s performance on the Video-MME dataset demonstrates its capability to handle long videos. It can process up to 2000 frames or over 200,000 visual tokens, setting a new benchmark in this area. The Visual Needle-In-A-Haystack (V-NIAH) benchmark was developed to measure LMMs’ ability to locate and retrieve visual information over long contexts. LongVA showed superior performance in these evaluations, retrieving visual information accurately from up to 3000 frames.

Experiments showed that LongVA could effectively process and understand long videos, achieving state-of-the-art performance among 7B-scale models. The model was trained on a context length of 224K tokens, equivalent to 1555 frames, and it generalizes well beyond that, maintaining performance within 3000 frames. This demonstrates the effectiveness of the long context transfer phenomenon, where the extended context of the language model enhances the visual processing capabilities of the LMMs.
The researchers conducted detailed experiments to validate their approach. They used Qwen2-7B-Instruct as the backbone language model and performed continued pretraining with a context length of 224K over 900 million tokens. The training framework was designed to be memory efficient and maintain high GPU occupancy. The long context training was completed in just two days using eight A100 GPUs, showcasing the feasibility of this approach within academic budgets.

In conclusion, this research addresses the critical problem of processing and understanding long video sequences in large multimodal models. By extending the context length of the language model and aligning it with visual inputs, the researchers significantly improved the LMMs’ capability to handle long videos. The proposed LongVA model demonstrates substantial performance improvements, processing up to 2000 frames or over 200,000 visual tokens and setting a new standard for LMMs in this field. This work highlights the potential of long context transfer to enhance the capabilities of LMMs for long video processing.


Check out the Paper, Project, and Demo. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 45k+ ML SubReddit


🚀 Create, edit, and augment tabular data with the first compound AI system, Gretel Navigator, now generally available! [Advertisement]

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

A Laptop That Works Better With Your Android Phone
AI & Technology

A Laptop That Works Better With Your Android Phone

September 21, 2026
How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI
AI & Technology

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI

September 21, 2026
Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters
AI & Technology

Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters

September 21, 2026
StepFun Launches Step 5 Preview: A 600B-Total, 27B-Active MoE Model With 1M Context for Long-Horizon Agentic Work
AI & Technology

StepFun Launches Step 5 Preview: A 600B-Total, 27B-Active MoE Model With 1M Context for Long-Horizon Agentic Work

September 21, 2026
Next Post
‘House Republicans can’t get out of their own way’ in funding bill negotiations, Rep. Meeks says

‘House Republicans can’t get out of their own way’ in funding bill negotiations, Rep. Meeks says

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
A Laptop That Works Better With Your Android Phone

A Laptop That Works Better With Your Android Phone

September 21, 2026
GPT-6 Kalshi AI Trading Bot Week 1 Results – Printing Money?

GPT-6 Kalshi AI Trading Bot Week 1 Results – Printing Money?

September 14, 2026
Semi-truck crashed into overpass wall, left dangling

Semi-truck crashed into overpass wall, left dangling

September 20, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!